
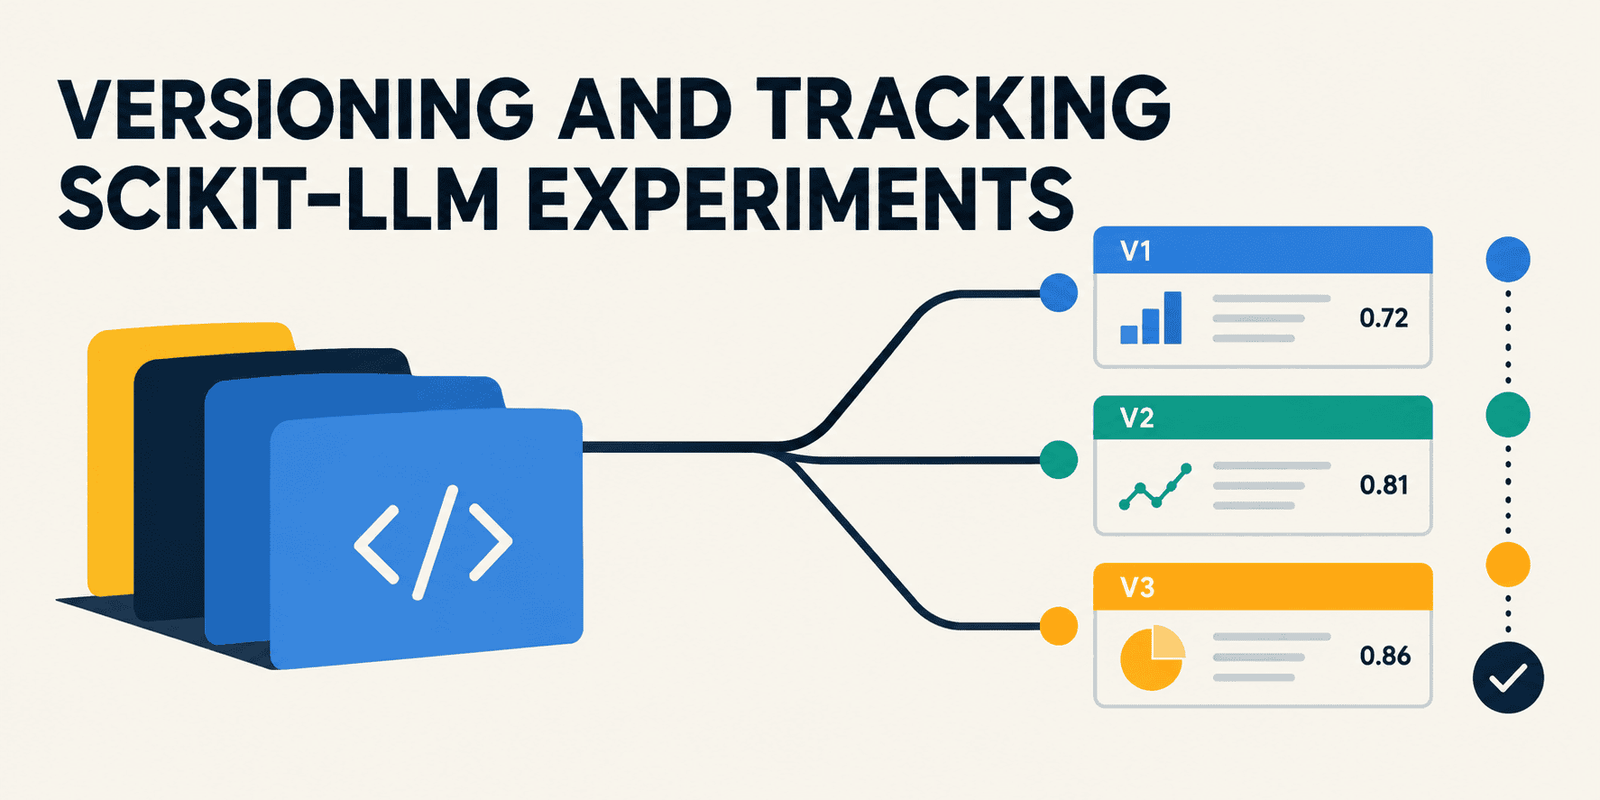
On this article, you’ll discover ways to construct, observe, examine, and register scikit-learn pipelines that combine massive language fashions utilizing Scikit-LLM and MLflow.
Matters we’ll cowl embody:
- The best way to configure Scikit-LLM and MLflow to assist native massive language mannequin execution and experiment monitoring.
- The best way to log a number of pipeline variations throughout totally different massive language mannequin backends and examine them utilizing MLflow’s monitoring API.
- The best way to promote the best-performing pipeline from a tracked experiment into MLflow’s Mannequin Registry for deployment.
Introduction
Registering, versioning, and evaluating scikit-learn-like pipelines that combine massive language fashions (LLMs) will be made simple with assistance from two cornerstone instruments: the Scikit-LLM library and MLflow, an open-source framework for managing the end-to-end lifecycle of machine studying initiatives.
This text demonstrates the steps to construct, log, examine, and register scikit-learn pipelines revolving round LLMs utilizing Scikit-LLM and MLflow. The code proven and described intimately beneath is designed with the first goal of making certain mannequin versioning and reproducibility throughout LLM backend updates — a frequent course of in actual settings that may rapidly escalate.
Setup and Preliminary Configurations
If you happen to haven’t finished so earlier than, or in case you are working this code on a cloud-based pocket book like Google Colab, step one is to put in the important thing libraries you will want:
|
pip set up “scikit-llm[gpt4all]” mlflow |
Make sure that to make use of the additional possibility in brackets when putting in scikit-llm to keep away from compatibility points.
Now, we initialize the configuration of Scikit-LLM with dummy credentials that allow native gpt4all mannequin execution. In the meantime, the MLflow mannequin registry —the important thing useful resource the place fashions can be versioned— depends on a database backend, which can also be configured within the code beneath. Furthermore, we initialize an MLflow monitoring experiment named "Scikit-LLM-Versioning". Lastly, we outline a small labeled dataset for zero-shot classification (extra about this LLM-driven type of classification job right here).
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
import mlflow import mlflow.sklearn from sklearn.pipeline import Pipeline from skllm.config import SKLLMConfig from skllm.fashions.gpt.classification.zero_shot import ZeroShotGPTClassifier
# 1. Dummy keys required by Scikit-LLM for native gpt4all execution SKLLMConfig.set_openai_key(“local-execution-key”) SKLLMConfig.set_openai_org(“local-execution-org”)
# 2. Database backend required for the MLflow Mannequin Registry mlflow.set_tracking_uri(“sqlite:///mlflow.db”) mlflow.set_experiment(“Scikit-LLM-Versioning”)
# Pattern dataset for zero-shot classification X_train = [ “The application crashed immediately.”, “Absolutely wonderful support team!”, “It works fine but is a bit slow.” ] y_train = [“bug”, “praise”, “feedback”] |
Logging the Baseline and Upgraded Pipelines
That is the place the true enjoyable begins. We initialize a baseline pipeline that trains a zero-shot classification mannequin utilizing a light-weight pre-trained LLM.
The with block that follows, named after the Orca Mini mannequin chosen, allows monitoring of the LLM backend sort and the mannequin file string as surroundings parameters, thereby fostering reproducibility. A "cloudpickle" serialization format (a variant of the basic pickle, or .pkl for brief, utilized in smaller machine studying fashions) is used to log the pipeline. Understanding this block is essential to leveraging LLM versioning in MLflow for subsequent experiment monitoring. As soon as execution completes, it outputs a novel MLflow run ID.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
LLM_V1 = “gpt4all::orca-mini-3k-71m-q4_0.gguf”
pipeline_v1 = Pipeline([ (‘llm_classifier’, ZeroShotGPTClassifier(model=LLM_V1)) ])
with mlflow.start_run(run_name=“Baseline_Orca_Mini”) as run_v1: mlflow.log_param(“llm_backend”, “gpt4all”) mlflow.log_param(“llm_model_file”, LLM_V1)
pipeline_v1.match(X_train, y_train)
# Override strict skops sort checking with cloudpickle mlflow.sklearn.log_model( pipeline_v1, “mannequin”, serialization_format=“cloudpickle” )
print(f“V1 Logged – Run ID: {run_v1.data.run_id}”) |
Output excerpt:
|
V1 Logged – Run ID: 0852aaec23364725b433f09973a3d911 |
Subsequent, let’s suppose we create a secondary, upgraded pipeline based mostly on a heavier LLM to reveal MLflow’s model-swapping capabilities. Particularly, we now goal "gpt4all::ggml-model-gpt4all-falcon-q4_0.bin", which makes for a sensible backend improve. The code beneath isolates this new pipeline inside a separate MLflow run named "Upgraded_Falcon". Every part else is finished simply as earlier than: pipeline parameterization, mannequin becoming, and logging —simply in a definite MLflow run, yielding a brand new distinctive ID.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
LLM_V2 = “gpt4all::ggml-model-gpt4all-falcon-q4_0.bin”
pipeline_v2 = Pipeline([ (‘llm_classifier’, ZeroShotGPTClassifier(model=LLM_V2)) ])
with mlflow.start_run(run_name=“Upgraded_Falcon”) as run_v2: mlflow.log_param(“llm_backend”, “gpt4all”) mlflow.log_param(“llm_model_file”, LLM_V2)
pipeline_v2.match(X_train, y_train)
# Override strict skops sort checking with cloudpickle mlflow.sklearn.log_model( pipeline_v2, “mannequin”, serialization_format=“cloudpickle” )
print(f“V2 Logged – Run ID: {run_v2.data.run_id}”) |
Output excerpt:
|
V2 Logged – Run ID: ee892572d0a641f89201c33479b98746 |
Auditing, Evaluating, and Registering Fashions
Now that we’ve got a number of logged pipeline variations, we invoke the MLflow search API to extract the complete versioning experiment and show it as a pandas DataFrame. Word that key auditing columns have been separated for readability: run ID, MLflow run identify, native LLM parameter, and execution standing. For a sensible contact, the outcomes beneath (based mostly on earlier runs resulting in the ultimate code included on this article) present historic audit info from a number of executions — displaying not solely MLflow monitoring of FINISHED pipelines but additionally early FAILED makes an attempt.
|
experiment = mlflow.get_experiment_by_name(“Scikit-LLM-Versioning”) runs_df = mlflow.search_runs(experiment.experiment_id)
comparison_df = runs_df[[‘run_id’, ‘tags.mlflow.runName’, ‘params.llm_model_file’, ‘status’]]
print(“Experiment Monitoring Audit:”) show(comparison_df) |
|
run_id tags.mlflow.runName params.llm_model_file standing 0 ee892572d0a641f89201c33479b98746 Upgraded_Falcon gpt4all::ggml–mannequin–gpt4all–falcon–q4_0.bin FINISHED 1 0852aaec23364725b433f09973a3d911 Baseline_Orca_Mini gpt4all::orca–mini–3k–71m–q4_0.gguf FINISHED 2 68781001dec14e0cbe46e71cf38e92c4 Upgraded_Falcon gpt4all::ggml–mannequin–gpt4all–falcon–q4_0.bin FINISHED 3 37e6011d2cca4e43a0a426cb936582e6 Baseline_Orca_Mini gpt4all::orca–mini–3k–71m–q4_0.gguf FINISHED 4 5ccd7e21a74a4fcc8a01633231417b28 Baseline_Orca_Mini gpt4all::orca–mini–3k–71m–q4_0.gguf FAILED |
Word that when you run the offered code and all cells execute with out errors, you might even see a shorter record — ideally containing solely two logged runs related to the 2 pipelines, each with FINISHED standing.
To wrap up, let’s shift from logged to registered. In different phrases, let’s see tips on how to extract the optimum execution run and promote (formally register) its related mannequin into MLflow’s Mannequin Registry. The code searches the DataFrame to seek out the primary run matching the "Upgraded_Falcon" label and secures its run ID. This goal pipeline is then registered within the backend database, formally recorded as Model 1.
|
best_run_id = runs_df[runs_df[‘tags.mlflow.runName’] == ‘Upgraded_Falcon’].iloc[0][‘run_id’] model_uri = f“runs:/{best_run_id}/mannequin”
registered_model = mlflow.register_model( model_uri=model_uri, identify=“Production_ZeroShot_Classifier” )
print(f“Efficiently registered mannequin ‘{registered_model.identify}'”) print(f“Present Registry Model: {registered_model.model}”) |
Output:
|
Efficiently registered mannequin ‘Production_ZeroShot_Classifier’ Present Registry Model: 1 |
We simply carried out a hardcoded, handbook mannequin choice, however what if you wish to discover and register the one with the most effective efficiency — as an illustration, the very best accuracy? You possibly can do one thing like this earlier than calling mlflow.register_model():
|
# Retrieving runs ordered by accuracy (highest to lowest) best_runs_df = mlflow.search_runs( experiment_ids=[experiment.experiment_id], order_by=[“metrics.accuracy DESC”] )
# Extracting the ID of absolutely the high performer metric_winner_id = best_runs_df.iloc[0] print(metric_winner_id) |
Output:
|
run_id 0605f300074a4d91b1e3438348d157f1 experiment_id 1 standing FINISHED artifact_uri /content material/mlruns/1/0605f300074a4d91b1e3438348d1… begin_time 2026–08–29 14:53:18.182000+00:00 finish_time 2026–08–29 14:53:22.007000+00:00 params.llm_model_file gpt4all::ggml–mannequin–gpt4all–falcon–q4_0.bin params.llm_backend gpt4all tags.mlflow.supply.identify fileId=1GM67JQ61d3Y7eibN63YS6Udjt5qxf14x tags.mlflow.runName Upgraded_Falcon tags.mlflow.consumer root tags.mlflow.supply.sort NOTEBOOK |
Wrapping Up
The 2-step (logging and registering) workflow for LLM pipeline versioning launched on this article is designed to stop your official mannequin registry from turning into cluttered with failed makes an attempt, messy code excerpts, or inferior take a look at runs that led nowhere. The monitoring desk displaying logged variations is used to match a set of tough drafts, publishing solely the ultimate “winner(s)” to the registry database for deployment or energetic use.