
A monetary companies crew spends important time every week manually creating shopper PowerPoint shows from quarterly stories, compliance paperwork, and market analyses. Every presentation requires studying a whole bunch of pages, extracting key knowledge factors, structuring slides, and producing supporting visuals. This put up walks you thru constructing an AI agent system utilizing Amazon Bedrock AgentCore that automates this workflow, finishing in underneath 90 seconds in our inner testing. This method reduces presentation creation time whereas grounding content material in supply paperwork. The answer deploys a supervisor agent on AgentCore runtime, a functionality of Amazon Bedrock AgentCore, utilizing the Strands Brokers framework to orchestrate doc era and summarization instruments. Anthropic Claude Sonnet 4.6 (accessible on Amazon Bedrock) handles content material creation, Amazon Titan Textual content Embeddings v2 powers vector search, and Stability AI Secure Picture Inpaint (accessible on Amazon Bedrock) generates slide pictures. This put up features a public repository with the code property.
Resolution overview
The answer deploys a single supervisor agent on Amazon Bedrock AgentCore runtime that selects between doc era and summarization instruments primarily based on person requests. A Retrieval Augmented Era (RAG) pipeline makes use of Amazon OpenSearch Serverless for vector storage and semantic search throughout multimodal content material.
The answer features a REST API constructed with .NET 8 minimal APIs, so you may combine with current enterprise functions by normal HTTP calls. AWS Lambda provides serverless compute, together with containerized capabilities for PowerPoint era. The answer secures the implementation with Amazon Digital Non-public Cloud (Amazon VPC) isolation, AWS Key Administration Service (AWS KMS) encryption, and AWS Id and Entry Administration (IAM) least-privilege entry management.
Key ideas
This part covers AgentCore runtime, RAG, and content material security guardrails as they apply to this answer.
Agent orchestration with Amazon Bedrock AgentCore
A single AI agent producing paperwork from massive information bases should retrieve content material, construction outlines, generate textual content, create pictures, and assemble recordsdata. Fairly than implementing these competing tasks in a monolithic perform, the answer makes use of a tool-based structure the place a supervisor agent routes requests to specialised instruments.
Amazon Bedrock AgentCore runtime supplies a platform to construct, join, and optimize brokers at scale, with any framework or mannequin. The agent code runs in an remoted container with session administration, built-in id, and observability. The answer makes use of the Strands Brokers framework (an open supply SDK for constructing AI brokers) to implement the supervisor logic.
The supervisor agent exposes two instruments:
- generate_pptx: Creates PowerPoint shows by invoking the PPTX Generator Lambda perform, which retrieves content material from the information base, generates slide outlines, creates AI pictures, and assembles the ultimate doc.
- generate_summary: Extracts and synthesizes data from the information base utilizing RAG to ship correct, grounded responses.
The agent determines whether or not a request requires doc era, content material summarization, or each, then invokes the suitable device. You may add new capabilities by defining new instruments within the agent code with out modifying current ones.
Retrieval Augmented Era (RAG) for enterprise information
RAG addresses a elementary problem in AI programs: delivering correct, up-to-date data grounded in enterprise knowledge fairly than relying solely on the mannequin’s coaching knowledge. The implementation makes use of Amazon Bedrock Information Bases, which mix vector search with massive language fashions (LLMs) to retrieve related context earlier than producing responses.
The RAG pipeline works as follows:
- You add enterprise paperwork to Amazon Easy Storage Service (Amazon S3).
- The system chunks and parses paperwork, making use of particular dealing with for multimodal content material together with tables, charts, and pictures.
- Amazon Titan Textual content Embeddings v2 converts every chunk into high-dimensional vectors that seize semantic that means.
- Amazon OpenSearch Serverless shops the vectors, making a searchable vector database.
- At question time, the system converts the person’s request into an embedding and performs similarity search to retrieve related doc chunks.
- Retrieved chunks provide context to the language mannequin, which generates responses grounded within the supply materials.
This method is designed to assist cut back hallucinated content material by grounding generated paperwork in supply data from the enterprise information base.
Observe: The Amazon OpenSearch Serverless assortment knowledge airplane should stay publicly accessible as a result of Amazon Bedrock Information Bases accesses Amazon OpenSearch Serverless from AWS-managed infrastructure, not by buyer VPC endpoints. IAM knowledge entry insurance policies shield the gathering, and VPC-only entry restricts the Amazon OpenSearch Serverless dashboard.
Amazon Bedrock Guardrails for content material security
Enterprise AI functions require content material moderation to satisfy organizational requirements and compliance necessities. Amazon Bedrock Guardrails provides built-in content material filtering and security mechanisms built-in all through the doc era pipeline.
Guardrails function at a number of levels:
- Enter processing: Filters person requests to assist forestall injection points and inappropriate content material.
- Output era: Screens mannequin outputs to confirm compliance with content material insurance policies.
- Personally identifiable data (PII) dealing with: Detects and anonymizes or blocks PII.
The implementation creates customized guardrails by AWS Cloud Improvement Equipment (AWS CDK), configured with particular insurance policies tailor-made to enterprise doc creation. The agent applies guardrails on the mannequin invocation degree, offering constant content material security with out requiring handbook configuration for every deployment.
Resolution structure
The next diagram illustrates the agent-based doc era system.
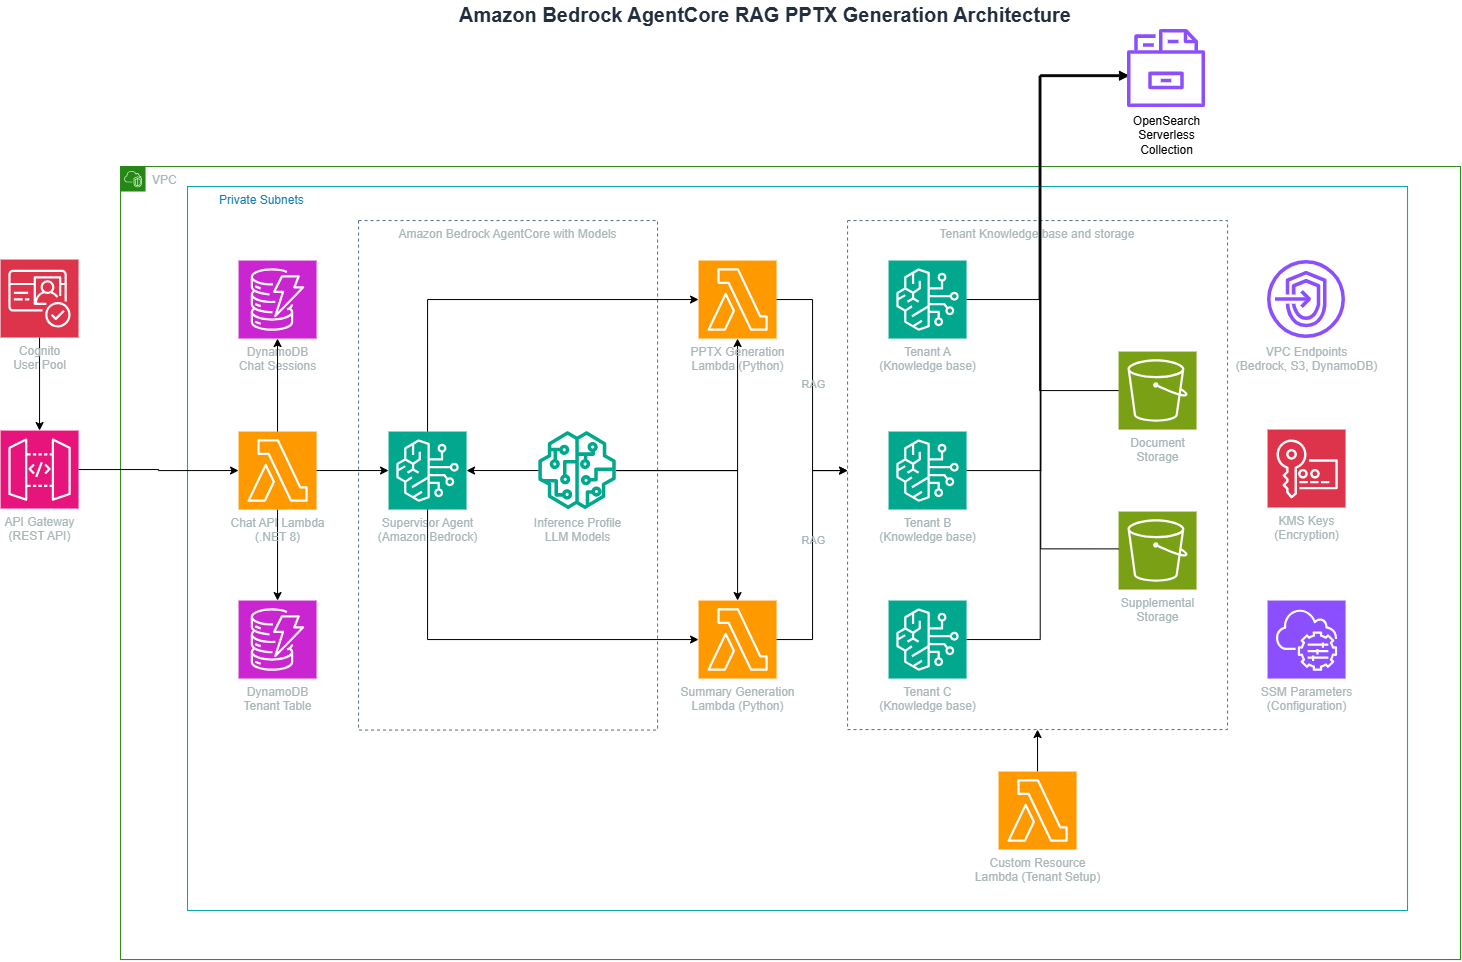
Determine 1: Structure of the Amazon Bedrock AgentCore RAG presentation era system
The information movement begins with person requests arriving by Amazon API Gateway, which routes them to a .NET-based Chat API operating on AWS Lambda. The API maintains dialog state in Amazon DynamoDB. It then invokes the supervisor agent hosted on Amazon Bedrock AgentCore runtime.
The supervisor agent analyzes the request and selects the suitable device. For doc era, it invokes the PPTX Generator Lambda (a containerized Python perform). For summarization, the supervisor invokes the Abstract Generator Lambda, which queries the information base by the retrieve_and_generate API.
The system processes, chunks, and embeds paperwork saved in Amazon S3 utilizing Amazon Titan Textual content Embeddings v2. Amazon OpenSearch Serverless indexes the embeddings for quick semantic search. When instruments question the information base, Amazon OpenSearch Serverless retrieves related chunks, that are then equipped as context to Anthropic Claude Sonnet 4.6 (on Amazon Bedrock) for producing grounded responses.
The system shops generated paperwork in Amazon S3 and returns presigned URLs for safe obtain. Safety measures embrace:
- AWS WAF with managed rule units and IP-based fee limiting on Amazon API Gateway.
- Amazon Cognito with the Plus characteristic plan and superior safety mode for menace safety.
- Amazon Bedrock Guardrails provisioned by AWS CDK for constant content material filtering.
- Amazon DynamoDB with point-in-time restoration, deletion safety, and customer-managed AWS KMS encryption.
- Amazon S3 buckets with versioning, server entry logging, and block public entry.
- AWS X-Ray tracing on Lambda capabilities for distributed debugging.
- Enter validation with regex-based tenant ID and session ID verification.
- Tenant isolation by AWS Safety Token Service (AWS STS) function assumption per tenant.
Conditions
Earlier than deploying, you want the next instruments and entry configured in your setting:
- AWS setting:
- An energetic AWS account with permissions for deploying infrastructure.
- AWS Command Line Interface (AWS CLI) configured with credentials.
- IAM function with applicable service entry insurance policies.
- Improvement instruments:
- AWS companies entry:
- Amazon Bedrock with mannequin entry for Anthropic Claude Sonnet 4.6, Amazon Titan Textual content Embeddings v2, and Stability AI Secure Picture Inpaint (accessible by Amazon Bedrock). For mannequin availability by Area, see Supported fashions by AWS Area in Amazon Bedrock.
- Amazon Bedrock AgentCore entry enabled in your account.
- Amazon API Gateway Regional REST API integration timeout configured to no less than 300 seconds. The default is 29 seconds. For extra data, see API Gateway quotas.
- An current Amazon VPC with non-public subnets.
- An Amazon S3 bucket for deployment artifacts.
Arrange the answer
The setup course of consists of configuring deployment parameters and initializing the AWS CDK setting.
- Clone the repository and navigate to the venture listing:
- Create the configuration file
pipeline-params.inion the repository root:Set
awscliprofileto your AWS CLI profile identify, or go away empty to make use of setting variable credentials. - Bootstrap AWS CDK (one-time per account and Area):
This creates the AWS CloudFormation CDKToolkit stack required for AWS CDK deployments.
- Make construct scripts executable:
Construct and deploy
The deployment consists of three phases: constructing artifacts, deploying infrastructure, and deploying the AgentCore runtime agent.
Construct section
The construct section compiles software code and packages deployment artifacts. Run the construct script:
This compiles the .NET tasks (Chat API) and packages them as Lambda deployment packages. It builds the PPTX Generator container picture utilizing Docker or Finch and authenticates with Amazon Elastic Container Registry (Amazon ECR). It then pushes the container picture and shops construct artifacts within the asset-output listing.
Infrastructure deployment section
The infrastructure deployment creates AWS sources and configures service integrations. Run the deployment script:
The deployment creates 4 AWS CloudFormation stacks in dependency order:
- VPCEndpointsStack: Configures Amazon VPC endpoints for AWS companies together with Amazon Bedrock AgentCore.
- OpensearchStack: Provisions Amazon OpenSearch Serverless assortment for vector storage.
- AgentCoreStack: Creates guardrails, Lambda capabilities, IAM roles, and shops configuration in AWS Methods Supervisor Parameter Retailer.
- ChatApiStack: Deploys Amazon API Gateway and Chat API Lambda.
AgentCore runtime deployment
After the infrastructure stacks are deployed, deploy the supervisor agent to AgentCore runtime:
This script builds the supervisor agent container (ARM64), pushes it to Amazon ECR, creates the AgentCore runtime and endpoint, and updates the Methods Supervisor parameter with the endpoint Amazon Useful resource Identify (ARN). The Chat API references this endpoint ARN to route requests to the agent.
After deployment, AWS CloudFormation outputs embrace the Amazon API Gateway endpoint URL and useful resource identifiers.
Configuration
The answer provides a number of configuration factors:
Agent directions
Edit agent/app.py to change the supervisor agent’s system immediate and conduct. The agent makes use of Strands Brokers with two instruments outlined in agent/instruments.py:
- generate_pptx: Invokes the PPTX Generator Lambda for doc creation.
- generate_summary: Invokes the Abstract Generator Lambda for information base queries.
Mannequin choice
In pipeline-params.ini, alter mannequin identifiers:
ParsingInferenceProfileId: Mannequin for information base doc parsing (Anthropic Claude Haiku 4.5 really helpful for value effectivity).AgentInferenceProfileId: Mannequin for agent reasoning (Anthropic Claude Sonnet 4.6 really helpful).EmbeddingModelId: Embedding mannequin for vector search (Amazon Titan Textual content Embeddings v2).ImageGenerationModelId: Mannequin for slide picture era (Stability AI Secure Picture Inpaint).
With inference profiles as a substitute of direct mannequin IDs, requests draw on a broader multi-Area capability pool, which will increase throughput and helps keep constant efficiency underneath load.
Lambda configuration
Regulate compute sources within the stack recordsdata:
- Chat API: 128 MB reminiscence, 29-second timeout, 100 reserved concurrency (in
api.py). - PPTX Generator: 900 MB reminiscence, 300-second timeout, 50 reserved concurrency (in
pptx_gen.py). - Abstract Generator: 512 MB reminiscence, 300-second timeout, 50 reserved concurrency (in
sum_gen.py).
Outcomes
In inner testing with a 90-page Amazon 2024 Annual Report PDF, the answer produced the next efficiency metrics:
- Presentation era time: 70–90 seconds end-to-end (together with information base retrieval, content material era, picture creation, and file meeting).
- Slide rely: Six slides with title, bullet factors, picture+textual content, image-only, and takeaway codecs.
- Picture era: Two AI-generated pictures per presentation utilizing Stability AI Secure Picture Inpaint.
- Price per era: Roughly $0.04 in mannequin invocation prices at time of writing in us-east-1 (textual content and picture era, with picture era accounting for almost all of value).
- Information base ingestion: Underneath 2 minutes for a single 1.3 MB PDF doc.
PowerPoint shows
The next figures present instance slides from a generated presentation.
Determine 2: Generated title slide with customizable branding
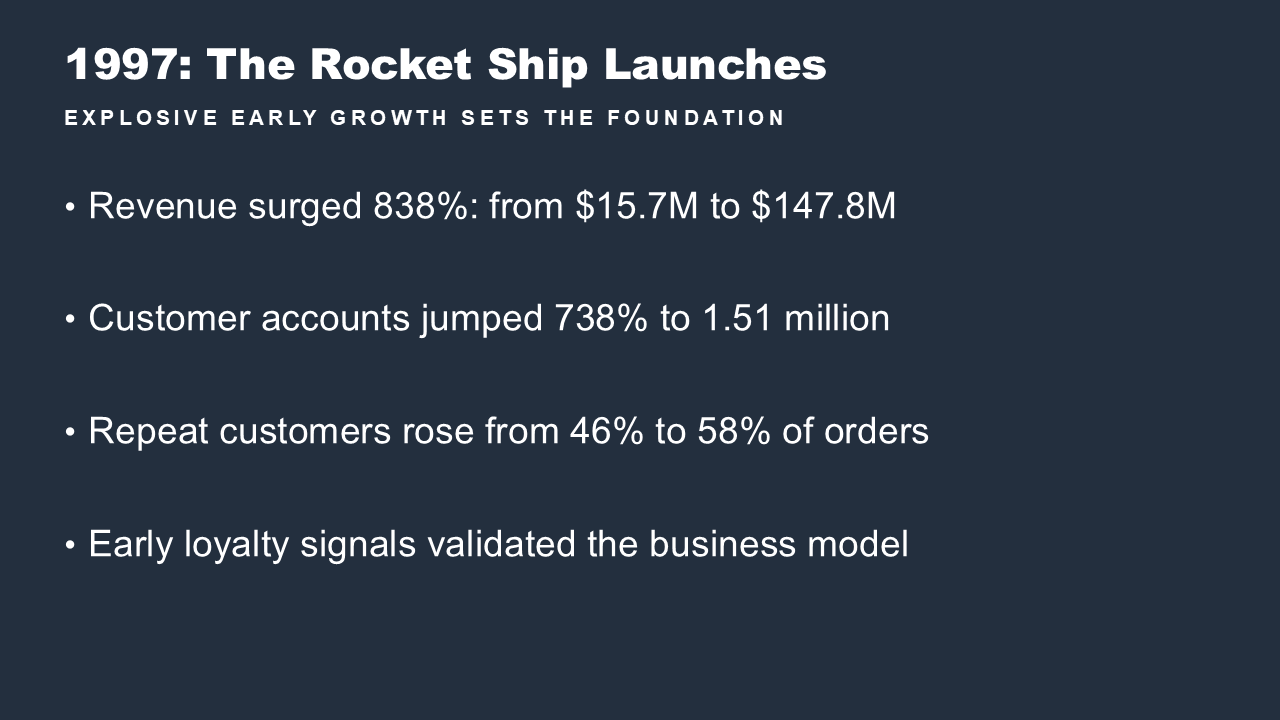
Determine 3: Generated content material slide with bullet factors
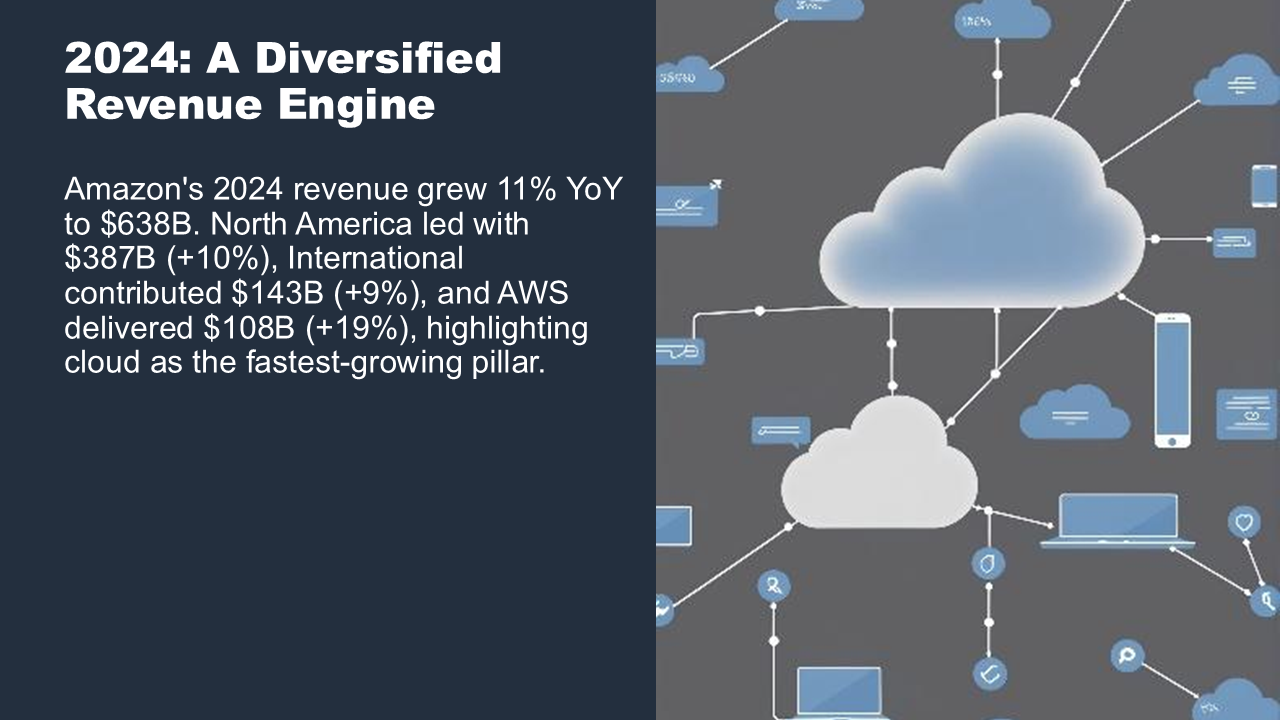
Determine 4: Generated slide combining textual content with an AI-generated picture
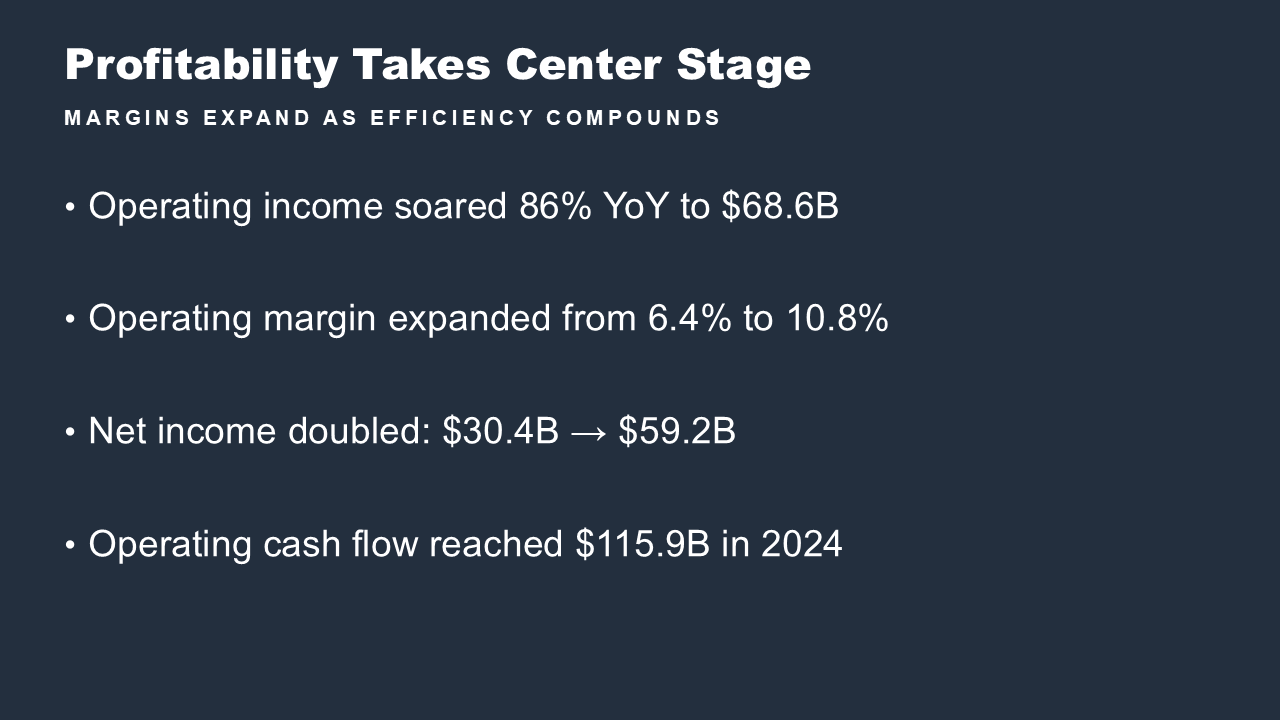
Determine 5: Generated content material slide summarizing profitability metrics
Determine 6: Generated image-only slide with an AI-generated visible
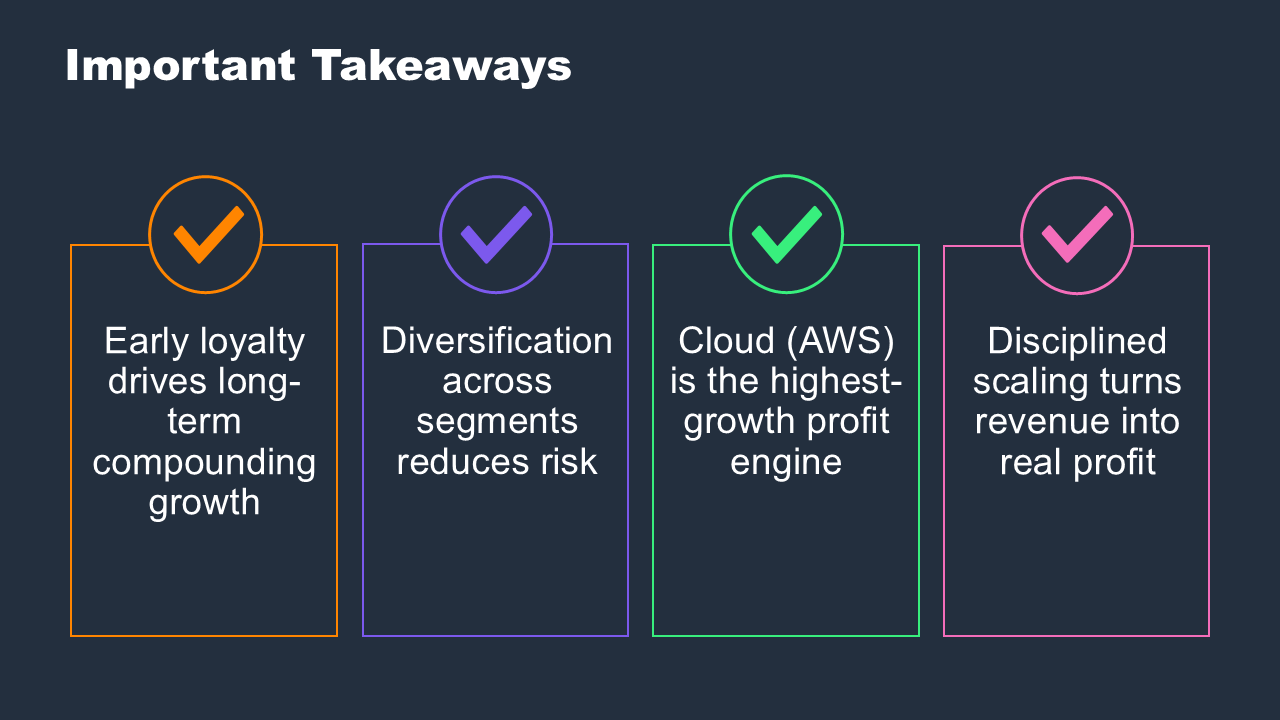
Determine 7: Generated takeaways slide
Generated shows embrace:
- Title slides with customizable branding.
- Content material slides with bullet factors and structured textual content.
- Picture slides with AI-generated visuals from Stability AI Secure Picture Inpaint (on Amazon Bedrock).
- Speaker notes with presentation steerage.
- Constant formatting primarily based on company templates.
Summaries
Abstract outputs supplied to the information base embrace:
- Concise synthesis of data base content material.
- Quotation monitoring to supply paperwork.
- Structured formatting with key factors highlighted.
API responses
The Chat API returns:
- Streaming responses for real-time person suggestions. As a result of inner testing confirmed that presentation era takes 70–90 seconds (exceeding the default Amazon API Gateway 29-second integration timeout), the Chat API makes use of an asynchronous invocation sample. Use streaming or polling to obtain the ultimate outcome fairly than ready on a synchronous REST name.
- Dialog context upkeep throughout a number of turns.
- Amazon S3 presigned URLs for doc downloads (5-minute expiration).
Generated content material undergoes Amazon Bedrock Guardrails validation to confirm compliance with content material insurance policies earlier than supply.
Clear up
To keep away from ongoing costs, delete the deployed sources:
- Delete the AgentCore runtime and endpoint:
- Flip off Amazon DynamoDB deletion safety (required earlier than stack deletion):
- Delete AWS CloudFormation stacks in reverse dependency order:
- Empty Amazon S3 buckets earlier than deletion (AWS CloudFormation can’t delete non-empty buckets):
- Delete Amazon ECR repositories containing container pictures:
- Delete tenant information base sub-stacks (created by the tenant provisioner):
Safety issues
This answer makes use of Lambda setting variables for configuration values corresponding to mannequin IDs, Amazon S3 bucket names, and guardrail IDs. These are useful resource identifiers, not secrets and techniques. For manufacturing deployments, use AWS Secrets and techniques Supervisor for delicate configuration values corresponding to API keys and database credentials.
The AgentCore runtime agent runs in an remoted container with session-level isolation. Every person session operates in a devoted setting, serving to to stop cross-session knowledge contamination.
Conclusion
On this put up, you constructed an AI agent system with Amazon Bedrock AgentCore that automates enterprise doc era. The supervisor agent deployed on AgentCore runtime routes requests to specialised instruments for doc creation and summarization, lowering presentation creation to about 90 seconds in an inner take a look at.
The RAG pipeline grounds generated content material in supply paperwork, and Amazon Bedrock Guardrails verifies content material compliance. You may adapt this structure for automated report era in monetary companies, technical documentation for engineering groups, or proposal creation for gross sales organizations.
To get began, clone the GitHub repository and comply with the setup directions. For extra details about the companies used, confer with the Amazon Bedrock AgentCore documentation, Strands Brokers SDK, and AWS CDK Developer Information.
Concerning the authors