
Reflection AI launched Beam, an open-weight mannequin for agentic coding and long-horizon duties similar to sustaining code, utilizing instruments, deciphering outcomes, and finishing multi-step workflows. The open-weight launch offers builders and researchers management over the runtime, deployment atmosphere, and customization course of.
On this publish, we clarify Reflection’s imaginative and prescient and present how one can deploy Beam on AWS. Begin with an Amazon SageMaker JumpStart real-time endpoint for a completely managed path. If you want Kubernetes-native management over distributed GPU infrastructure, use Amazon SageMaker HyperPod Inference with JumpStart, SGLang, or vLLM. We additionally clarify how Beam’s 501 billion complete parameters form checkpoint storage, weight reminiscence, sharding, and parallelism, whereas its 23 billion energetic parameters affect per-token compute.
At launch, Beam is out there in Amazon SageMaker JumpStart in US East (N. Virginia) and US East (Ohio).
Reflection’s imaginative and prescient for open intelligence
Reflection’s mission is to make intelligence open and accessible to all by means of open mannequin weights, printed analysis, and open supply software program. Its full AI stack spans fashions, core software program, manufacturing infrastructure, and purposes. Beam brings this strategy to builders constructing software program engineering and agentic methods.
About Reflection Beam
Beam is a sparse mixture-of-experts mannequin for resolving software program points, modifying code, calling instruments, and performing on intermediate outcomes. It has 501 billion complete parameters and 23 billion energetic parameters, and Reflection reviews an efficient context size of 1 million tokens.
Reflection releases Beam’s weights by means of Hugging Face underneath the Apache 2.0 license. Beam 1.0 is out there in BF16, FP8, and NVFP4 checkpoint variants. These codecs present totally different reminiscence footprints and {hardware} compatibility. You’ll be able to deploy the mannequin with the AWS managed JumpStart container configuration or examine and customise the mannequin with SGLang or vLLM in your AWS atmosphere.
Perceive the deployment structure
Select the serving path that meets your management and scaling necessities.
- Begin with a SageMaker JumpStart real-time endpoint whenever you need an AWS managed mannequin bundle, endpoint, and invocation API with out working Kubernetes.
- Use JumpStart on HyperPod Inference whenever you need the AWS managed container and mannequin configuration on a HyperPod cluster orchestrated by Amazon Elastic Kubernetes Service (Amazon EKS).
- Use SGLang or vLLM on HyperPod Inference when it is advisable to management the serving picture, runtime arguments, quantization, or distributed execution.
- Measurement the deployment for checkpoint storage, weight reminiscence, KV cache, context size, batching, runtime overhead, and the supported parallelism.
- Outline the anticipated concurrency and latency targets, then configure replicas, caching, routing, and autoscaling from measured workload conduct.
The JumpStart real-time path packages the mannequin, container, and endpoint behind a managed deployment workflow. The HyperPod path exposes the cluster and serving runtime so that you could management distributed execution, caching, routing, and scaling.
The next diagram reveals the parts utilized by the HyperPod path. Beam may be sourced by means of SageMaker JumpStart, Hugging Face Hub, or an optionally available Amazon Easy Storage Service (Amazon S3) mirror. The distributed staff use the AWS managed JumpStart container or a customized SGLang or vLLM runtime.
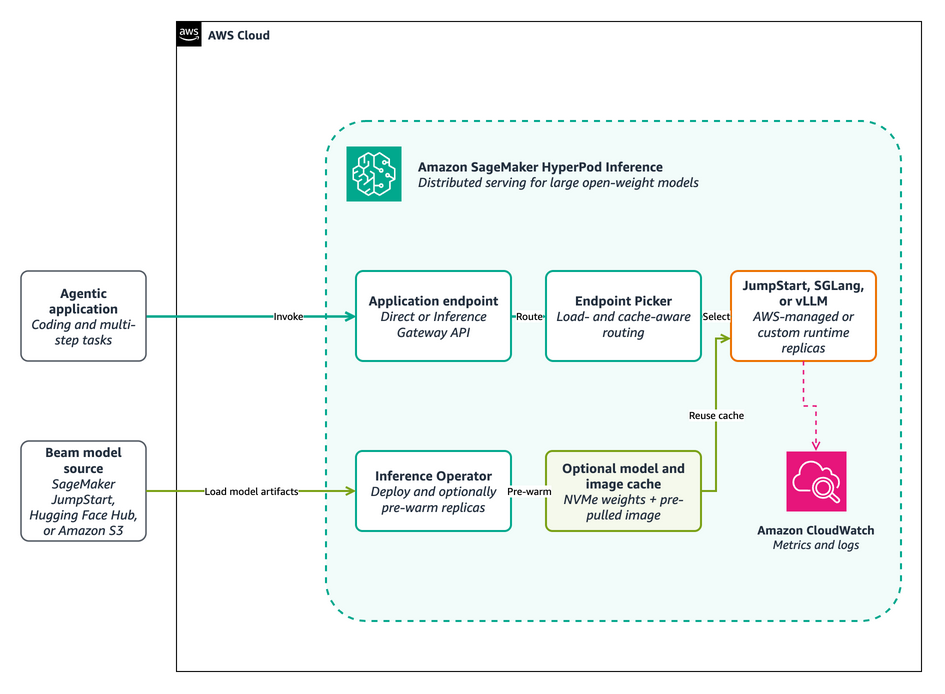
Determine 1: Distributed Beam deployment with Amazon SageMaker HyperPod Inference
Conditions
You want:
- An AWS account with permissions in your chosen SageMaker deployment path and its supporting AWS Id and Entry Administration (IAM), networking, and storage sources.
- Entry to Beam by means of SageMaker JumpStart or one of many Beam 1.0 checkpoint repositories on Hugging Face.
- Acceptance of the mannequin phrases, the AWS Command Line Interface (AWS CLI), and Python 3.11 or later.
- GPU quota and capability for a supported Beam configuration.
Plan and procure GPU capability
Beam’s 501 billion complete parameters require a multi-GPU deployment. BF16 has the biggest weight-memory requirement, so plan a multi-node configuration with sufficient combination GPU reminiscence for the weights and runtime overhead. For FP8, use ml.p5.48xlarge with NVIDIA H100 GPUs or ml.p5e.48xlarge and ml.p5en.48xlarge with H200 GPUs. For NVFP4, use ml.p6-b200.48xlarge with NVIDIA B200 GPUs. Affirm that the launched checkpoint, runtime, and parallel structure help the chosen occasion kind.
- Calculate reminiscence for weights, KV cache, and runtime overhead for one duplicate, then affirm the estimate with a load check.
- Select an AWS Area that helps the required accelerated occasion.
- Verify the service quota and accessible capability for the chosen occasion kind. Use on-demand capability when accessible, or use a SageMaker coaching plan as a short-term reservation for scheduled work.
- Enable time for picture switch, weight obtain, shard loading, and runtime initialization.
Path 1: Get began with a SageMaker JumpStart real-time endpoint
Use a JumpStart real-time endpoint first whenever you need the shortest path from the mannequin catalog to a managed HTTPS endpoint. The pattern helps the BF16, FP8, and NVFP4 mannequin IDs by means of one variant-aware command. Its README and Python file are the supply of reality for supported occasion varieties, request schema, deployment command, and cleanup command.
- Clone the pattern repository.
- Enter the SageMaker JumpStart deployment pattern listing.
- Create and activate a Python digital atmosphere.
- Set up the pattern dependency.
- Run the bounded deployment, invocation, and cleanup lifecycle for FP8.
The command deploys the FP8 endpoint, sends a brief request, prints the response, and cleans up the endpoint. Use
bf16ornvfp4to pick one other checkpoint variant; NVFP4 is the default whenever you omit--variant. Use the Python features within the README when it is advisable to preserve an endpoint working.
Path 2: Deploy with SageMaker HyperPod Inference
Use HyperPod Inference whenever you want Kubernetes-native management over distributed GPU infrastructure. You should use the AWS managed JumpStart container configuration or deploy Beam with SGLang or vLLM. The HyperPod Inference deployment pattern README and its configuration recordsdata are the supply of reality for launched manifests, mannequin and picture identifiers, supported runtime variations, and instructions.
Earlier than you start, configure kubectl entry to an EKS-orchestrated HyperPod cluster with the HyperPod Inference Operator and required add-ons. You additionally want the cluster digital non-public cloud (VPC), subnets, safety teams, entry to the chosen Beam and runtime artifacts, and native NVMe capability should you allow mannequin caching. Use an remoted Hugging Face entry token if the chosen repository requires authentication.
Deploy a pinned Beam revision from Hugging Face Hub for improvement and experimentation. For manufacturing deployments and mannequin caching, copy the checkpoint to Amazon S3 or Amazon FSx. HyperPod mannequin and picture caching can preload weights onto node-local NVMe storage and pre-pull the serving picture.
The HyperPod Inference Gateway offers an OpenAI-compatible interface and routes requests throughout replicas. HyperPod Inference additionally helps managed tiered KV caching and clever routing. These are among the many Amazon SageMaker Inference capabilities launched in 2026.
The following diagram expands the mannequin preparation and runtime request stream. When mannequin caching is enabled, the Inference Operator warms eligible nodes with the chosen weights and serving picture. At runtime, the Inference Gateway and Endpoint Picker can direct every request to an appropriate JumpStart-managed, SGLang, or vLLM duplicate.
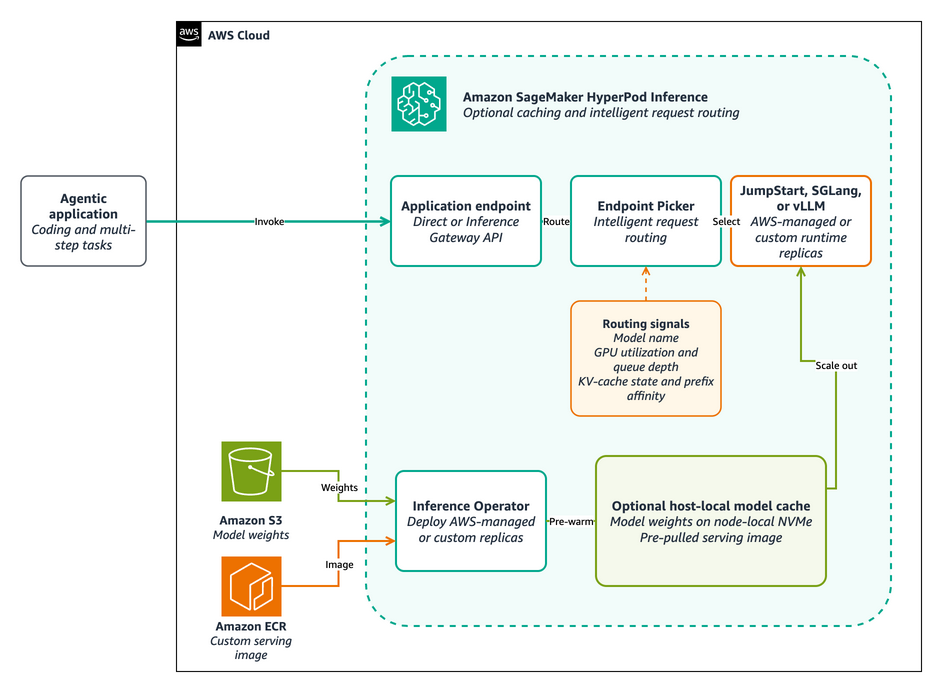
Determine 2: HyperPod mannequin caching and request routing
Put together deployment artifacts
Use immutable inputs so that you could reproduce deployment and efficiency outcomes.
- Use the JumpStart mannequin launch recorded within the deployment pattern.
- Select the BF16, FP8, or NVFP4 checkpoint for a customized runtime.
- For a customized runtime, preserve the general public Beam commit SHA and picture digest within the pattern launch configuration.
- Mirror the launched picture into a non-public Amazon Elastic Container Registry (Amazon ECR) repository solely when your cluster can not pull the upstream picture or your group requires an authorised registry.
- Maintain tokens, generated secrets and techniques, non-public mannequin IDs, registry credentials, and unpublished outcomes out of the repository.
Select a serving path
Begin with SageMaker JumpStart until your workload requires a particular inference runtime or configuration.
| Serving path | Use it when | What you handle |
| SageMaker JumpStart | You need an AWS-managed container and mannequin configuration with much less runtime upkeep. | Choose the Beam mannequin model, supported occasion kind, endpoint configuration, and scaling coverage. |
| SGLang or vLLM | You want a particular inference runtime or configuration, similar to customized runtime arguments, parsers, quantization, or parallelism. | Pin the supported runtime picture, mannequin revision, parser configuration, and distributed execution settings. |
Deploy with SageMaker JumpStart
SageMaker JumpStart reduces container integration work whereas HyperPod retains management over cluster capability, scaling, and observability.
- In SageMaker Studio, open the JumpStart mannequin catalog.
- Below All public fashions, select Beam.
- Select SageMaker HyperPod because the deployment goal.
- Choose the cluster and Kubernetes namespace.
- Enter an endpoint identify, and select Deploy.
- Affirm the deployment standing earlier than invoking the endpoint with the launched JumpStart request schema.
For an infrastructure-as-code workflow, use the launched JumpStart configuration within the HyperPod pattern. You’ll be able to examine the reflection-beam-jumpstart.yaml manifest template earlier than configuring the deployment.
- Clone the pattern repository, and enter the HyperPod Beam listing.
- Create the native configuration recordsdata described within the README.
- Validate the JumpStart configuration earlier than altering the cluster.
- Deploy the JumpStart configuration.
The helper renders and applies the launched JumpStartModel useful resource with out writing populated launch values to disk.
Deploy with SGLang or vLLM
Select SGLang or vLLM whenever you want direct management over the serving runtime. Earlier than configuring the deployment, examine the reflection-beam-sglang.yaml manifest template or the reflection-beam-vllm.yaml manifest template. The pattern README stays the supply of reality for launched values and instructions.
- Clone the pattern repository.
- Enter the HyperPod Beam listing.
- Create the native configuration recordsdata described within the README.
- Validate the chosen configuration earlier than altering the cluster.
- Deploy Beam, and watch for a terminal deployment state.
Exchange
sglangwithvllmto make use of vLLM. The helper validates the chosen settings, applies the rendered manifest with out writing launch values to disk, waits with a set timeout, and prints diagnostics if deployment fails.
Invoke Beam
Invoke JumpStart endpoints with the launched mannequin request schema. For SGLang or vLLM, use the bounded smoke check included within the HyperPod pattern.
Invoke the deployed endpoint
- Set up the pattern shopper dependency.
- Run a non-public well being test and brief request with the beneficial beginning sampling settings.
Exchange
sglangwithvllmfor a vLLM deployment. The helper selects a prepared employee, opens a short lived port-forward, checks endpoint well being, sends the request, and closes the port-forward.
The response resembles the next:
For an authenticated Inference Gateway, use the bearer-token process within the HyperPod pattern README. Maintain credentials out of supply code, manifests, and command historical past.
Measure and tune efficiency
- Check every serving path with repeated, consultant coding and tool-use requests on the anticipated concurrency.
- Document the Beam mannequin model, picture digest, occasion kind, precision, context size, parallelism, serving arguments, cache state, and check repetitions.
- Measure request success fee, p50 and p95 time to first token, time per output token, end-to-end latency, and combination output tokens per second.
- Tune batch measurement, KV cache allocation, duplicate depend, autoscaling, and mannequin and picture caching from these outcomes.
- Recheck output high quality after altering precision or quantization.
Clear up
Delete sources whenever you end testing to keep away from ongoing costs.
- For a SageMaker JumpStart real-time endpoint, observe the cleanup directions within the SageMaker JumpStart deployment pattern README.
- For JumpStart, SGLang, or vLLM on Amazon SageMaker HyperPod Inference, observe the cleanup directions within the HyperPod Inference deployment pattern README.
- Delete a devoted HyperPod or Amazon EKS cluster created for the walkthrough.
- Delete unused cached weights, mirrored artifacts, load balancers, log teams, momentary IAM roles, and captured inference information.
Conclusion
Reflection Beam offers builders an open-weight mannequin designed for agentic coding and multi-step duties. Begin with a SageMaker JumpStart real-time endpoint for a completely managed deployment. Use SageMaker HyperPod Inference with JumpStart whenever you want Kubernetes-native infrastructure management with out managing the serving container, or select SGLang or vLLM whenever you want a customized runtime.
Use the SageMaker JumpStart deployment pattern or the HyperPod Inference deployment pattern, then observe the directions.
To study extra about Reflection AI and its imaginative and prescient for open intelligence, go to Reflection AI and browse Introducing Beam.
Assets
Concerning the authors