SageMaker Inference now helps Multi-Occasion GPU to maximise GPU utilization for mannequin endpoints
Once you deploy a mannequin to a GPU endpoint, the smallest unit of GPU you possibly can request is one ...
Once you deploy a mannequin to a GPU endpoint, the smallest unit of GPU you possibly can request is one ...
On this article, you'll discover ways to match an LLM inference optimization approach to the precise bottleneck in your workload ...
On this article, you'll find out how speculative decoding works, why it produces actual pace features on the {hardware} stage, ...
Single-Area inference can throttle when demand exceeds native capability. Groups in Thailand, Malaysia, Singapore, Indonesia, and Taiwan want entry to ...
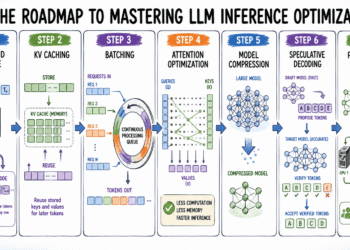
The Roadmap to Mastering LLM Inference Optimization - MachineLearningMastery.com The Roadmap to Mastering LLM Inference Optimization The Roadmap to Mastering ...
When Salesforce got down to make Agentforce (Salesforce’s AI basis for brokers) extremely out there (HA) throughout a number of ...
This publish is co-written with Chris Dickens from OpenAI. Amazon Bedrock now gives OpenAI GPT-5.6 fashions on Amazon Bedrock in ...

Monitoring and troubleshooting generative AI inference endpoints working at scale is difficult. When your massive language mannequin (LLM) endpoint’s P99 ...

In the present day, we’re saying inline payload help for Amazon SageMaker AI Async Inference. Prospects can now ship inference ...

"""Steady batching = iteration-level scheduling + ragged (packed) batching. Two approaches are in contrast (each run BATCH_SIZE sequences concurrently, so thecomparability ...