
A number of groups throughout the identical firm more and more want shared entry to costly GPU clusters for his or her generative AI operations, whereas sustaining isolation boundaries, useful resource equity, and operational independence. Think about an information science group coaching giant language fashions, a pc imaginative and prescient group operating inference workloads, and a analysis group experimenting with new mannequin architectures. All of them may want entry to the identical cluster. With no well-designed multi-tenant (multi-team) structure, organizations face uncontrolled useful resource consumption, weak isolation between groups, an incapacity to attribute shared GPU prices to the groups that incur them, and administrative overhead that slows down innovation.
Amazon SageMaker HyperPod is a purpose-built AI service that simplifies the administration of large-scale compute clusters for gen AI workloads. It supplies resilient, optimized clusters orchestrated by Amazon Elastic Kubernetes Service (Amazon EKS) or Slurm, so organizations can run distributed coaching, interactive improvement, and mannequin inference at scale. On the identical time, it robotically handles node well being monitoring, fault restoration, and cluster lifecycle administration.
On this publish, we current a reference structure for constructing a multi-tenant atmosphere on Amazon SageMaker HyperPod with EKS. This structure makes use of AWS IAM Identification Heart for centralized authentication, per-team SageMaker AI domains for a tailor-made person expertise, Kubernetes namespaces for workload isolation, HyperPod Activity Governance for truthful useful resource allocation, and namespace-level price allocation for per-team spend visibility and chargeback. By the top of this publish, you’ll have a transparent blueprint for a number of groups to effectively share a single HyperPod EKS cluster.
Structure overview
The next diagram illustrates the high-level structure of a multi-tenant HyperPod EKS deployment. On this instance, two groups (Workforce A and Workforce B) share a single HyperPod EKS cluster, every working inside their very own remoted namespace.
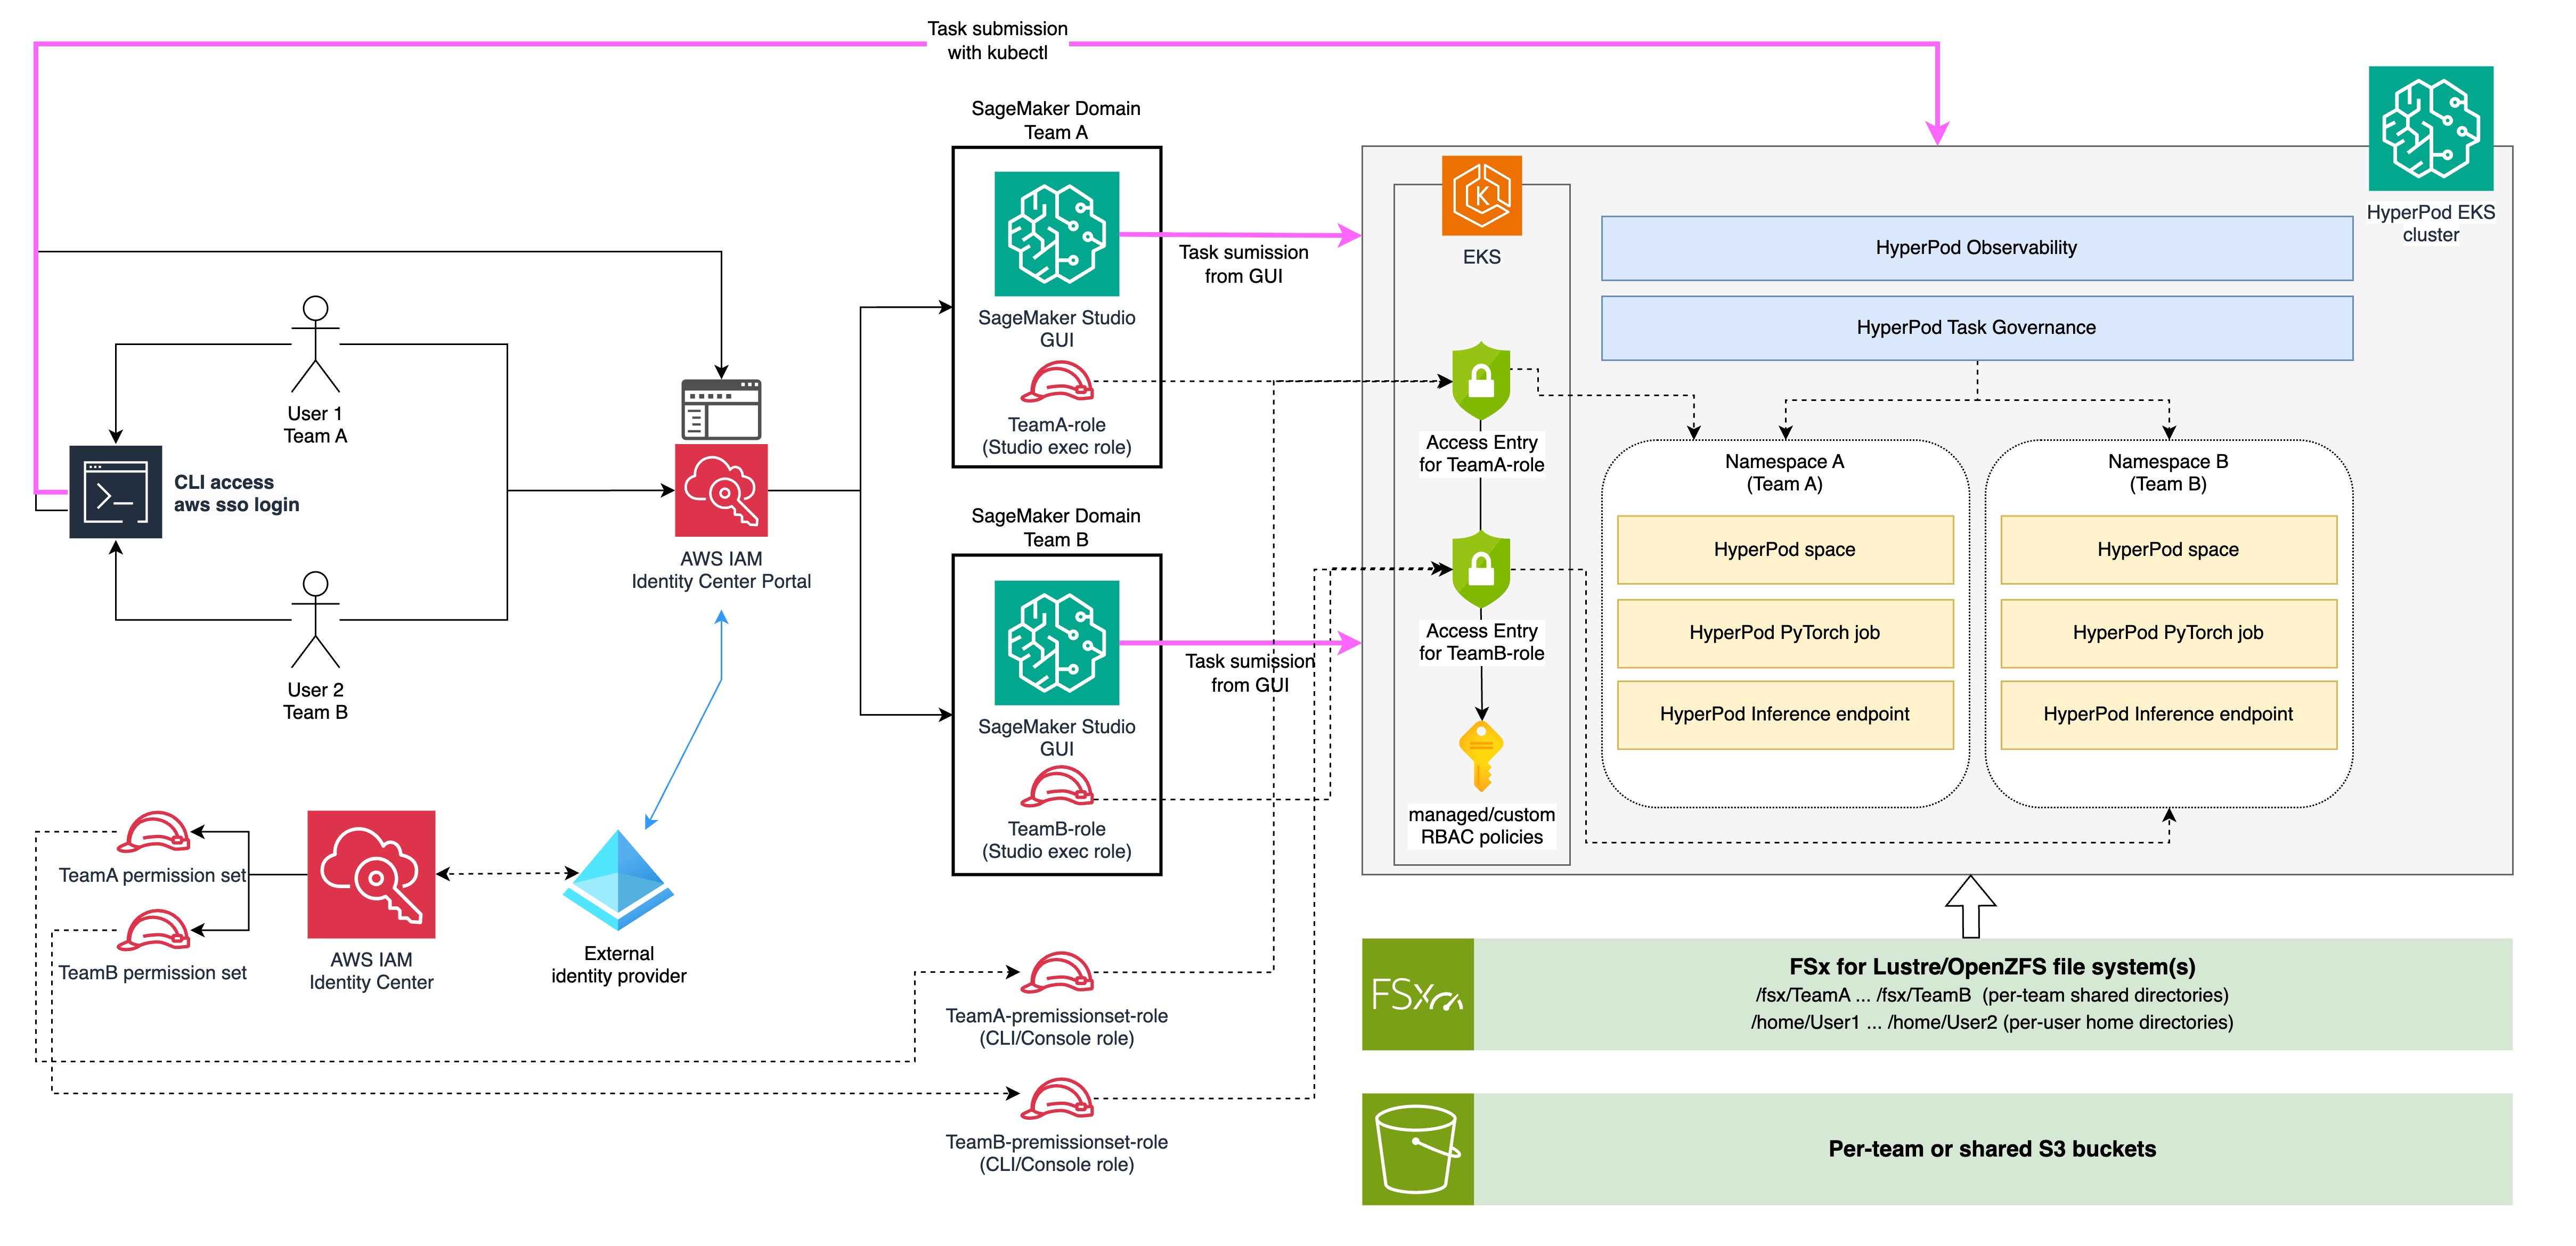
Determine 1: Excessive-level multi-tenant structure for 2 groups sharing one HyperPod EKS cluster
The structure is structured as a layered circulation from left to proper, connecting person id by authorization controls and into remoted workload namespaces on the cluster.
Customers and authentication
On the far left, particular person customers from every group (Person 1 from Workforce A, Person 2 from Workforce B) work together with the system by two paths. Each paths authenticate by the AWS IAM Identification Heart Portal, which federates with an exterior id supplier (akin to Microsoft Entra ID) proven on the bottom-left.
The primary path is thru CLI entry. Customers authenticate with aws sso login, which redirects them to the Identification Heart portal, after which receive momentary credentials from their group’s permission set to submit duties on to the EKS cluster with kubectl. Within the diagram, the pink arrow flows from the CLI terminal throughout the highest straight into the HyperPod EKS cluster.
The second path is thru the Identification Heart portal straight, the place customers choose the SageMaker Studio software to sign up to their team-specific SageMaker AI area.
Every group has a corresponding permission set (TeamA permission set, TeamB permission set) that carries the AWS Identification and Entry Administration (IAM) insurance policies wanted for CLI workflows. Identification Heart robotically provisions an IAM function for every permission set, proven within the diagram as TeamA-permissionset-role and TeamB-permissionset-role (labeled “CLI/Console function”). This function serves because the IAM principal when customers authenticate by aws sso login.
SageMaker AI domains
From the Identification Heart portal, customers are routed to their team-specific SageMaker AI area. Every area (SageMaker AI area Workforce A and SageMaker AI area Workforce B) supplies a devoted Amazon SageMaker Studio GUI and is configured with a team-specific execution function (TeamA-role and TeamB-role respectively). These domains function the first workspace interface, so customers can submit duties from the GUI (proven by the pink arrows flowing towards EKS).
EKS entry management
On the EKS boundary, entry entries map IAM roles to Kubernetes permissions. The diagram reveals entry entries for TeamA-role and TeamB-role (the Studio execution roles), which authorize requests originating from the SageMaker Studio GUI. Entry entries should even be configured for the Identification Heart-provisioned CLI/Console roles (TeamA-permissionset-role and TeamB-permissionset-role) to authorize requests arriving by kubectl. All entry entries are related to managed or {custom} role-based entry management (RBAC) insurance policies (represented by the important thing icon) and scoped to the group’s designated namespace. In consequence, whether or not entry originates from Studio or the CLI, customers can solely work together with assets in their very own namespace.
HyperPod EKS cluster
The cluster itself is depicted with two cross-cutting platform layers on the prime: HyperPod Observability (for monitoring and dashboards) and HyperPod Activity Governance (for compute quota administration and scheduling priorities). Beneath these layers, the cluster is partitioned into Namespace A (Workforce A) and Namespace B (Workforce B). Inside every namespace, groups can run their very own HyperPod Areas (interactive improvement environments), HyperPod PyTorch jobs (distributed coaching workloads), and HyperPod Inference endpoints (mannequin serving).
Storage
Beneath the cluster, the structure consists of two storage tiers. The primary is a POSIX-compliant file system (Amazon FSx for Lustre or Amazon FSx for OpenZFS) organized into per-team shared directories (/fsx/TeamA, /fsx/TeamB) and per-user residence directories (/residence/User1, /residence/User2). The second is per-team or shared Amazon Easy Storage Service (Amazon S3) buckets for object storage, ruled by the group’s IAM execution function.
This structure isolates every group from authentication by authorization to workload execution, whereas sharing costly GPU infrastructure effectively.
Authentication and entry management
The inspiration of any multi-tenant system is powerful authentication: verifying who customers are earlier than they work together with any useful resource. On this structure, AWS IAM Identification Heart serves because the centralized authentication layer, federating with an exterior id supplier to handle person identities and group memberships.
Why AWS IAM Identification Heart
AWS IAM Identification Heart (successor to AWS Single Signal-On) supplies a single place to handle workforce identities throughout AWS accounts and functions. For a multi-tenant HyperPod deployment, it provides a number of key capabilities:
- Centralized id administration – Slightly than sustaining separate person databases per AWS service, Identification Heart supplies a single supply of reality for all person identities and their group memberships.
- Federation with current id suppliers – Most enterprises already handle their workforce identities in programs like Microsoft Entra ID (previously Azure AD), Okta, or Ping Identification. Identification Heart integrates with these suppliers, so organizations can reuse their current id infrastructure with out duplicating person accounts.
- Native integration with SageMaker AI – SageMaker AI domains help Identification Heart authentication, so customers can sign up to SageMaker Studio by their company id supplier with single sign-on (SSO).
- AWS account entry – Identification Heart also can grant customers entry to the underlying AWS account with particular permission units, which help CLI workflows alongside the Studio GUI expertise.
- Required for Amazon Managed Grafana – Amazon Managed Grafana makes use of Identification Heart as its authentication mechanism for workforce customers, making it the pure alternative when groups additionally want entry to observability dashboards for monitoring their workloads.
Study extra: What’s IAM Identification Heart
Configuring Identification Heart with an exterior id supplier
On this reference structure, we use Microsoft Entra ID because the exterior id supplier, although the identical sample applies to most traditional Safety Assertion Markup Language (SAML) 2.0 suppliers.
The configuration entails:
- Group construction within the id supplier – In Entra ID, create teams that correspond to your organizational groups. In our instance, we outline three teams:
TeamA,TeamB, andAdmin. Every group accommodates the customers belonging to that group (for instance,user1-teamA@instance.comwithin theTeamAgroup). - SCIM provisioning – Allow SCIM (System for Cross-domain Identification Administration) synchronization between Entra ID and AWS IAM Identification Heart. SCIM supplies computerized provisioning and de-provisioning of customers and teams. When a brand new person is added to the
TeamAgroup in Entra ID, they’re robotically synchronized to Identification Heart and achieve applicable entry with out handbook intervention. - SAML-based authentication – Configure SAML 2.0 federation in order that when customers authenticate, they accomplish that towards Entra ID. Identification Heart acts because the service supplier, trusting the assertions out of your Entra ID tenant.
With this configuration, you handle group membership (which drives all downstream authorization selections) in your current company listing, and it propagates to AWS robotically.
The next picture reveals an instance of how organizational groups will be represented in Microsoft Entra ID, with devoted teams for TeamA, TeamB, and Admin.
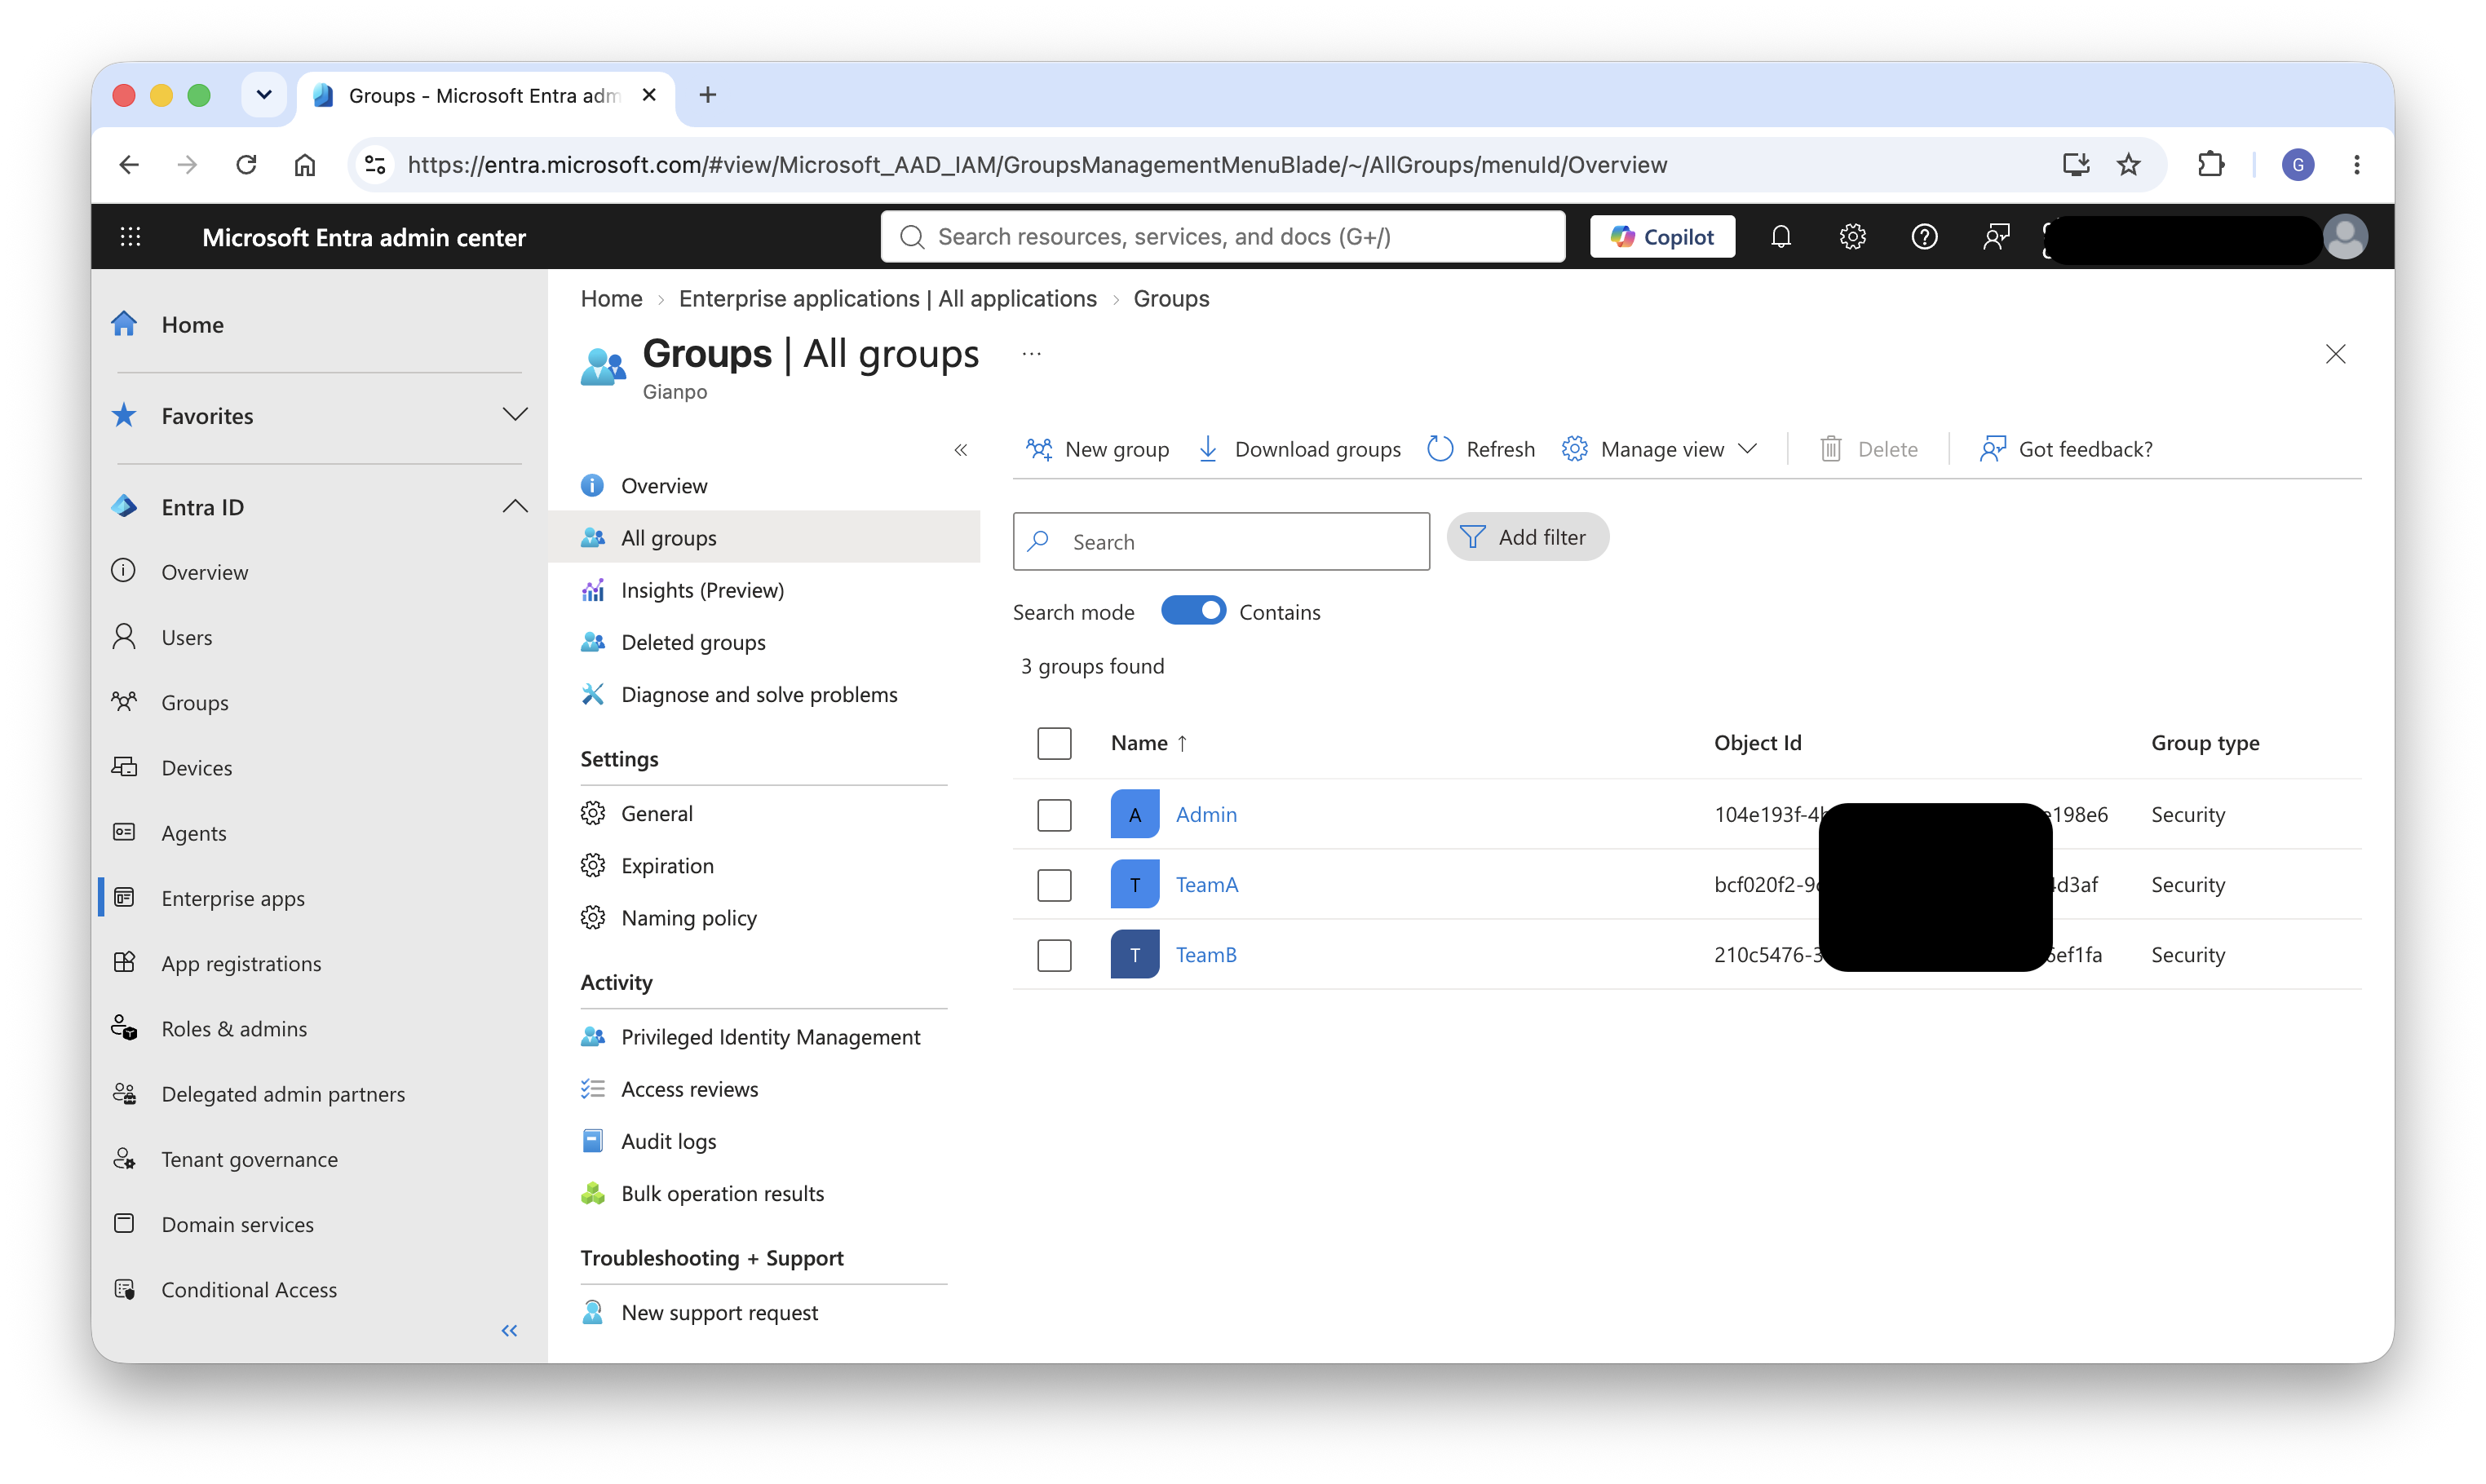
Determine 2: Organizational groups represented as teams in Microsoft Entra ID
Then, the next picture reveals the corresponding teams in AWS IAM Identification Heart, robotically provisioned from Entra ID by SCIM synchronization.
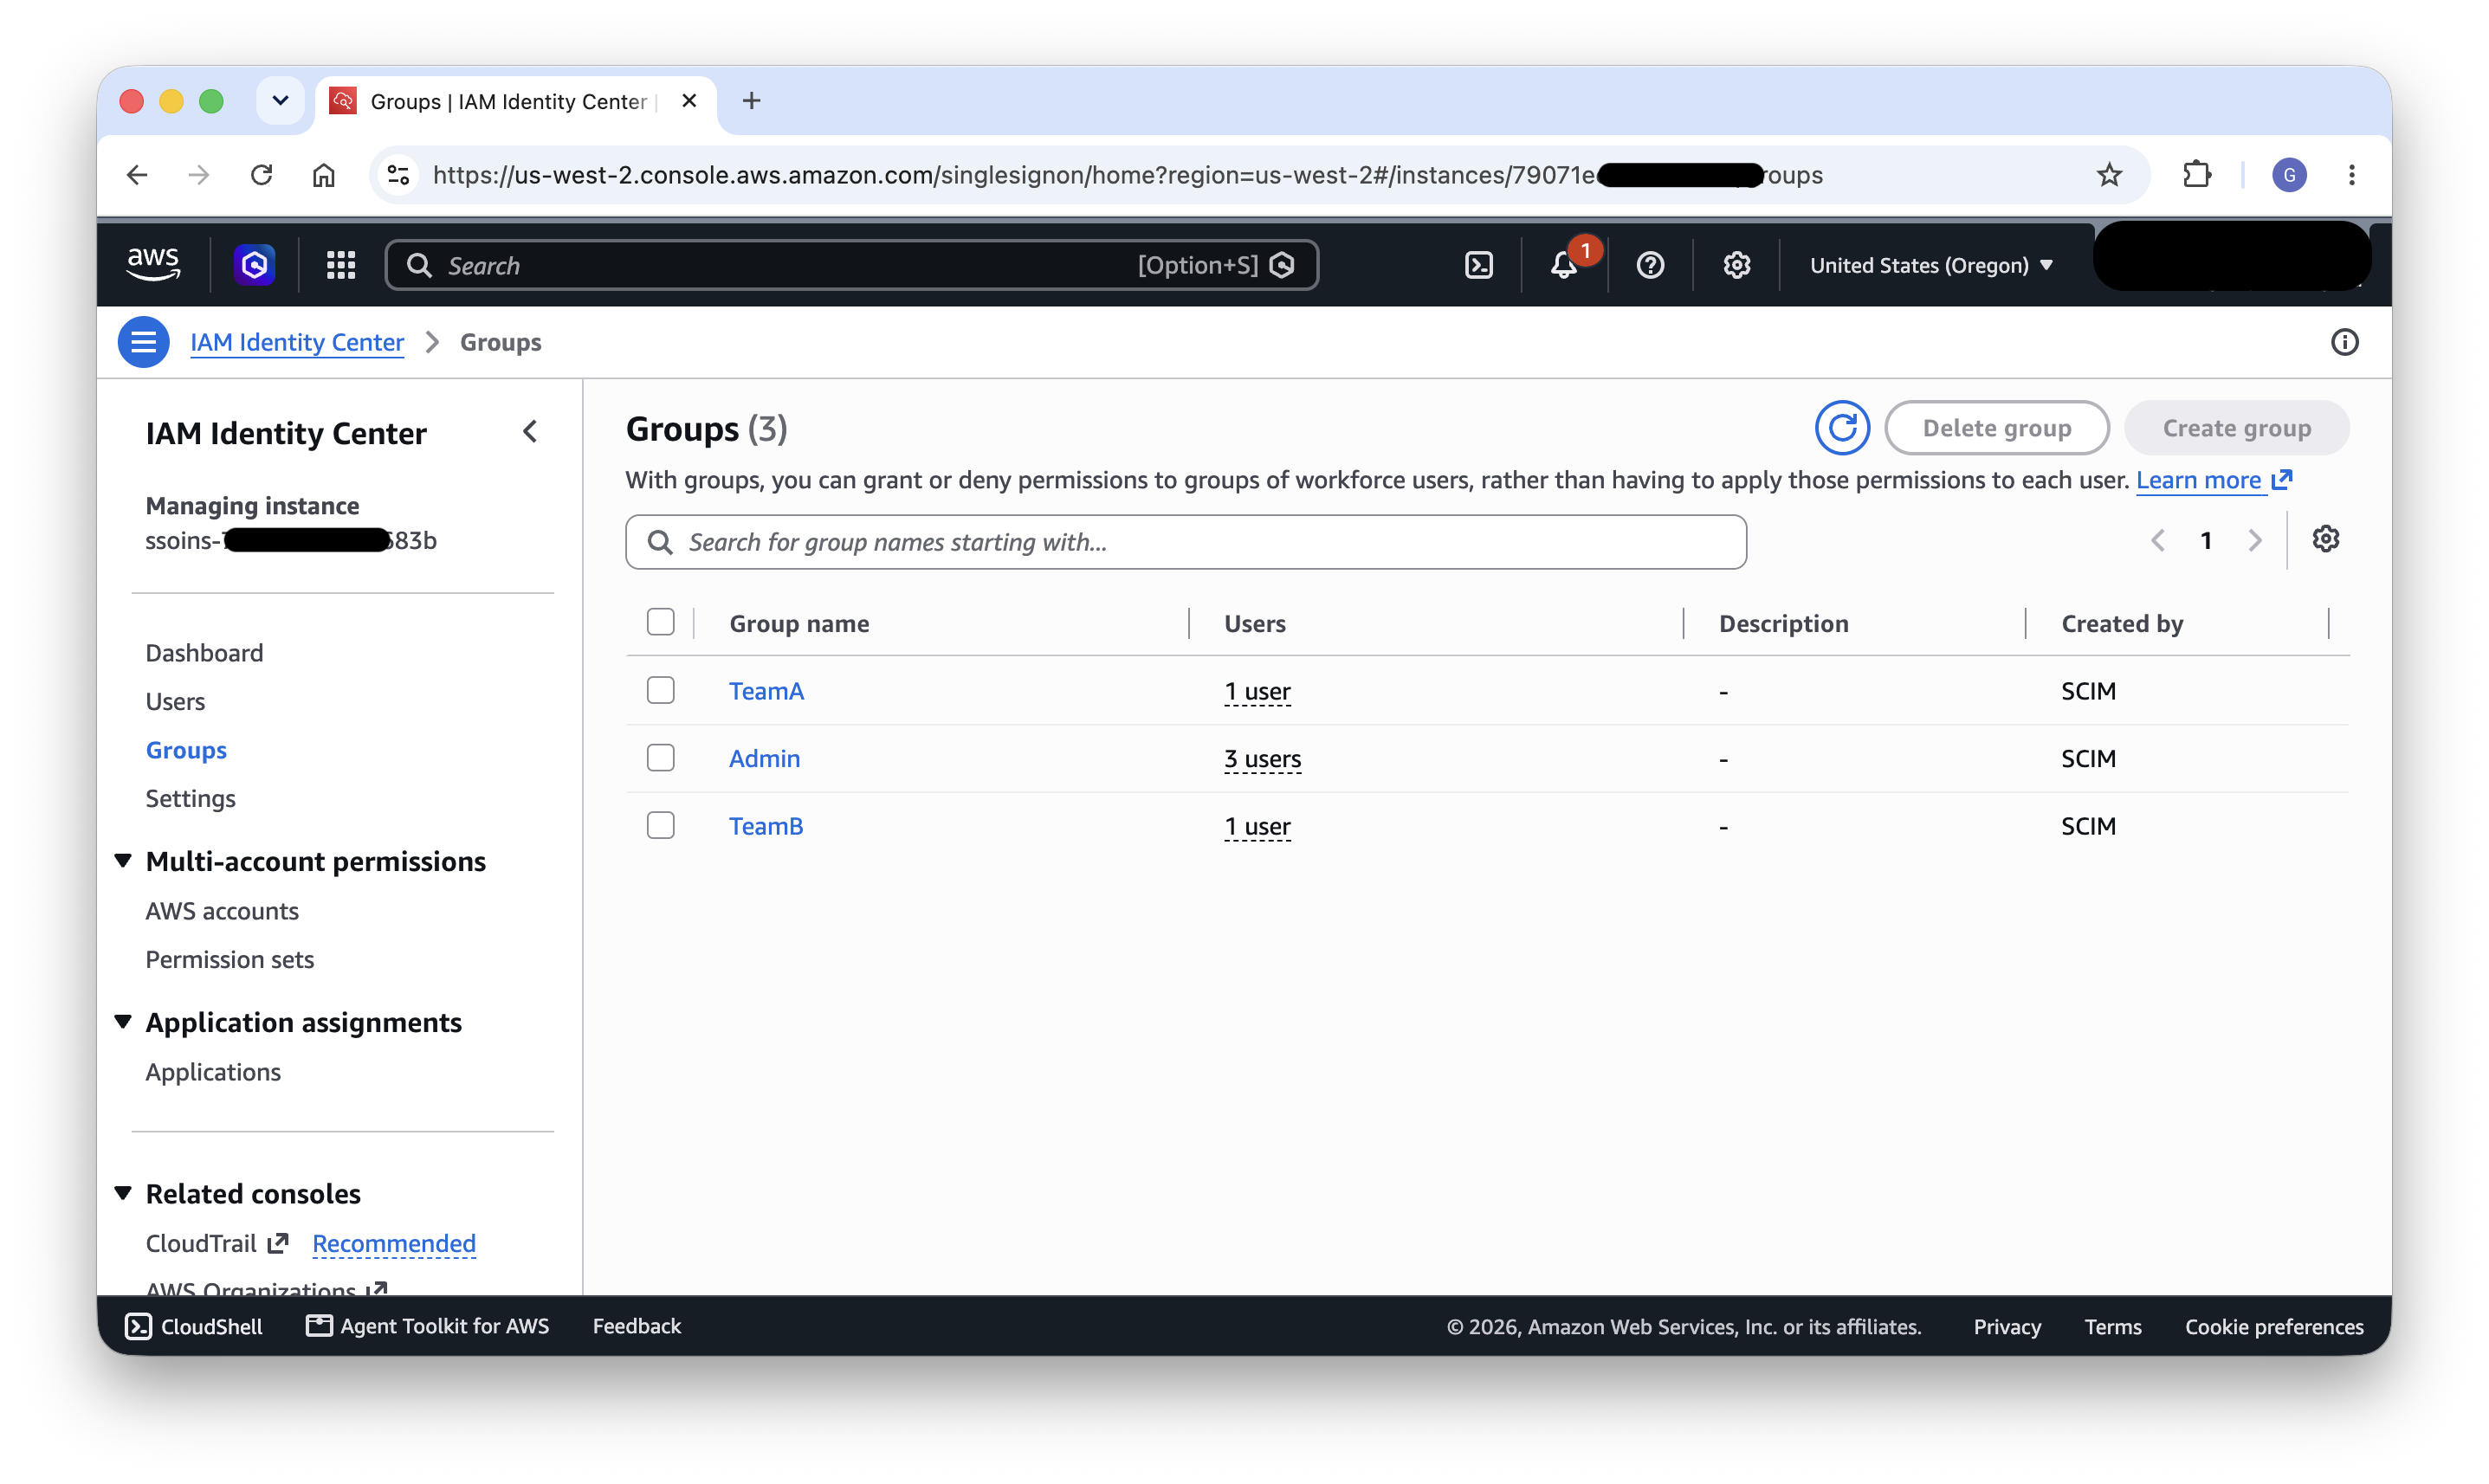
Determine 3: Corresponding teams in AWS IAM Identification Heart, provisioned by SCIM
Study extra: Join an exterior id supplier · SCIM profile and SAML 2.0 implementation
Authorization
With authentication established, the subsequent layer is authorization: controlling what actions every group can carry out throughout AWS companies and the Kubernetes cluster. Authorization on this structure operates at two ranges: IAM for service-level entry, and Kubernetes RBAC for cluster-level entry.
Per-team IAM roles
Every group requires a devoted IAM function that encapsulates the AWS degree permissions wanted for his or her AI and machine studying (ML) workflows. These roles function the SageMaker AI area execution function and outline what AWS companies the group can entry.
A typical group IAM function ought to embody insurance policies granting entry to:
- Amazon SageMaker AI – For managing HyperPod clusters, MLflow monitoring servers, and different SageMaker AI assets by the SageMaker AI API.
- Amazon S3 – For studying coaching datasets and writing mannequin artifacts, checkpoints, and logs. Scope these permissions to team-specific bucket prefixes.
- Amazon CloudWatch – For viewing logs and metrics associated to the group’s workloads.
- Amazon EKS – Particularly, the
eks:AccessKubernetesApiandeks:MutateViaKubernetesApipermissions, which the SageMaker Studio GUI must make Kubernetes API calls on behalf of the person (for instance, itemizing Areas or submitting jobs).
The belief coverage on every IAM function should embody sagemaker.amazonaws.com as a trusted principal, so SageMaker AI can assume the function on behalf of customers after they function by Studio. For those who plan to reuse the identical execution function as an EKS Pod Identification affiliation for in-cluster workloads (as mentioned later within the Amazon S3 storage part), the belief coverage should additionally embody pods.eks.amazonaws.com as a trusted principal. CLI entry by Identification Heart makes use of a separate permission set with its personal insurance policies (see the “AWS account entry by Identification Heart” part), so CLI permissions will be independently scoped.
Study extra: use SageMaker AI execution roles
AWS account entry by Identification Heart
Past SageMaker Studio, groups typically want direct AWS account entry for CLI operations akin to operating kubectl instructions, scripting workflows, or accessing assets programmatically. Identification Heart permission units present this functionality.
For the Admin group, assign a permission set with administrative entry as required by your organization’s insurance policies, granting the mandatory account entry for cluster administration and administrative operations.
For Workforce A and Workforce B, create permission units with inline or managed insurance policies that grant the permissions wanted for CLI workflows straight. A typical group permission set consists of permissions for eks:AccessKubernetesApi (to view Kubernetes assets from AWS Console), scoped S3 entry for the group’s information, and CloudWatch learn entry for monitoring. These insurance policies are outlined independently from the Studio execution function, so directors can tailor CLI permissions to the particular operations that groups carry out from the command line.
Customers retrieve momentary credentials by the AWS Command Line Interface (AWS CLI) utilizing aws sso login, which they’ll then use to configure kubectl for direct interplay with the EKS cluster.
The next picture reveals the per-team permission units in AWS IAM Identification Heart, offering scoped AWS account entry for CLI workflows akin to operating kubectl and aws sso login towards the EKS cluster.
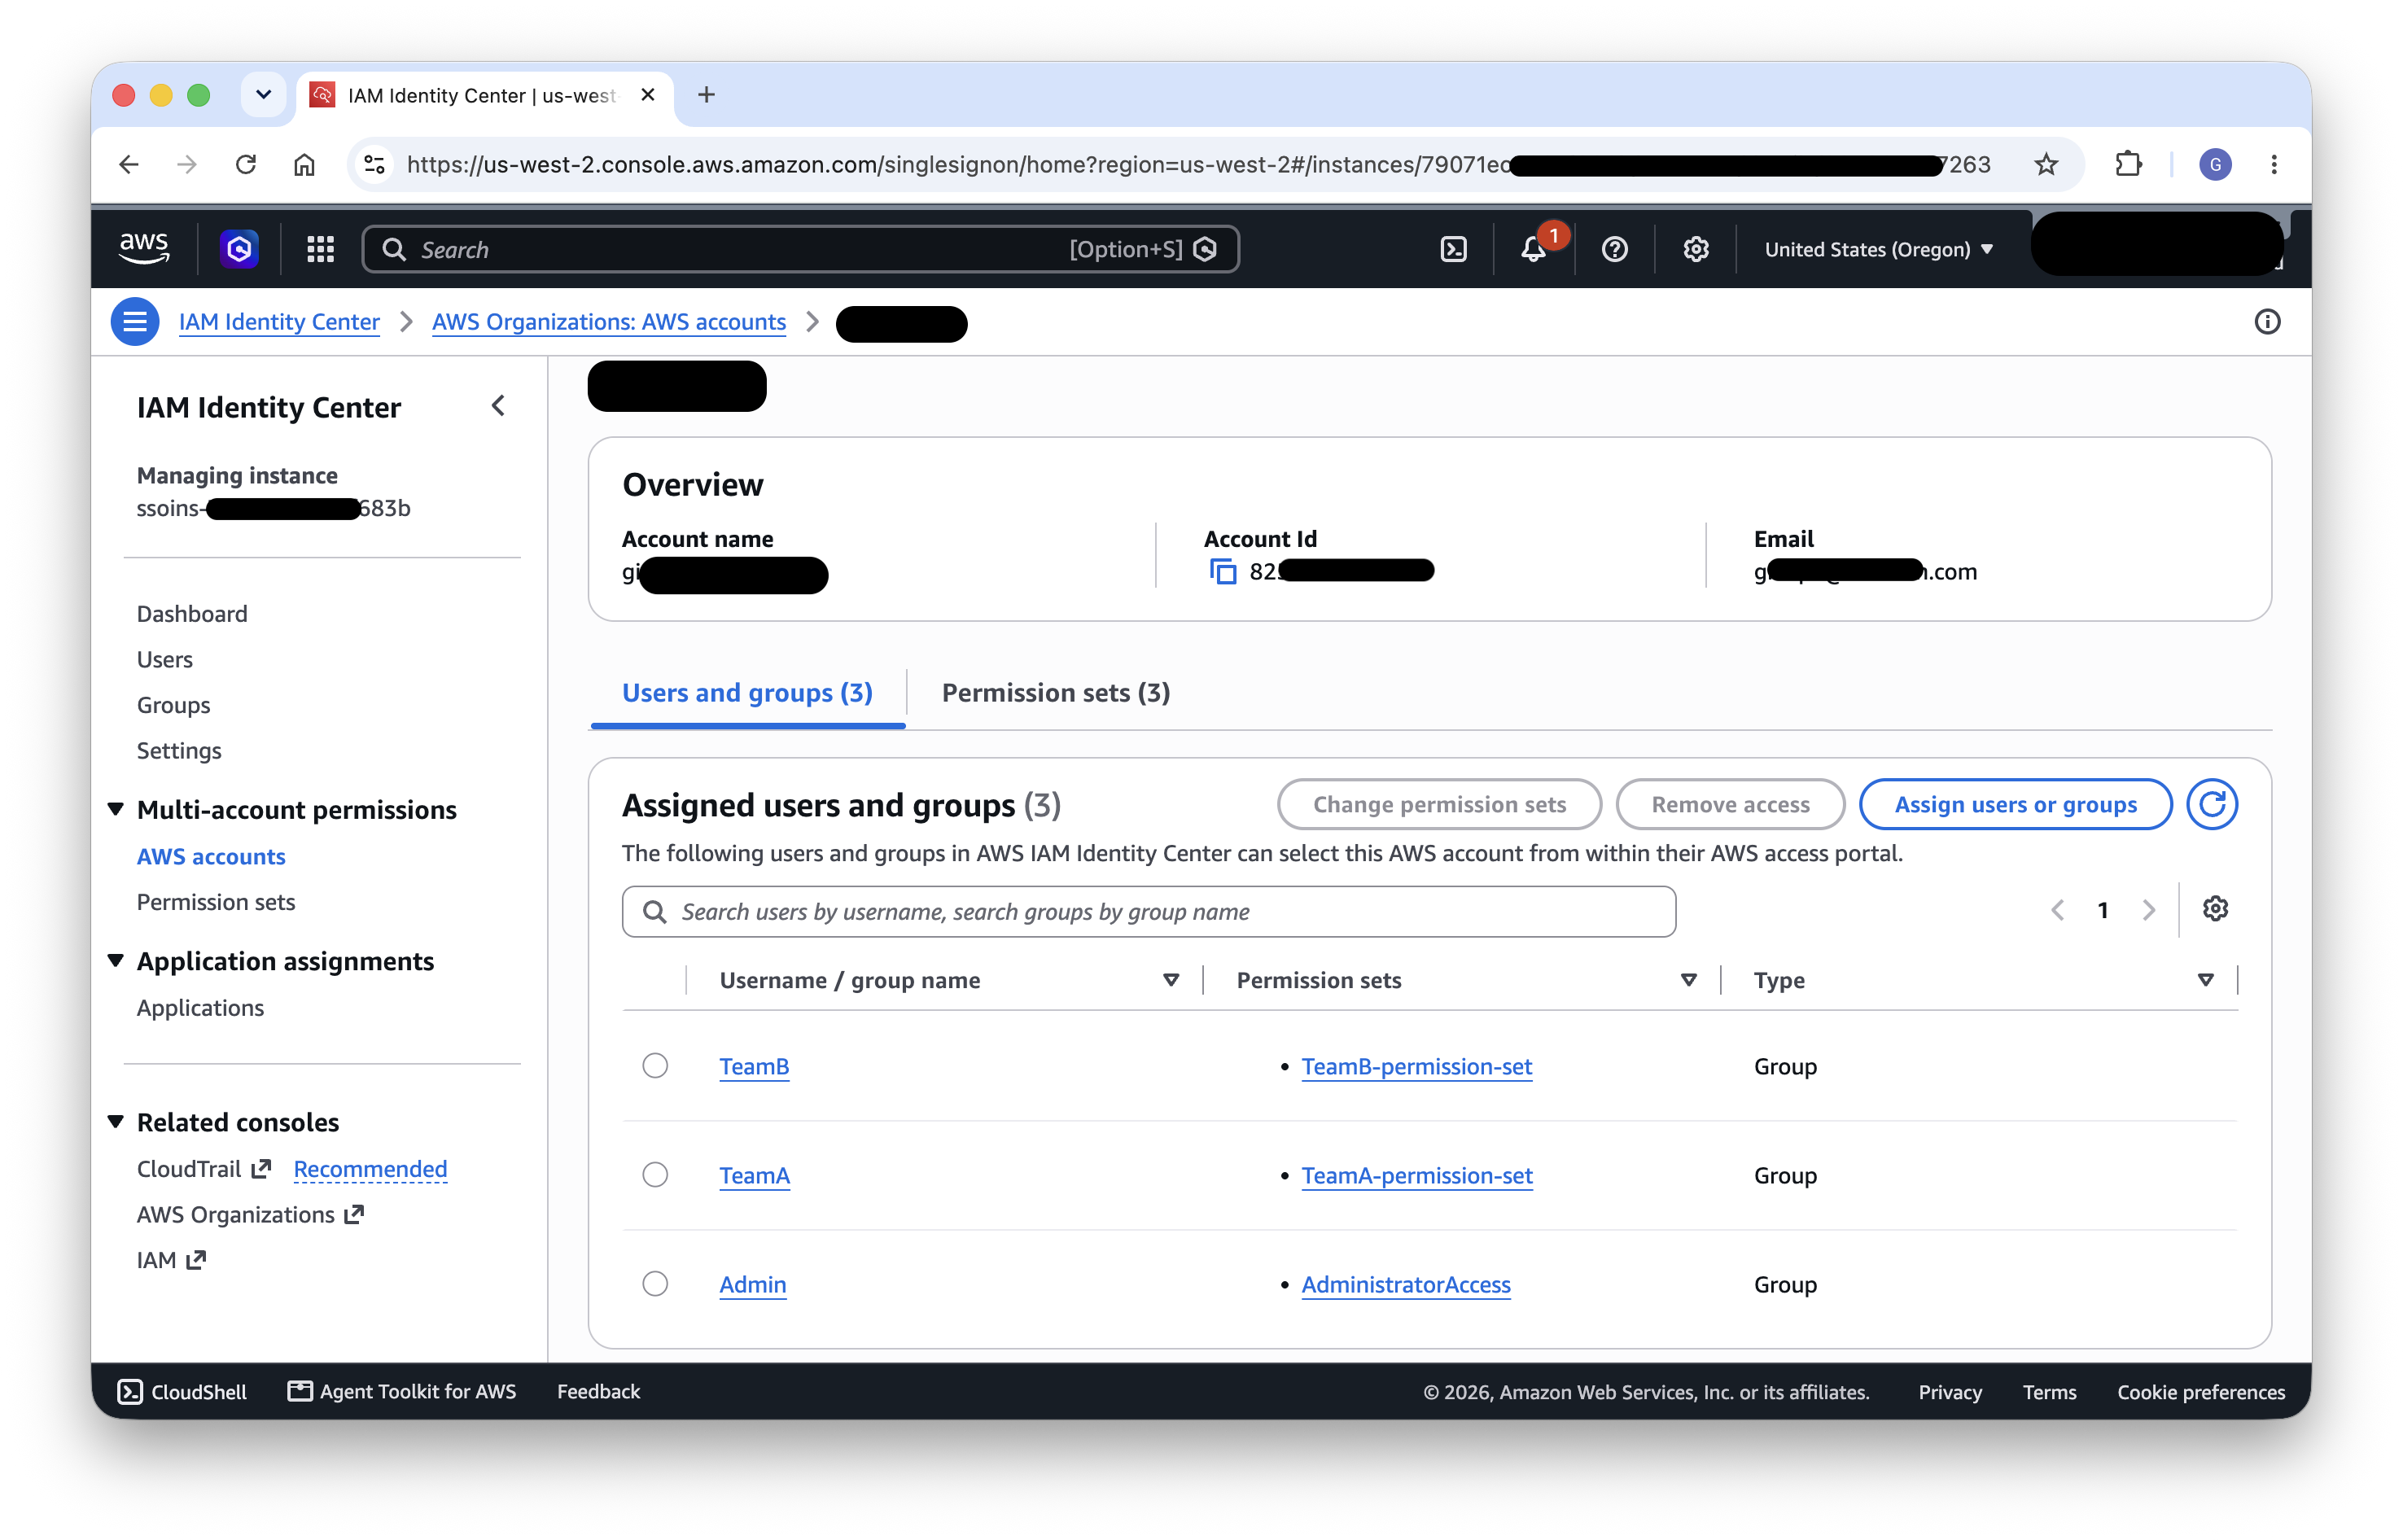
Determine 4: Per-team permission units in AWS IAM Identification Heart for CLI workflows
Study extra: Handle AWS accounts with permission units
Configuring the AWS CLI
Workforce members configure the AWS CLI to authenticate by Identification Heart by operating aws configure sso. This creates profiles in ~/.aws/config that reference the suitable Identification Heart session and permission set. Every group member makes use of their team-specific profile when interacting with the cluster from the command line, sustaining authorization boundaries whether or not entry originates from Studio or from an area terminal.
The ensuing configuration defines a shared sso-session block for the Identification Heart portal and one named profile per group, every pointing at that group’s permission set. Workforce members then run aws sso login --profile to acquire momentary credentials scoped to their permission set:
Study extra: Configuring IAM Identification Heart authentication with the AWS CLI
SageMaker AI domains
SageMaker AI domains present the workspace boundary for every group, providing a tailor-made person expertise, pre-configured execution roles, and built-in integration with Identification Heart authentication.
Why SageMaker AI domains
Utilizing one SageMaker AI area per group is a well-established sample for organizing multi-team environments. This strategy provides a number of benefits:
- Established multi-team sample – AWS has documented this strategy extensively for separating strains of enterprise or groups with a number of domains, making it a confirmed and supported configuration.
- Native Identification Heart authentication – Every area will be configured with Identification Heart authentication, that means customers sign up as soon as by their company id supplier and land straight of their group’s Studio atmosphere.
- Constructed-in group configuration – Domains already present mechanisms to specify configurations for customers and groups with out requiring further {custom} entities. For instance, settings like group execution function will be specified at area degree, and overridden at person profile degree for max flexibility.
- Navigation customization – With area settings, directors can conceal navigation objects that aren’t related to the group’s workflows, presenting a targeted interface tailor-made to HyperPod use circumstances.
Study extra: SageMaker AI area entities and statuses · A number of domains overview
Establishing per-team domains
Create one SageMaker AI area per group with Identification Heart authentication. In our instance, we create TeamA-domain and TeamB-domain. Every area is configured as follows:
- Default execution function – Set the area’s default execution function to the team-specific IAM function created within the authorization step. All actions carried out by Studio inherit the suitable permissions in consequence.
- Identification Heart group project – Add the corresponding Identification Heart group (for instance, the
TeamAgroup) to the area. This prompts the SageMaker Studio software for all members of that group, granting them entry to the Studio interface. - Utility project verification – After configuring group entry, evaluation the applying project in Identification Heart to verify that the right teams are mapped to the right domains.
- Navigation customization – Configure the default navigation settings for every area to current solely the related capabilities. For instance, you may conceal objects not associated to HyperPod workflows, offering a streamlined HyperPod-focused person expertise that reduces cognitive overhead for group members who solely have to work with HyperPod assets.
The next picture reveals the SageMaker AI console with one area per group (TeamA-domain and TeamB-domain), every offering an remoted workspace boundary.
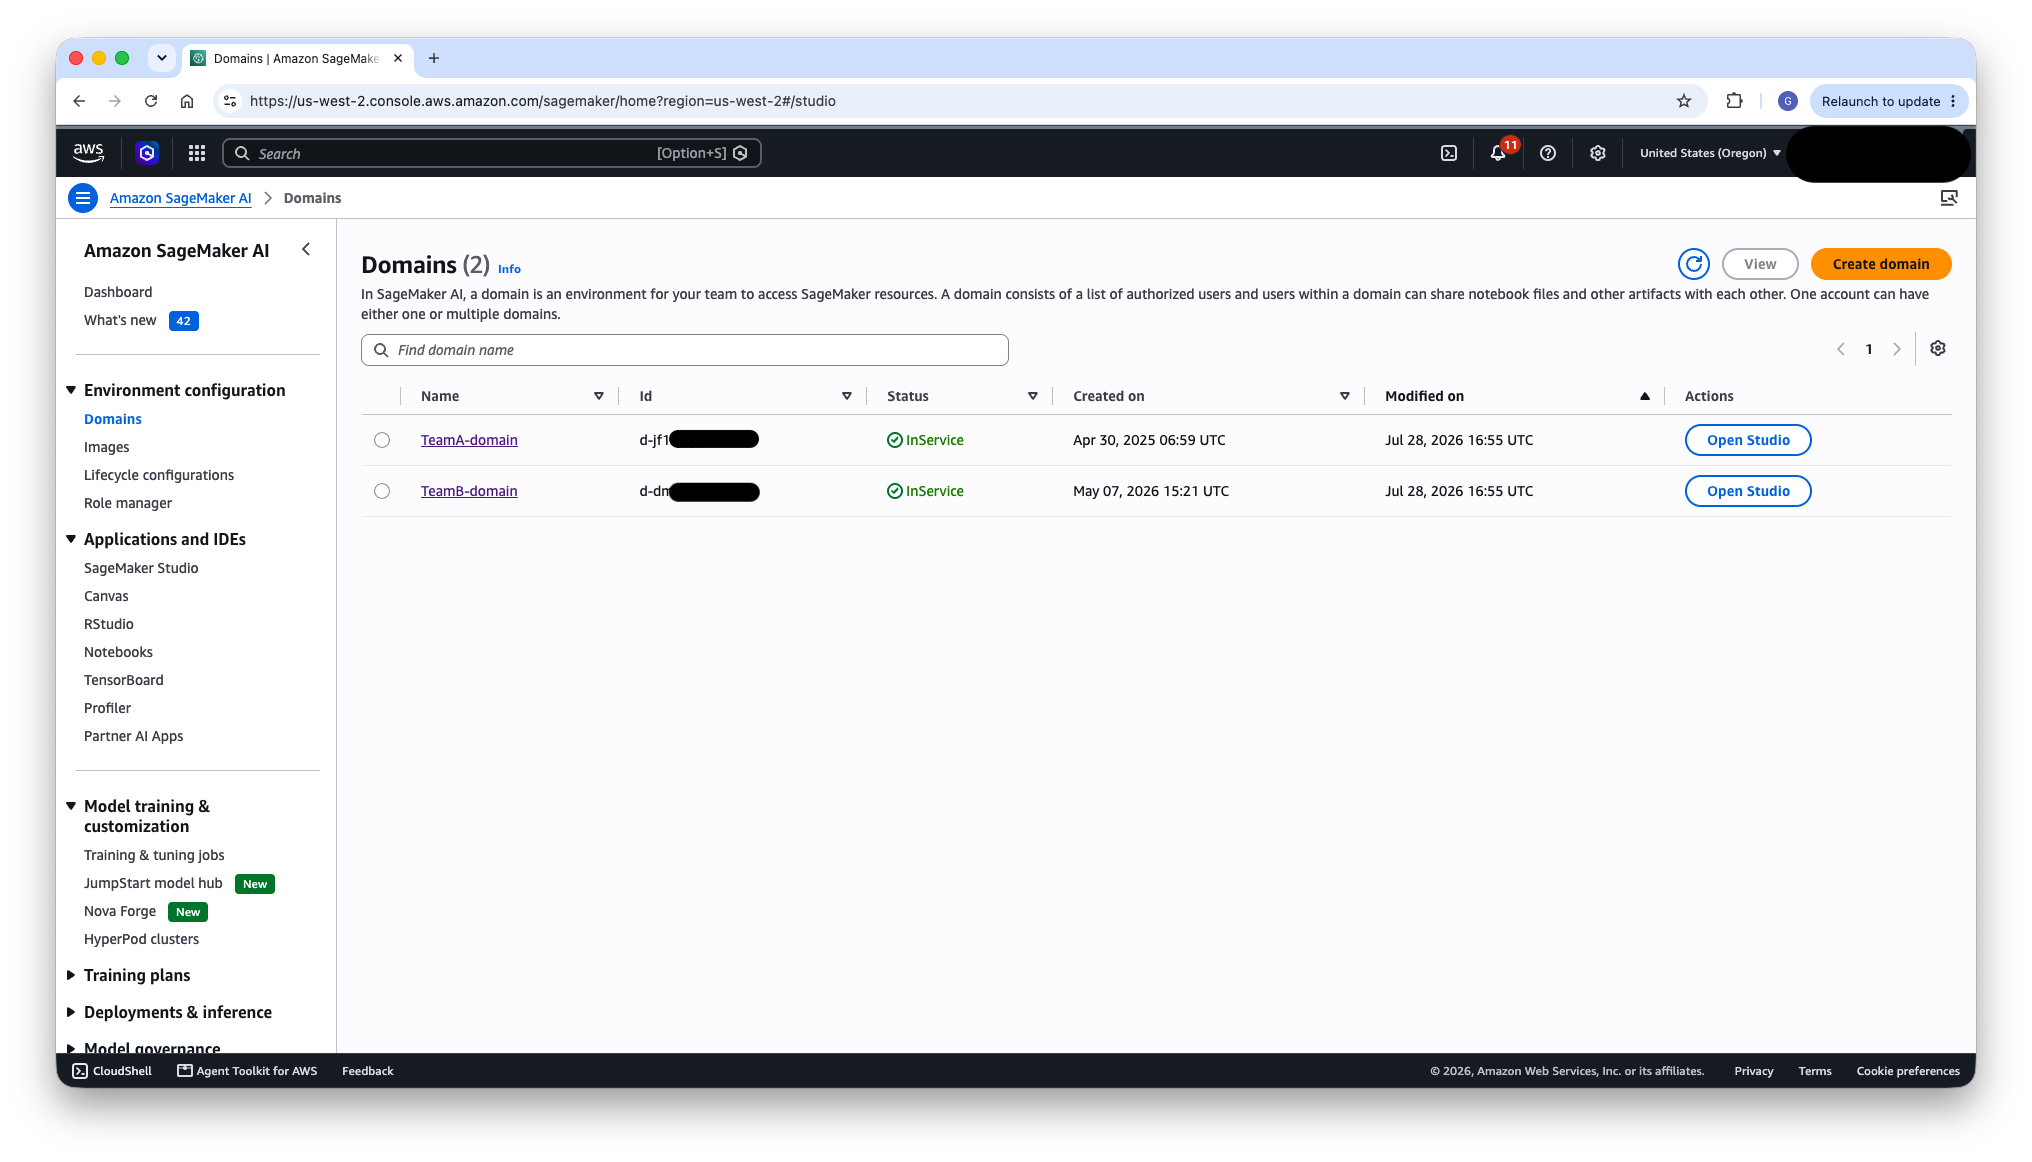
Determine 5: One SageMaker Area per group within the SageMaker console
Then the next picture reveals the main points of TeamA-domain, together with the assigned Identification Heart teams.
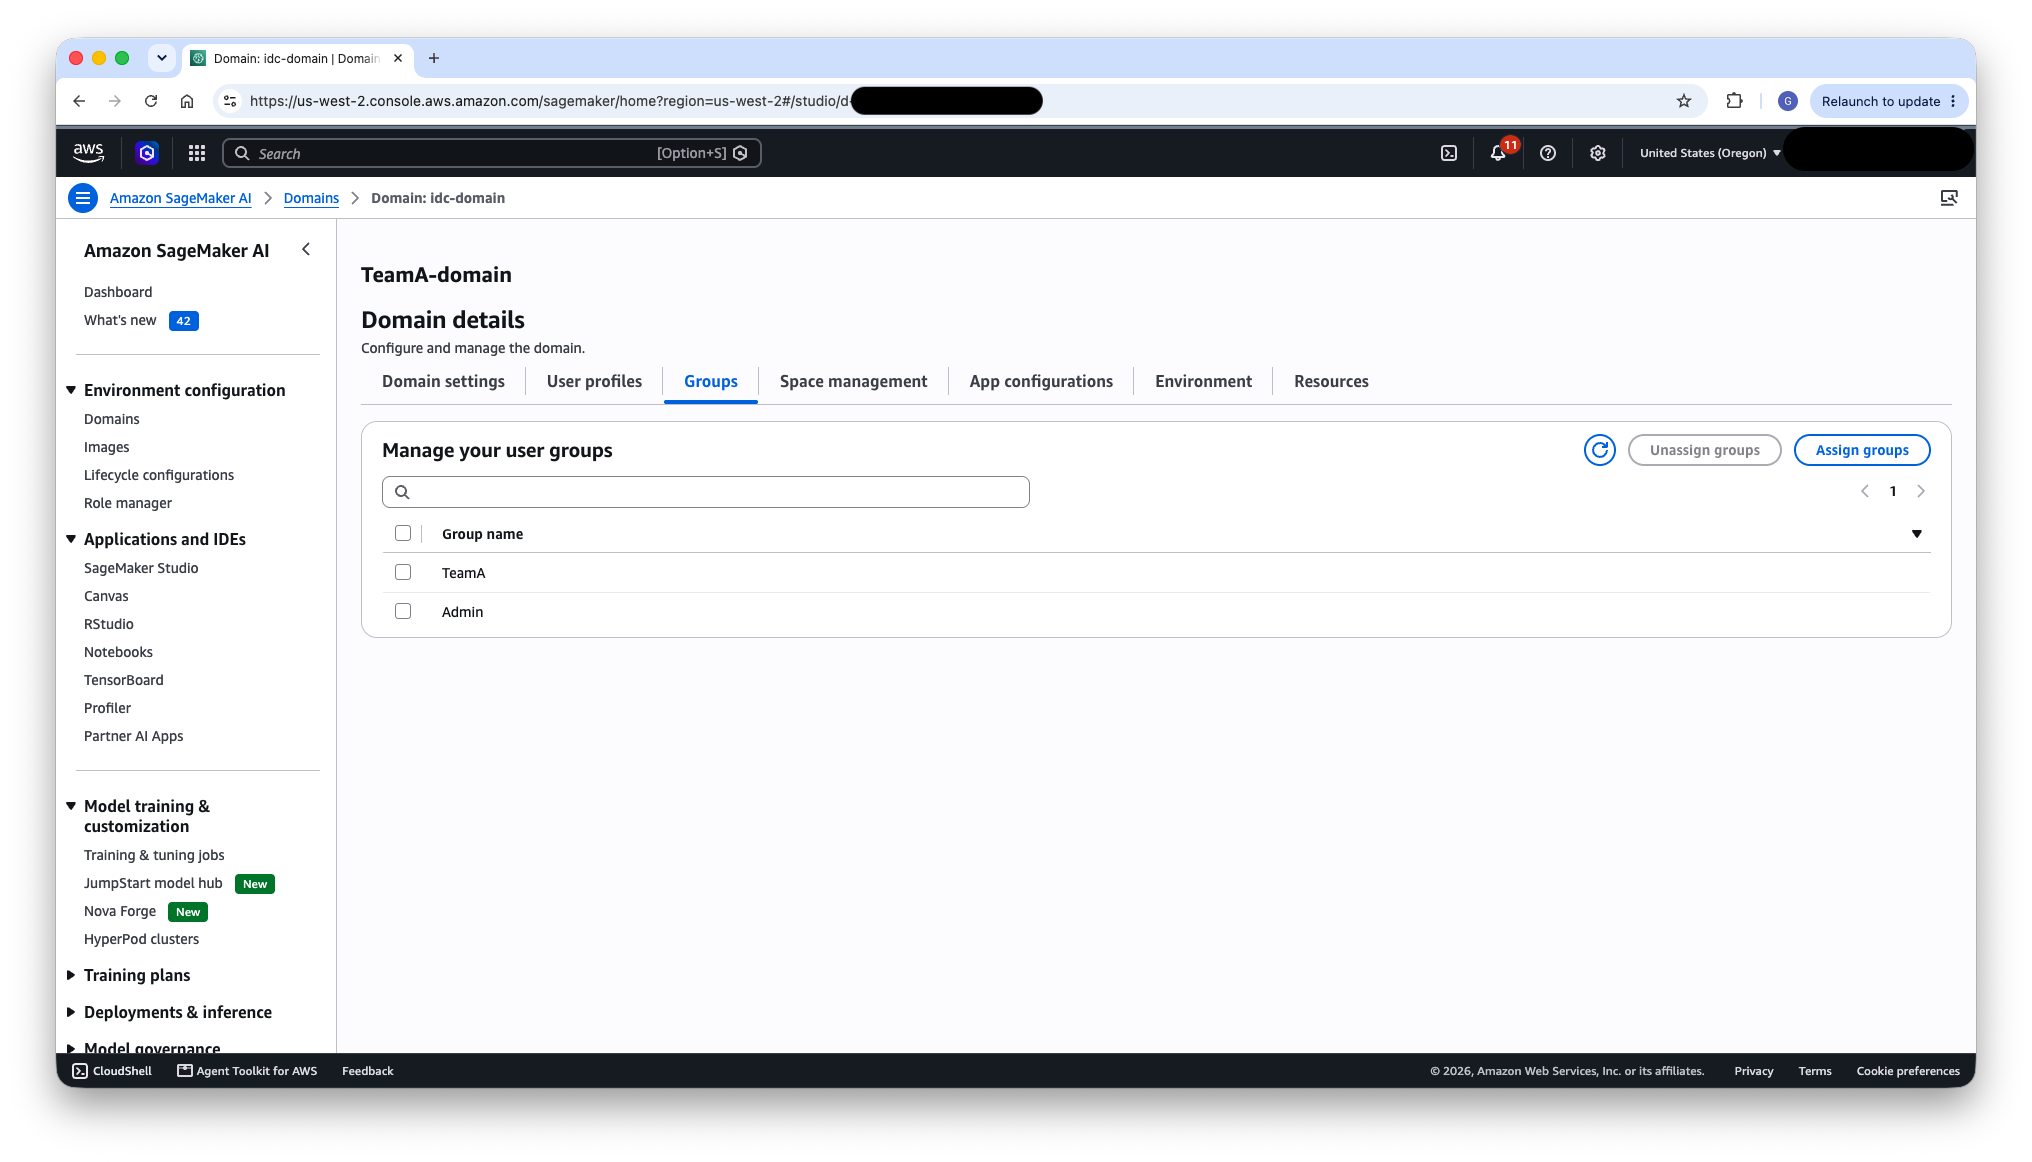
Determine 6: TeamA-domain configuration with its assigned Identification Heart teams
HyperPod EKS cluster configuration
The HyperPod EKS cluster is the place workloads are executed. Multi-tenancy on the cluster degree is achieved by Kubernetes namespaces for isolation and EKS entry entries for authorization.
Namespace isolation
Create a devoted Kubernetes namespace for every group, for instance hyperpod-ns-team-a and hyperpod-ns-team-b. Namespaces present a logical boundary throughout the cluster, isolating every group’s workloads (Areas, coaching jobs, inference endpoints) from each other.
Observe: Namespaces are an isolation boundary, not a tough safety boundary. This structure targets multi-team inside a single group: groups that share a cluster underneath a standard administrative area and a baseline of mutual belief. It isn’t designed for multi-customer isolation between mutually untrusted tenants.
Namespaces, RBAC, and quotas forestall unintentional interference (groups overwriting one another’s assets or exceeding their compute allocation) however aren’t a protection towards a decided malicious tenant: namespaced pods share the identical nodes and kernel, and cluster-scoped assets (nodes,
PersistentVolumes, CRDs, some operator elements) sit outdoors any namespace.For untrusted tenants or strict regulatory isolation, use stronger boundaries akin to separate clusters or accounts, devoted node swimming pools, and runtime sandboxing. For the multi-team situation right here, namespace isolation mixed with RBAC, Activity Governance quotas, and the POSIX id controls described later strike an applicable steadiness of separation and operational simplicity.
Namespaces will be created manually with kubectl create namespace or provisioned robotically by HyperPod Activity Governance, which manages namespaces as a part of its quota and scheduling configuration.
The next picture reveals the cluster namespaces (managed with HyperPod Activity Governance), with one devoted namespace per group (hyperpod-ns-team-a and hyperpod-ns-team-b) offering workload isolation.
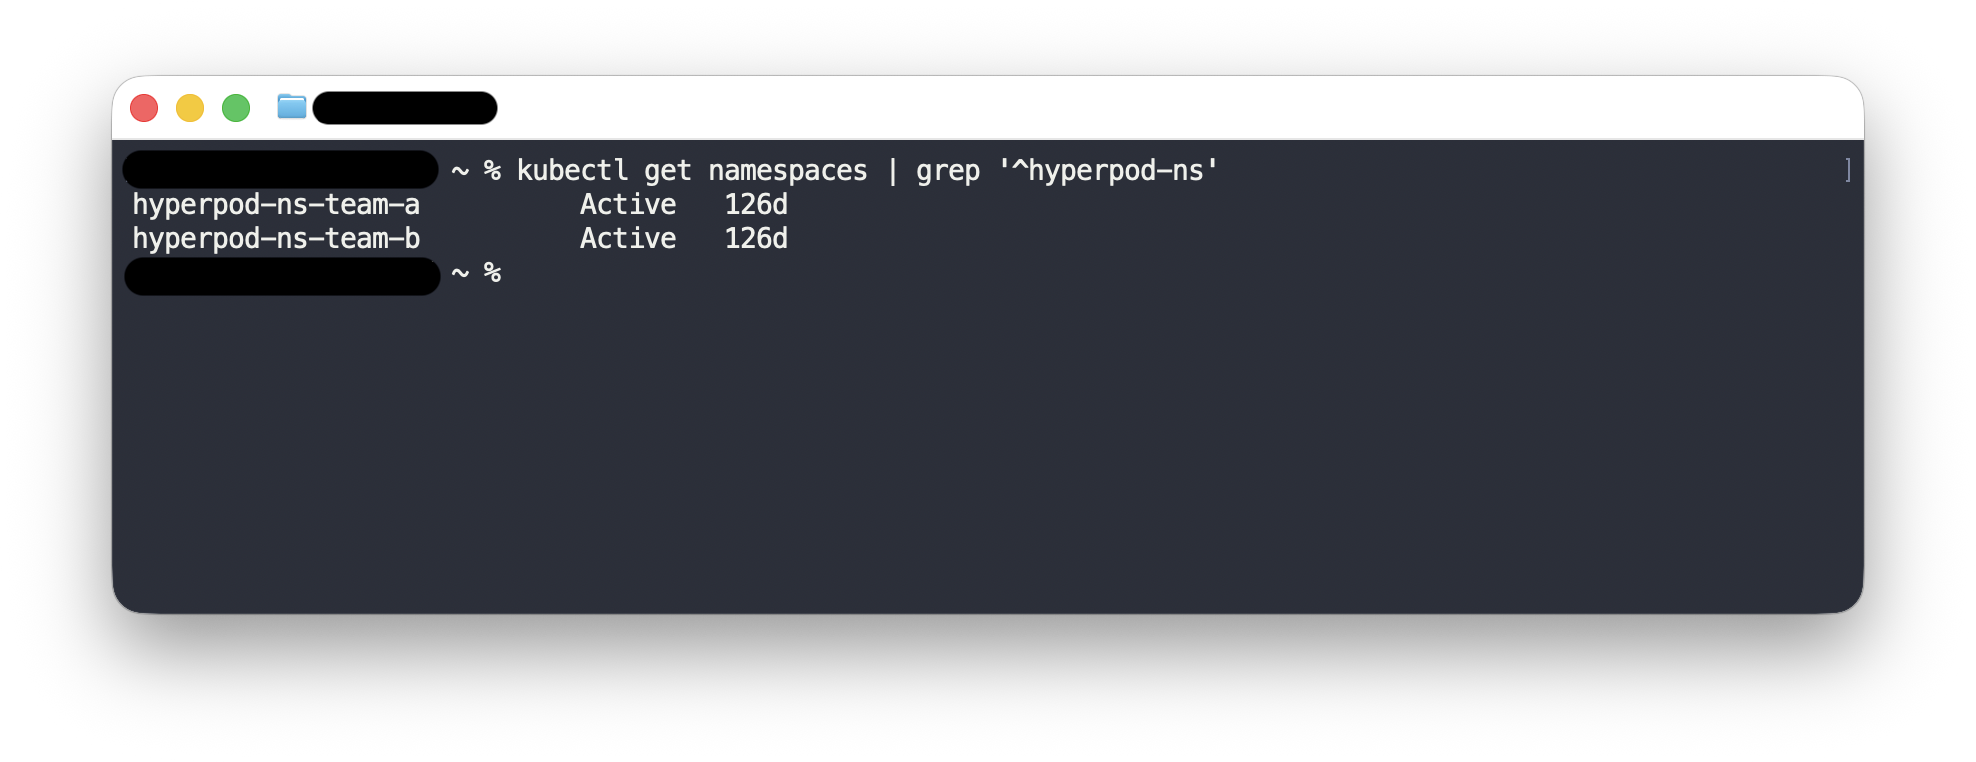
Determine 7: Devoted Kubernetes namespace per group for workload isolation
Study extra: Kubernetes namespaces
Community isolation
Namespaces don’t limit community site visitors. By default, Kubernetes networking is flat: each pod can attain each different pod throughout all namespaces. In consequence, a pod in hyperpod-ns-team-a can open a connection to a pod in hyperpod-ns-team-b except you add controls. To scope pod-to-pod reachability alongside group boundaries, use Kubernetes NetworkPolicy assets.
The really helpful sample is default-deny per namespace: begin by denying all ingress (and optionally egress), then explicitly enable the site visitors every group wants, usually intra-namespace communication plus required egress akin to DNS, storage endpoints, and AWS APIs. The next instance denies all ingress in a group’s namespace after which permits site visitors solely from pods throughout the identical namespace:
NetworkPolicy enforcement will depend on a Container Community Interface (CNI) that helps it. On EKS, you possibly can allow community coverage help within the Amazon Digital Non-public Cloud (Amazon VPC) CNI.
As with namespaces, NetworkPolicies scale back unintentional cross-team reachability and shrink the scope, however they aren’t by themselves an adversarial safety boundary on shared nodes. For stronger separation, think about devoted node swimming pools per group or separate clusters, as famous earlier.
Study extra: Kubernetes community insurance policies · Amazon VPC CNI community coverage
EKS entry entries
EKS entry entries join IAM principals to Kubernetes RBAC permissions. For every group, create two entry entries:
- Studio entry entry – The IAM principal is the group’s SageMaker AI area execution function. This entry is used when actions originate from the SageMaker Studio GUI.
- CLI entry entry – The IAM principal is the SSO-provisioned function created by Identification Heart for the group’s permission set (following the sample
AWSReservedSSO_). This entry is used when customers work together with the cluster by_ kubectl.
Each entries are scoped to the group’s namespace with managed or {custom} Kubernetes insurance policies. For instance, each Workforce A entries grant permissions solely inside hyperpod-ns-team-a. The 2 entries can carry totally different RBAC insurance policies if you would like. As an illustration, the CLI entry may limit write entry to sure useful resource varieties whereas the Studio entry permits full entry.
With this scoping, whether or not entry originates from Studio or from the CLI, customers can solely work together with assets in their very own namespace. Making an attempt to checklist or modify assets in one other group’s namespace leads to a Kubernetes Forbidden error.
For extra superior situations, you should utilize Kubernetes teams within the entry entry to map customers to {custom} ClusterRoles or Roles that present fine-grained permissions past the usual managed insurance policies.
The next picture reveals an EKS entry entry for Workforce B’s function, scoped right down to the hyperpod-ns-team-b namespace, so its permissions apply solely inside Workforce B’s namespace.
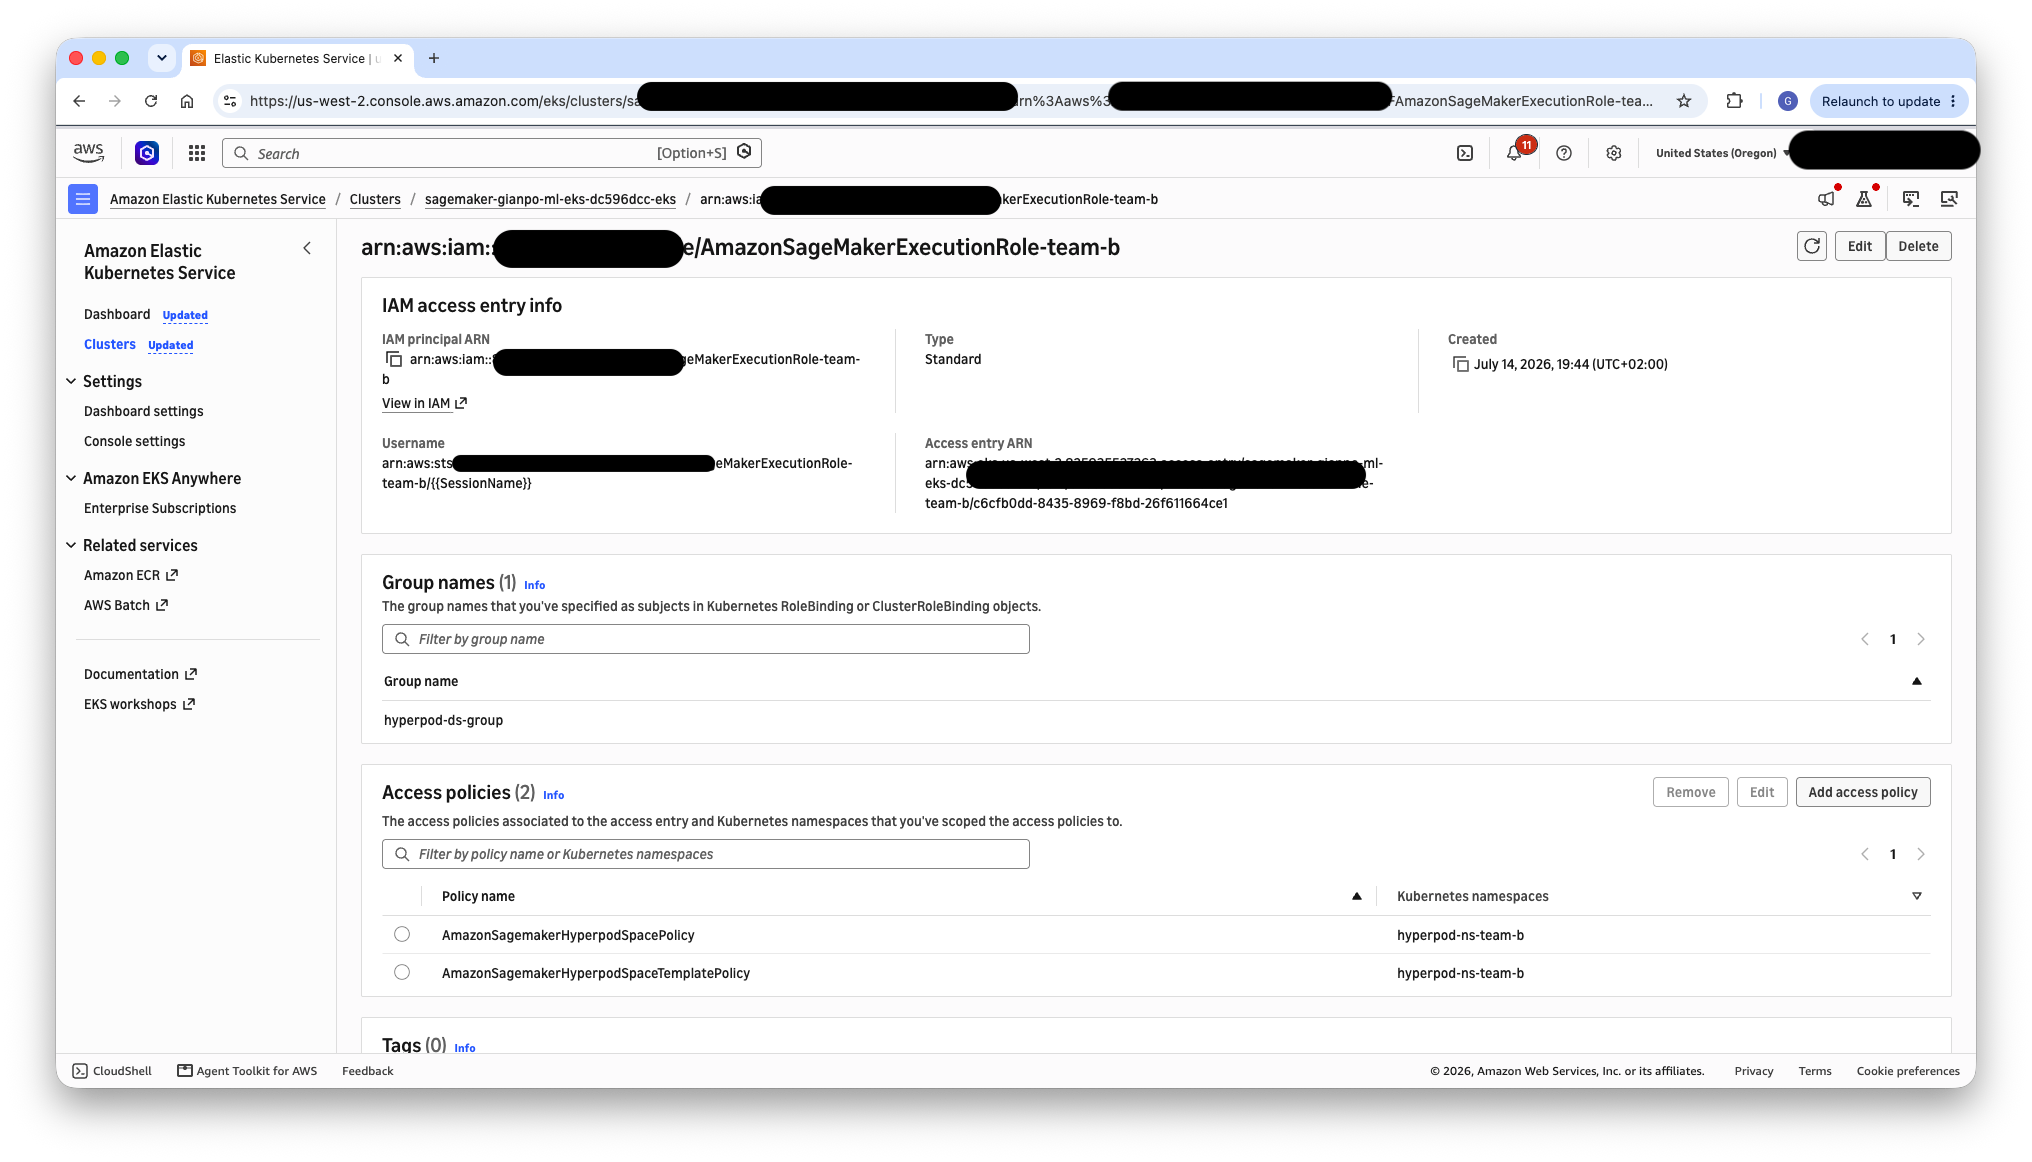
Determine 8: EKS entry entry scoped to Workforce B’s namespace
Study extra: Grant IAM customers entry to Kubernetes with EKS entry entries
HyperPod Activity Governance
When Activity Governance is enabled on the cluster, it supplies an extra layer of useful resource administration:
- Compute quotas – Outline how a lot GPU and CPU capability every group can eat. This prevents a single group from monopolizing shared {hardware} throughout coaching runs.
- Priorities – Assign scheduling priorities to every group or workload kind, permitting vital manufacturing inference workloads to preempt experimental coaching jobs when assets are constrained.
- Honest scheduling – With Activity Governance, when a number of groups are competing for assets, allocation follows the configured insurance policies fairly than a first-come-first-served mannequin.
Configure Activity Governance with applicable quotas and priorities per group namespace, balancing between assured minimal allocations and burst capability for bursty workloads.
The next picture reveals the Activity Governance compute allocations for the 2 groups, with every group’s namespace assigned its personal quota of cluster compute capability.
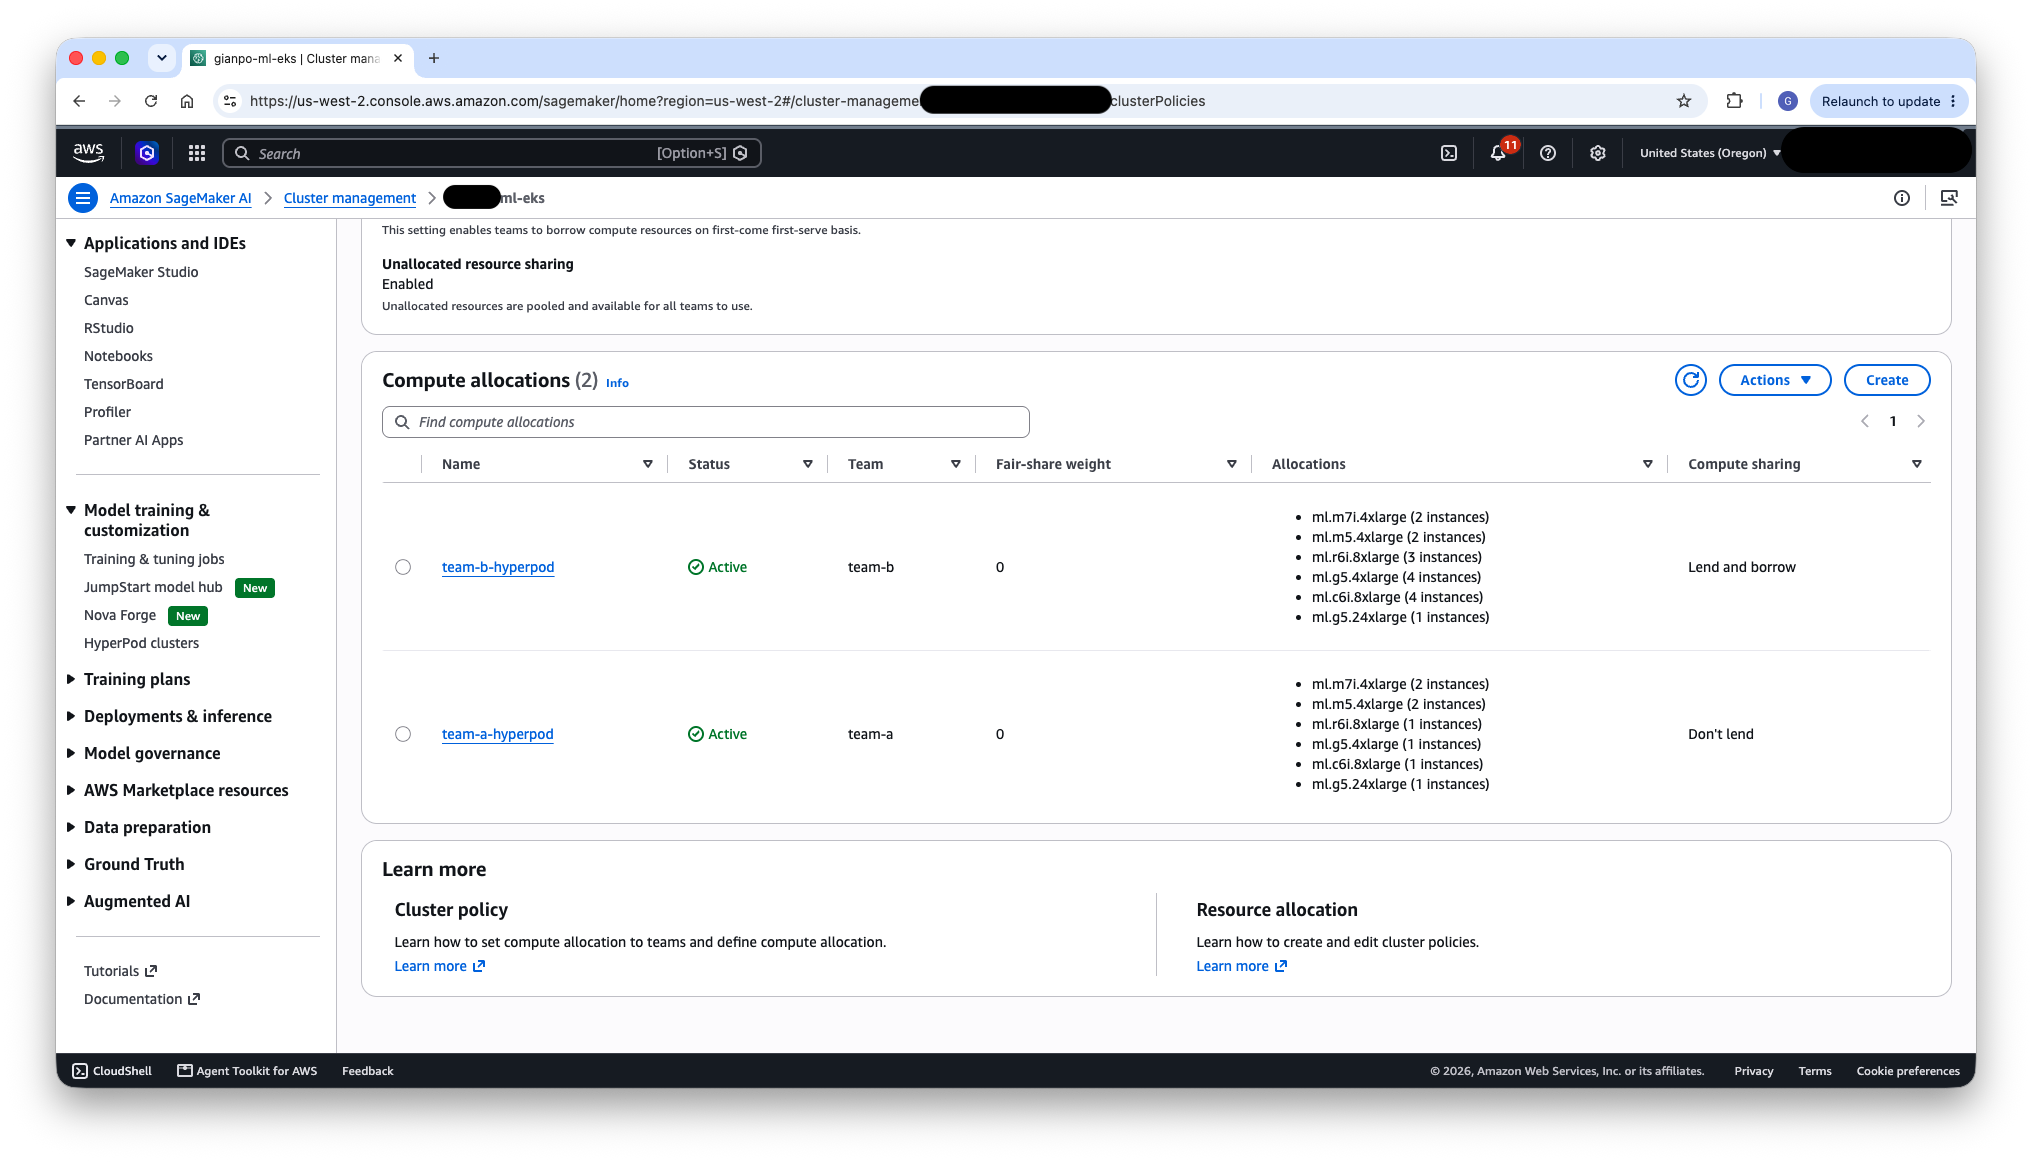
Determine 9: Activity Governance compute allocations per group namespace
Study extra: SageMaker HyperPod process governance
Storage
Storage is a key element of synthetic intelligence and machine studying (AI/ML) environments shared throughout groups. Groups want high-performance file programs for coaching information, checkpoints, and mannequin artifacts, whereas sustaining applicable entry boundaries between groups.
POSIX-compliant file programs
For workloads that require a shared, high-performance POSIX file system (widespread for distributed coaching the place a number of nodes learn the identical dataset or write checkpoints), think about the next choices:
- Amazon FSx for Lustre – Offers high-throughput, low-latency parallel file system entry, very best for large-scale coaching workloads that have to learn giant datasets at excessive velocity.
- Amazon FSx for OpenZFS – Provides a general-purpose file system with robust POSIX semantics, snapshots, and compression. Effectively-suited for workloads that want conventional file system options alongside excessive efficiency.
- Amazon Elastic File System (Amazon EFS) – Offers totally managed, elastic Community File System (NFS) storage. EFS additionally helps entry factors, which may simplify per-team listing isolation by mapping totally different mount factors to totally different directories with enforced UIDs and GIDs.
The storage format usually follows this construction:
- Per-team shared directories – Every group has a shared listing (for instance,
/fsx/TeamA,/fsx/TeamB) for datasets, fashions, and artifacts that every one group members have to entry. - Per-user residence directories – Every person has a private residence listing (for instance,
/residence/User1,/residence/User2) for particular person work, experiments, and notebooks.
The POSIX permission mannequin on these file programs depends on UIDs, GIDs, and supplemental teams to implement entry boundaries. These POSIX identities ought to then be propagated to the pod safety context when a person launches a HyperPod Area or submits a coaching job, in order that file system entry respects the configured possession and permissions. We advocate utilizing a Kubernetes mutating admission webhook to retrieve POSIX id info out of your id retailer. When a workload is submitted, the webhook seems to be up the id at runtime and modifies the safety context of the Pod accordingly.
Study extra: FSx for Lustre · FSx for OpenZFS · Amazon EFS
Amazon S3 storage
For object storage, entry to S3 buckets is ruled by the group’s IAM execution function. You possibly can create per-team buckets or use a shared bucket with per-team prefixes, counting on IAM insurance policies to implement isolation. Pods throughout the cluster want applicable service accounts configured with IAM Roles for Service Accounts (IRSA) or Pod Identification to authenticate to S3. For simplicity, you possibly can affiliate the identical execution function configured on the SageMaker AI area to a Kubernetes service account throughout the group’s namespace, offering constant S3 entry from each Studio and cluster workloads.
Study extra: IAM roles for service accounts (IRSA) · EKS Pod Identification
HyperPod Areas
HyperPod Areas present interactive improvement environments (IDEs) operating straight on cluster nodes. On a shared cluster, Areas have to be correctly scoped to every group’s namespace and configured with applicable useful resource templates.
Area templates
Create namespace-scoped Area templates for every group. These templates outline the useful resource configurations (occasion varieties, storage volumes, atmosphere variables) accessible to group members when creating Areas. By scoping templates to a namespace, you be sure that every group can solely launch Areas inside their designated boundary.
When HyperPod Activity Governance is enabled, templates ought to embody the default labels required by the governance system (akin to group identifiers and precedence labels). The cluster administrator pre-configures these labels in order that group members don’t have to specify them manually when launching Areas.
The next instance reveals a JupyterLab Area template scoped to Workforce A. The team-specific components are the metadata.namespace, the Activity Governance queue label underneath baseLabels, and the defaultVolumes that mount the group’s shared file system and the person’s residence listing:
Persistent quantity claims
Create the suitable Persistent Quantity Claims (PVCs) in every group’s namespace, referencing the shared file system. These PVCs mount the group’s shared listing and the person’s residence listing into the Area, offering entry to coaching information, checkpoints, and private workspaces.
Proprietor-only and shared Areas
Think about your group’s necessities round Area sharing:
- Proprietor-only Areas – Every Area is accessible solely by the person who created it. That is the default configuration, applicable when groups work on delicate or impartial tasks.
- Shared Areas – A number of group members can entry the identical Area, helpful for pair programming, collaborative debugging, or shared improvement environments. When enabling shared Areas, be sure that POSIX permissions and supplemental teams are configured to permit applicable entry to recordsdata created throughout the Area.
Study extra: Interactive improvement environments on Amazon SageMaker HyperPod EKS clusters
Studio expertise
Whereas groups can work together with the cluster completely from the CLI utilizing kubectl, SageMaker Studio supplies a graphical entry level to the cluster for customers preferring a managed, GUI-driven workflow. On this structure, every group accesses Studio by its personal SageMaker AI area (as described earlier), signing in with the identical Identification Heart credentials and working throughout the boundaries of the group’s namespace.
The next picture reveals the IAM Identification Heart entry portal that customers attain after signing in with their company credentials, offering single sign-on entry to their assigned SageMaker Studio functions and Amazon Managed Grafana functions.
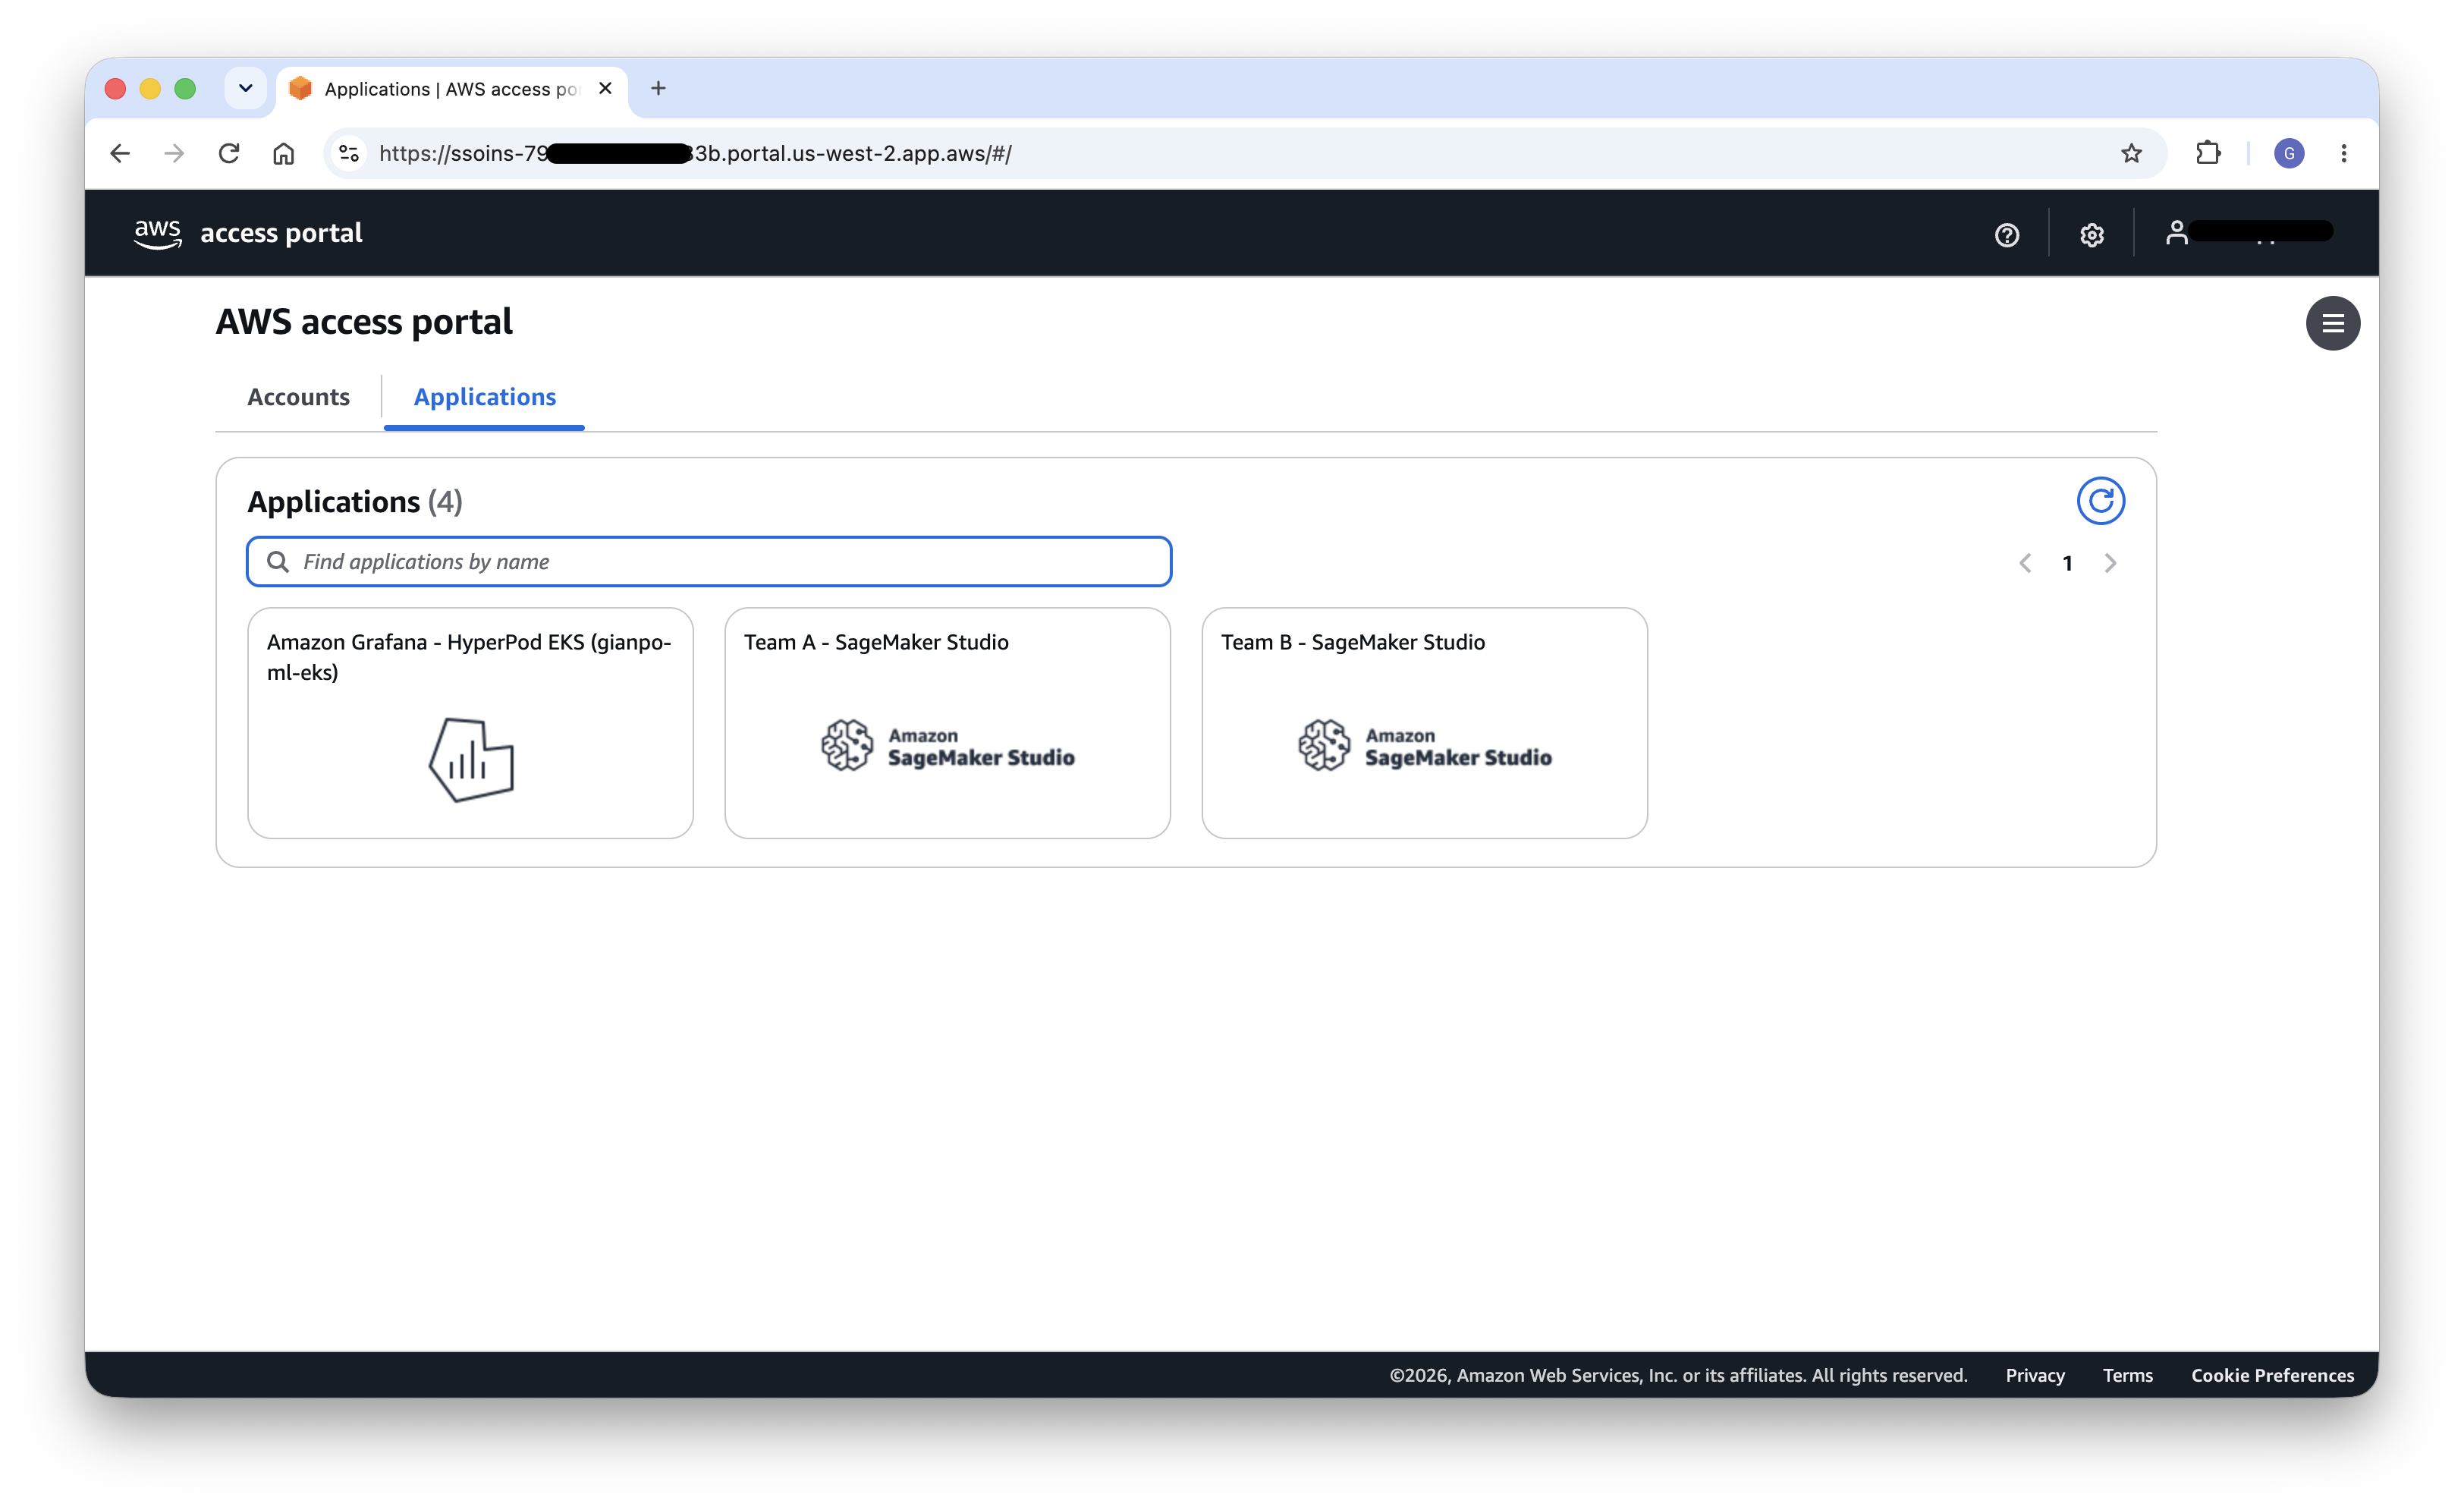
Determine 10: IAM Identification Heart entry portal with single sign-on to assigned functions
From the Studio UI, group members can:
- Handle HyperPod Areas – Launch interactive improvement environments from the namespace-scoped Area templates the administrator has configured, with out writing Kubernetes manifests or specifying Activity Governance labels manually. Workforce members also can begin, cease, and hook up with their operating Areas, opening the related IDE (akin to JupyterLab) straight within the browser.
- Handle Ray workloads – Create and monitor Ray clusters, join a JupyterLab or Code Editor workspace to a cluster, submit distributed jobs, and open the Ray Dashboard and Amazon Managed Grafana observability dashboards, all with out writing Kubernetes manifests or operating
kubectlinstructions.
As a result of Studio operates by the group’s Area execution function and the corresponding EKS entry entry, all actions are scoped to the group’s namespace. A person launching a Area or a Ray cluster from Studio can solely create it inside their very own group’s boundary, in step with the isolation mannequin enforced for CLI entry.
The next picture reveals create a HyperPod Area from the SageMaker Studio UI, the place a group member selects a namespace-scoped Area template with out writing Kubernetes manifests or specifying Activity Governance labels manually.
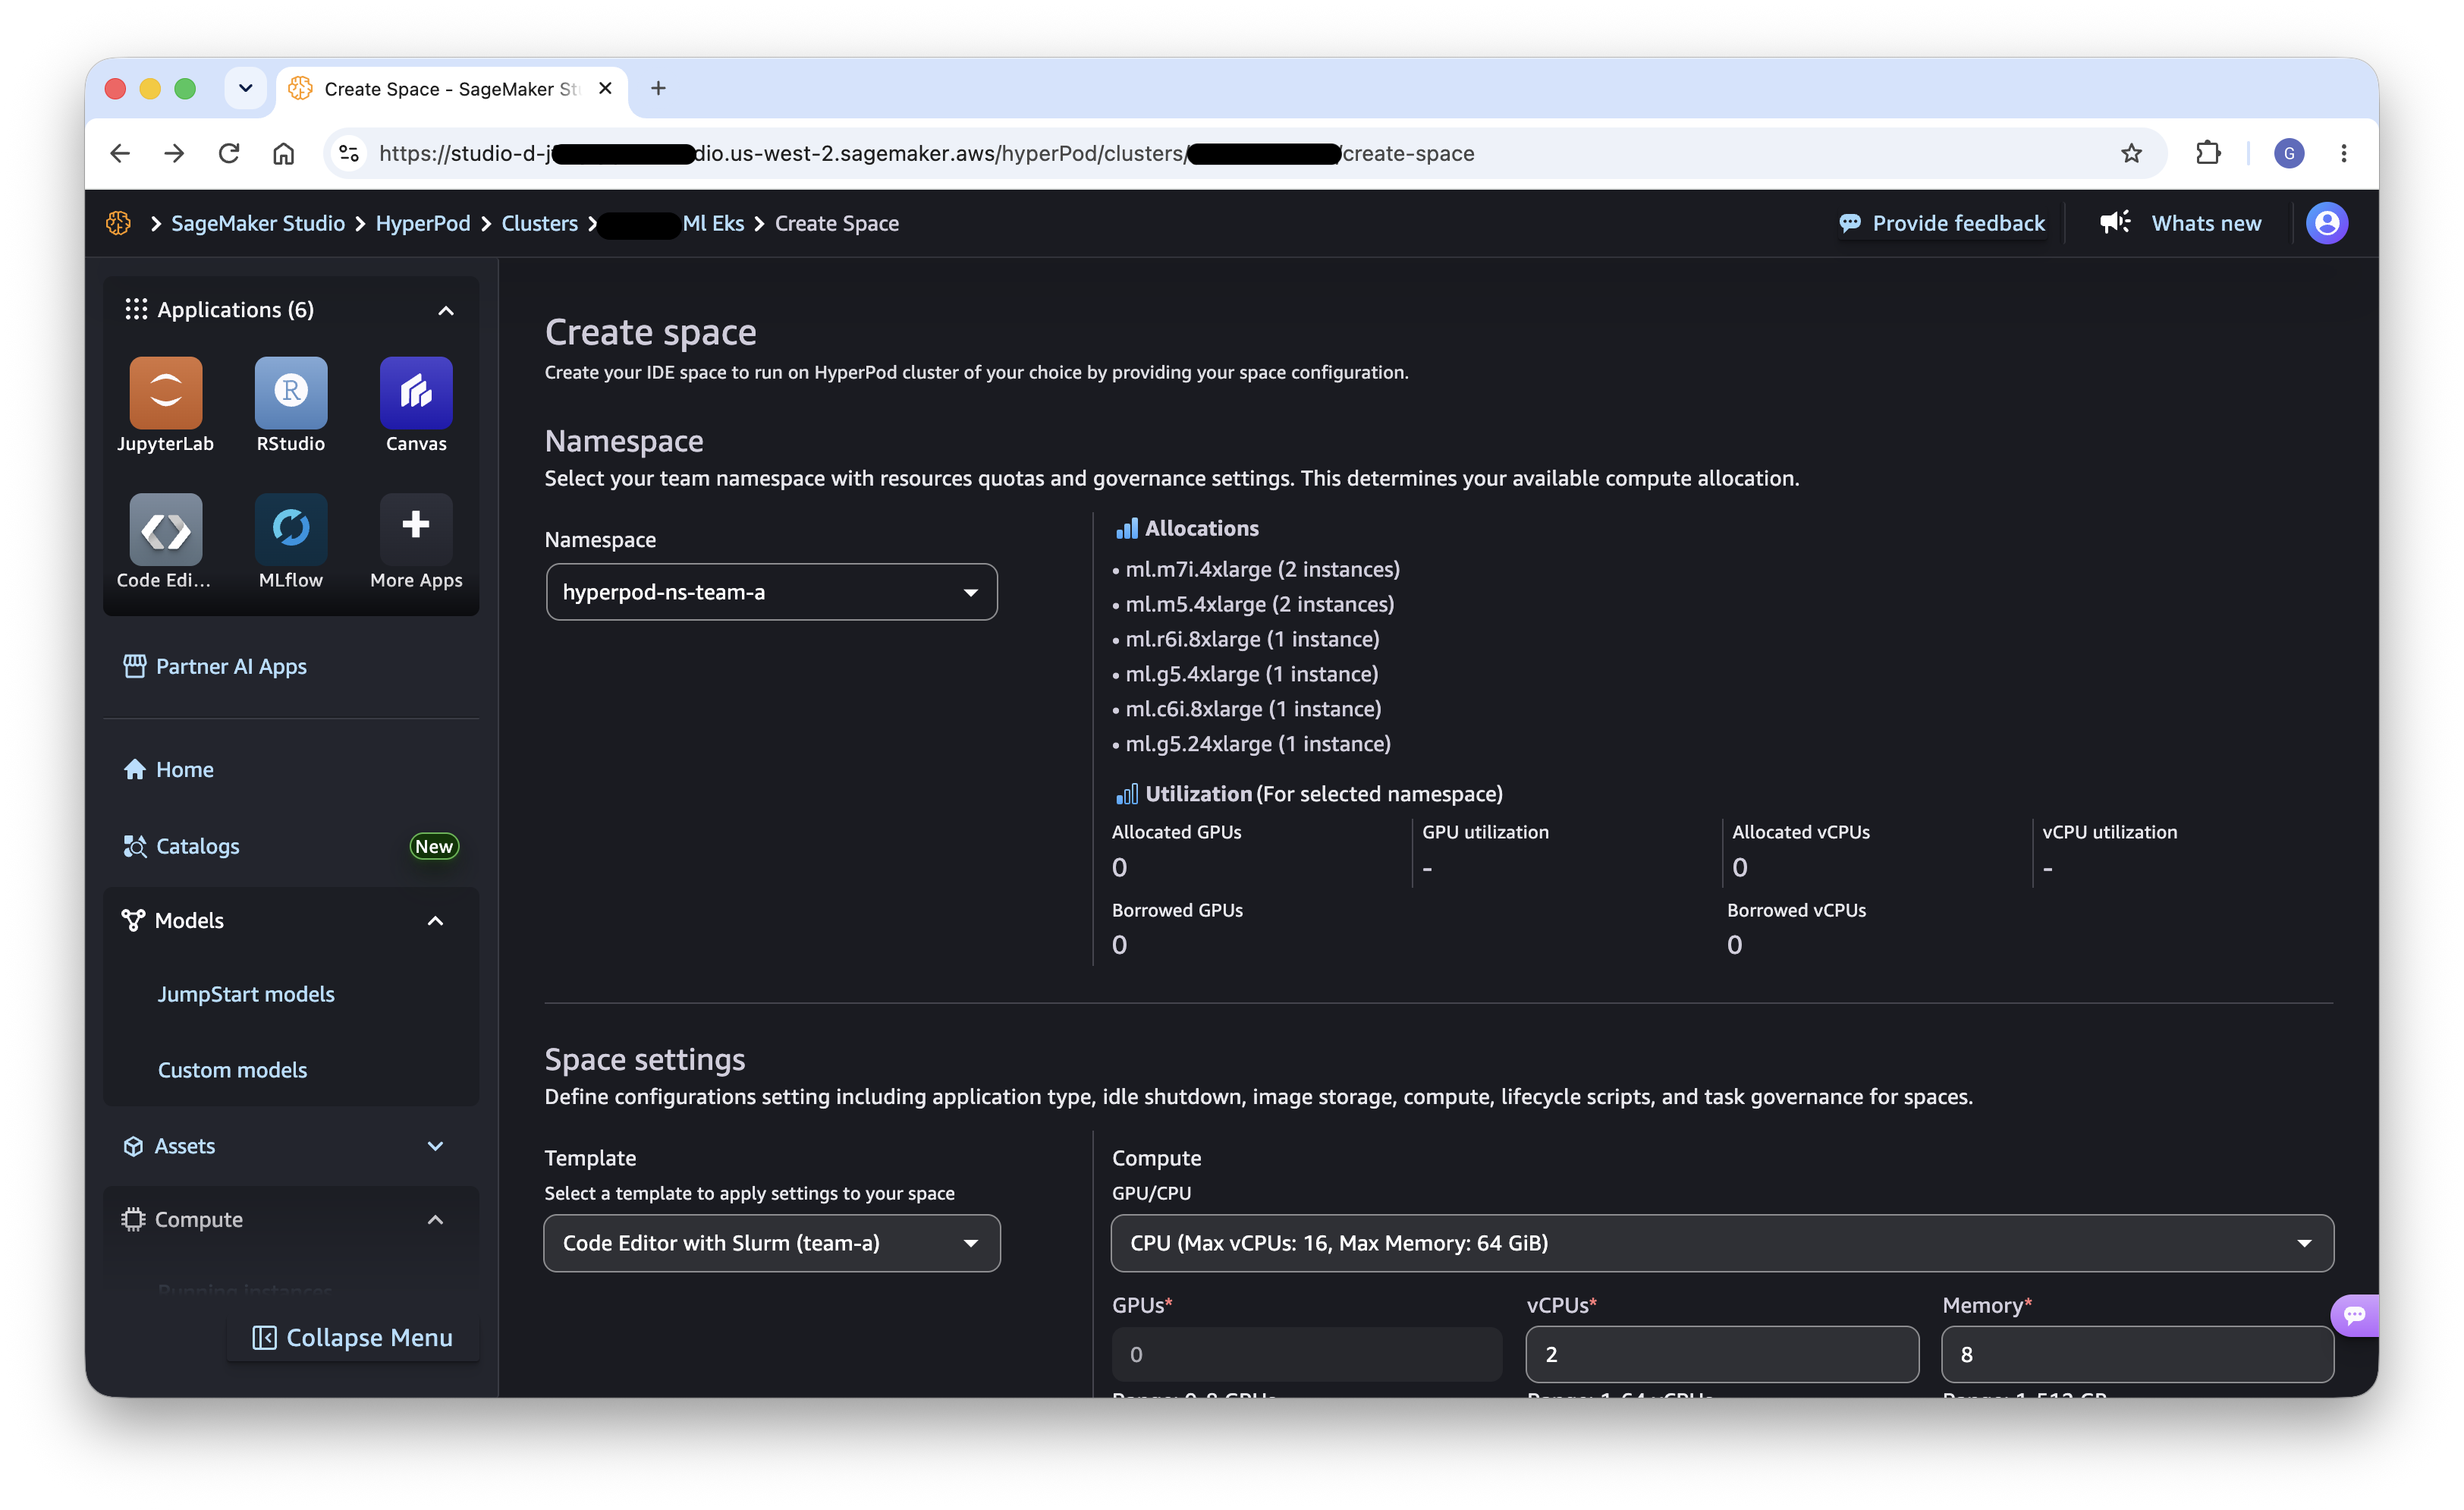
Determine 11: Making a HyperPod Area from a namespace-scoped template in SageMaker Studio
Study extra: Interactive improvement environments on Amazon SageMaker HyperPod EKS clusters · Introducing new Ray capabilities on SageMaker HyperPod
HyperPod Coaching Operator
The HyperPod Coaching Operator permits groups to submit distributed coaching jobs as Kubernetes {custom} assets (for instance, HyperPodPyTorchJob). Within the multi-tenant structure, coaching jobs are namespace-scoped, that means they robotically inherit the group’s isolation boundaries.
Groups can submit coaching jobs from the CLI utilizing kubectl apply with the suitable job manifest. The job runs within the group’s namespace, makes use of the group’s compute quotas (if Activity Governance is enabled), and has entry to the group’s storage volumes.
When Activity Governance is enabled, coaching jobs are topic to the group’s allotted quotas and precedence settings. If a group has consumed its assured allocation, jobs is perhaps queued till assets develop into accessible or till lower-priority workloads are preempted.
The 2 components that anchor a job to a group are the metadata.namespace (which scopes the job to the group’s isolation boundary) and the Activity Governance labels. Activity Governance is constructed on Kueue, so the job is routed to the group’s native queue by kueue.x-k8s.io/queue-name. It’s assigned a scheduling precedence by kueue.x-k8s.io/priority-class, whose worth is the title of a WorkloadPriorityClass outlined on the cluster:
Study extra: Utilizing the HyperPod coaching operator
HyperPod Inference Operator
The HyperPod Inference Operator permits groups to deploy fashions as inference endpoints straight on the cluster. Just like coaching jobs, inference endpoints are namespace-scoped and topic to the group’s RBAC insurance policies and Activity Governance quotas.
Groups can deploy fashions from the CLI by creating inference endpoint {custom} assets of their namespace. The endpoints are remoted per namespace, that means Workforce A can’t entry or intervene with Workforce B’s inference endpoints.
For manufacturing inference workloads that require excessive availability, think about assigning larger scheduling precedence to inference endpoints than to coaching jobs, in order that mannequin serving isn’t interrupted by batch coaching workloads.
As with coaching jobs, the inference endpoint is positioned within the group’s metadata.namespace and carries the Activity Governance labels. Right here, the kueue.x-k8s.io/priority-class references a higher-priority WorkloadPriorityClass in order that mannequin serving can preempt batch coaching when the group’s assets are constrained:
Study extra: Deploying fashions on Amazon SageMaker HyperPod
HyperPod Observability
Visibility into cluster well being, workload efficiency, and useful resource utilization is important for all groups. HyperPod Observability supplies built-in monitoring and dashboarding capabilities by Amazon Managed Grafana.
Configuring group entry to Grafana
Groups want entry to observability dashboards to observe their workloads, troubleshoot efficiency points, and perceive useful resource consumption. Nevertheless, in a multi-tenant atmosphere, this entry ought to usually be read-only:
- Configure Identification Heart authentication for Amazon Managed Grafana – On the Amazon Managed Grafana console, navigate to Authentication and allow AWS IAM Identification Heart. Customers can then sign up to Grafana with the identical company credentials they use for SageMaker Studio.
- Assign group teams as Viewers – Map the Identification Heart teams (
TeamA,TeamB) to the Grafana Viewer function. This grants group members read-only entry to dashboards and metrics with out the power to change dashboards or information sources. - Admin entry – Assign the
Admingroup to the Grafana Admin or Editor function, to allow them to create and modify dashboards, configure alerting, and handle information sources. - Workforce-specific dashboards – Think about creating devoted dashboards that filter information by namespace, so every group sees solely their very own workload metrics. Amazon Managed Grafana helps Grafana Groups (a Grafana-native RBAC idea, distinct from the organizational groups on this structure), which will be mapped from Identification Heart teams to limit dashboard visibility and supply an extra layer of knowledge isolation.
The next picture reveals the Grafana function assignments in Amazon Managed Grafana. The group teams (TeamA, TeamB) are assigned the Viewer function for read-only entry to dashboards and metrics, whereas the admin group is assigned the Admin function, granting it the power to create and modify dashboards, configure alerting, and handle information sources.
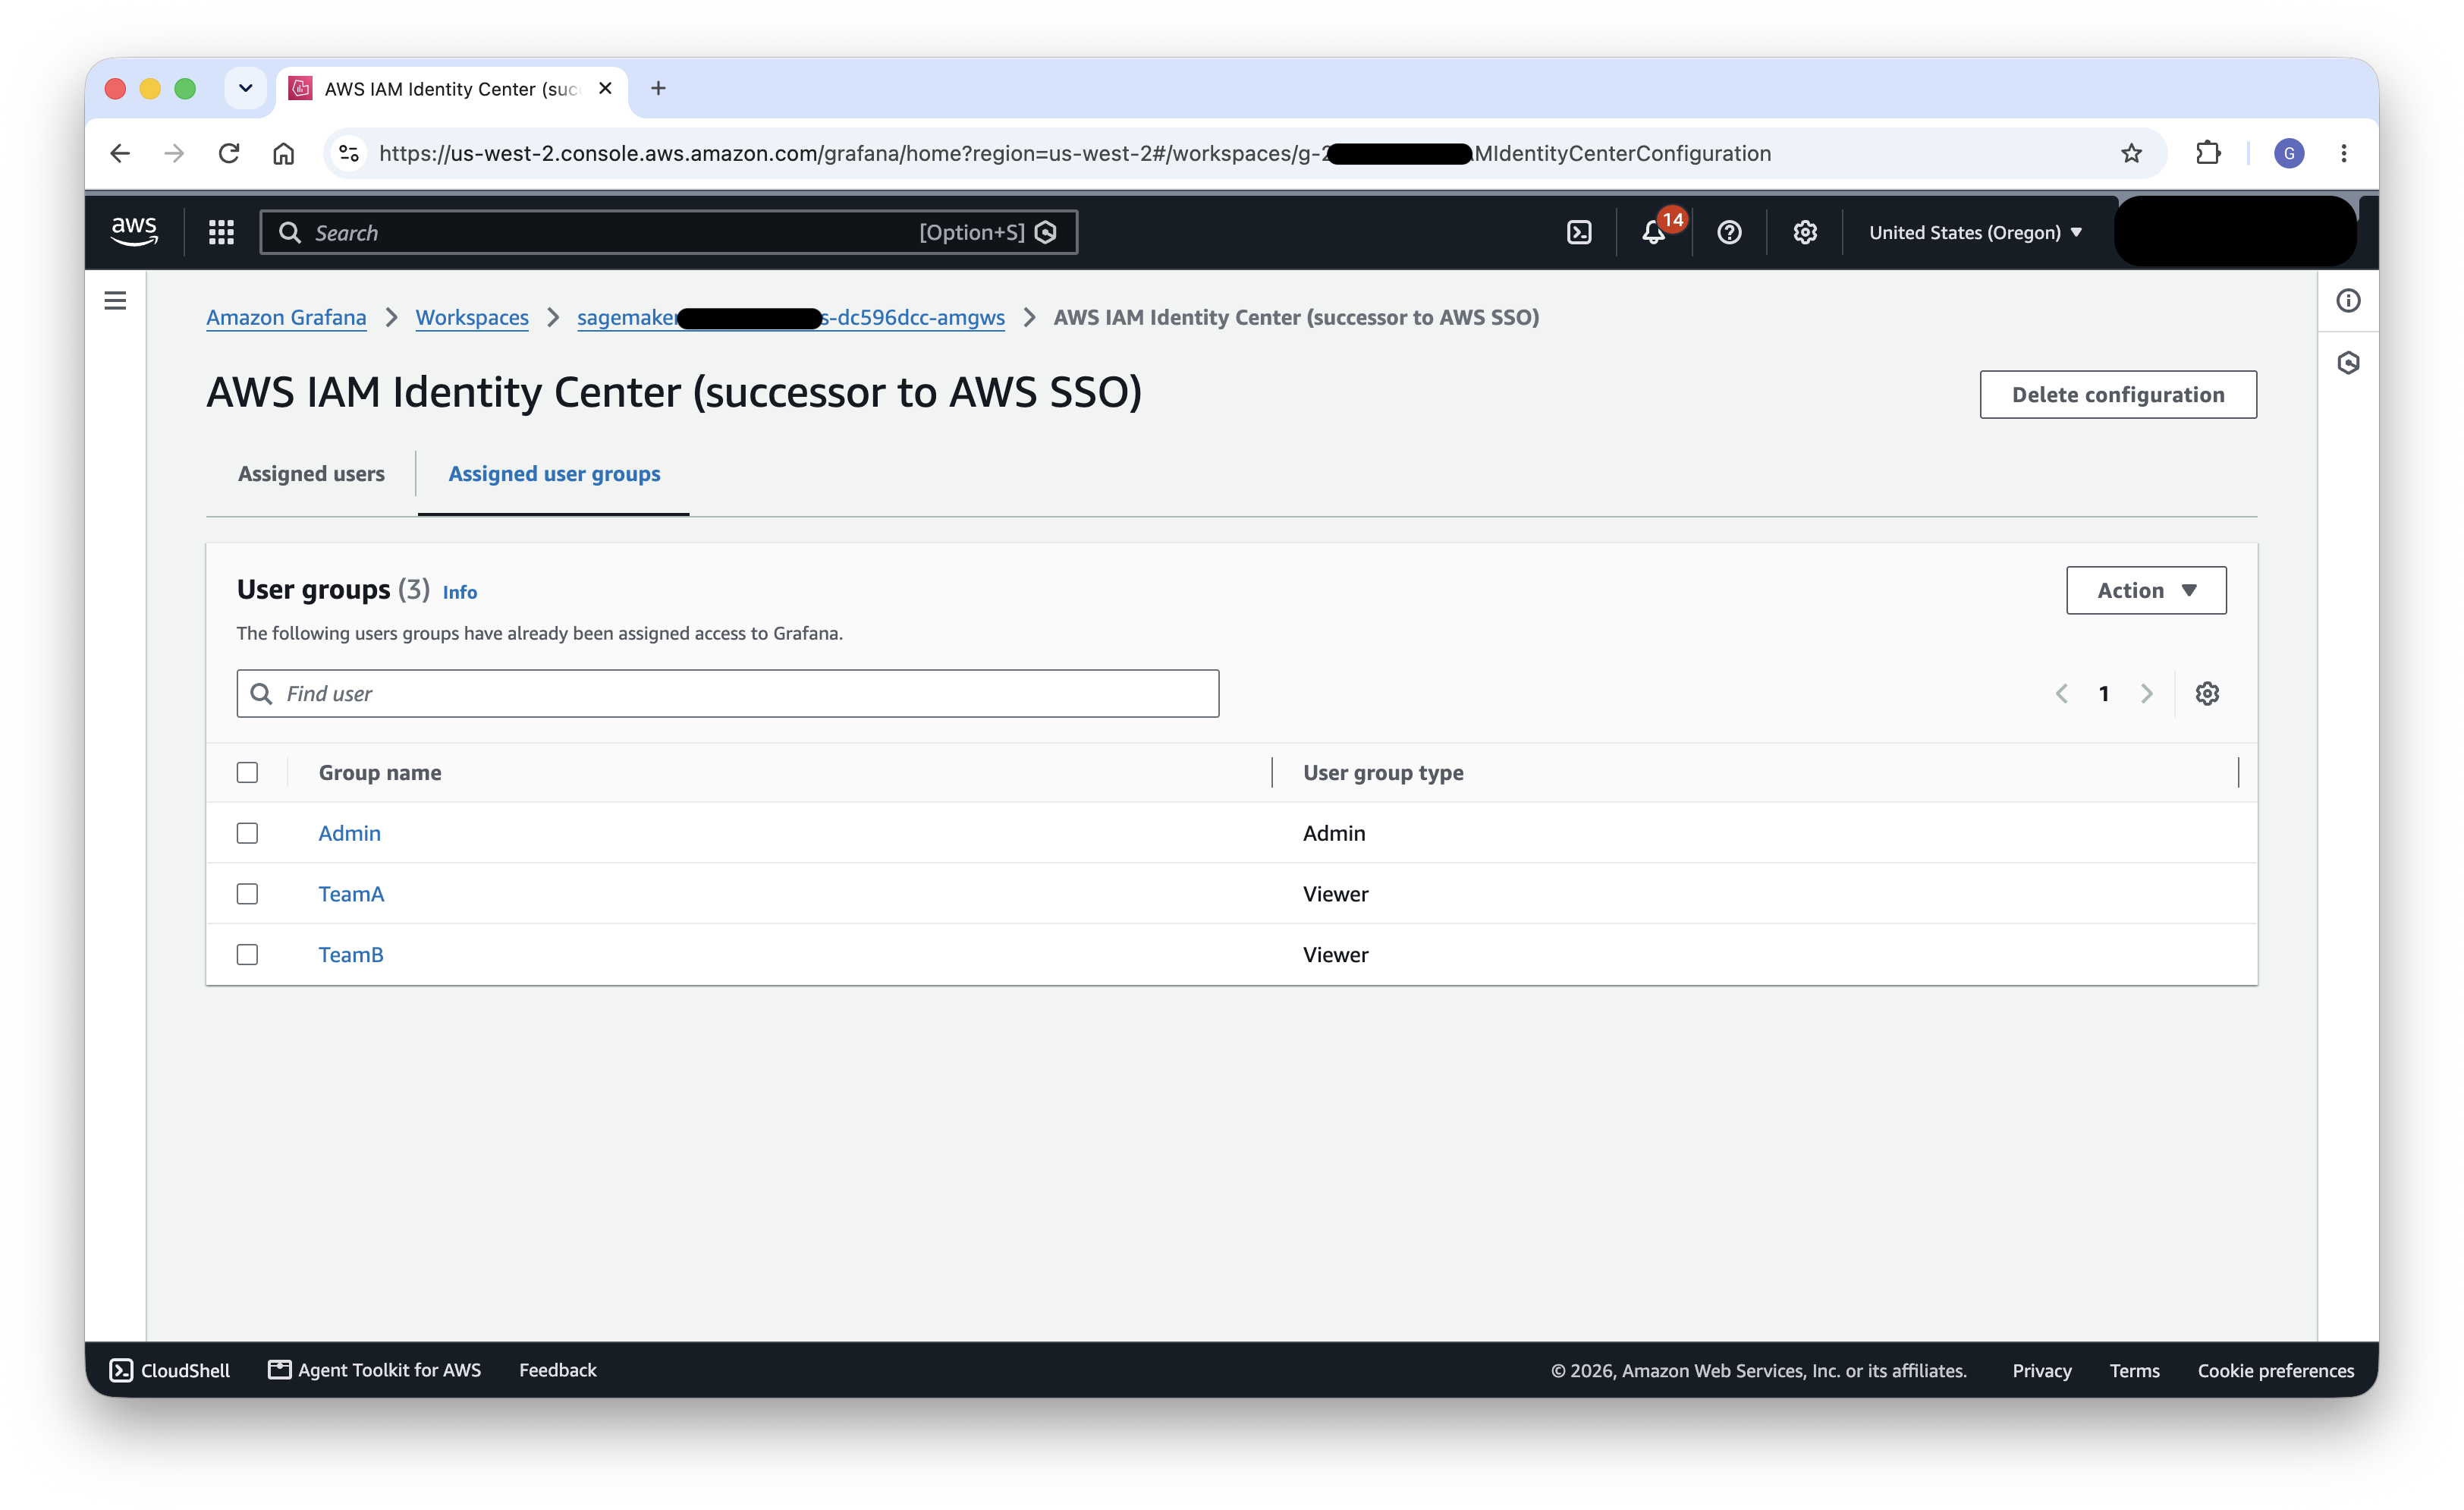
Determine 12: Grafana function assignments granting groups read-only Viewer entry
Study extra: Observability for Amazon SageMaker HyperPod cluster orchestrated by Amazon EKS
Value allocation and chargeback
In a multi-tenant atmosphere the place groups share costly GPU infrastructure, understanding who consumes what is important for accountability, budgeting, and chargeback. Kubecost addresses this want by breaking down in-cluster spend throughout native Kubernetes ideas (namespace, label, deployment, and repair) and mapping it to organizational ideas like group, undertaking, or atmosphere.
As a result of this structure already isolates every group in a devoted namespace (hyperpod-ns-team-a, hyperpod-ns-team-b), namespace-level price allocation aligns straight with group boundaries. This offers platform directors a transparent per-team view of GPU, CPU, reminiscence, storage, and community consumption with none further workload tagging. For step-by-step directions on deploying and configuring Kubecost on a HyperPod cluster, see Kubecost on SageMaker HyperPod.
Enabling group visibility
After Kubecost is gathering information, group price by namespace within the Allocations dashboard to see per-team spend. As a result of every group owns a namespace, this straight produces a per-team price breakdown protecting compute, reminiscence, storage, and community. Simply as with observability dashboards, groups profit from visibility into their very own price information:
- Scope views to every group’s namespace – Kubecost helps filtering and saved experiences by namespace, so every group can evaluation its personal consumption and developments with out seeing different groups’ information.
- Set budgets and alerts – Configure per-namespace funds thresholds and alerts, so groups and platform directors are notified when spending approaches outlined limits, supporting the identical resource-fairness objectives as HyperPod Activity Governance.
- Assist chargeback and showback – Namespace-level allocation experiences can feed inside chargeback (billing groups for his or her utilization) or showback (reporting utilization with out billing) processes, giving finance and platform groups the info that they should attribute shared GPU prices pretty.
The next picture reveals the Kubecost Allocations dashboard grouped by namespace, displaying the cumulative price over the past 7 days for every group’s namespace.
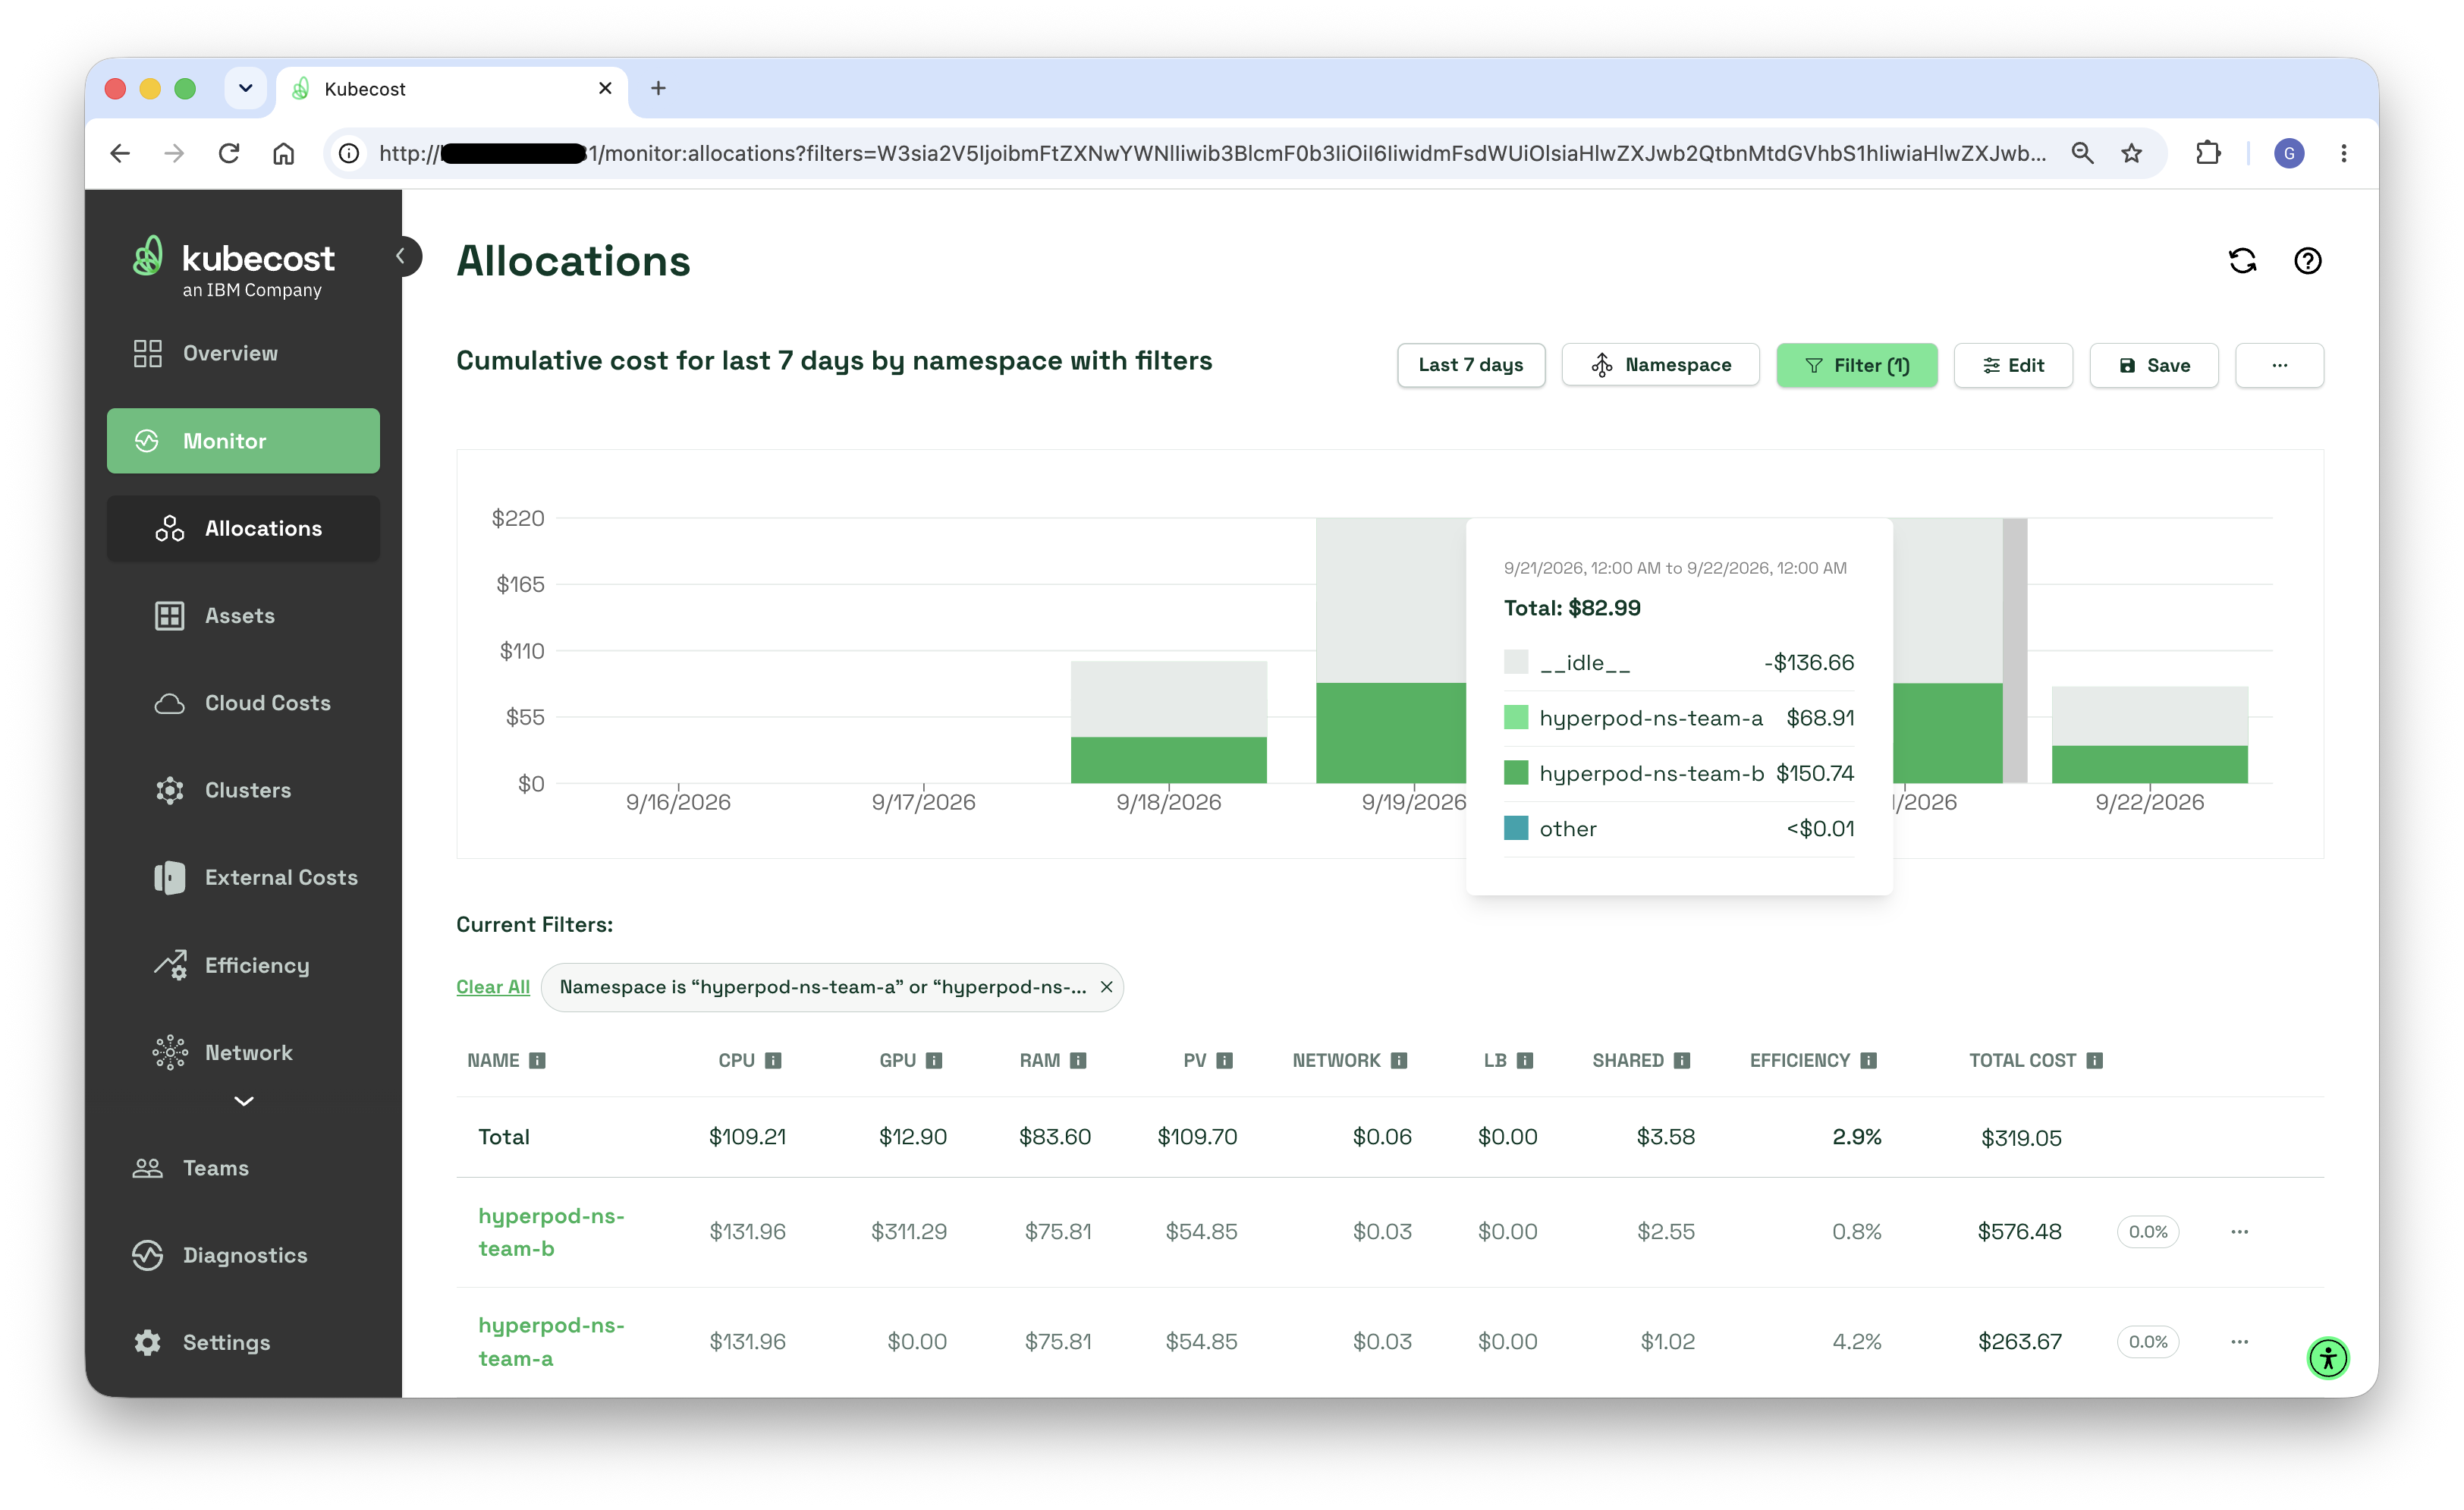
Determine 13: Kubecost Allocations dashboard grouped by namespace for per-team price
Study extra: Kubecost on SageMaker HyperPod · Kubecost
Conclusion
This publish offered a reference structure for constructing multi-tenant environments on Amazon SageMaker HyperPod with EKS. By combining AWS IAM Identification Heart for authentication, per-team IAM roles for AWS degree authorization, SageMaker AI domains for a tailor-made workspace expertise, Kubernetes namespaces for workload isolation, HyperPod Activity Governance for truthful useful resource allocation, and namespace-level price allocation for per-team spend visibility, a number of groups can effectively share a single HyperPod EKS cluster.
It is a versatile, composable strategy that mixes a number of constructing blocks right into a cohesive answer. The structure accommodates quite a lot of use circumstances and organizational buildings. For instance, organizations can prolong this sample to attach groups to HyperPod Slurm clusters alongside EKS, offering a unified multi-tenant expertise throughout totally different orchestration backends.
Whereas this strategy requires assembling and configuring a number of elements, the result’s a excessive diploma of management and customization that may be tailor-made to every group’s particular isolation, compliance, and operational necessities. The foundational patterns (id federation, namespace isolation, RBAC, quota-based governance, and price allocation) will stay relevant.
To get began, strive constructing this multi-tenant setup by yourself Amazon SageMaker HyperPod EKS cluster, and adapt the constructing blocks to your group’s isolation, governance, and cost-allocation necessities.
In regards to the authors