
Organizations constructing functions powered by synthetic intelligence (AI) face a recurring problem: giving giant language mannequin (LLM) brokers entry to enterprise knowledge lakes with out duplicating integration logic throughout each agent and utility. Most groups start by wiring brokers on to databases and APIs, with no shared gateway resembling a Mannequin Context Protocol (MCP) server in between. Every new dataset calls for customized code, and every agent reimplements its personal entry management. Because the variety of datasets or brokers grows, permission enforcement drifts, and onboarding a brand new knowledge supply turns into a multi-day engineering effort.
Our crew helps Amazon’s North America Kind Heart (NASC) community, the place planning groups depend on operational knowledge to handle capability, labor, and package deal circulate. To provide these groups conversational entry to that knowledge, we constructed a serverless Mannequin Context Protocol (MCP) server on Amazon Elastic Container Service (Amazon ECS) with AWS Fargate to handle this drawback for planning groups in NASC. The server acts as a centralized, agent-agnostic gateway between AI brokers and our enterprise knowledge lake. Exposing a brand new dataset requires solely a JSON metadata file that the server discovers mechanically on the following pipeline sync.
On this put up, we describe the structure, present how a metadata-driven strategy removes the necessity for per-dataset integration code, and clarify how the serverless infrastructure helps a number of brokers and functions in a multi-tenant setting.
Drawback assertion and design objectives
Two interrelated challenges formed how we designed this technique: fragmented knowledge entry patterns and an unsustainable onboarding mannequin.
Integration problem at scale
Our knowledge lake comprises 1000’s of datasets spanning operational metrics, enterprise analytics, and domain-specific knowledge. A number of groups needed AI assistants that would question this knowledge conversationally, however every constructed its personal integration from scratch. Every agent embedded its personal SQL era logic, schema data, and connection dealing with, so a schema change meant patching each agent individually. Entry management was fragmented, with no single audit level for knowledge entry selections. Onboarding a brand new dataset required customized instrument code, question validation, and redeployment, sometimes a multi-day effort per desk.
Design objectives
We established 4 necessities:
- Configuration-driven knowledge lake entry. Including a dataset requires solely a metadata file, not code.
- Agent-agnostic instrument interfaces. Any MCP-compatible shopper can invoke the identical instruments.
- Centralized permission enforcement. Entry management is enforced on the MCP server layer.
- Elastic infrastructure. The system scales with bursty AI workload patterns.
Answer overview
The structure separates issues into 4 layers (shopper, MCP server, instruments, and knowledge-base refresh), every independently scalable and deployable. A metadata catalog underpins the instruments layer, storing schema descriptions, column-level semantics, and desk relationships that the AI agent references when producing SQL. As a result of the agent derives schema data from the catalog at question time, there isn’t any have to hardcode desk buildings or redeploy when schemas change. The knowledge-base refresh layer retains that catalog present, indexing new dataset metadata because it arrives. The next sections describe every layer intimately.
Structure walkthrough
The next diagram reveals the request circulate from consumer question to knowledge layer throughout all 4 layers. A consumer submits a question from a shopper utility (net chat, Slack, an IDE plugin, or an exterior agent). The request resolves by Amazon Route 53 for DNS and reaches an Software Load Balancer in a public subnet, configured with HTTPS and AWS WAF. The load balancer routes to Amazon Cognito, which authenticates the consumer and enriches the request. Authenticated visitors then enters the non-public subnet, the place the shopper layer runs on Amazon ECS Fargate. This layer handles session state in Amazon DynamoDB and forwards requests by an inner Software Load Balancer to the MCP server layer, additionally on Amazon ECS Fargate. Within the MCP server layer, an AI agent powered by Amazon Bedrock orchestrates instruments constructed with FastMCP (a Python framework for constructing MCP servers). Amazon Bedrock Guardrails is utilized to each mannequin interplay. On the best, the info layer holds the instrument backends. Amazon Athena and Amazon Redshift run SQL queries towards the info lake, and Amazon Bedrock Information Bases, the totally managed Retrieval Augmented Era (RAG) functionality, handles semantic search. Information ingestion into Amazon Easy Storage Service (Amazon S3) and the data bases is dealt with by AWS Lambda. Every layer is described intimately within the sections that observe.
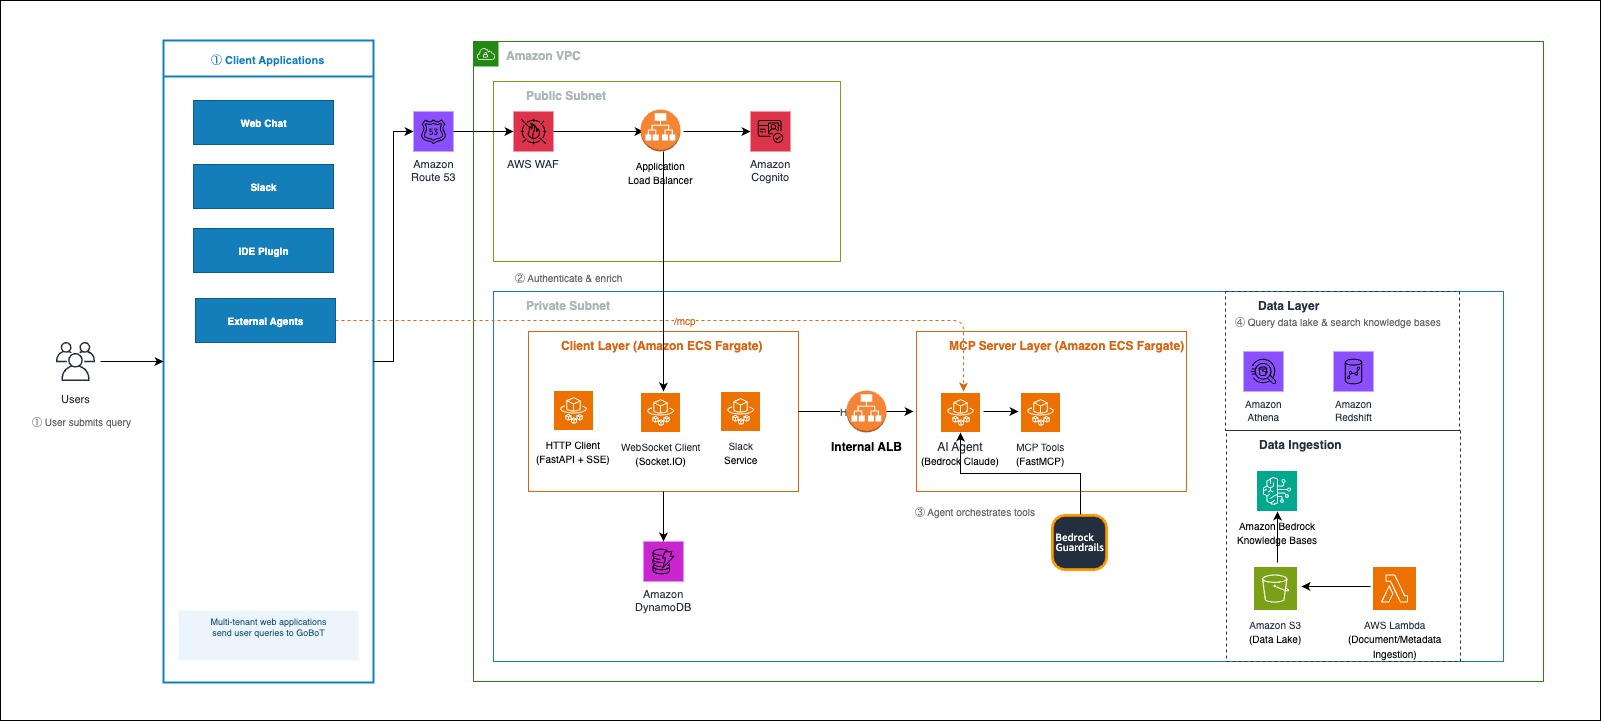
Determine 1: Request circulate by the serverless MCP server, from shopper functions to the info layer
MCP shopper layer: Authentication and session administration
A request flows from the shopper utility by Amazon Route 53 for DNS decision to an Software Load Balancer configured with HTTPS and AWS WAF. The load balancer forwards visitors to the Amazon ECS Fargate shopper service, which integrates with Amazon Cognito for JSON Internet Token (JWT) authentication and Amazon DynamoDB for session storage.
A context mapping configuration drives this enrichment, scoping every question to solely the related tables. In our testing, this scoping retains end-to-end interplay latency within the 15–20 second vary. The next instance reveals a context mapping configuration:
When a context specifies tables, the MCP server narrows its search of the metadata catalog to these tables, decreasing noise and enhancing SQL era accuracy. Including a brand new enterprise area requires solely including an entry to this mapping.
MCP server layer: Stateless execution with dialog state
The MCP server runs by itself ECS Fargate cluster, remoted from the shopper layer. Requests attain it by Amazon Route 53 and an inner Software Load Balancer in a personal subnet. The server handles full orchestration together with question evaluation, instrument choice, execution, and response era. By means of the MCP protocol endpoint (/mcp), a FastMCP-powered JSON-RPC interface, exterior MCP-compatible purchasers resembling Amazon Q Developer or IDE extensions can uncover and invoke instruments immediately.
Fargate duties are stateless with dialog state endured in DynamoDB, so duties might be changed or scaled with out knowledge loss. When a request arrives, the agent retrieves session historical past, analyzes consumer intent utilizing Amazon Bedrock, discovers and invokes acceptable instruments, and streams outcomes again to the consumer.
Instruments layer and metadata-driven knowledge lake entry
Every instrument is registered with FastMCP and discoverable at runtime:
| Sr.no | Instrument | Backend | Objective |
| 1 | SQL question instruments |
Amazon Athena Amazon Redshift |
SQL queries towards any configured dataset within the knowledge lake and Redshift |
| 2 | Doc and metadata search | Amazon Bedrock Information Bases | Semantic search over inner documentation, desk metadata and crew wikis |
| 3 | Coverage search | Amazon Bedrock Information Bases | Search operational insurance policies and normal procedures |
The Athena question instruments are the first interface to the info lake. The agent first queries the metadata catalog to know obtainable schemas, generates an optimized SQL question by Amazon Bedrock, validates and auto-corrects the SQL for Athena compatibility, then executes it. Outcomes circulate again to the orchestrating agent for pure language synthesis.
Accountable AI controls
Amazon Bedrock Guardrails is utilized to all LLM interactions and is designed to filter dangerous content material, implement grounding checks, and assist block immediate injection makes an attempt. These guardrails function as manufacturing controls on the MCP server layer, so each related agent advantages from the identical content material security insurance policies no matter the way it connects. The Athena question instruments implement SELECT-only queries, rejecting write operations on the instrument stage earlier than they attain the info lake.
Information base refresh layer: Dataset onboarding with a single JSON file
All the system is constructed round configuration-driven extensibility. Including a brand new dataset requires a metadata JSON file describing the desk and an optionally available context mapping entry. The file captures the desk’s schema, enterprise context, and column-level semantics. It serves as the only supply of reality that the AI agent makes use of to know and question the dataset:
The business_description_for_the_table subject carries engine-specific question hints, resembling “all the time use date() to wrap string literals,” that scale back SQL validation failures. The column_details subject pairs every column_name [type] with a pure language description and pattern values, giving the agent each schema consciousness and enterprise semantics. The sample_values subject issues for correct WHERE clause era as a result of the agent learns actual knowledge patterns, for example that warehouse_id holds codes like FC-EAST-07 fairly than spelled-out names like “East area facility.”
The pipeline picks up metadata recordsdata, generates vector embeddings with Amazon Titan Textual content Embeddings, and indexes them into Amazon Bedrock Information Bases. As soon as listed, the desk is discoverable by all related brokers with out handbook re-indexing or server restarts.
To enhance accuracy for particular functions, an engineer can optionally affiliate the dataset with a enterprise context. This narrows the search scope, so the agent prioritizes the best tables. The next instance reveals a context mapping entry:
If no context is specified, the agent searches throughout all listed tables. The context mapping reduces latency and improves SQL accuracy by limiting the search area. This scoping is optionally available and might be added at any time with out modifying the metadata recordsdata themselves.
Placing it collectively: A question in motion
When a consumer asks, “What have been our high 10 highest-value orders final month?”, the shopper enriches the request with enterprise context to slender scope. The agent converts the query right into a vector embedding, searches the metadata catalog for matching schemas, and selects probably the most related desk through a light-weight LLM name.
Utilizing the chosen schema, column descriptions, and engine-specific question hints, the agent generates a SQL assertion resembling:
The SQL is validated and auto-corrected for engine compatibility, then executed towards Amazon Athena. The agent codecs the outcomes right into a pure language response and streams it again to the consumer. In our testing, this end-to-end circulate completes inside 15–20 seconds.
The identical orchestration extends past pure SQL. As a result of doc search is registered as one other instrument on the identical server, the agent can reply questions that span structured and unstructured sources in a single flip, resembling “What was our return charge for This fall, and what does the product crew’s evaluation say concerning the root causes?” For that request, the agent runs an Athena question for the return-rate determine and a Information Bases doc seek for the evaluation, then combines each into one response.
Safety and multi-tenant entry
That single-turn orchestration works solely as a result of each instrument name passes by the identical managed gateway. The structure makes use of layered safety fairly than a single enforcement level. The MCP server runs in non-public subnets behind an inner Software Load Balancer and isn’t reachable from the web. Solely the shopper layer, which sits behind a public-facing Software Load Balancer with AWS WAF, can route requests to it. Amazon Cognito validates consumer id on the shopper layer, and solely authenticated, token-bearing requests are forwarded downstream. On the instrument stage, the Athena question instruments implement SELECT-only queries, rejecting write operations earlier than they attain the info lake. All instrument invocations are logged to Amazon CloudWatch with structured JSON, which supplies safety groups a single audit level for knowledge entry throughout each agent and utility. This structure is accessible within the AWS Areas the place Amazon Bedrock and Amazon Bedrock Information Bases can be found.
This centralized design can be what makes the server multi-tenant. As a result of the standardized /mcp endpoint accepts any MCP-compatible shopper no matter which LLM or orchestration framework it makes use of, a number of brokers share the identical instruments and the identical entry controls. Including a brand new agent requires solely pointing it on the server endpoint, so onboarding one other crew extends the system with out weakening or duplicating the safety mannequin.
Serverless infrastructure and scaling
Every layer scales by a mechanism suited to its workload sample:
| Layer | Scaling mechanism | Set off |
| Consumer (ECS Fargate) | ECS Service Auto Scaling | CPU utilization (50% threshold) |
| MCP Server (ECS Fargate) | ECS Service Auto Scaling | CPU/Reminiscence utilization |
| Athena | Serverless (automated) | Question concurrency |
| Amazon Bedrock | Managed service scaling | Inference requests |
Amazon ECS Fargate offers serverless compute with no EC2 cases to handle. Downstream providers (Athena, Bedrock) scale mechanically, so the system handles a single question or a whole lot of concurrent queries with out configuration adjustments.
Use circumstances and extensions
This structure helps a number of patterns past primary question-answering. Enterprise data assistants can mix knowledge lake queries with doc search to reply complicated questions spanning each structured knowledge and unstructured data, resembling “What’s our return charge for This fall, and what does the product crew’s evaluation say concerning the root causes?” Inner analytics copilots let enterprise customers question the info lake conversationally with out writing SQL, counting on the metadata descriptions and question hints to information the agent towards correct, performant question patterns.
The standardized /mcp endpoint additionally helps multi-agent workflows. A number of specialised brokers for knowledge evaluation, doc retrieval, and operational alerting can share the identical MCP server, every accessing the total instrument suite by a standard protocol. Onboarding a brand new crew’s knowledge follows the identical configuration-driven sample. They add a metadata JSON file, and inside one pipeline sync cycle their dataset is discoverable by each related agent and utility.
Conclusion
A centralized MCP server on Amazon ECS Fargate offers a scalable, safe gateway between AI brokers and enterprise knowledge lakes. The metadata-driven strategy removes the necessity for per-dataset integration code, and the Mannequin Context Protocol normal means any MCP-compatible shopper can join with out customized adapters.
The important thing architectural choice is separating the instrument layer from the agent layer. Brokers evolve quickly, however knowledge entry patterns ought to outlive any single agent implementation. Treating extensibility as a configuration drawback fairly than a code drawback accelerates onboarding.
To be taught extra, see Amazon ECS on AWS Fargate, Amazon Bedrock, the Amazon Bedrock Information Bases consumer information, Amazon Athena, and the Mannequin Context Protocol specification.
Subsequent steps
We’re extending this structure in two instructions. First, finer-grained entry management the place desk homeowners can mark delicate columns as restricted per permission group, and the agent mechanically excludes these columns from generated SQL with out prompt-level adjustments.
Second, closing the suggestions loop in order that when queries fail or produce low-confidence outcomes, the system captures the failure sample and surfaces focused options for enhancing column descriptions, including question hints.
Concerning the authors