
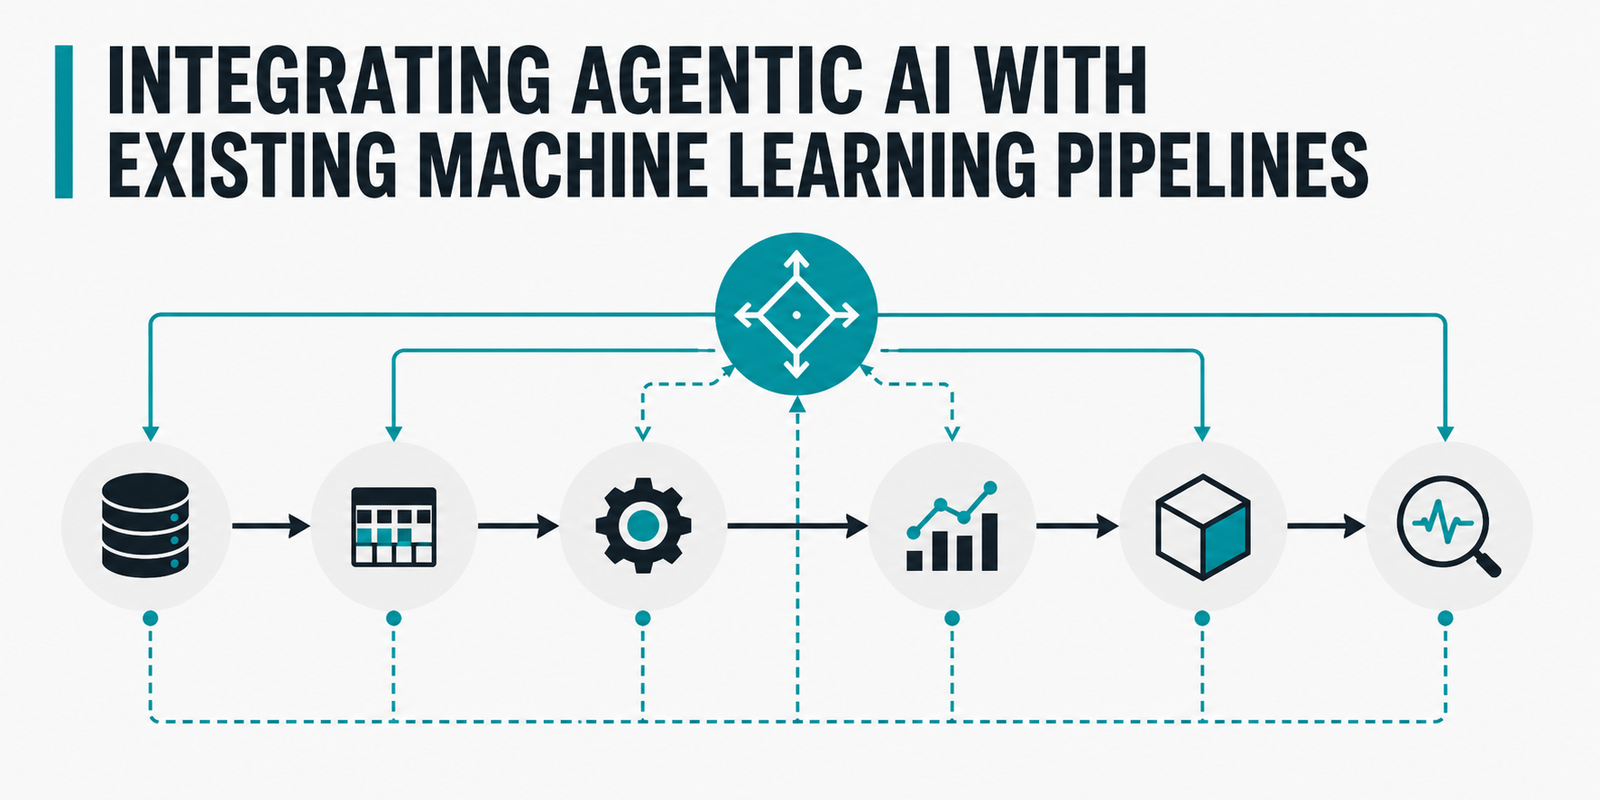
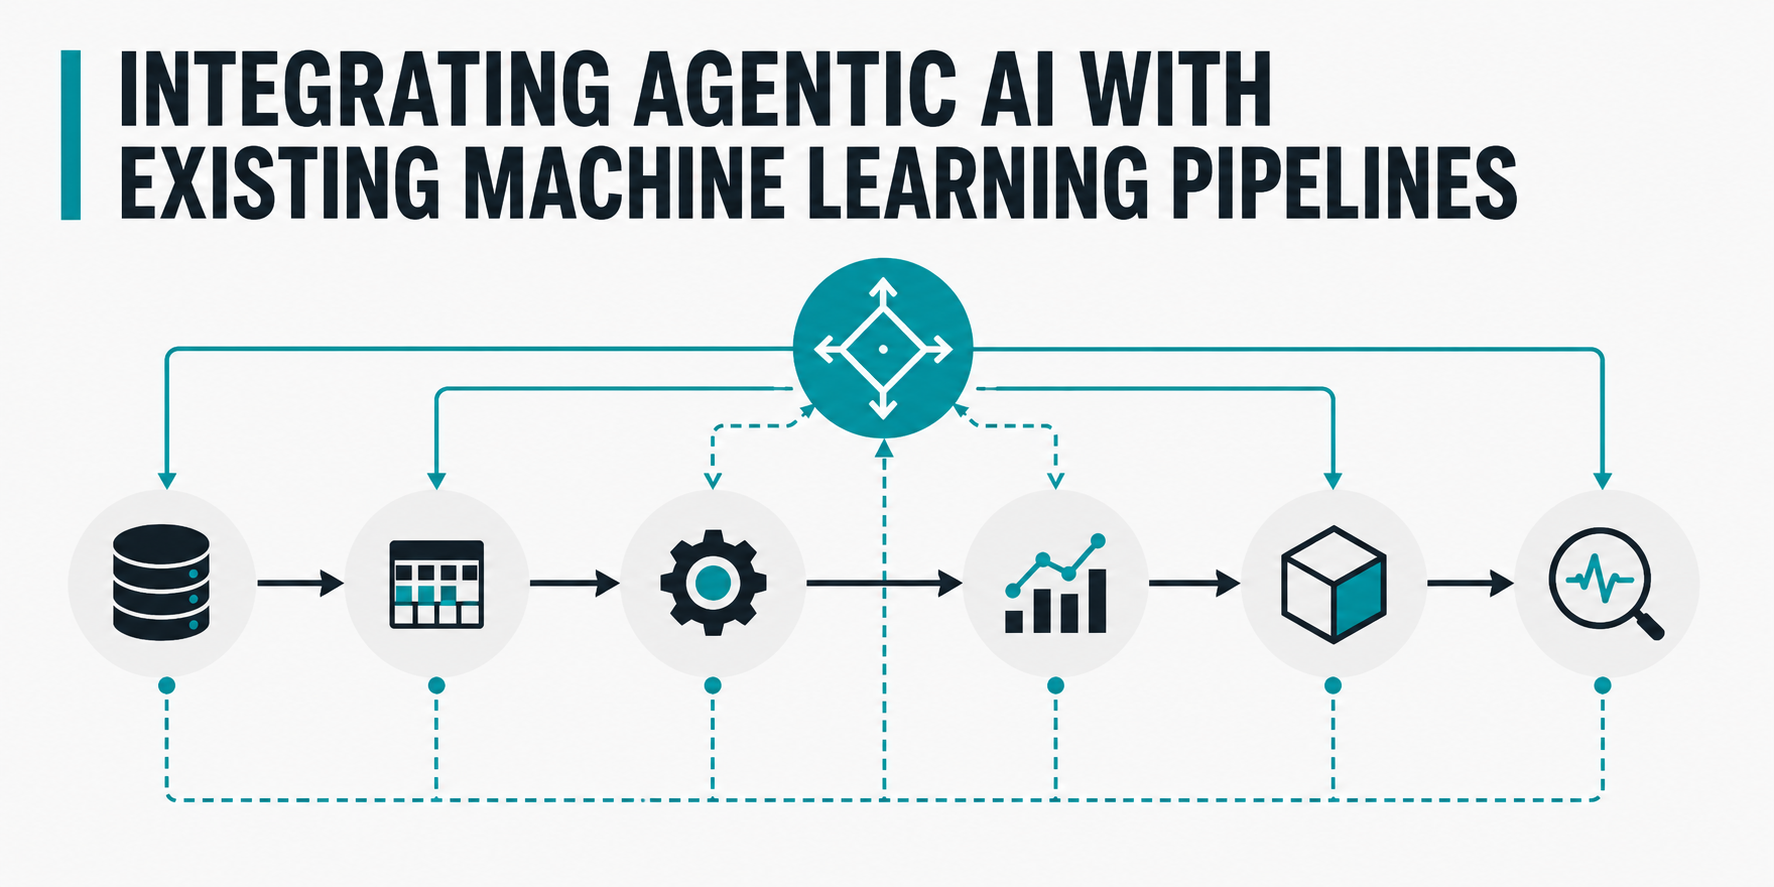
On this article, you’ll learn to mix a classical machine studying pipeline with an agentic AI system to construct a hybrid, autonomous buyer retention workflow.
Matters we are going to cowl embrace:
- How one can generate an artificial dataset and practice a random forest classifier for buyer churn prediction utilizing scikit-learn.
- How one can design an agentic AI system — full with instruments and an LLM-powered reasoning core — that interprets machine studying predictions and acts on them autonomously.
- How one can wire the machine studying pipeline and the agent collectively right into a single, end-to-end runnable Python utility.
Introduction
Agentic AI and machine studying pipelines are removed from incompatible in the case of constructing production-ready AI purposes. The truth is, embracing them as two sides of the identical coin has grow to be greater than a mere development: it constitutes a contemporary foundational structure sample that drives the shift from passive predictive analytics to autonomous decision-making and motion.
Conventional machine studying pipelines excel at sample recognition duties of various complexity, however they’re purely reactive of their base type. In the meantime, agentic AI programs are all about proactivity: mixed with predictive machine studying fashions, they will construct on the insights yielded by such fashions to plan, use instruments, and handle real-world use circumstances with little or no human steerage.
On this hands-on article, we are going to present you the way to bridge the hole between reactive machine studying fashions and proactive AI brokers. We are going to assemble a light-weight, free, runnable Python pipeline that:
- Predicts buyer churn based mostly on a classical machine studying mannequin constructed with scikit-learn.
- Palms the obtained predictions over to an agent endowed with a state-of-the-art LLM to autonomously motive and execute completely different buyer retention methods.
Stipulations
All the coding tutorial may be run without spending a dime in Google Colab or a neighborhood Jupyter pocket book, supplied you’ve got the mandatory libraries put in and imported.
In case you are utilizing Colab, on the time of writing, the one library you would possibly have to manually set up is Groq:
Be sure to additionally import the next:
|
import numpy as np from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split from groq import Groq |
Since Groq — one among in the present day’s most succesful open-source LLM suppliers — requires an API key, remember to register on their web site and create your individual API key right here. You have to to include it in your pocket book or Google Colab account. The code under is designed to learn the API key from the “Secrets and techniques” part discovered on the left-hand sidebar in Google Colab: create a brand new secret variable there known as GROQ_API_KEY, and paste your precise Groq API key into the “worth” subject.
These directions will enable you inject the newly added API key into your program:
|
import os from google.colab import userdata
# Injecting the Colab secret into commonplace atmosphere variables os.environ[“GROQ_API_KEY”] = userdata.get(‘GROQ_API_KEY’) |
Step-by-Step Information
As soon as the stipulations are arrange, we are going to begin constructing the classical machine studying pipeline — for buyer churn prediction — that may later be prolonged by incorporating agentic AI rules and instruments.
First, we’d like a prospects dataset to feed to our machine studying mannequin. For this instance, we are going to synthetically generate our personal dataset containing 500 prospects, every described by two predictor options plus a goal variable indicating whether or not the client is liable to churn. The 2 enter options are the month-to-month buyer spend and the variety of help tickets issued by the client: each are real-world predictors of a buyer’s willingness to stick with or abandon a model. Discover that the code makes use of numpy capabilities to introduce random noise, making the artificially generated information look sensible:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
# ========================================== # 0. SYNTHETIC DATASET GENERATION # ==========================================
# Producing a sensible dataset of 500 prospects described by two enter options np.random.seed(42) n_samples = 500
# Function 1: Month-to-month buyer’s spend (uniformly distributed between $10 and $150) spend = np.random.uniform(10, 150, n_samples)
# Function 2: Assist tickets issued by buyer (Poisson distribution, averaging 1.5 tickets) tickets = np.random.poisson(lam=1.5, dimension=n_samples)
# Generate goal variable / Binary class (Churn): # Churn threat will increase with extra tickets and reduces with greater spend base_churn_risk = (tickets * 0.15) + np.the place(spend < 30, 0.3, 0) – np.the place(spend > 100, 0.2, 0) # Add some random noise to make the dataset sensible base_churn_risk += np.random.regular(0, 0.1, n_samples) base_churn_risk = np.clip(base_churn_risk, 0, 1) # 0 = Retain, 1 = Churn (Threshold at 0.5) y = (base_churn_risk > 0.5).astype(int) X = np.column_stack((spend, tickets)) |
Subsequent, we construct a easy, classical machine studying pipeline by splitting the dataset into coaching and check units and coaching a random forest ensemble classifier. We confirm the mannequin’s efficiency on the check set earlier than persevering with:
|
# ========================================== # 1. CLASSIC ML PIPELINE (Predictive -> Classification) # ==========================================
# Practice/Check Break up X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Practice the predictive classifier on the bigger dataset print(f“Coaching ML Mannequin on {len(X_train)} data…”) ml_model = RandomForestClassifier(n_estimators=50, max_depth=5, random_state=42) ml_model.match(X_train, y_train) print(f“Mannequin Accuracy on Check Set: {ml_model.rating(X_test, y_test)*100:.1f}%n”) |
Prediction outcomes on the check information:
|
Coaching ML Mannequin on 400 data... Mannequin Accuracy on Check Set: 91.0% |
A 91% accuracy is sweet sufficient for our functions, so we are going to proceed to incorporating our agent into the loop.
The primary side we are going to create for our agent is its “fingers” — in different phrases, the instruments the agent can use to carry out particular actions because of its reasoning and decision-making. Whereas in real-world settings these instruments usually work together with exterior parts, companies, and databases through API calls or comparable protocols, we mock two customer-oriented actions right here utilizing easy printed messages:
|
# ========================================== # 2. THE TOOLS (Agentic “Palms”) # ========================================== # These are two capabilities the agent can be allowed to set off in the true world. # Actions are mocked and emulated by utilizing parameterized print messages def send_discount(customer_id): return f“[Action Executed] Despatched a 20% low cost code to Buyer {customer_id}.”
def schedule_support_call(customer_id): return f“[Action Executed] Escalated Buyer {customer_id} to a human agent for a check-in.” |
Whereas having the agent name its accessible instruments is the way it exerts influence as soon as deployed, it’s the cognition core — accountable for the agent’s reasoning and execution — the place the precise “intelligence” takes place:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 |
# ========================================== # 3. THE AGENT’S COGNITION (Reasoning & Execution) # ========================================== class RetentionAgent: def __init__(self): print(“Connecting to Groq API (Llama 3.3 70B)…n”) # Robotically picks up the GROQ_API_KEY atmosphere variable self.shopper = Groq() self.model_name = “llama-3.3-70b-versatile”
def _reason(self, immediate): # We use the usual Chat Completions API chat_completion = self.shopper.chat.completions.create( messages=[ { “role”: “system”, “content”: “You are an autonomous customer retention agent. You must output exactly one word: either ‘call’ or ‘discount’.” }, { “role”: “user”, “content”: prompt } ], mannequin=self.model_name, temperature=0.0, # Zero temperature ensures deterministic, logical selections ) return chat_completion.selections[0].message.content material.strip().decrease()
def process_customer(self, customer_id, options): print(f“— Processing Buyer {customer_id} —“)
# Step A: Getting the prediction from the traditional ML pipeline churn_prob = ml_model.predict_proba([features])[0][1] spend_val, tickets_val = options print(f“ML Prediction: {churn_prob*100:.0f}% churn threat.”)
# Step B: Autonomous Guardrail – solely act if the chance is excessive if churn_prob < 0.5: return “Agent Resolution: No motion wanted. Buyer is low threat.n”
# Step C: Agentic Reasoning (Context Injection) # A 70B mannequin from Groq handles this logic effortlessly, together with the easy math reasoning wanted on this use case. immediate = ( f“Buyer {customer_id} has a {churn_prob*100:.0f}% threat of churning. “ f“They at present spend ${spend_val:.2f} per thirty days and have filed {int(tickets_val)} help tickets. “ f“Enterprise Rule: If a buyer has filed greater than 2 help tickets, they’re annoyed and wish a human ‘name’. “ f“In any other case, they’re simply price-sensitive and we should always ship a ‘low cost’.” )
# The LLM “thinks” and decides on the instrument resolution = self._reason(immediate) print(f“Agent Reasoning output: ‘{resolution}'”)
# Step D: Device Execution (Routing to a selected agent’s “hand”) if “name” in resolution: outcome = schedule_support_call(customer_id) elif “low cost” in resolution: outcome = send_discount(customer_id) else: outcome = f“[Action Failed] Agent returned an unrecognized instrument title: {resolution}”
return outcome + “n” |
Let’s briefly break down the code above:
- Utilizing object-oriented programming, we created a specialised agent for our goal area known as
RetentionAgent. Importantly, this agent is linked to an LLM that acts as its internal cognition engine. We particularly selected a Llama 3.3 mannequin served by Groq, which is light-weight sufficient to run feasibly in a pocket book however highly effective sufficient to reliably carry out the supposed reasoning job. - The agent’s
_reason()technique prepares the immediate for the LLM and configures mannequin settings acceptable to our state of affairs, comparable to setting temperature to zero for deterministic output. - The agent’s
process_customer()technique bridges the hole with the machine studying mannequin constructed earlier. It fetches buyer churn predictions and constructs a immediate that injects the prediction alongside different buyer information, asking the LLM what motion to take. The core resolution logic that triggers agent motion is dealt with right here.
As soon as all of the constructing blocks are in place, it’s time to run our hybrid ML-agentic pipeline. We instantiate the agent and check it on three instance prospects. Pay shut consideration to the profiles of those three prospects and cross-reference them with the LLM immediate outlined contained in the agent’s reasoning technique:
|
# ========================================== # 4. RUN THE PIPELINE # ========================================== agent = RetentionAgent()
# Testing the pipeline on a couple of particular profiles to see the routing in motion
# Check Case 1: Average spend, low tickets -> Mannequin would possibly predict low/reasonable threat. # If excessive threat, agent ought to choose low cost. print(agent.process_customer(customer_id=101, options=[25.50, 1]))
# Check Case 2: Average spend, excessive tickets -> Mannequin predicts excessive threat, Agent ought to schedule name. print(agent.process_customer(customer_id=102, options=[45.00, 5]))
# Check Case 3: Excessive spend, zero tickets -> Mannequin predicts very low threat, Agent bypasses. print(agent.process_customer(customer_id=103, options=[140.00, 0])) |
Output:
|
Connecting to Groq API (Llama 3.3 70B)...
—– Processing Buyer 101 —– ML Prediction: 57% churn threat. Agent Reasoning output: ‘low cost’ [Action Executed] Despatched a 20% low cost code to Buyer 101.
—– Processing Buyer 102 —– ML Prediction: 88% churn threat. Agent Reasoning output: ‘name’ [Action Executed] Escalated Buyer 102 to a human agent for a verify–in.
—– Processing Buyer 103 —– ML Prediction: 0% churn threat. Agent Resolution: No motion wanted. Buyer is low threat. |
The outcomes align with what one would anticipate. That stated, remember that the mannequin alternative issues: we chosen an LLM that’s well-suited to this job and set its temperature to zero to forestall non-deterministic habits, which is undesirable on this context. In the event you select a distinct mannequin, your outcomes might differ.
Closing Remarks
On this article, we constructed a hybrid pipeline step-by-step that mixes classical machine studying for buyer churn prediction with an agentic AI resolution able to turning these predictions into an autonomous reasoning, decision-making, and motion workflow. This demonstrates the way to bridge the hole between two key pillars of contemporary AI options in company and organizational environments.