
On this article, you’ll learn to construct a multi-modal RAG pipeline in Python that retrieves and causes over each textual content and pictures extracted from complicated paperwork.
Matters we are going to cowl embrace:
- How you can parse a PDF into separate textual content and picture parts utilizing the
unstructuredlibrary. - How you can generate searchable textual content summaries for extracted photographs utilizing GPT-4o, and retailer every part in a multi-vector retrieval system.
- How you can question the pipeline with a multimodal immediate that passes each textual content chunks and uncooked photographs to GPT-4o for a grounded last reply.
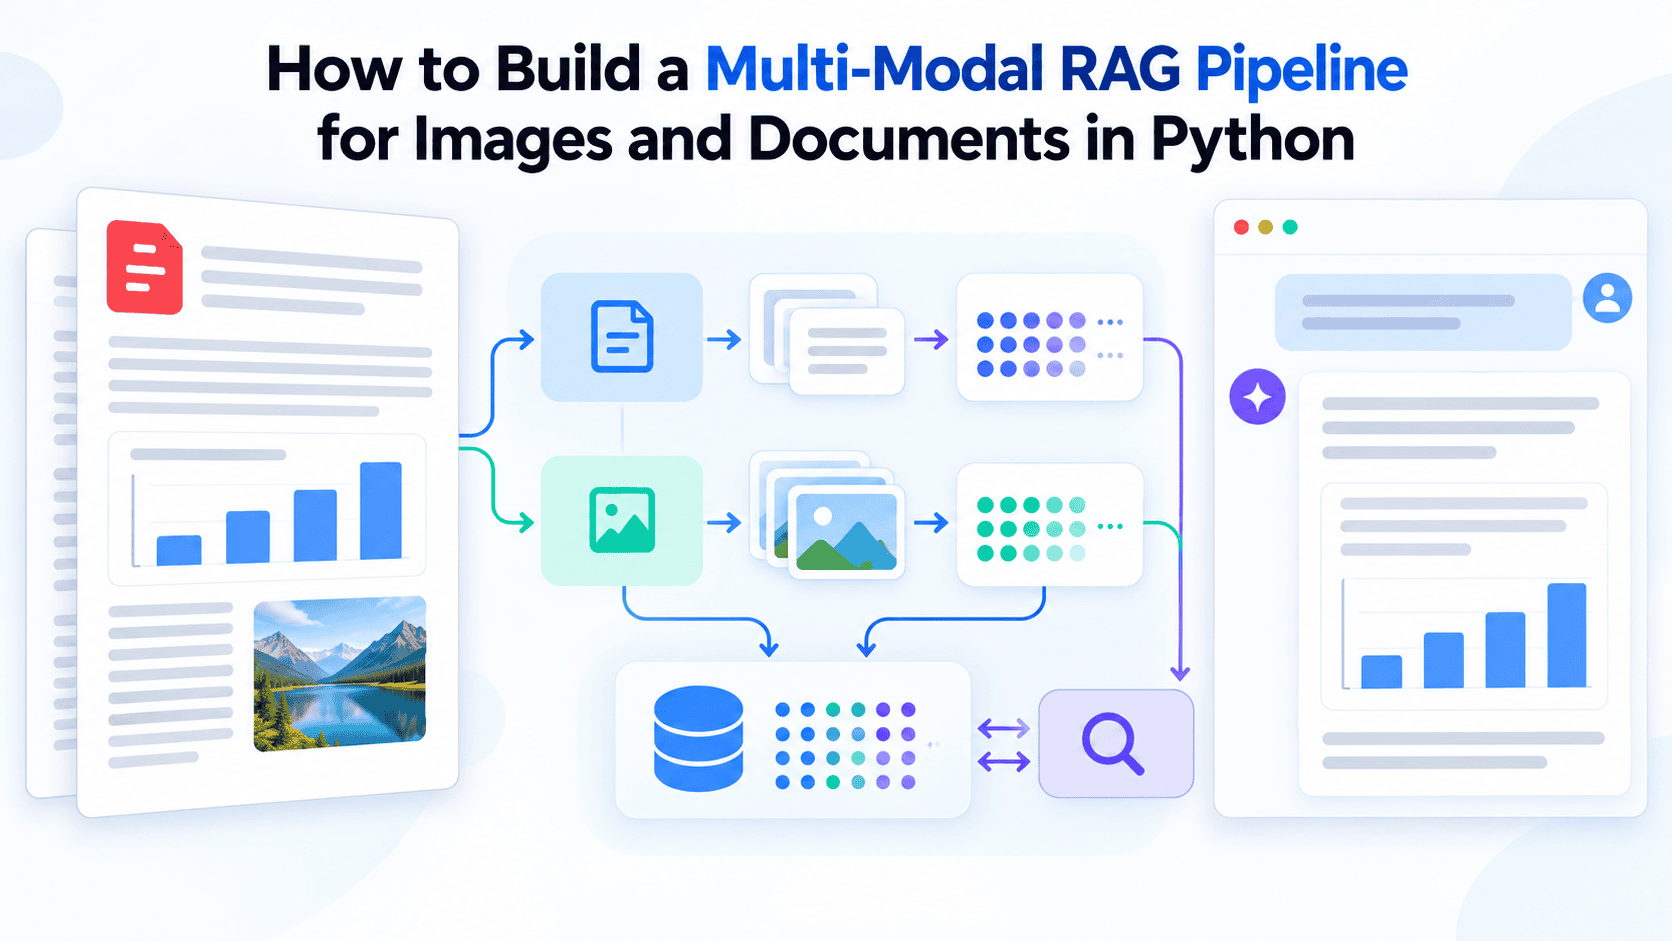
Commonplace retrieval-augmented technology works nice for plain textual content. However feed it a PDF full of embedded charts, scanned diagrams, or information tables, and issues crumble quick. Textual content-based chunking destroys desk formatting and skips photographs, so your pipeline finally ends up answering questions from an incomplete image of the doc.
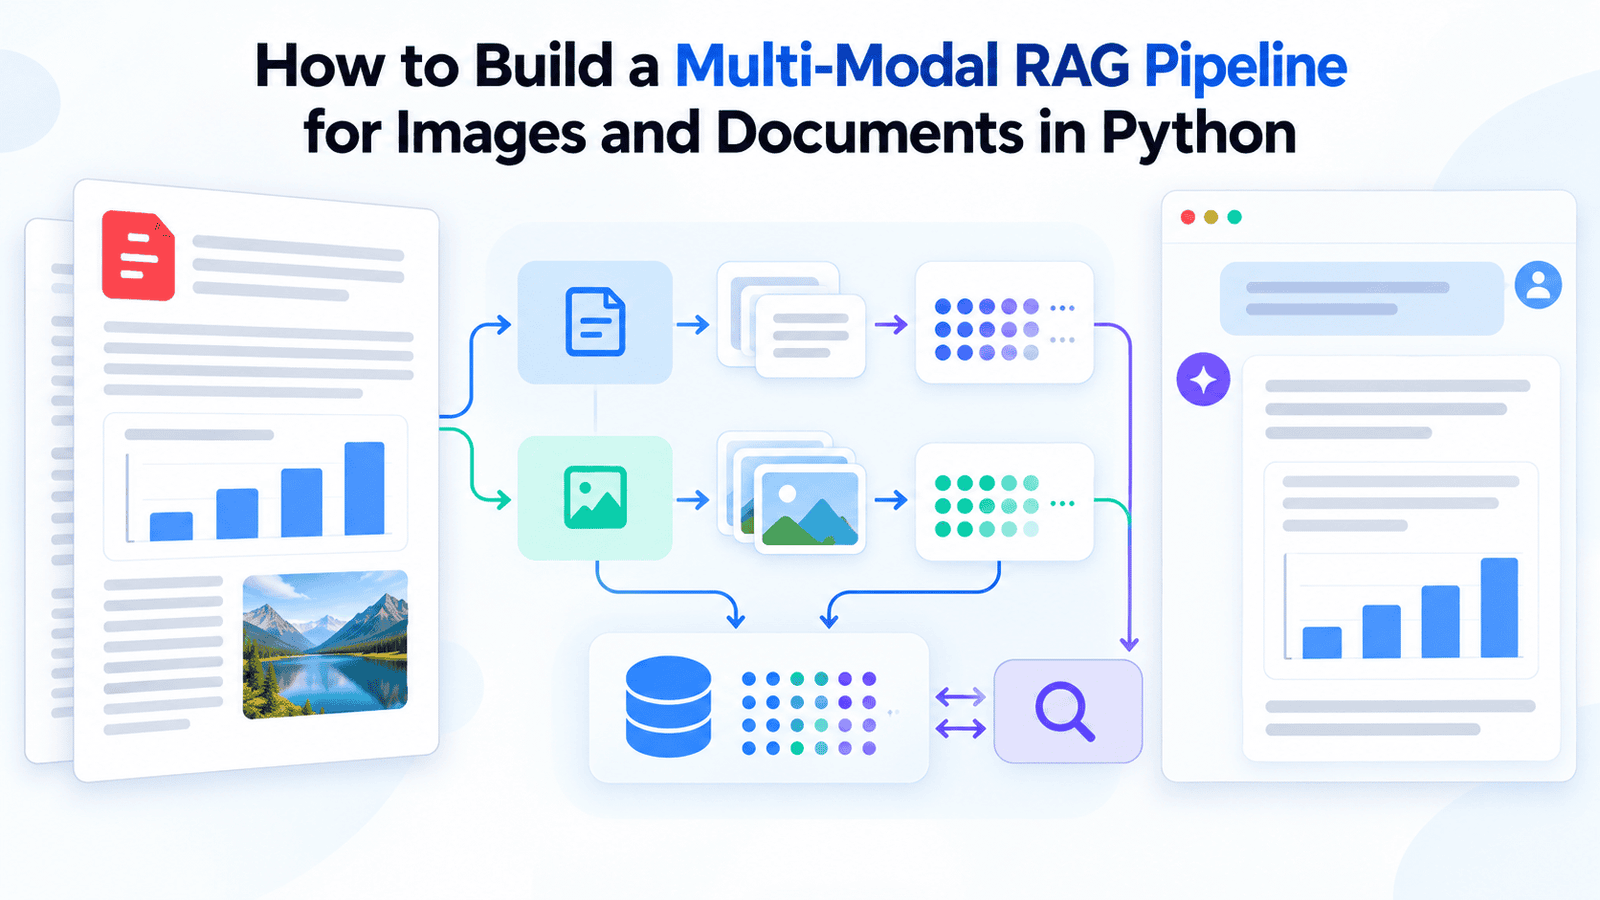
A multi-modal RAG pipeline fixes this by treating photographs as first-class retrievable objects alongside textual content. On this tutorial, we’ll construct one in Python utilizing LangChain, the unstructured library, and the OpenAI API. We’ll parse a posh PDF into separate textual content and picture parts, generate searchable summaries for every picture, retailer every part in a multi-vector retrieval system, and question it with a immediate that returns each textual content and visible proof to GPT-4o for a last reply.
As lined in The Multimodal AI Information on KDnuggets, fashionable AI techniques are designed to cause throughout content material varieties natively. This tutorial applies that precept to a sensible drawback: paperwork that blend prose, tables, and embedded photographs. The place the MLM multi-modal RAG implementation takes a neighborhood PyTorch method suited to audio and image-heavy workloads, this information makes use of an API-driven structure that runs on commonplace {hardware} and suits enterprise doc use instances effectively.
Conditions and Setup
You’ll want an OpenAI API key and the next packages put in. The poppler-utils system dependency is required by unstructured to extract photographs from PDFs.
|
pip set up langchain langchain–openai unstructured[pdf] chromadb pillow apt–get set up –y poppler–utils |
Set your API key as an surroundings variable earlier than working any code:
|
import os os.environ[“OPENAI_API_KEY”] = “your-api-key-here” |
The pipeline has 4 levels: parse, summarize, retailer, and retrieve. Each maps to one of many code blocks beneath.
Step 1: Parsing the Doc into Textual content and Picture Parts
The unstructured library does the heavy lifting right here. Its partition_pdf() perform reads the doc and classifies every ingredient by sort. It separates paragraphs, tables, and embedded photographs as an alternative of treating the entire file as a flat stream of characters.
|
from unstructured.partition.pdf import partition_pdf
raw_elements = partition_pdf( filename=“report.pdf”, extract_image_block_types=[“Image”], extract_image_block_output_dir=“./extracted_images”, infer_table_structure=True, chunking_strategy=“by_title”, max_characters=4000, ) |
extract_image_block_output_dir tells unstructured the place to save lots of extracted picture information, whereas extract_image_block_types controls which ingredient varieties get pulled out. Subsequent, separate the returned parts into textual content and picture lists:
|
text_elements = [] image_paths = []
for el in raw_elements: if “CompositeElement” in str(sort(el)): text_elements.append(str(el)) elif “Picture” in str(sort(el)): image_paths.append(el.metadata.image_path)
print(f“Extracted {len(text_elements)} textual content chunks, {len(image_paths)} photographs”) |
The loop separates composite textual content chunks from picture parts, storing the picture file paths for the subsequent step.
Step 2: Producing Searchable Summaries for Every Picture
Textual content-based vector databases can’t index uncooked photographs, so every picture wants a textual content illustration that captures its content material in a approach that’s retrievable by a pure language question. This step passes each extracted picture to GPT-4o with a immediate designed to supply dense, searchable descriptions.
|
import base64 from openai import OpenAI
shopper = OpenAI() |
With the shopper prepared, outline a perform that base64-encodes every picture and sends it to GPT-4o with a retrieval-focused immediate:
|
def summarize_image(image_path): with open(image_path, “rb”) as f: image_data = base64.b64encode(f.learn()).decode(“utf-8”) response = shopper.chat.completions.create( mannequin=“gpt-4o”, messages=[{“role”: “user”, “content”: [ {“type”: “image_url”, “image_url”: {“url”: f“data:image/png;base64,{image_data}”}}, {“type”: “text”, “text”: “Describe this image in detail for use in a search system.”} ]}] ) return response.decisions[0].message.content material |
To run it throughout all extracted photographs:
|
image_summaries = [summarize_image(p) for p in image_paths] |
Every abstract turns into the searchable proxy for its supply picture. The uncooked picture file is stored individually and retrieved by reference when a question matches its abstract.
A notice on prices: each extracted picture triggers a GPT-4o API name at indexing time. In case you’re working with giant paperwork filled with embedded logos or icons, take into account filtering out photographs beneath a minimal file measurement earlier than passing them to summarize_image().
Step 3: Constructing the Multi-Vector Retailer
That is the place the structure diverges from commonplace RAG. A MultiVectorRetriever maintains two shops: a vector retailer that holds embedded textual content chunks and picture summaries for similarity search, and a doc retailer that holds the uncooked supply content material linked to these embeddings by means of distinctive IDs.
|
import uuid from langchain_openai import OpenAIEmbeddings from langchain_chroma import Chroma from langchain.storage import InMemoryStore from langchain.retrievers.multi_vector import MultiVectorRetriever from langchain_core.paperwork import Doc
embeddings = OpenAIEmbeddings(mannequin=“text-embedding-3-small”) vectorstore = Chroma(embedding_function=embeddings) docstore = InMemoryStore() retriever = MultiVectorRetriever(vectorstore=vectorstore, docstore=docstore) text_ids = [str(uuid.uuid4()) for _ in text_elements] image_ids = [str(uuid.uuid4()) for _ in image_summaries] |
This initializes each shops and generates a singular ID for every ingredient. The vector retailer holds the searchable summaries; the doc retailer holds the uncooked content material. With the IDs in place, populate each:
|
retriever.vectorstore.add_documents( [Document(page_content=t, metadata={“doc_id”: i}) for t, i in zip(text_elements + image_summaries, text_ids + image_ids)] ) raw_docs = ( [Document(page_content=t, metadata={“type”: “text”}) for t in text_elements] + [Document(page_content=p, metadata={“type”: “image”}) for p in image_paths] ) retriever.docstore.mset(record(zip(text_ids + image_ids, raw_docs))) |
Wrapping uncooked content material in Doc objects with an specific sort discipline retains the retrieval logic in Step 4 clear. Every ID hyperlinks an embedded abstract within the vector retailer to its corresponding uncooked Doc within the doc retailer.
Step 4: Querying the Pipeline with Multimodal Retrieval
At question time, the retriever embeds the query and finds the closest matches throughout each textual content and picture summaries. If a match factors to a picture path, the uncooked file is loaded and handed to GPT-4o alongside any retrieved textual content. GPT-4o then generates a solution grounded in each content material varieties.
|
def query_pipeline(query): docs = retriever.invoke(query) text_content, image_content = [], [] for doc in docs: if doc.metadata.get(“sort”) == “picture”: with open(doc.page_content, “rb”) as f: img_b64 = base64.b64encode(f.learn()).decode(“utf-8”) image_content.append({“sort”: “image_url”, “image_url”: {“url”: f“information:picture/png;base64,{img_b64}”}}) else: text_content.append({“sort”: “textual content”, “textual content”: doc.page_content}) |
The metadata examine routes every retrieved Doc cleanly: picture paths get opened and base64-encoded, whereas textual content chunks go by means of as-is. The perform then assembles each right into a single multimodal GPT-4o name:
|
response = shopper.chat.completions.create( mannequin=“gpt-4o”, messages=[{“role”: “user”, “content”: text_content + image_content + [{“type”: “text”, “text”: question}]}] ) return response.decisions[0].message.content material |
Name the perform with any query in regards to the doc:
|
reply = query_pipeline(“What does the income chart present for Q3?”) print(reply) |
GPT-4o causes throughout all retrieved proof — each textual content and pictures — earlier than returning a last reply.
Conclusion
This pipeline handles what commonplace RAG can’t: paperwork the place a very powerful info lives in charts, diagrams, or embedded graphics. The 4 levels are: parse with unstructured, summarize photographs with GPT-4o, retailer with a multi-vector retriever, and question with a multimodal immediate. This sample scales to analysis papers, monetary reviews, product manuals, and any doc sort that mixes textual content with visuals.
From right here, you may lengthen the pipeline by including re-ranking to enhance retrieval precision, persisting the Chroma vector retailer to disk for manufacturing use, or exploring vision-language fashions like ColPali that skip the parsing step by embedding doc pages as photographs.