Automationscribe.com
  • Home
  • AI Scribe
  • AI Tools
  • Artificial Intelligence
  • Contact Us
No Result
View All Result
Automation Scribe
  • Home
  • AI Scribe
  • AI Tools
  • Artificial Intelligence
  • Contact Us
No Result
View All Result
Automationscribe.com
No Result
View All Result

Deploy frontier AI fashions on AWS Trainium with SGLang-Neuron

admin by admin
November 12, 2026
in Artificial Intelligence
0
Deploy frontier AI fashions on AWS Trainium with SGLang-Neuron
399
SHARES
2.3k
VIEWS
Share on FacebookShare on Twitter


In the present day, Amazon introduced that SGLang-Neuron is publicly out there and could be accessed by an AWS Deep Studying Container, launched by RadixArk in collaboration with Annapurna Labs. With SGLang-Neuron, you possibly can serve fashions and generate reinforcement studying (RL) rollouts with SGLang on AWS Trainium utilizing the identical SGLang interface you employ in the present day. Trainium is a portfolio of AWS AI chips that delivers sturdy economics for AI coaching and inference at scale. Now, operating SGLang on Trainium follows the SGLang workflow you already know: you launch fashions by SGLang’s server interface and invoke the endpoint utilizing the identical technology APIs. Beneath that interface, SGLang-Neuron runs on native PyTorch. With its out-of-tree plugin design, Trainium assist and SGLang core develop independently and iterate sooner.

How SGLang runs on Trainium

SGLang-Neuron is an out-of-tree plugin that connects SGLang with AWS Trainium. Putting in the plugin registers the neuron platform by SGLang’s plugin entry factors, and setting SGLANG_PLATFORM=neuron selects it when the server begins. SGLang core continues to supply the API server, request lifecycle, RadixAttention, and prefix-cache bookkeeping. The plugin implements the Trainium-specific fashions, consideration, combination of consultants (MoE), and the graph runner.
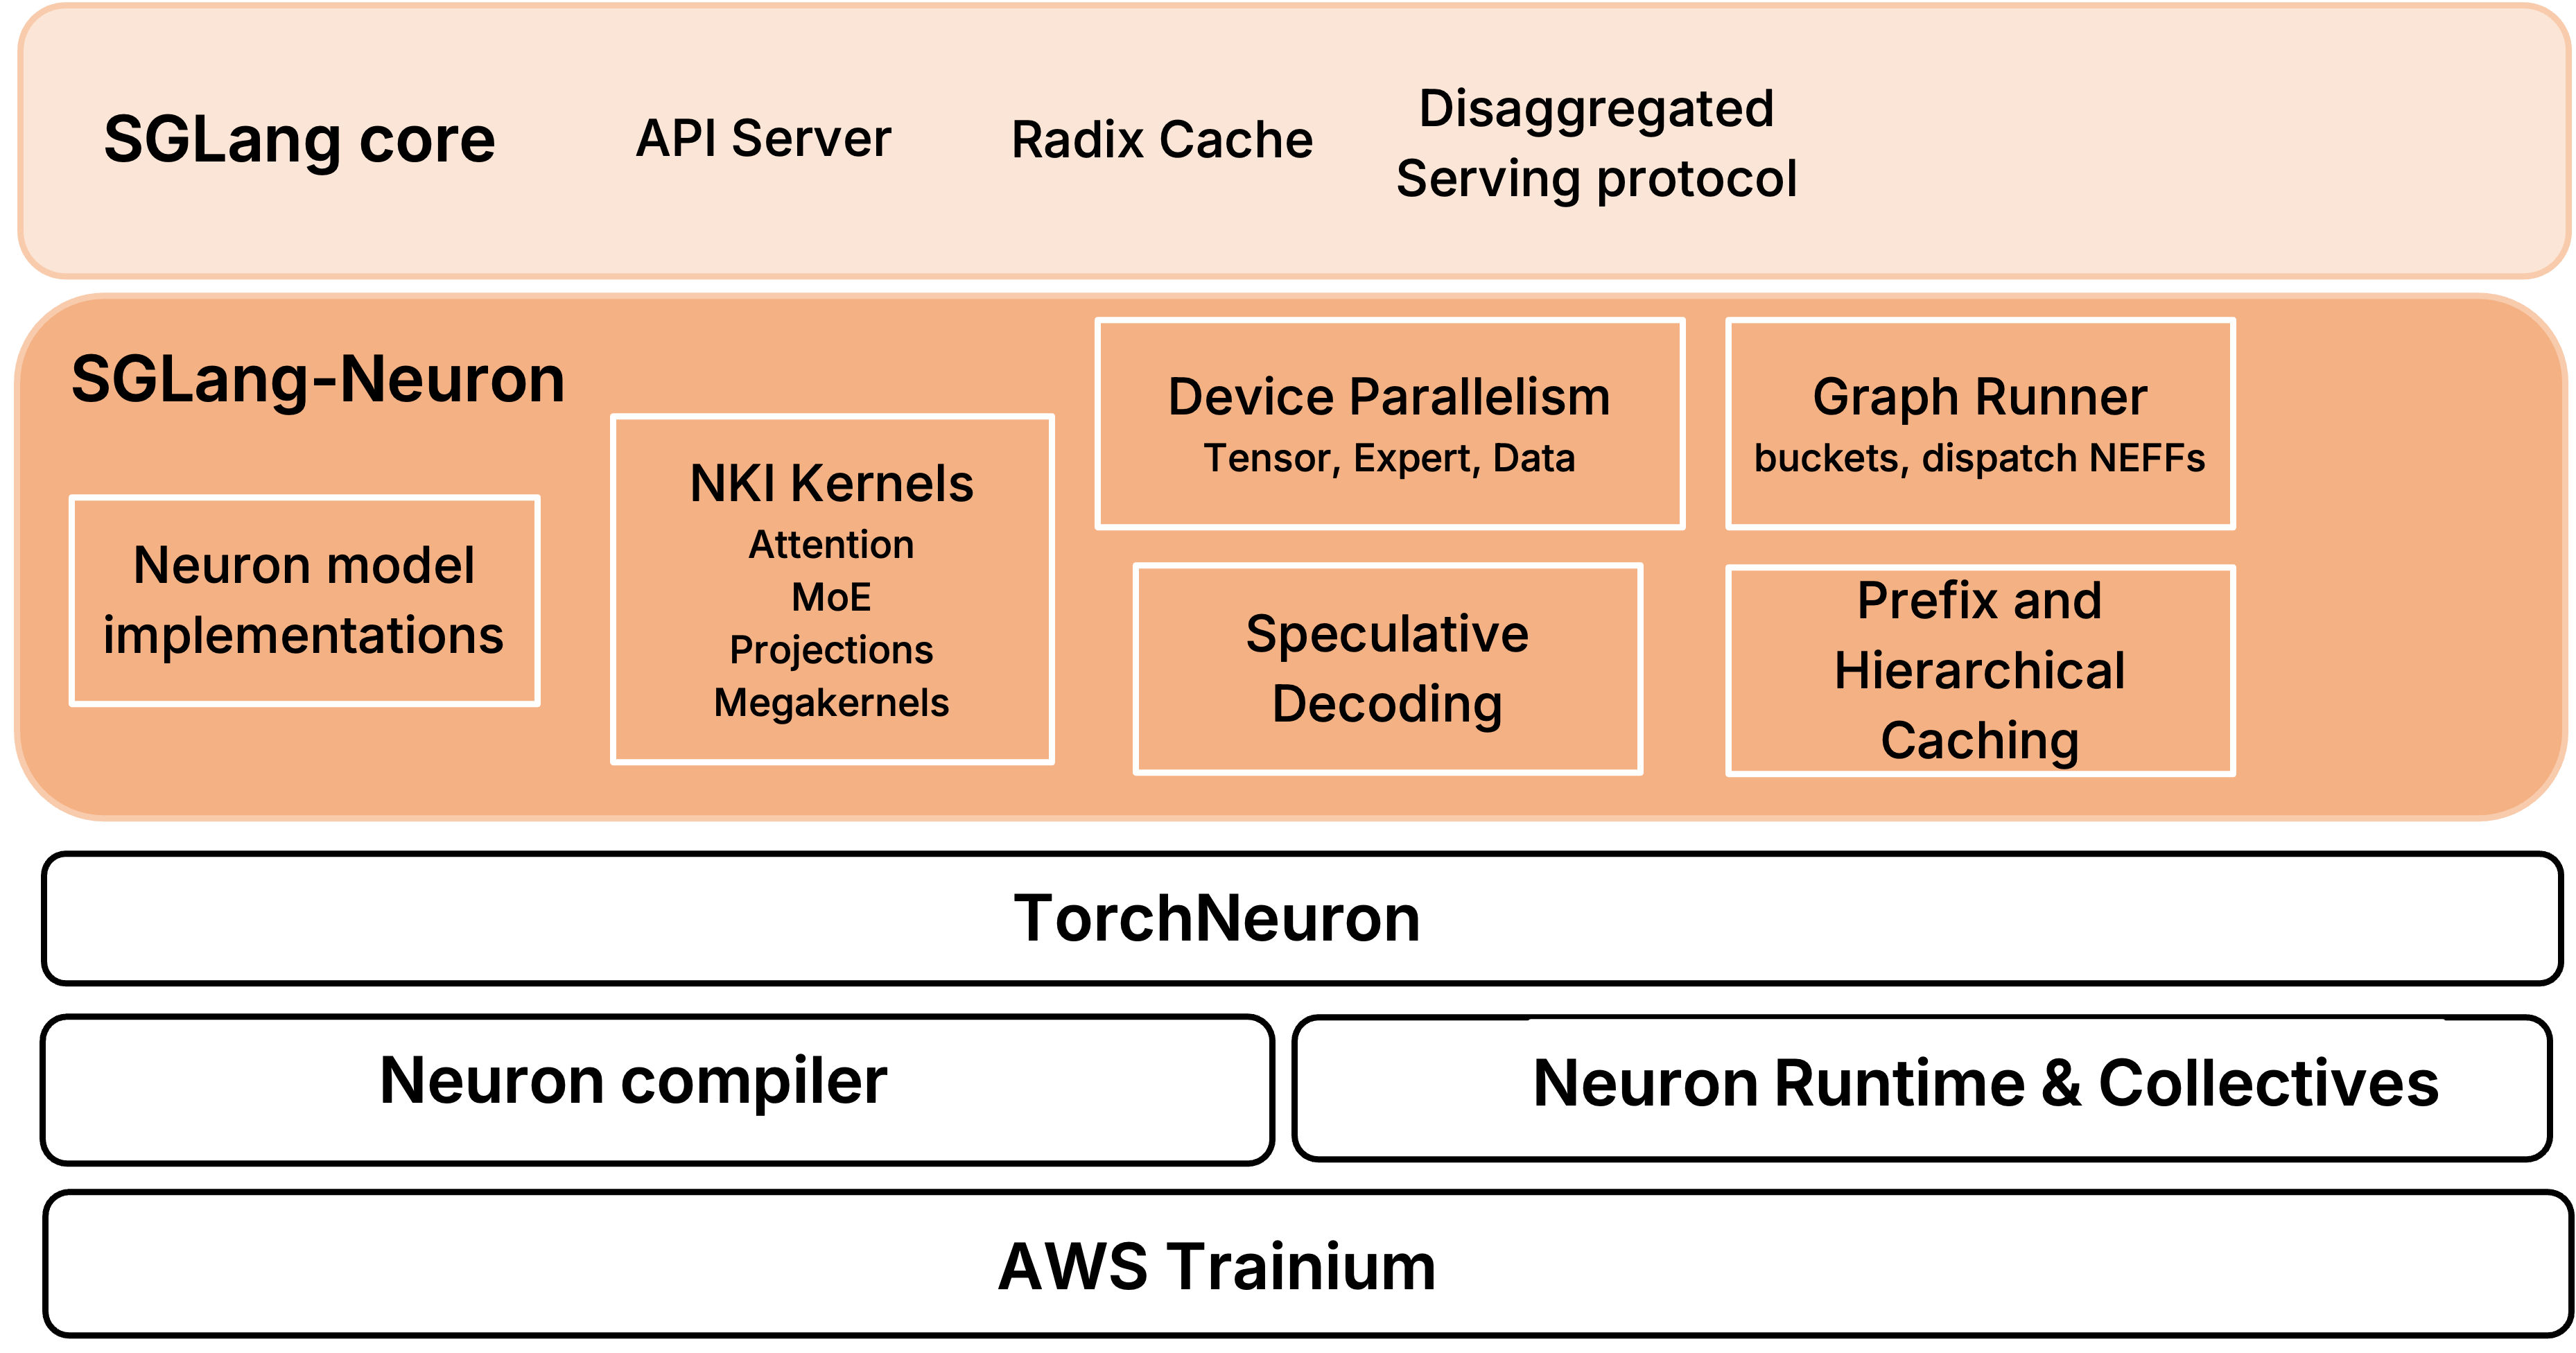
Architecture of SGLang-Neuron on AWS Trainium, showing SGLang core and the Trainium plugin components

Determine 1: SGLang-Neuron on AWS Trainium

TorchNeuron registers Trainium as a local PyTorch machine. SGLang-Neuron makes use of customary PyTorch operations for the mannequin execution path and incorporates kernels written with the Neuron Kernel Interface (NKI) for efficiency. It compiles these operations and kernels into executable packages utilizing torch.compile, which the graph runner prepares and executes throughout serving.

SGLang-Neuron additionally helps PD disaggregation. On this configuration, a prefill server computes the immediate KV cache and transfers it to a decode server utilizing NIXL over Elastic Cloth Adapter (EFA). The decode server then generates the remaining tokens. Every server nonetheless makes use of SGLang’s scheduler and request lifecycle, whereas the plugin manages the Trainium execution and KV-cache switch path.

Serving fashions on AWS Trainium utilizing SGLang-Neuron

To comply with this walkthrough, you employ a Trainium3 Amazon Elastic Compute Cloud (Amazon EC2) occasion with a pytorch-inference-sglang-neuronx container. Listed below are the steps:

  1. Begin the container.
    docker run --rm -it 
    --privileged --ipc=host 
    -v /path/to/work:/work 
    public.ecr.aws/neuron/pytorch-inference-sglang-neuron:v0.1.0-neuron-py314-sdk-2.33.0-ubuntu26.04 
    /bin/bash

  2. Launch the SGLang mannequin server contained in the container.
    SGLANG_PLATFORM=neuron 
    python -m sglang.launch_server 
    --model-path openai/gpt-oss-120b 
    --tp-size 8 
    --ep-size 8 
    --kv-cache-dtype fp8_e4m3 
    --context-length 10240 
    --chunked-prefill-size 8192 
    --max-running-requests 64 
    --max-total-tokens 655360 
    --mem-fraction-static 0.8 
    --host 127.0.0.1 
    --port 30000

  3. Ship a request to the mannequin server.
    curl -s http://127.0.0.1:30000/v1/chat/completions 
    -H 'Content material-Sort: software/json' 
    -d '{
    "mannequin": "openai/gpt-oss-120b",
    "messages": [
    {"role": "user", "content": "Explain why the sky appears blue."}
    ],
    "temperature": 0,
    "max_tokens": 128
    }'

For added data, please see the SGLang-Neuron getting began information for setup directions, and discover the repository documentation for supported fashions, options, and validated configurations.

Conclusion

SGLang-Neuron brings SGLang’s acquainted serving workflow to AWS Trainium by native PyTorch. You will get began by launching the SGLang-Neuron container and following the quickstart to serve a supported mannequin. Strive it together with your workloads, contribute by the venture repository, and share suggestions to assist form future mannequin and have assist.


Concerning the authors
Alex Nails

Alex Nails

Alex is a Member of Technical Workers at RadixArk. He leads MultiHardware and is a core developer of SGLang.

Yihao Wang

Yihao Wang

Yihao is a Member of Technical Workers at RadixArk. He works on each multi-modal/diffusion fashions and multi-hardware.

Lingyan Hao

Lingyan Hao

Lingyan is a Product Supervisor at RadixArk. She works on SGLang adoption and multi-hardware enablement.

Srecharan Selvam

Srecharan Selvam

Srecharan is a software program engineer engaged on AI Inference know-how at Annapurna Labs, Amazon.

Zeyu Wang

Zeyu Wang

Zeyu is a software program engineer engaged on AI Inference know-how at Annapurna Labs, Amazon.

Vinesh Ravuri

Vinesh Ravuri

Vinesh is a software program engineer engaged on AI Inference know-how at Annapurna Labs, Amazon.

Yuchen Jiang

Yuchen Jiang

Yuchen is a software program engineer engaged on AI Inference know-how at Annapurna Labs, Amazon.

Pinak Panigrahi

Pinak Panigrahi

Pinak works on efficiency optimization of AI fashions on AWS Trainium at Annapurna Labs, Amazon.

Chi Wang

Chi Wang

Chi is a Software program Growth Supervisor engaged on AI Inference know-how at Annapurna Labs, Amazon.

Tags: AWSDeployfrontierModelsSGLangNeuronTrainium
Previous Post

Construct autonomous AI brokers with Amazon Bedrock and Spring AI

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Popular News

  • The Journey from Jupyter to Programmer: A Fast-Begin Information

    The Journey from Jupyter to Programmer: A Fast-Begin Information

    407 shares
    Share 163 Tweet 102
  • Speed up edge AI improvement with SiMa.ai Edgematic with a seamless AWS integration

    407 shares
    Share 163 Tweet 102
  • Greatest practices for Amazon SageMaker HyperPod activity governance

    407 shares
    Share 163 Tweet 102
  • Context Engineering — A Complete Fingers-On Tutorial with DSPy

    406 shares
    Share 162 Tweet 102
  • Construct a serverless audio summarization resolution with Amazon Bedrock and Whisper

    406 shares
    Share 162 Tweet 102

About Us

Automation Scribe is your go-to site for easy-to-understand Artificial Intelligence (AI) articles. Discover insights on AI tools, AI Scribe, and more. Stay updated with the latest advancements in AI technology. Dive into the world of automation with simplified explanations and informative content. Visit us today!

Category

  • AI Scribe
  • AI Tools
  • Artificial Intelligence

Recent Posts

  • Deploy frontier AI fashions on AWS Trainium with SGLang-Neuron
  • Construct autonomous AI brokers with Amazon Bedrock and Spring AI
  • Introducing usage-based pricing for Amazon SageMaker AI bidirectional streaming
  • Home
  • Contact Us
  • Disclaimer
  • Privacy Policy
  • Terms & Conditions

© 2024 automationscribe.com. All rights reserved.

No Result
View All Result
  • Home
  • AI Scribe
  • AI Tools
  • Artificial Intelligence
  • Contact Us

© 2024 automationscribe.com. All rights reserved.