Selecting the best mannequin for a selected utility requires a sensible approach to check it with consultant inputs. Amazon SageMaker JumpStart offers entry to a broad catalog of already pretrained fashions. On this submit, we present the right way to deploy an accessible mannequin from SageMaker JumpStart, run a light-weight and repeatable efficiency check utilizing the SageMaker Python SDK, and delete the endpoint when testing is full. For supported fashions and accessible capability, this workflow offers a repeatable analysis path, though deployment time varies by mannequin, occasion kind, quota, and AWS Area.
In 2026, SageMaker JumpStart launched two enhancements that simplify mannequin discovery and deployment. Within the Mannequin Hub part of the Amazon SageMaker AI console, you may browse the SageMaker JumpStart catalog, view pattern notebooks, and open them straight in SageMaker Studio. Pre-configured endpoint deployment choices present named configurations optimized for priorities comparable to low value, low latency, or general-purpose workloads throughout a variety of generative AI fashions, together with Neuron-optimized configurations. Moreover, now you can go from Hugging Face mannequin discovery to SageMaker AI deployment in a single click on utilizing the brand new deep hyperlink integration.
Resolution overview
Our strategy makes use of a reusable Python script that performs three steps:
Uncover and deploy a mannequin from SageMaker JumpStart.
Run model-specific pattern prompts and measure latency, approximate output size, and single-request technology charge.
Clear up the endpoint.
This sample works for a lot of appropriate SageMaker JumpStart fashions, though payload codecs, required occasion varieties, end-user license settlement (EULA) necessities, and response schemas might require model-specific changes.
Conditions
An AWS account with SageMaker AI permissions.
Python 3+ with SageMaker Python SDK v3 put in (pip set up "sagemaker>=3,<4").
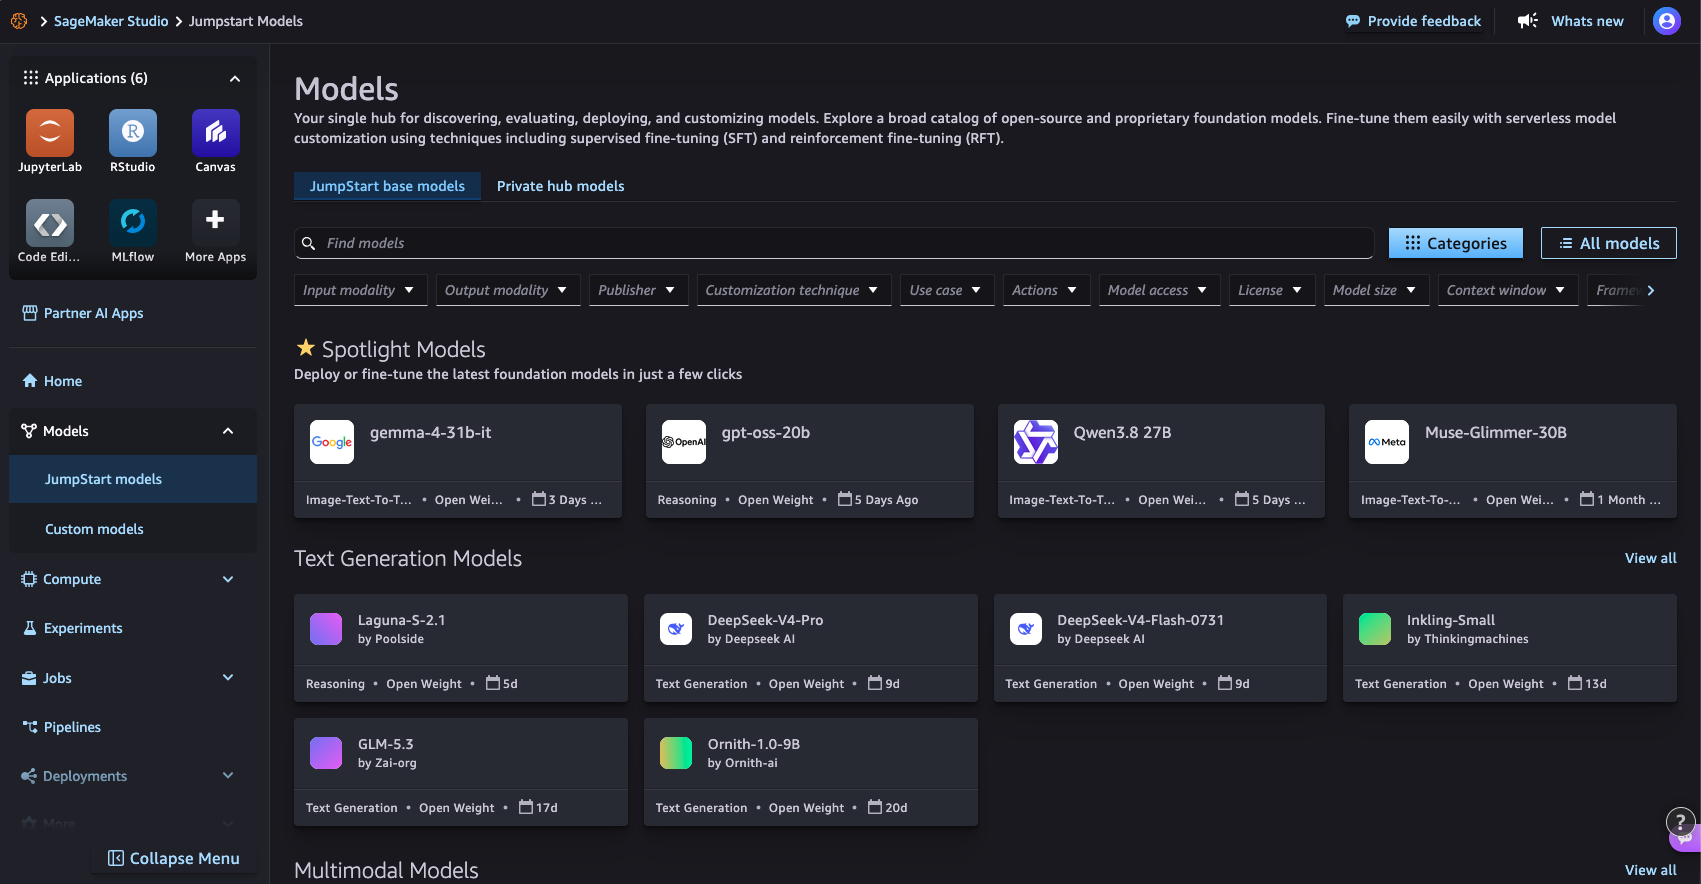
UI path to search out fashions in SageMaker JumpStart:
Determine 1: Searching the mannequin catalog on the SageMaker JumpStart Fashions web page in SageMaker Studio
Code path utilizing SageMaker Python SDK:
from sagemaker.core.jumpstart.notebook_utils import (
    list_jumpstart_models,
)

REGION = "us-east-1"

fashions = list_jumpstart_models(
    filter="activity == textgeneration",
    area=REGION,
    list_versions=True,
)

print(f"Discovered {len(fashions)} textual content technology fashions")

for model_id, model_version in fashions[:10]:
    print(
        f" - {model_id} "
        f"(model {model_version})"
    )
Or search by mannequin identify:
from sagemaker.core.jumpstart.notebook_utils import list_jumpstart_models

ids = list_jumpstart_models(
    filter="model_id incorporates qwen",
    area=REGION,
    list_versions=True,
)

print(f"{len(ids)} fashions matched in {REGION}n")

for model_id, model in ids:
    print(f"{model_id:<55} v{model}")
Step 1.b: Deploy the mannequin
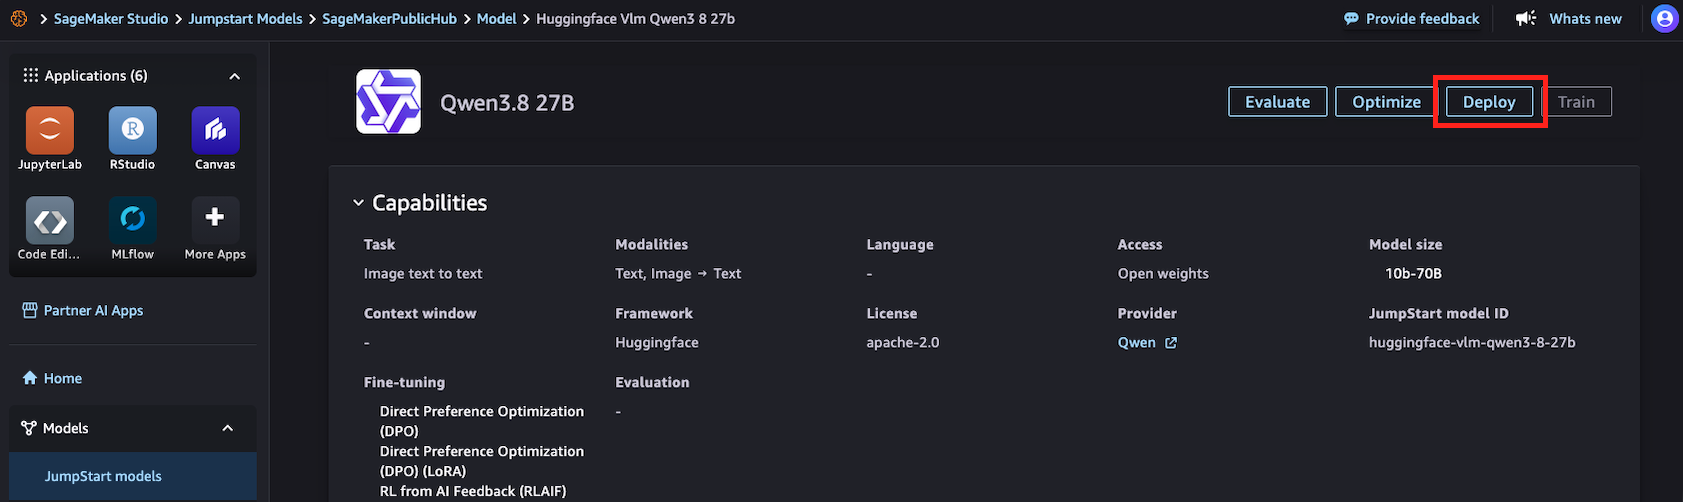
UI path to deploy fashions from SageMaker JumpStart:
Determine 2: Deploying a mannequin from its SageMaker JumpStart element web page in SageMaker Studio
Code path utilizing SageMaker Python SDK:
import time

from sagemaker.core.jumpstart.accessors import JumpStartModelsAccessor
from sagemaker.core.jumpstart.configs import JumpStartConfig
from sagemaker.core.coaching.configs import Compute
from sagemaker.serve import ModelBuilder

MODEL_ID = "huggingface-vlm-qwen3-5-27b"
MODEL_VERSION = "1.13.0"
REGION = "us-east-1"
ACCEPT_EULA = False  # Set True solely after reviewing the mannequin phrases

def get_field(worth, identify, default=None):
    if isinstance(worth, dict):
        return worth.get(identify, default)
    return getattr(worth, identify, default)

# Resolve the JumpStart-recommended deployment configuration.
specs = JumpStartModelsAccessor().get_model_specs(
    area=REGION,
    model_id=MODEL_ID,
    model=MODEL_VERSION,
)

if isinstance(specs, record):
    if not specs:
        increase ValueError(
            f"No JumpStart specification discovered for {MODEL_ID}"
        )
    specs = specs[0]

recommended_instance_type = get_field(
    specs,
    "default_inference_instance_type",
)

if not recommended_instance_type:
    increase ValueError(
        f"No really useful occasion kind discovered for {MODEL_ID}"
    )

print(f"Mannequin: {MODEL_ID}")
print(f"Area: {REGION}")
print(f"Beneficial occasion: {recommended_instance_type}")

begin = time.time()

jumpstart_config = JumpStartConfig(
    model_id=MODEL_ID,
    model_version=MODEL_VERSION,
    accept_eula=ACCEPT_EULA,
)

model_builder = ModelBuilder.from_jumpstart_config(
    jumpstart_config=jumpstart_config,
    compute=Compute(
        instance_type=recommended_instance_type,
        instance_count=1,
    ),
)

mannequin = model_builder.construct()
endpoint = model_builder.deploy()
deploy_time = time.time() - begin

print(f"Deployed in {deploy_time:.1f} seconds")
print(f"Endpoint: {endpoint.endpoint_name}")
Step 2: Run pattern prompts and measure efficiency
from sagemaker.core.payloads import retrieve_all_examples
import json
import time

MODEL_ID = "huggingface-vlm-qwen3-5-27b"
MODEL_VERSION = "1.13.0"
REGION = "us-east-1"

example_payloads = retrieve_all_examples(
    area=REGION,
    model_id=MODEL_ID,
    model_version=MODEL_VERSION,
    serialize=True,
)

#you may re-create the endpoint pointer utilizing the endpoint identify:
#from sagemaker.core.sources import Endpoint
#endpoint = Endpoint.get(endpoint_name="",area=REGION)

def read_response_body(end result):
    physique = end result.physique
    if hasattr(physique, "learn"):
        physique = physique.learn()
    if isinstance(physique, bytes):
        physique = physique.decode("utf-8")
    if isinstance(physique, str):
        attempt:
            return json.masses(physique)
        besides json.JSONDecodeError:
            return physique
    return physique

def extract_output(response):
    """Deal with frequent JumpStart text-generation response codecs."""
    if isinstance(response, record):
        response = response[0] if response else ""
    if isinstance(response, dict):
        decisions = response.get("decisions")
        if decisions:
            selection = decisions[0]
            message = selection.get("message")
            if isinstance(message, dict):
                return message.get("content material", "")
            return selection.get("textual content", "")
        for area in (
            "generated_text",
            "output_text",
            "textual content",
        ):
            if area in response:
                return response[field]
    return response

outcomes = []

for payload in example_payloads or []:
    begin = time.perf_counter()
    end result = endpoint.invoke(
        physique=payload.physique,
        content_type=payload.content_type,
        settle for=payload.settle for,
    )
    latency = time.perf_counter() - begin
    response = read_response_body(end result)
    output = extract_output(response)
    if not isinstance(output, str):
        output = json.dumps(output, indent=2)
    # That is an estimate based mostly on whitespace-separated phrases.
    output_words = len(output.cut up())
    outcomes.append(
        {
            "request_preview": payload.physique[:50],
            "latency_s": spherical(latency, 2),
            "estimated_output_words": output_words,
            "words_per_second": spherical(
                output_words / latency,
                1,
            ) if latency > 0 else 0,
        }
    )
    print("Enter:n", payload.physique, finish="nn")
    print("Output:n", output, finish="nn")
    print(
        f"Latency: {latency:.2f} secondsn"
        f"Estimated output phrases: {output_words}n"
        f"Estimated single-request output technology charge: "
        f"{output_words / latency:.1f} phrases/secondn"
    )
    print("-" * 80)

print("nSummary:")
for lead to outcomes:
    print(end result)
Consequence:
Enter:
{"max_tokens": 256, "messages": [{"content": "What is deep learning?", "role": "user"}], "mannequin": "/decide/ml/mannequin"}
Output:
Here is a considering course of that results in the reason of deep studying:
1. **Deconstruct the Request:**
* **Query:** "What's deep studying?"
* **Intent:** The person needs a transparent, complete, but accessible definition and overview of deep studying.
* **Goal Viewers:** Seemingly somebody searching for a normal understanding, presumably a scholar, tech
fanatic, or skilled exploring the sector. The tone must be informative, structured, and
not overly jargon-heavy (although key phrases want rationalization).
2. **Preliminary Brainstorming & Key Ideas:**
* What's it? A subset of machine studying, which is a subset of AI.
* Core mechanism: Synthetic Neural Networks (ANNs).
* "Deep" means many layers (hidden layers).
* How does it work? Studying representations from information (characteristic studying).
* Key functions: Picture recognition, NLP, speech, self-driving vehicles.
* Why is it in style now? Large information, GPU energy, higher algorithms.
* Professionals/Cons: Excessive accuracy vs. black field, information starvation.
3. **Structuring the Reply:**
Latency: 9.07 seconds
Estimated output phrases: 153
Estimated single-request output technology charge: 16.9 phrases/second
--------------------------------------------------------------------------------
Abstract:
{'request_preview': '{"max_tokens": 256, "messages": {"content material": "What', 'latency_s': 9.07, 'estimated_output_words': 153, 'words_per_second': 16.9}
This sample works for a lot of accessible SageMaker JumpStart fashions, however the payload format, required occasion kind, EULA, and response parsing might require model-specific changes. Through the use of constant check prompts and measuring latency, throughput, and output high quality throughout fashions, you may evaluate choices and choose the fitting match in your workload.
Do that strategy with totally different fashions from Amazon SageMaker JumpStart to search out the fitting steadiness of high quality, velocity, and price in your functions.