
IDC analysis exhibits that document-related challenges value organizations $19,732 for every info employee yearly and cut back productiveness by 21.3 p.c. Organizations receiving invoices from lots of of suppliers typically face layouts that change by issuer and alter with out discover. Template-based programs require fixed upkeep at this scale. Employees can spend as much as 30 p.c of their time on document-related duties, and guide information entry error charges vary from 1–4 p.c. Standard clever doc processing (IDP) options tackle a few of this burden, however they require in depth upfront configuration for every doc format and break when layouts differ throughout distributors.
On this put up, you learn to construct an agentic IDP system utilizing Amazon Bedrock AgentCore that classifies, extracts, validates, and learns from enterprise paperwork with minimal human intervention. Amazon Bedrock AgentCore is a platform to construct, join, and optimize brokers at scale, with any framework or mannequin. Your brokers mechanically deal with new doc codecs, reminiscent of provider invoices, buy orders, insurance coverage claims, and mortgage functions. By the top of this put up, you possibly can:
- Deploy a multi-agent IDP system, typically in underneath 20 minutes.
- Course of new doc sorts with out guide template configuration.
- Let brokers practice themselves on every new doc format and reuse what they study, so later paperwork of that kind go straight to extraction with out retraining.
Challenges with rule-based doc processing
Many IDP pipelines require you to outline templates, extraction guidelines, and validation logic for each doc format upfront. When a brand new vendor sends a purchase order order with a special format, the pipeline breaks. This creates three core challenges:
- Template rigidity: Every new doc format requires guide configuration, and even minor format adjustments could cause extraction failures.
- No studying: The identical extraction errors repeat throughout related paperwork as a result of the system doesn’t retain information from earlier corrections.
- Scaling burden: Every new vendor or doc variant multiplies the upkeep effort, and organizations processing paperwork from lots of of sources face ongoing operational prices.
An agentic method addresses these challenges. As a substitute of static templates, AI brokers analyze every doc, generate extraction directions, validate outcomes, and study from corrections mechanically. Over time, your system builds a information base of doc codecs, so that you course of related paperwork with minimal further configuration.
Answer overview
On this resolution, eight specialised brokers collaborate throughout two graph-based workflows operating on Amazon Bedrock AgentCore.
The next diagram exhibits the multi-agent workflow graph constructed utilizing Strands Brokers, an open supply SDK for constructing AI brokers.
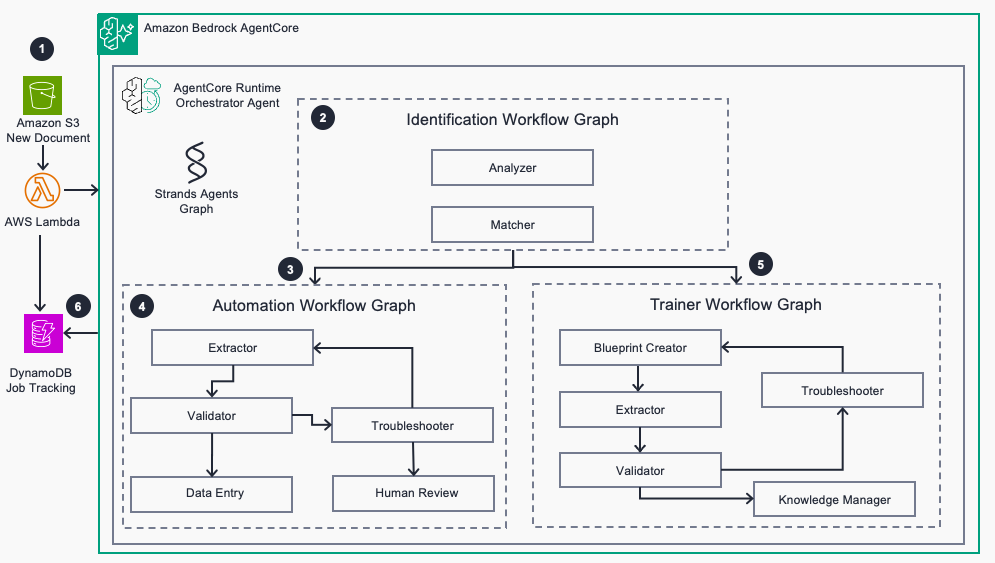
Determine 1: Multi-agent orchestration workflow graph
- Identification workflow: The Analyzer agent extracts textual content utilizing Amazon Textract and identifies the doc kind and sender. The Matcher agent searches for related paperwork utilizing vector similarity in Amazon S3 Vectors, a functionality of Amazon Easy Storage Service (Amazon S3).
- Coaching workflow (new doc sorts): When no match is discovered, the Directions agent generates extraction prompts, the Extractor agent extracts structured information, and the Validator agent checks outcomes towards schemas and enterprise guidelines in Amazon Aurora DSQL. If validation fails, the Directions Fixer agent refines the prompts and retries. On success, the Save Directions agent persists the directions for reuse.
- Automation workflow (recognized doc sorts): When a match is discovered, the Extractor agent makes use of current directions. If validation fails, the Troubleshooter agent fixes the extracted information immediately with out modifying directions.
The way it works
The next diagram exhibits the infrastructure structure for the answer.
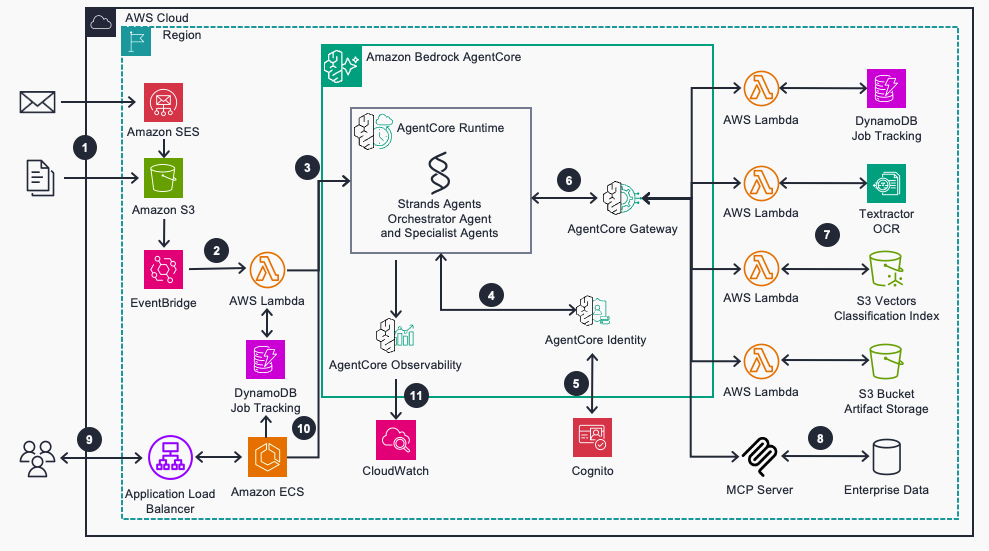
Determine 2: Agentic IDP infrastructure structure on AWS
- Enterprise paperwork arrive in Amazon Easy E-mail Service (Amazon SES) or direct add to Amazon S3.
- Amazon EventBridge triggers an AWS Lambda perform that creates a monitoring job in Amazon DynamoDB and invokes AgentCore runtime, a functionality of Amazon Bedrock AgentCore.
- AgentCore runtime orchestrates doc processing via Strands Brokers.
- Your brokers securely entry AWS assets via machine-to-machine credentials managed by AgentCore Id, a functionality of Amazon Bedrock AgentCore, and Amazon Cognito.
- Your Lambda capabilities change into agent-compatible instruments via the Mannequin Context Protocol (MCP) interface of AgentCore Gateway, a functionality of Amazon Bedrock AgentCore.
- Brokers extract textual content utilizing Amazon Textract, classify paperwork utilizing vector embeddings in S3 Vectors, and validate information towards enterprise guidelines in Aurora DSQL.
- Brokers entry enterprise information via MCP servers to validate extracted content material towards enterprise guidelines.
- You monitor standing and troubleshoot points via a chat-enabled dashboard hosted on Amazon Elastic Container Service (Amazon ECS).
- You acquire visibility into agent efficiency via AgentCore Observability, a functionality of Amazon Bedrock AgentCore, and Amazon CloudWatch telemetry.
Deploy the answer
Observe these steps to deploy the answer infrastructure and internet UI to your AWS account.
Conditions
To deploy this resolution, you could have:
- An AWS account.
- Entry to Amazon Bedrock with Amazon Nova and Anthropic (Claude) fashions enabled. For mannequin availability by AWS Area, discuss with Supported fashions by AWS Area in Amazon Bedrock.
- Entry to Amazon Bedrock AgentCore (Runtime, Gateway, Id), S3 Vectors, and Amazon Aurora DSQL in a supported Area.
- AWS Cloud Improvement Package (AWS CDK) v2 put in.
- Docker put in and operating (required for constructing and deploying container pictures).
- Python 3.11+ and Node.js 18+.
- AWS Id and Entry Administration (IAM) permissions to create S3 buckets, Lambda capabilities, DynamoDB tables, Cognito consumer swimming pools, Amazon Elastic Container Registry (Amazon ECR) repositories, and Amazon ECS providers.
- Clone the repository and arrange the atmosphere:
- Deploy the stacks:
This deploys six AWS CloudFormation stacks: Core (S3, Cognito, DynamoDB), Gateway (Lambda instruments, AgentCore Gateway), Aurora (Amazon Aurora DSQL), Agent (AgentCore runtime, containers), UI Orchestrator (API endpoints), and Fashionable UI (React app on Amazon CloudFront). Deployment takes roughly 15–20 minutes.
- Confirm deployment by checking that every stack exhibits
CREATE_COMPLETEwithin the CloudFormation console.
Course of information and evaluate outcomes
After deployment, you obtain an e-mail with the CloudFront URL, username, and non permanent password.
Course of a doc
- Sign up to the net UI and select Course of Doc.
- Add a pattern buy order from
infrastructure/sample_data/purchase_orders/coaching/. - The doc enters the agent workflow:
- The Analyzer agent extracts textual content and identifies the sender and doc kind.
- The Matcher agent searches for related paperwork within the vector retailer.
- For a brand new doc kind, the coaching workflow generates extraction directions, extracts information, validates it, and saves the directions for future use.
- For a recognized doc kind, the automation workflow extracts information utilizing current directions and validates it.
- Evaluation leads to the Evaluation Jobs and Directions tab to confirm extracted information, validation outcomes, and generated directions.
Instance: A brand new doc kind (coaching workflow)
Suppose you add the primary buy order from a brand new retailer, Two Wheel Retailer. The Matcher agent searches the vector retailer, finds no related doc, and routes the job via the coaching workflow.
The Analyzer agent makes use of Amazon Textract to extract the uncooked doc textual content:
The Directions agent generates extraction prompts from the schema, and the Extractor agent produces structured JSON:
The Validator agent checks the outcome towards the schema and fails:
The seller’s SKU format (SB-004) doesn’t match Acme Bikes’ inside format (AB-SB-004). The Directions Fixer agent diagnoses the mismatch and provides an express SKU transformation rule to the extraction immediate: prefix vendor SKUs with AB-. On the second cross, the seven line objects validate efficiently, and the Save Directions agent persists the refined immediate to the vector retailer. Finish-to-end time for this primary run: 3 minutes 49 seconds.
Instance: A recognized doc kind (automation workflow)
When a second buy order from Two Wheel Retailer arrives, the Matcher agent finds the saved directions from the primary run with a confidence rating of three.946 (threshold: 3.7) and routes the job via the automation workflow:
- The Extractor agent applies the saved directions immediately, so the orchestrator skips immediate technology. The SKU transformation rule discovered throughout coaching applies mechanically (
EL-002→AB-EL-002,HB-071→AB-HB-071,PD-002→AB-PD-002). - The three line objects validate on the primary cross with an order whole of $5,979.19.
- Finish-to-end processing completes in 1 minute 30 seconds, down from 3 minutes 49 seconds on the primary run.
Use the interactive chat
The dashboard features a chat interface for troubleshooting:
- Ask
what instruments do you might haveto see accessible agent capabilities. - Ask
listing directionsto view saved extraction directions. - Ask
what's the standing of job XXXXto test processing progress. - Ask
what went flawed with job XXXX, how can we replace the directions?to diagnose failures.
Perceive how accuracy improves over time
The system improves over time via two suggestions loops:
- Coaching loop: When the Directions Fixer agent refines extraction prompts after validation failures, the improved directions are saved and reused for related paperwork.
- Processing loop: When the Troubleshooter agent fixes extraction errors, it offers detailed evaluation that helps establish patterns in doc format variations.
When altering fashions, use AgentCore Evaluations, a functionality of Amazon Bedrock AgentCore, to substantiate that extraction high quality stays acceptable. The answer already makes use of AgentCore Observability, so it has the required instrumentation.
Estimated value
You pay just for what you utilize, as a result of the answer runs on serverless and on-demand assets with no idle prices. For a workload of 10 coaching paperwork and 1,000 processed paperwork every month in US East (N. Virginia), the estimated value is roughly $58 monthly. Basis mannequin (FM) inference via Amazon Bedrock represents roughly 85 p.c of the whole value, at roughly $0.055 per doc. Precise value relies upon largely on the fashions assigned to every agent. Mannequin decisions are centralized in brokers/orchestratorgraph/utils/config.py, so you should use lower-cost fashions for less complicated duties and stronger fashions the place wanted. For detailed pricing, discuss with the Amazon Bedrock pricing web page.
Customise the answer to your use case
You get a purchase order order processing use case with an artificial bike firm dataset, a pre-built JSON schema, and a validation Lambda perform that checks extracted information towards product and vendor information in a mock ERP database. To course of your individual paperwork, you could exchange the included schemas and validation logic with your individual.
Outline your doc schema
Create a JSON schema that defines the fields you need to extract for every doc kind. The pattern buy order schema in brokers/orchestratorgraph/doc_schema/purchase_order_schema.json offers a reference. Your schema ought to specify discipline names, information sorts, and whether or not every discipline is explicitly said within the doc or inferred from context.
Construct your validation course of
The included validator checks buy order information towards artificial vendor and product tables in Aurora DSQL. Your manufacturing implementation requires a validation course of tailor-made to your online business guidelines. For instance:
- An bill validator may test vendor IDs towards your accounts payable system and confirm line merchandise totals match the bill whole.
- A contract validator may confirm that the doc accommodates required clauses and that dates and get together names match your information.
- A claims validator may test coverage numbers, protection limits, and claimant info towards your coverage administration system.
So as to add a brand new validator, create a Lambda perform that accepts extracted JSON and returns a cross/fail outcome with detailed error messages, then register it as a device in AgentCore Gateway. Confer with gateway/instruments/po_validator_tool/ for the implementation sample.
Replace agent prompts
The agent prompts in brokers/orchestratorgraph/prompts/ reference buy order terminology. Replace these prompts to replicate your doc sorts and extraction necessities. The Orchestrator agent, Validator agent, and Directions agent every include document-type-specific language that it’s best to adapt.
Greatest practices
Preserve these suggestions in thoughts as you practice and function your agentic IDP system.
- Begin with consultant samples: Add 5–10 paperwork per kind throughout coaching, together with edge circumstances with format variations, to construct dependable extraction directions.
- Use enterprise rule validation: Join validators to your reference information (vendor lists, product catalogs) in Aurora DSQL to catch extraction errors early.
- Monitor agent efficiency: Use AgentCore Observability and CloudWatch to trace execution paths, establish bottlenecks, and measure extraction accuracy over time.
- Add doc sorts incrementally: Create a JSON schema for every new doc kind and a corresponding validation Lambda perform. The brokers deal with the remainder.
- Add guardrails for manufacturing: Apply Amazon Bedrock Guardrails to implement content material filtering and grounding checks on agent outputs. That is particularly essential once you course of delicate doc sorts reminiscent of insurance coverage claims or mortgage functions.
- Evaluation the OWASP Prime 10 for LLMs: Seek the advice of the OWASP Prime 10 for LLMs and Generative AI Apps for safety issues when constructing functions that use massive language fashions (LLMs).
Clear up
Vital: Earlier than operating cleanup, export the info you need to retain. The destroy.py script completely deletes processed paperwork (S3), job historical past (DynamoDB), validation information (Aurora DSQL), and discovered extraction directions (vector retailer).
To keep away from ongoing expenses, take away the deployed assets:
Confirm that the six CloudFormation stacks are deleted on the console: AgenticIDP-Core-Dev, AgenticIDP-Gateway-Dev, AgenticIDP-Aurora-Dev, AgenticIDP-Agent-Dev, AgenticIDP-UIOrchestr-Dev, and AgenticIDP-ModernUI-Dev.
Conclusion
On this put up, you discovered easy methods to construct a self-improving doc processing system utilizing Amazon Bedrock AgentCore, the place specialised AI brokers collaborate to categorise, extract, validate, and study from enterprise paperwork. This agentic method adapts to new doc codecs mechanically and improves accuracy over time via suggestions loops, changing guide template configuration with autonomous studying.
As subsequent steps:
- Deploy the pattern resolution and check with the included buy order samples.
- Add your individual doc sorts by creating JSON schemas and validation guidelines.
- Discover easy methods to combine extracted information with downstream programs reminiscent of ERP, CRM, or content material administration instruments.
To study extra concerning the providers and patterns used on this put up, discuss with the next assets:
For knowledgeable steerage on constructing doc processing options, AWS Skilled Companies and AWS Companions can assist.
Concerning the authors