
Serving massive language fashions (LLMs) effectively requires adequate GPU reminiscence and cautious coordination of immediate processing and token era. GLM-5.3’s FP8 weights, for instance, exceed the 640 GB of GPU reminiscence on a single ml.p5.48xlarge occasion, earlier than accounting for KV cache and runtime overhead. Lengthy prompts may sluggish token era when each share the identical GPUs.
Amazon SageMaker HyperPod Inference now helps NVIDIA Dynamo, combining Dynamo’s distributed inference capabilities with the infrastructure administration of HyperPod to deal with these challenges. Dynamo is an open supply distributed inference framework that helps multi-node deployment, disaggregated prefill and decode, and KV-aware routing with engines resembling vLLM, SGLang, and TensorRT-LLM. HyperPod helps these deployments with high-performance Elastic Cloth Adapter (EFA) networking, coordinated GPU scheduling, and node well being monitoring and restoration. On this publish, we illustrate multi-node and disaggregated serving by means of a deployment instance, share benchmark outcomes, and description finest practices for optimizing inference on HyperPod.
How the mixing works
The HyperPod Inference add-on installs the Dynamo customized useful resource definitions and these serving and scheduling elements:
- HyperPod Inference Operator manages endpoint deployment by means of an InferenceEndpointConfig (IEC) customized useful resource. Its
dynamoSpecpart provides the Dynamo configuration. - Dynamo operator manages assets outlined in a DynamoGraphDeployment (DGD), together with the frontend, mannequin staff, duplicate counts, and useful resource necessities.
- Grove coordinates associated teams of pods, together with multi-node staff, and their scaling relationships.
- Kubernetes AI (KAI) Scheduler locations pods on GPU assets, utilizing gang scheduling to schedule the pods required for a multi-node employee collectively.
AWS Deep Studying Containers (DLCs) present the Dynamo runtime, whereas the add-on manages built-in element variations. To undertake a supported Dynamo launch, replace the add-on.
Deployment structure
The next diagram reveals the deployment paths, serving elements, and infrastructure administration for disaggregated inference on SageMaker HyperPod. The Dynamo frontend routes requests to prefill staff, which course of prompts, and decode staff, which generate tokens. These separate swimming pools enable unbiased scaling and tuning. Each swimming pools load the total mannequin weights, and KV cache transfers between them over EFA.
Dynamo additionally helps aggregated serving, the place prefill and decode run in the identical employee. In both topology, staff can run on one occasion or span a number of cases utilizing tensor and pipeline parallelism. Dynamo’s KV-aware router considers reusable prefix KV cache and lively employee load in each topologies. Prefix reuse can scale back immediate recomputation and enhance time to first token, whereas load consciousness helps keep away from overloading staff. For extra particulars on the Dynamo structure, see the Dynamo Information Base overview.
HyperPod supplies node, GPU, and EFA well being monitoring and manages node alternative, whereas the orchestration elements recreate affected staff. Deployments configured by means of InferenceEndpointConfig with dynamoSpec assist invocation by means of SageMaker endpoints.
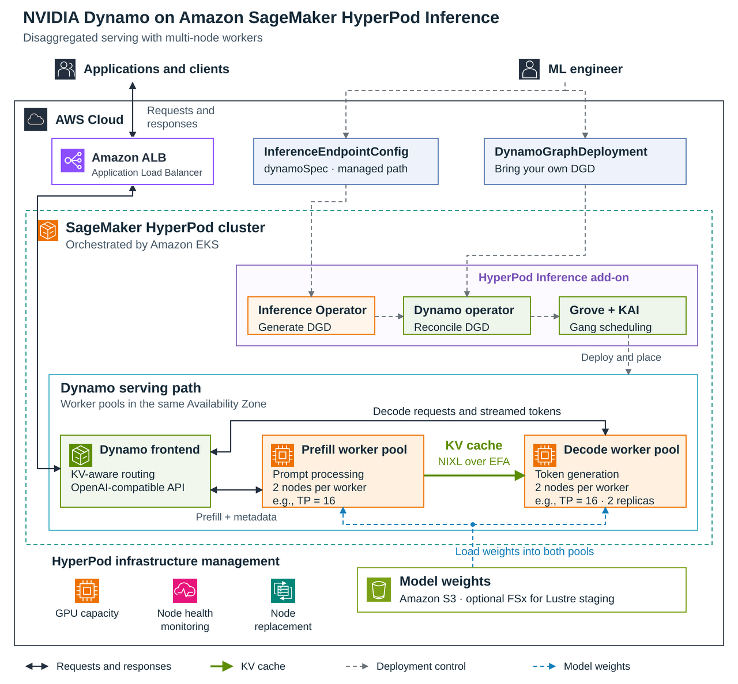
Determine 1: Deployment paths, serving elements, and infrastructure administration for NVIDIA Dynamo on Amazon SageMaker HyperPod Inference
Two methods to configure your deployment
Whether or not you might be new to HyperPod, new to Dynamo, or each, the add-on affords two deployment paths to suit your workflow:
Convey-your-own DynamoGraphDeployment (DGD) lets current Dynamo customers proceed utilizing upstream documentation, recipes, and manifests, with the Dynamo operator managing the deployment. To carry an current DGD to HyperPod, use a supported container picture and configure storage, networking, and pod placement on your cluster.
InferenceEndpointConfig with dynamoSpec lets current HyperPod Inference customers deploy a brand new Dynamo endpoint utilizing the identical configuration format and OpenAI-compatible interface they already know. For the inference engine, you possibly can select vLLM, SGLang, or TensorRT-LLM, with vLLM utilized by default. The operator additionally provides defaults for KV-aware routing and duplicate counts.
Each paths assist single-instance and multi-node deployments. In both case, HyperPod manages node well being and alternative. The desk summarizes the tasks for every path.
| Convey-your-own DGD | InferenceEndpointConfig with dynamoSpec | |
| You write | Full DGD manifest | IEC containing dynamoSpec |
| Greatest for | Groups wanting direct management of the serving graph or reuse of current DGDs | Groups wanting managed endpoint setup by means of IEC |
| Mannequin weights | You configure downloading or mounting the weights | The operator levels weights from Amazon Easy Storage Service (Amazon S3) or Amazon FSx |
| Endpoint, TLS, registration | You configure and handle these assets | Managed by means of the HyperPod Inference Operator |
| Autoscaling | You configure and handle scaling | Kubernetes Occasion-driven Autoscaling (KEDA) by means of autoScalingSpec for aggregated and disaggregated deployments |
Deployment instance: GLM-5.3
The next excerpts use the InferenceEndpointConfig (IEC) deployment path with vLLM on ml.p5.48xlarge cases. Dynamo-specific settings belong underneath spec.dynamoSpec. Mannequin supply and endpoint settings are included within the full manifest.
Multi-node aggregated serving
This configuration runs one model-worker duplicate throughout two cases (16 GPUs), with two frontend replicas for request dealing with. Setting dynamoSpec.frontend.routingMode to kv-aware activates KV-aware routing.
Right here, spec.replicas controls the variety of model-worker replicas, whereas frontend.replicas controls the variety of frontend replicas.
Multi-node disaggregated serving
Substitute aggregation underneath spec.dynamoSpec with the next disaggregation block, protecting the previous frontend configuration. Duplicate counts are set individually for prefill and decode. This instance runs one prefill duplicate and two decode replicas, every spanning two cases, for a complete of six cases.
Apply the deployment
Apply the whole manifest with kubectl apply. The HyperPod Inference Operator makes the configured mannequin weights out there to the employees and generates the DGD. Grove and KAI Scheduler coordinate placement in order that the pods required for every multi-node employee are scheduled collectively.
After the SageMaker endpoint is prepared and configured for chat completions, shoppers can ship an OpenAI-compatible request payload by means of the SageMaker Runtime API:
Benchmarks
We benchmarked Dynamo on SageMaker HyperPod throughout two fashions to check serving configurations.
Disaggregated prefill and decode for Qwen3-235B
We used AIPerf to check aggregated and disaggregated serving for Qwen3-235B-A22B-FP8 utilizing Dynamo with TensorRT-LLM on two p5en.48xlarge cases (16 H200 GPUs). Requests contained 4,000 enter tokens and 200 output tokens. We retained measured factors that met two targets: P90 time to first token under one second, and median era velocity of not less than 50 tokens per second per consumer. Amongst these factors, disaggregated serving achieved 2.05× the best aggregated throughput: 207 versus 101 output tokens per second per GPU, at concurrency 80 and 32, respectively.
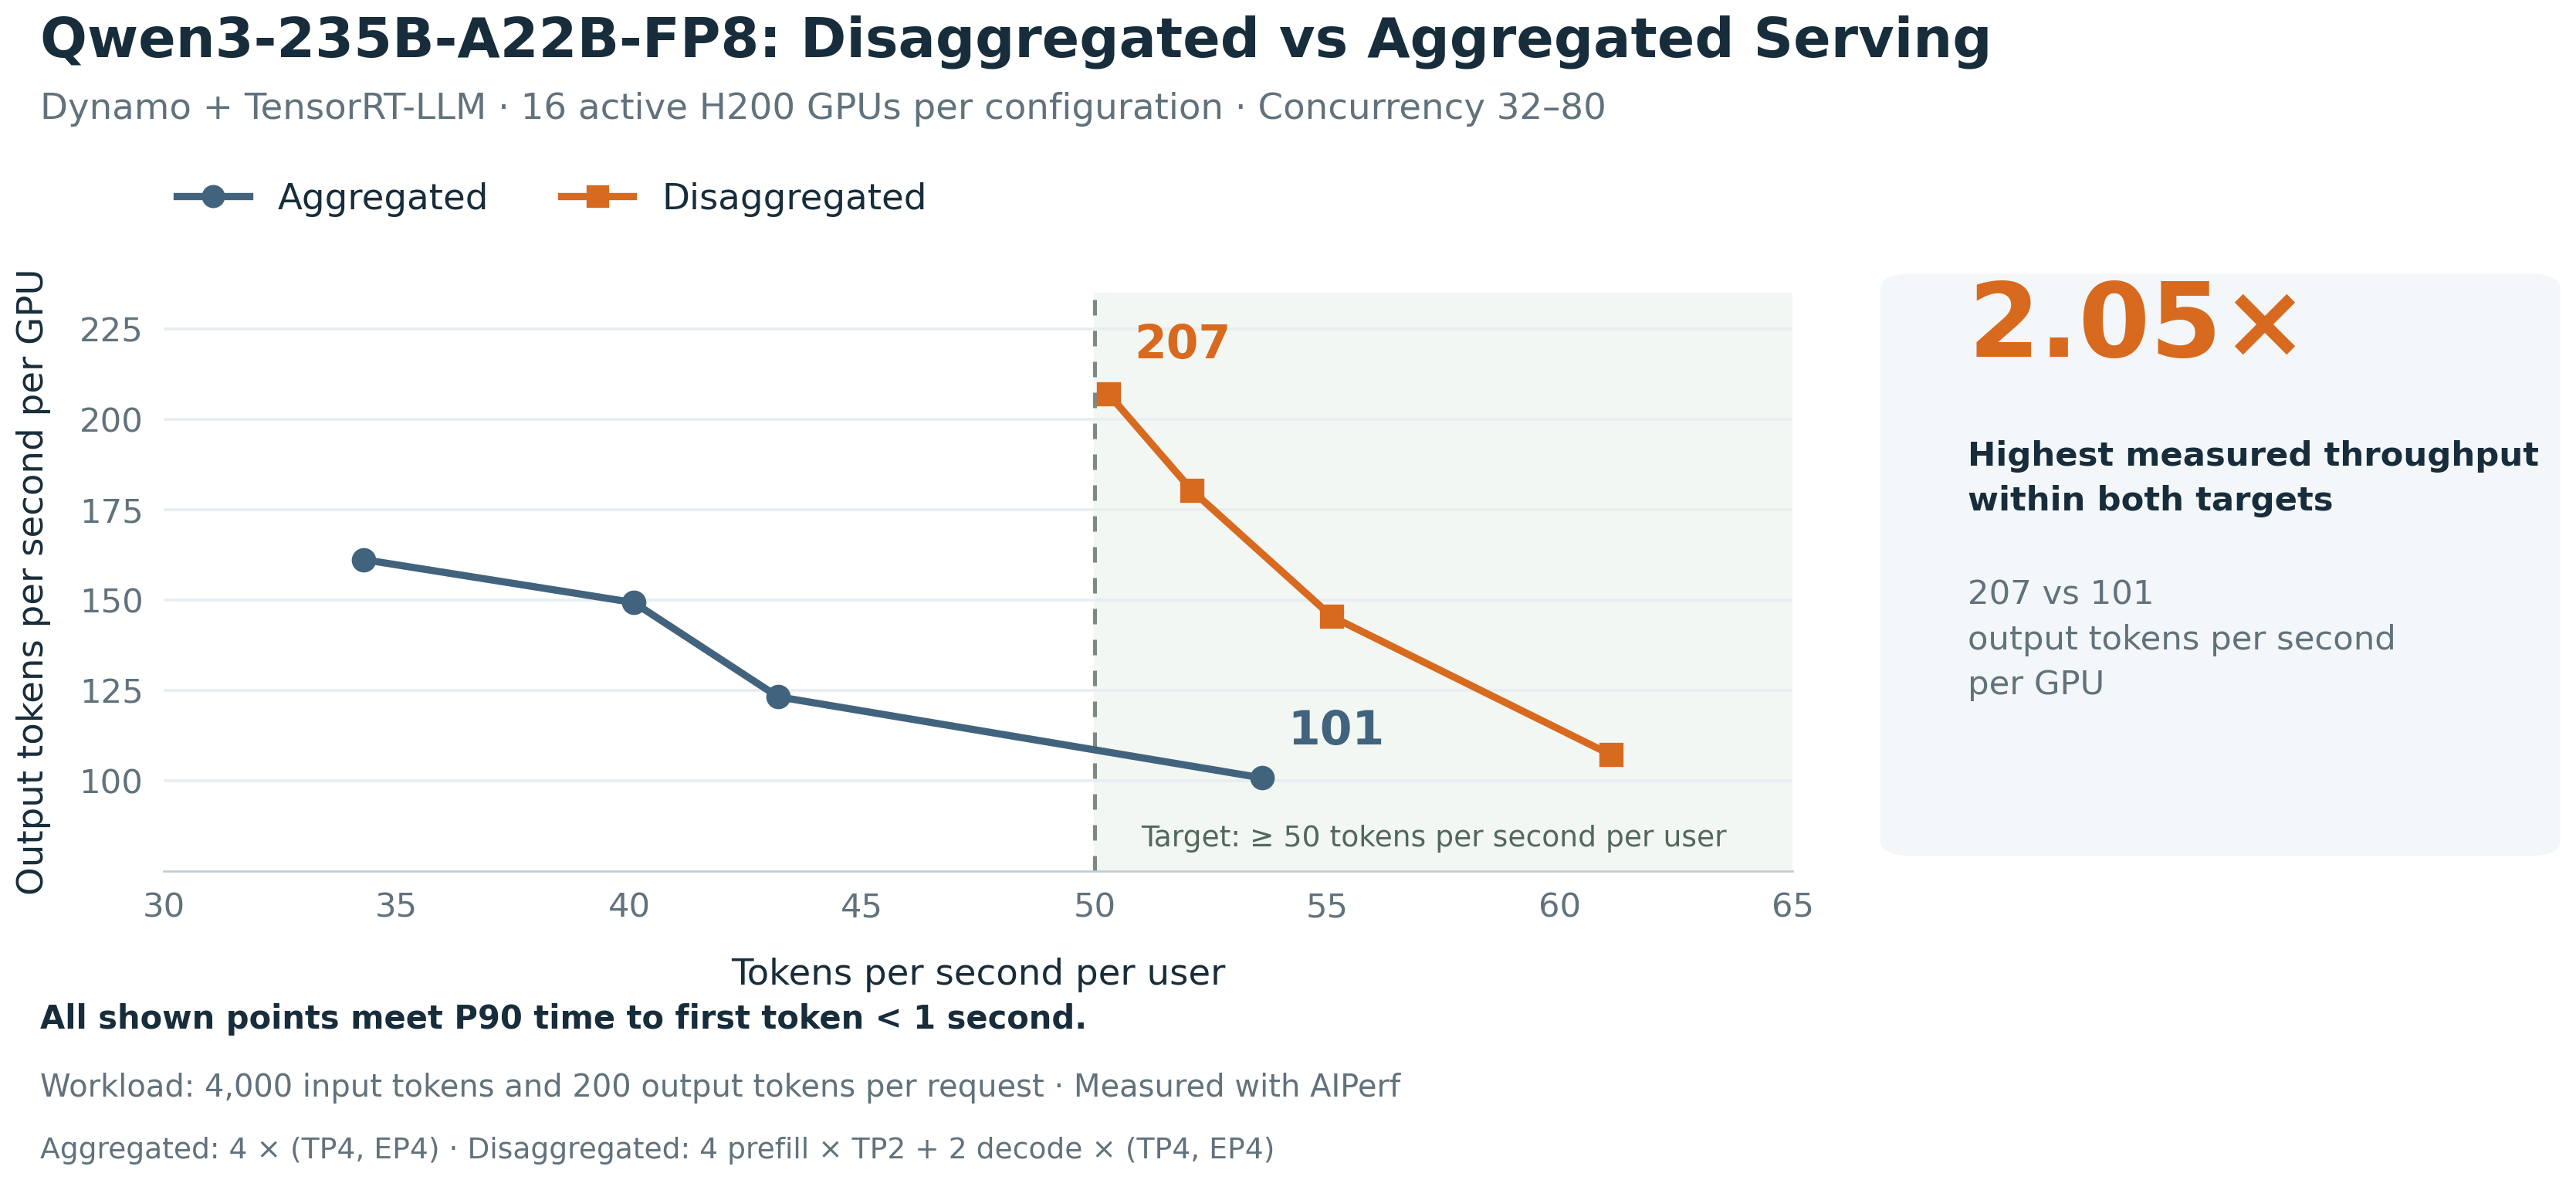
Determine 2: Aggregated in comparison with disaggregated serving throughput for Qwen3-235B-A22B-FP8
Multi-node aggregated serving for Qwen3.5-397B
Dynamo helps multi-node serving in each aggregated and disaggregated modes for fashions that exceed a single occasion’s GPU reminiscence. To judge a employee spanning nodes, we used AIPerf to benchmark multi-node aggregated serving for Qwen3.5-397B-A17B-FP8 with Dynamo and vLLM, utilizing TP4 × PP2 and eight lively H200 GPUs. This mannequin matches on one occasion, so in observe you wouldn’t cut up it. It serves right here as a managed baseline. We in contrast eight GPUs on one p5en.48xlarge in opposition to 4 GPUs on every of two cases, utilizing the identical mannequin, parallelism, and workload configuration. With an agentic workload that includes excessive prefix reuse at concurrency 32, the two-node configuration delivered 126.4 output tokens per second per GPU, retaining 99.1 % of single-node throughput. This reveals that Dynamo on SageMaker HyperPod can serve a mannequin that wants multiple occasion throughout nodes. The node boundary itself doesn’t develop into a big throughput penalty.
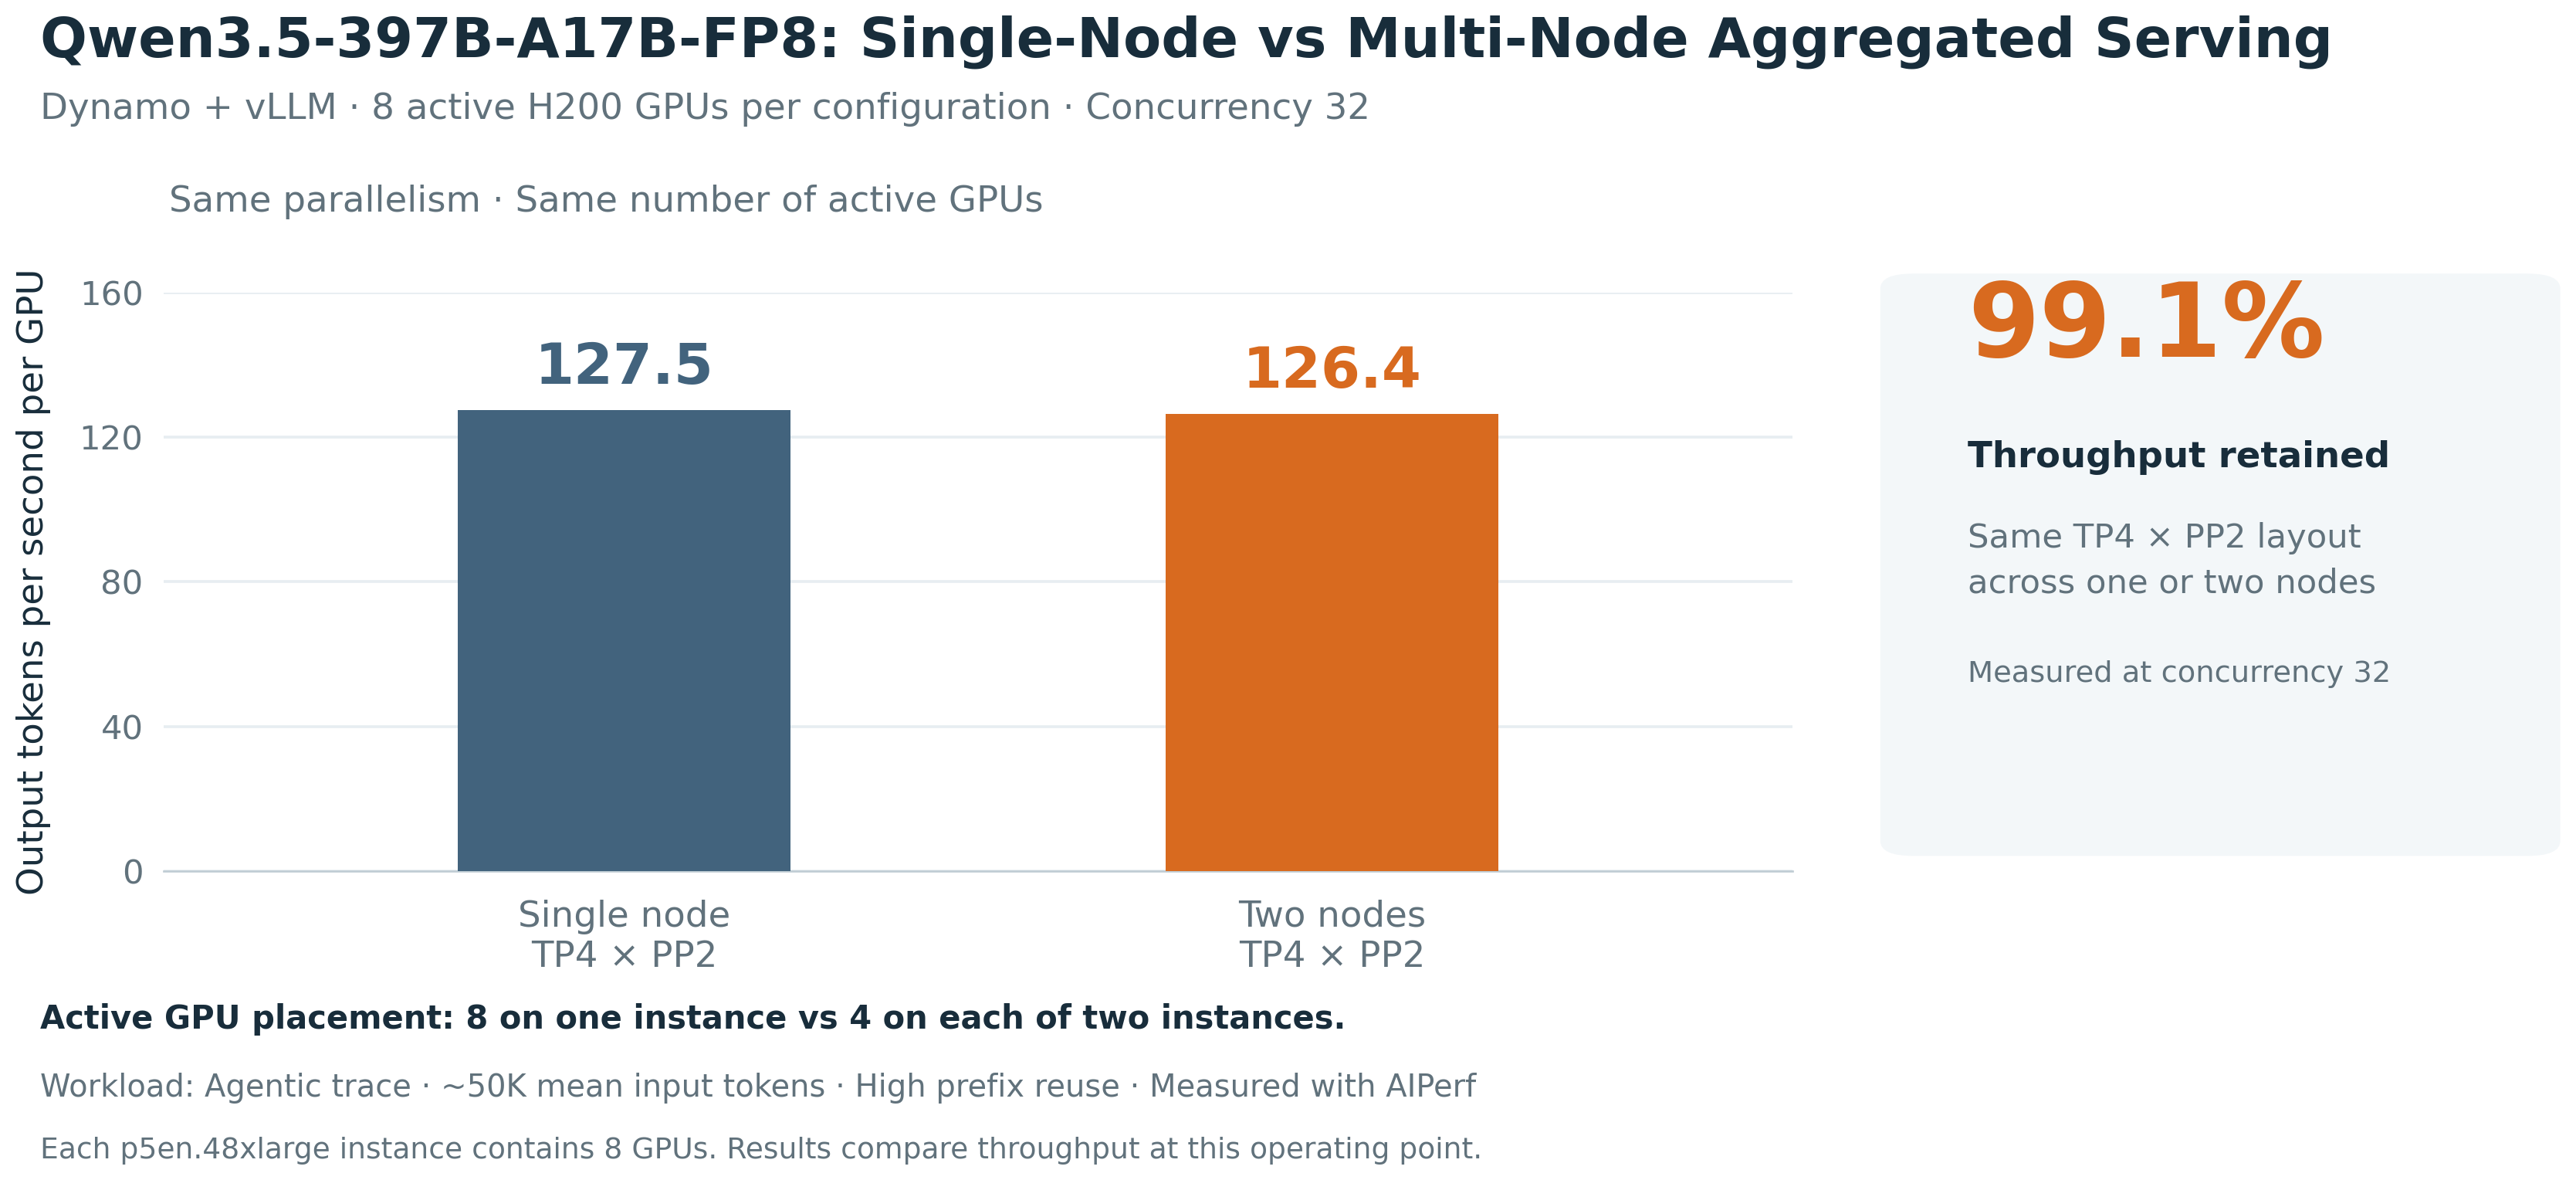
Determine 3: Single-node in comparison with two-node throughput for multi-node aggregated serving of Qwen3.5-397B-A17B-FP8
Greatest practices for optimized inference
NVIDIA Dynamo supplies recipes and instruments that can assist you choose a serving configuration, benchmark efficiency, and tune your deployment on SageMaker HyperPod.
- Begin with an identical recipe – Select a Dynamo recipe on your mannequin, inference engine, and GPU kind. Account for mannequin weights, KV cache, and runtime reminiscence when sizing staff. For supported configurations, AISimulate may also help examine aggregated and disaggregated serving, select parallelism, and dimension prefill and decode employee swimming pools earlier than testing on GPUs.
- Confirm communication earlier than benchmarking – For deployments spanning cases, affirm that communication makes use of the supposed EFA transport, together with KV-cache transfers between prefill and decode staff. See the Dynamo EFA information.
- Benchmark consultant visitors – Replay your visitors with AIPerf, or use a generated agentic hint with consultant immediate lengths, output lengths, and prefix reuse. Sweep concurrency for every configuration, retain factors assembly your SLAs, and select primarily based on price and latency priorities.
- Tune from measured bottlenecks – Regulate topology and employee allocation earlier than engine settings, altering one variable at a time. Observe the efficiency tuning information, or use Dynamo optimization agent abilities to help with benchmarking and tuning. Validate every candidate in your goal HyperPod deployment.
Conclusion
NVIDIA Dynamo on SageMaker HyperPod Inference simplifies deploying and working massive fashions with multi-node serving, disaggregated prefill and decode, and KV-aware routing. The managed add-on installs the serving elements, and configuration defaults simplify endpoint setup. HyperPod manages mannequin weights, auto-scales clusters primarily based on GPU and inference metrics, displays node well being, and replaces failed nodes. Collectively, these capabilities scale back undifferentiated infrastructure work so groups can give attention to their fashions and functions. Get began with the setup directions and full deployment examples within the linked repository.
Acknowledgements
The authors want to thank Eliuth Triana, Felipe Garcia, Sanjana Checker, Junyuan Yang, Jiahong Liu, Anish Maddipoti, Jacob Kern and Abdullahi Olaoye from NVIDIA for his or her contributions to this publish. We additionally want to thank Can Solar, Ophelia Yang, Aryaman Kothari, David Oh, and Ayush Kumar from AWS for his or her contributions.
In regards to the authors