
In the present day, Amazon introduced that SGLang-Neuron is publicly out there and could be accessed by an AWS Deep Studying Container, launched by RadixArk in collaboration with Annapurna Labs. With SGLang-Neuron, you possibly can serve fashions and generate reinforcement studying (RL) rollouts with SGLang on AWS Trainium utilizing the identical SGLang interface you employ in the present day. Trainium is a portfolio of AWS AI chips that delivers sturdy economics for AI coaching and inference at scale. Now, operating SGLang on Trainium follows the SGLang workflow you already know: you launch fashions by SGLang’s server interface and invoke the endpoint utilizing the identical technology APIs. Beneath that interface, SGLang-Neuron runs on native PyTorch. With its out-of-tree plugin design, Trainium assist and SGLang core develop independently and iterate sooner.
How SGLang runs on Trainium
SGLang-Neuron is an out-of-tree plugin that connects SGLang with AWS Trainium. Putting in the plugin registers the neuron platform by SGLang’s plugin entry factors, and setting SGLANG_PLATFORM=neuron selects it when the server begins. SGLang core continues to supply the API server, request lifecycle, RadixAttention, and prefix-cache bookkeeping. The plugin implements the Trainium-specific fashions, consideration, combination of consultants (MoE), and the graph runner.
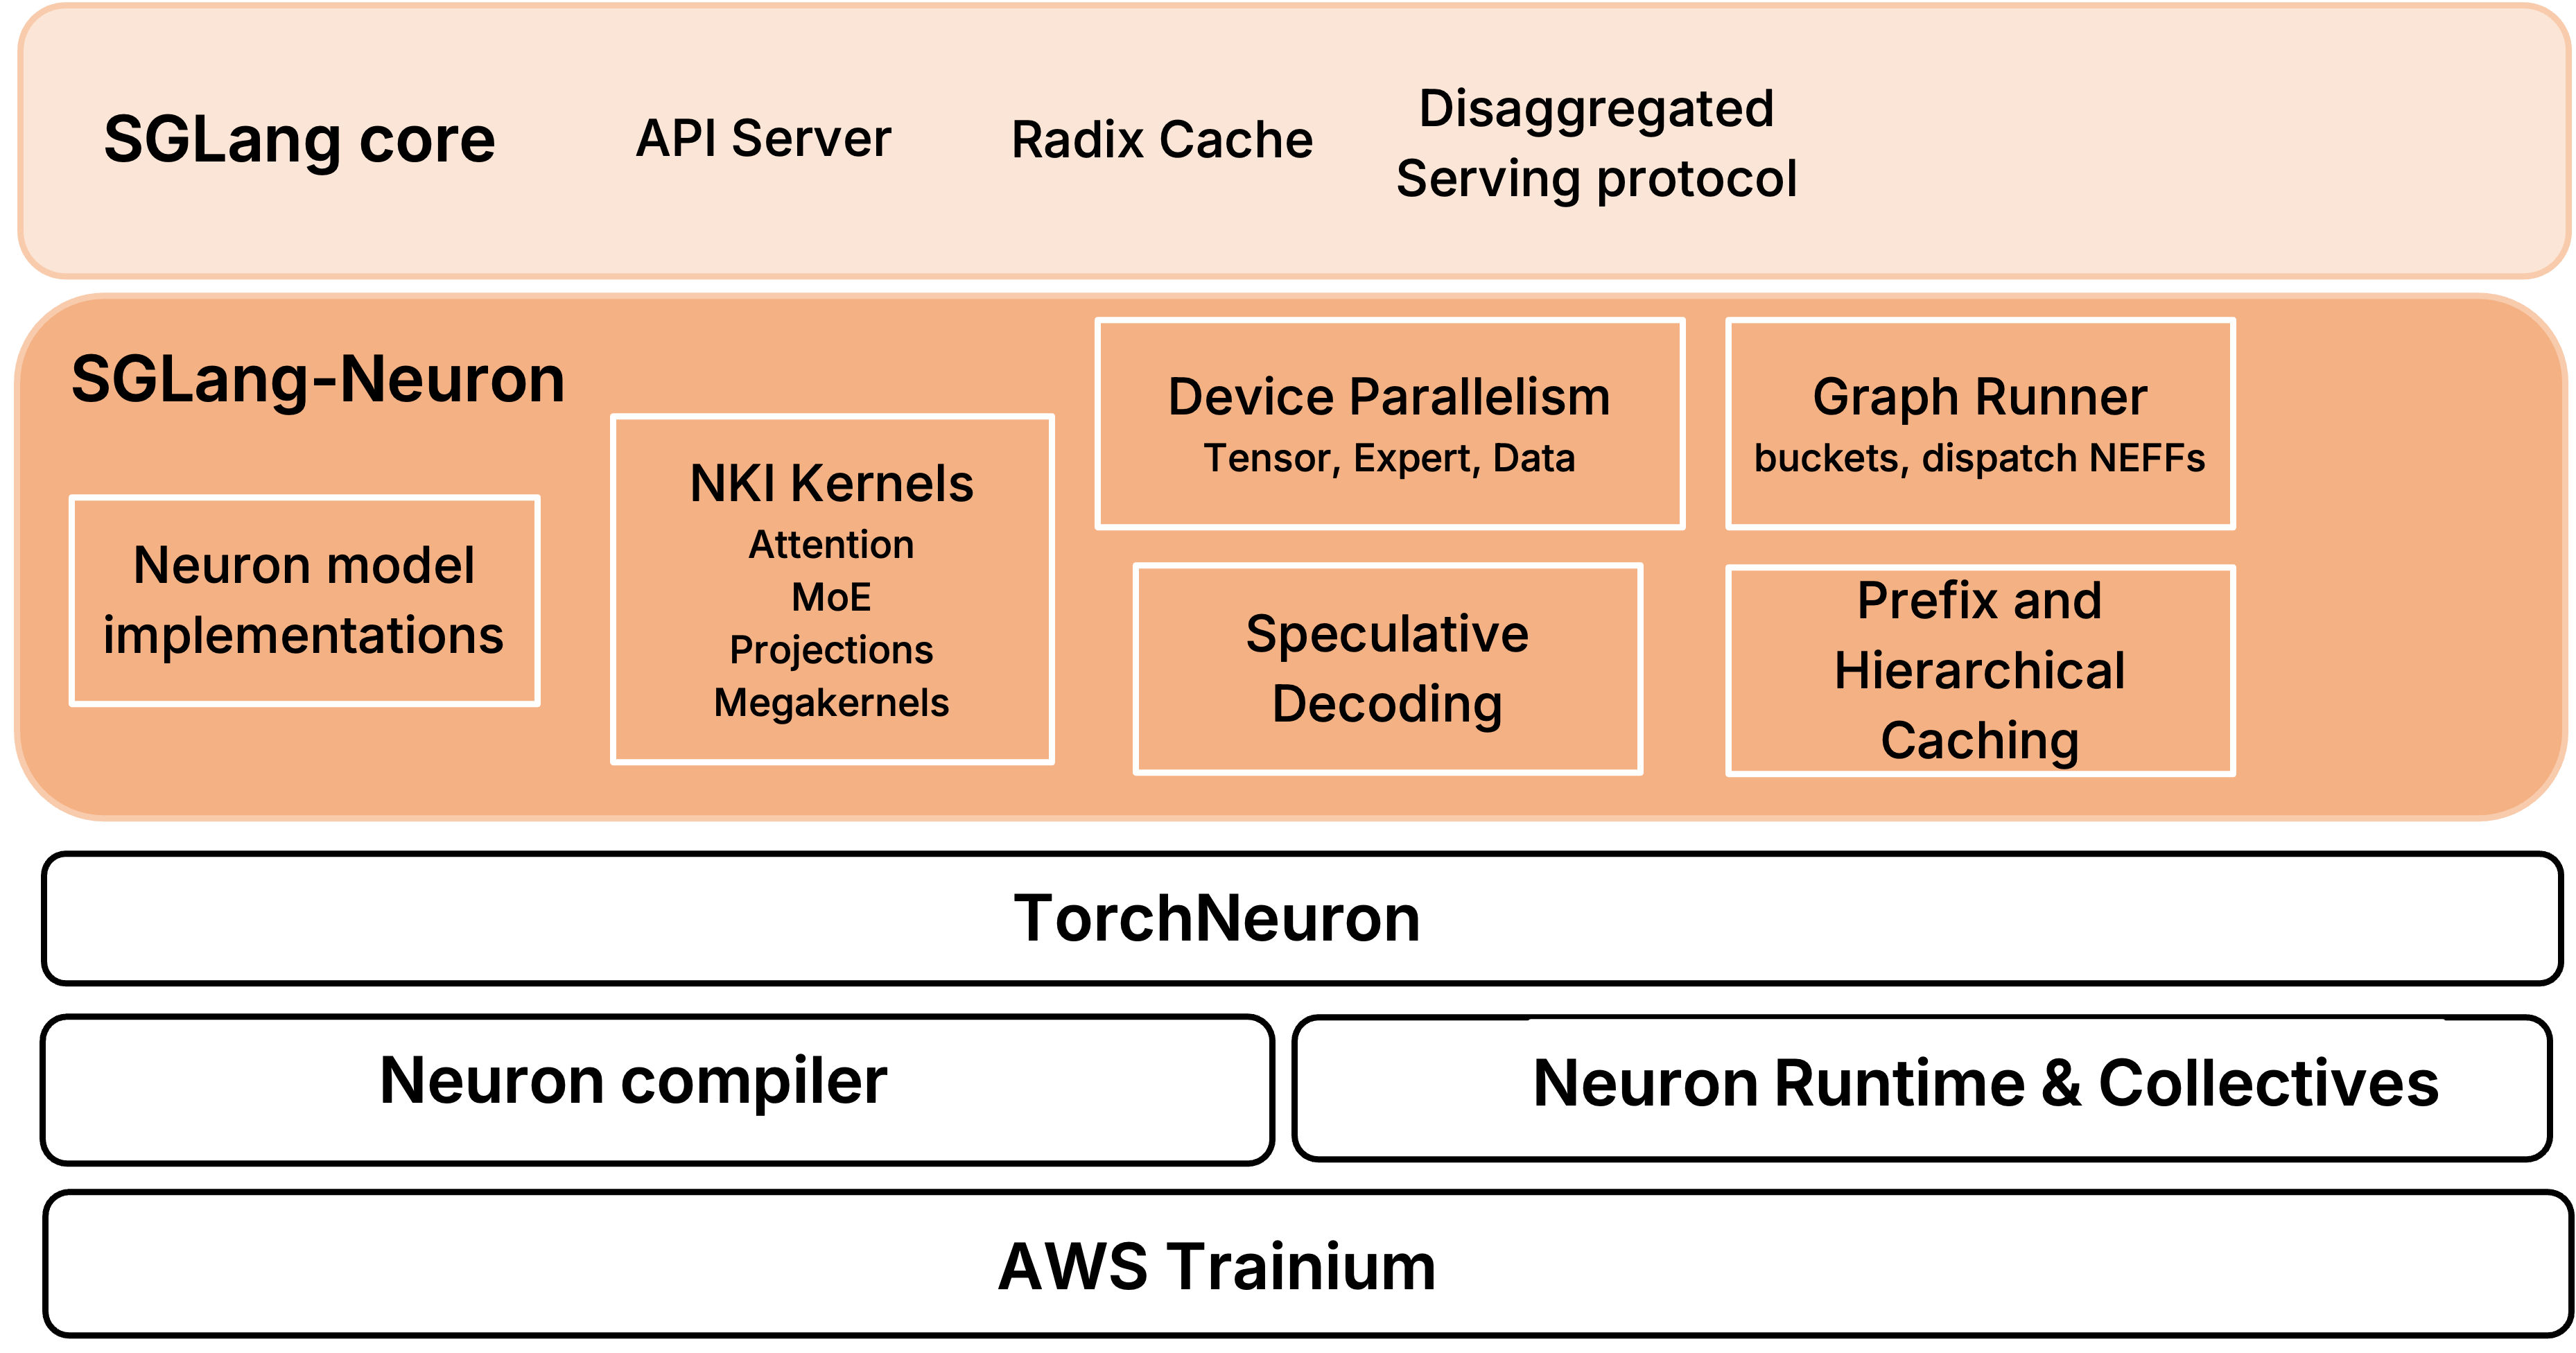
Determine 1: SGLang-Neuron on AWS Trainium
TorchNeuron registers Trainium as a local PyTorch machine. SGLang-Neuron makes use of customary PyTorch operations for the mannequin execution path and incorporates kernels written with the Neuron Kernel Interface (NKI) for efficiency. It compiles these operations and kernels into executable packages utilizing torch.compile, which the graph runner prepares and executes throughout serving.
SGLang-Neuron additionally helps PD disaggregation. On this configuration, a prefill server computes the immediate KV cache and transfers it to a decode server utilizing NIXL over Elastic Cloth Adapter (EFA). The decode server then generates the remaining tokens. Every server nonetheless makes use of SGLang’s scheduler and request lifecycle, whereas the plugin manages the Trainium execution and KV-cache switch path.
Serving fashions on AWS Trainium utilizing SGLang-Neuron
To comply with this walkthrough, you employ a Trainium3 Amazon Elastic Compute Cloud (Amazon EC2) occasion with a pytorch-inference-sglang-neuronx container. Listed below are the steps:
- Begin the container.
- Launch the SGLang mannequin server contained in the container.
- Ship a request to the mannequin server.
For added data, please see the SGLang-Neuron getting began information for setup directions, and discover the repository documentation for supported fashions, options, and validated configurations.
Conclusion
SGLang-Neuron brings SGLang’s acquainted serving workflow to AWS Trainium by native PyTorch. You will get began by launching the SGLang-Neuron container and following the quickstart to serve a supported mannequin. Strive it together with your workloads, contribute by the venture repository, and share suggestions to assist form future mannequin and have assist.
Concerning the authors