
Declare solutions are scattered throughout adjuster diary entries, restore estimates, police experiences, fee ledgers, and scanned attachments fairly than one searchable area. A policyholder would possibly ask whether or not a declare was accepted, whereas an adjuster would possibly want each open auto declare over $10,000 from final month. Each duties require discovering and mixing proof shortly and precisely.
Retrieval Augmented Technology (RAG) makes use of retrieved paperwork to floor mannequin responses. Amazon Bedrock Information Bases is the absolutely managed RAG functionality for paperwork. Amazon Bedrock handles parsing, chunking, embeddings, and vector storage, so you possibly can construct a conversational interface that returns cited solutions from declare recordsdata.
This technical how-to makes use of artificial declare data and doesn’t describe a manufacturing buyer deployment. You construct a claims assistant that solutions natural-language questions with citations by finishing these steps:
- Ingest declare paperwork and their metadata from Amazon Easy Storage Service (Amazon S3).
- Question them in plain language with the
AgenticRetrieveStreamAPI. - Ask multi-turn follow-up questions.
- Scope retrieval with metadata filters on attributes reminiscent of declare ID and declare kind.
- Add a contextual grounding guardrail to maintain solutions tied to the data.
The claims lookup problem
Policyholders, contact heart brokers, and adjusters ask totally different questions:
- Policyholders ask for a plain-language standing replace: “Has the estimate for declare CLM-100482 been accepted, and when will the test be issued?”
- Contact heart brokers want a quick, correct reply whereas the client waits, with out transferring the decision.
- Adjusters ask multi-part questions throughout claims, reminiscent of which open auto claims over $10,000 had been filed final month and what work stays on every.
Solutions are saved in PDF adjuster experiences, Phrase correspondence, and textual content notes fairly than constant database fields.
Information can battle or supersede earlier variations. A revised estimate can exchange an earlier one, or a provisional fee could be reversed later. The assistant should determine which estimate, fee, or standing controls.
As a result of claims are regulated, each reply have to be grounded in supply paperwork and embrace citations. Contact heart brokers can confirm a supply earlier than repeating a solution, and supervisors can audit how the assistant reached it.
Answer overview
The answer makes use of Amazon Bedrock Information Bases to index declare paperwork from Amazon S3 for retrieval.
Agentic retrieval by AgenticRetrieveStream plans a solution, breaks a multi-part query into sub-queries, and runs a number of retrieval passes. It checks whether or not the proof is ample earlier than producing a response.
The API streams hint occasions, reply textual content, and citations. Hint occasions expose the retrieval plan, and every quotation maps a part of the reply to a supply declare doc.
The next diagram reveals each paths. The ingestion lane hundreds declare paperwork and metadata right into a data base. The retrieval lane sends every query by AgenticRetrieveStream and an Amazon Bedrock Guardrails grounding test earlier than returning a cited reply.
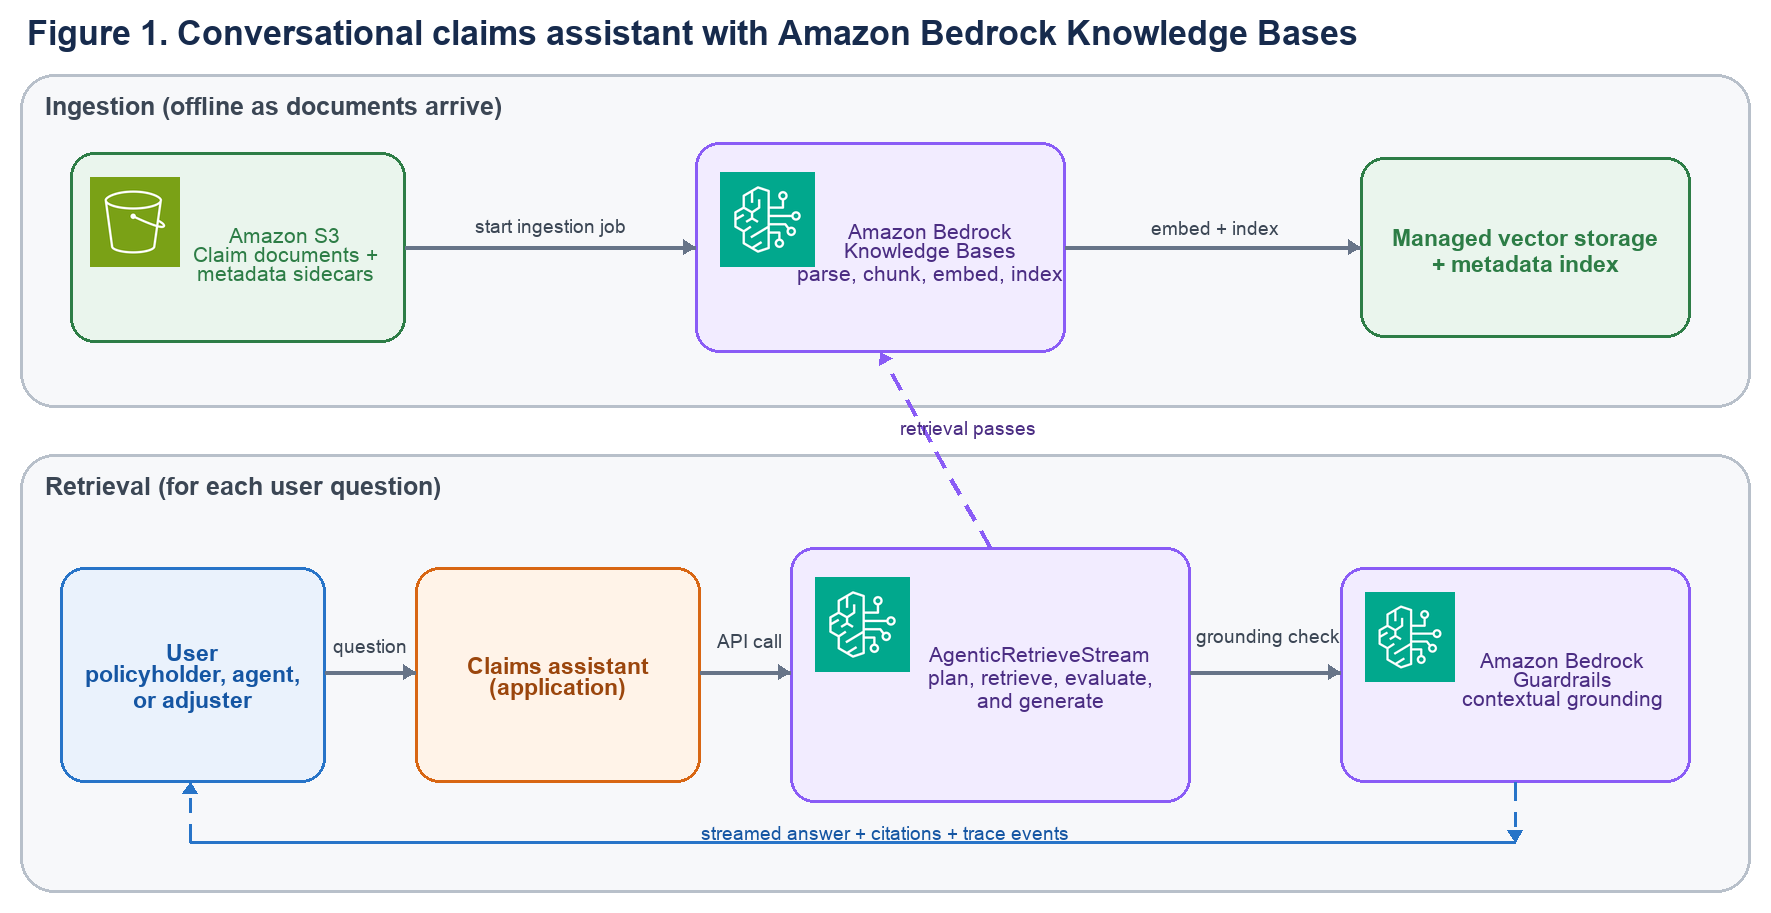
Determine 1: Conversational claims assistant with Amazon Bedrock Information Bases
The ingestion lane runs as paperwork arrive:
- Declare paperwork in PDF, Phrase, or textual content format land in Amazon S3 with matching metadata sidecars.
- An ingestion job synchronizes the S3 knowledge supply with the data base as paperwork change.
- The data base parses, chunks, embeds, and indexes the paperwork and their metadata in managed vector storage.
The retrieval lane runs for every query:
- The appliance calls
AgenticRetrieveStreamwith the query, dialog historical past, and optionally available metadata filters that scope the search. - A basis mannequin creates sub-queries and repeats retrieval till it has sufficient proof, as much as maxAgentIteration rounds.
- A contextual grounding test blocks solutions which can be unsupported by the retrieved data.
- Amazon Bedrock streams the reply, hint occasions, and citations, so the appliance can show output because it arrives.
Stipulations
Earlier than you start, confirm that you’ve got the next:
- An AWS account with AWS Id and Entry Administration (IAM) permissions for Amazon Bedrock and Amazon S3.
- Entry to a basis mannequin (FM) enabled by Amazon Bedrock mannequin entry.
- An AWS Area that helps the chosen basis mannequin and Amazon Bedrock Information Bases. This walkthrough makes use of US West (Oregon), us-west-2. Examine Supported fashions by AWS Area in Amazon Bedrock earlier than deployment.
- The AWS SDK for Python (Boto3), configured with credentials and a model that helps the APIs used right here.
- An S3 bucket for the artificial declare paperwork and metadata.
- Familiarity with Python and with primary RAG ideas.
Retailer one doc per declare in Amazon S3. The data base reads PDF adjuster experiences, Phrase correspondence, and textual content notes immediately, so you possibly can maintain paperwork of their native format.
Determine 2 reveals an artificial declare report. Present publicity is the estimated whole declare price. Its proof index identifies a outdated fax draft, that means a report changed by a more moderen model. The metadata sidecar repeats fields that the assistant can filter.
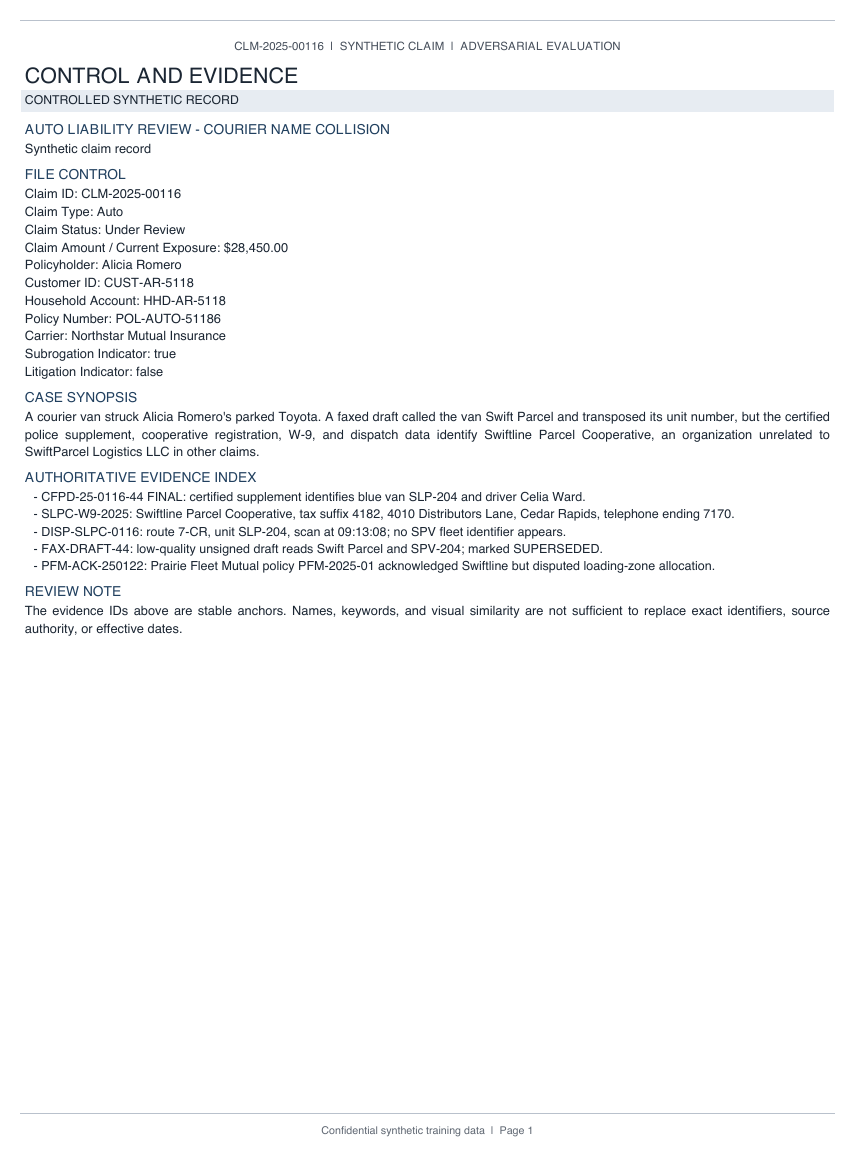
Determine 2: An artificial declare report with its file-control fields and proof index
For filtering, add an accompanying metadata file with the identical identify plus .metadata.json. For CLM-100482.pdf, use CLM-100482.pdf.metadata.json. Subrogation is an insurer’s effort to get well prices from a accountable third social gathering. The next instance describes one auto declare:
The sidecar comprises scalar string, quantity, and Boolean values. Worth sorts decide out there filters. The next desk lists fields used later within the queries.
This submit makes use of artificial knowledge. Don’t place actual personally identifiable info (PII) or protected well being info in these sources with out the required controls and approvals.
| Attribute | Sort | Instance | Filter use |
claim_id |
String | CLM-100482 |
equals for a single-claim lookup |
claim_type |
String | auto |
equals or in for a line of enterprise |
standing |
String | open |
in for energetic work queues |
quantity |
Quantity | 14250 |
numeric vary comparisons |
date_filed |
Quantity | 20260709 |
date ranges as YYYYMMDD integers |
area |
String | us-west |
tenant scoping from the session |
customer_id |
String | CUST-MM-1042 |
buyer scoping from the session |
has_subrogation |
Boolean | true |
equals for restoration work |
Retailer dates as YYYYMMDD integers as a result of metadata filters examine numbers fairly than date strings. This format helps ranges reminiscent of “filed final month.”
Retailer just one comparable financial worth in quantity. A reserve is cash put aside for the estimated declare price, whereas a maintain is quickly withheld. Hold reserves, funds, and holds in doc textual content so their labels stay clear.
Sidecar recordsdata are restricted to 10 KB. See Connect with Amazon S3 in your data base for the entire format.
The S3 format pairs every declare doc with its metadata file:
Create the managed data base and ingest the claims
Create the data base with the bedrock-agent shopper. Set knowledgeBaseConfiguration.kind and embeddingModelType to MANAGED.
Amazon Bedrock selects and operates the embedding mannequin. No vector retailer configuration is required. See CreateKnowledgeBase for all parameters. The next code creates the data base:
The roleArn service function grants the data base permission to learn the S3 bucket and use the managed embedding mannequin. See Create a service function for Amazon Bedrock Information Bases. To encrypt managed vector storage with a buyer managed AWS Key Administration Service (AWS KMS) key, move its ARN in serverSideEncryptionConfiguration.
Subsequent, join the S3 bucket as an information supply. The inclusionPrefixes setting limits ingestion to claims/:
Begin an ingestion job to parse, chunk, embed, and index the paperwork. Run it once more every time declare paperwork are added or up to date so the index stays synchronized:
Examine standing with get_ingestion_job or the Amazon Bedrock console. When the job completes, the claims are searchable. See StartIngestionJob for particulars.
Question claims with the AgenticRetrieveStream API
With the claims ingested, name AgenticRetrieveStream with the bedrock-agent-runtime shopper. See the API reference for full request and response syntax. The request has three elements:
- messages: Dialog turns. Every message has a person or assistant function and a content material.textual content worth.
- retrievers: As much as 5 data bases. Every features a data base ID and may specify a metadata filter and maxNumberOfResults (1–100). Improve the restrict for questions that span many claims.
- agenticRetrieveConfiguration: Planning mannequin and iteration restrict. Use MANAGED for the service mannequin. To make use of a selected mannequin, use CUSTOM with a mannequin ARN. maxAgentIteration caps the variety of planning and retrieval rounds.
This request asks for one declare’s standing. Setting generateResponse to True returns a natural-language reply:
Iterate over response[“stream”] and deal with these three occasion sorts:
- traceEvent: Experiences planning, retrieval, full-document growth, guardrail actions, standing, and generated sub-queries for every step.
- responseEvent: Offers incremental reply textual content that you could stream to the person.
- consequence: Incorporates deduplicated retrieval outcomes and, when generateResponse is True, the entire generated reply and its citations.
The next loop streams reply chunks as they arrive and retains the ultimate consequence for quotation rendering:
Learn the hint to see the plan
The essential loop prints every step and standing. This helper additionally prints sub-queries, full-document fetches, and guardrail actions:
Determine 3 reveals the agentic loop. The service plans a technique, creates sub-queries, retrieves proof, and checks whether or not it has sufficient. If wanted, it runs one other move earlier than producing a cited reply.
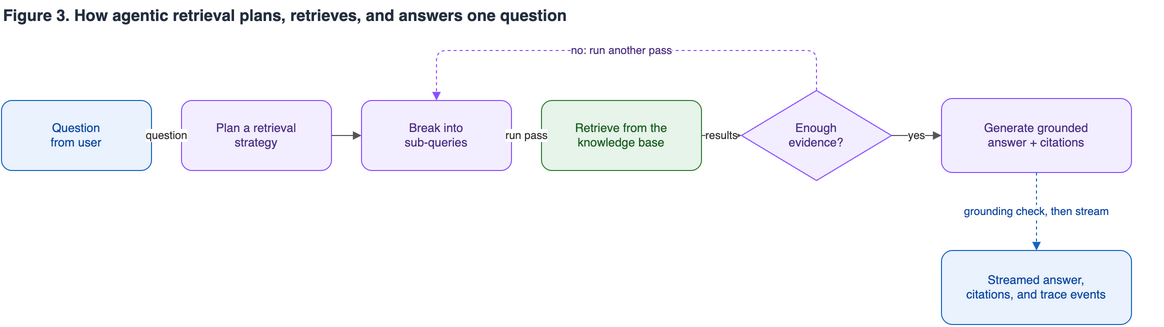
Determine 3: The agentic retrieval loop from query to cited reply
Render citations
Every quotation identifies a personality span within the reply and references supporting entries within the consequence occasion’s outcomes array. The appliance makes use of the indexes to affiliate the displayed textual content with its supply paperwork.
The next code prints every cited span beside the built-in x-amz-bedrock-kb-source-uri worth for its supply doc:
Ask follow-up questions in a multi-turn dialog
Comply with-up questions rely upon prior turns. After a standing reply, a policyholder would possibly ask, “Who’s the adjuster assigned to it?” The phrase it is resolved from the dialog historical past handed in messages.
Hold the dialog within the software. After every flip, append the person’s query and the assistant’s reply, then ship the entire checklist on the subsequent name:
The service makes use of earlier turns to resolve it to assert CLM-100482 and retrieves that declare’s adjuster. Course of the response stream as earlier than.
Metadata filters limit paperwork earlier than semantic search. Add them beneath the retriever’s retrievalOverrides. Use question filters for relevance, and derive authorization filters from the authenticated session on the server.
For a direct lookup by declare ID, use an equals filter:
For open auto claims over $10,000 filed in July 2026, mix declare kind, standing, quantity, and date situations with andAll:
This question can match many claims, so maxNumberOfResults is 50. A smaller restrict may omit matching claims from the abstract.
Supported operators embrace equals, notEquals, numeric comparisons, in, notIn, stringContains, listContains, and logical andAll/orAll. startsWith is restricted to Amazon OpenSearch Serverless vector shops. See Metadata and filtering and make sure operator help.
If a filter returns no paperwork, test for an empty consequence and return a transparent message reminiscent of “No claims match these standards” as an alternative of producing a solution.
What we measured
We measured this 30-document artificial corpus with Retrieve and RetrieveAndGenerate, not AgenticRetrieveStream. Deal with the outcomes as a baseline for the corpus and metadata schema, not an agentic retrieval benchmark.
The 40-question suite consists of direct lookups, comparisons, aliases, outdated data, reversed funds, and instruction-like doc textual content. Automated foundation-model grading makes the fact-level outcomes directional.
Anticipated-source retrieval recall measures required paperwork discovered. Quotation recall measures required paperwork cited. Each common per query at doc degree and don’t measure chunk precision.
The next desk reveals the general outcomes.
| Metric | Outcome |
| Questions answered | 40 of 40 |
| Solutions carrying citations | 40 of 40 |
| Imply citations per reply | 3.9 |
| Anticipated-source retrieval recall | 90.5% |
| Anticipated-source quotation recall | 81.2% |
| Chunks contradicting the requested filter | 0 |
Supply: the 40-question analysis suite and foundation-model grader described right here.
On 20 adversarial questions, retrieval recall was 96.7 % and quotation recall was 90.2 %. The mannequin stored equally named firms separate, preserved an allegation as an allegation, and ignored instruction-like textual content inside an attachment.
Determine 4 compares expected-source retrieval and quotation recall for the total suite and adversarial subset. These measurements use Retrieve and RetrieveAndGenerate.
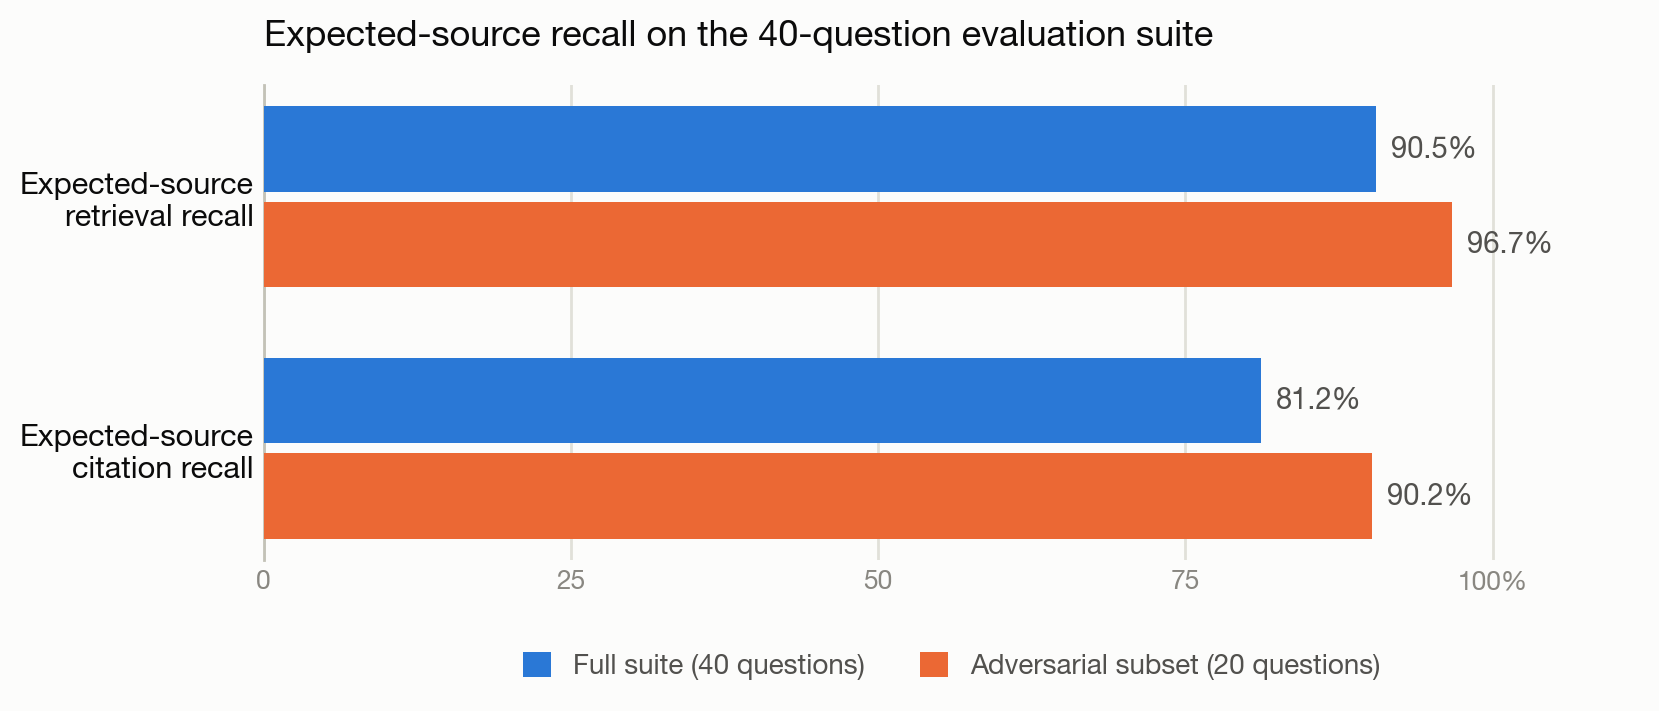
Determine 4: Anticipated-source retrieval and quotation recall, full suite versus adversarial subset
Slender claim-specific questions carried out finest. Broad unfiltered stock questions produced the three weakest outcomes.
Quotation protection doesn’t assure reply completeness, so measure completeness individually when it issues.
These outcomes use artificial paperwork and automatic grading. Run human overview by yourself corpus earlier than exposing an assistant to policyholders.
Add safety and governance
A claims assistant wants entry controls and grounded responses.
Scope filters to the authenticated person
Deal with metadata filters as an entry boundary. Derive area or customer_id from the authenticated session, mix it with question filters utilizing andAll, and by no means settle for the boundary from person textual content. The userContext area additionally helps access-control filtering.
IAM permissions
Grant solely the permissions wanted for agentic retrieval, knowledge-base entry, mannequin streaming, and guardrail actions:
AWS CloudTrail data calls to Amazon Bedrock for auditing.
Encryption
Amazon S3 encrypts objects at relaxation by default. See Configuring default encryption. You need to use buyer managed AWS KMS keys for the bucket and managed vector storage. API visitors makes use of Transport Layer Safety (TLS).
Contextual grounding with Amazon Bedrock Guardrails
Add an Amazon Bedrock Guardrails contextual grounding test to dam responses beneath configured grounding or relevance thresholds:
- Grounding: Consistency with retrieved declare paperwork.
- Relevance: Alignment with the person’s query.
Create a guardrail with the bedrock shopper. See CreateGuardrail for all coverage sorts, and select a excessive grounding threshold for claims:
Greater thresholds block extra responses. In claims workflows, declining to reply is safer than producing unsupported content material. Go the guardrail ID and model in policyConfiguration:
Agentic retrieval helps the BLOCK motion. A failed grounding test blocks the response, and hint occasions report the intervention.
Hold an individual within the loop to overview cited proof and make the ultimate declare choice.
Clear up
Delete the sources when completed to keep away from future costs:
- Delete the data base. This additionally removes the managed vector storage:
- Delete the guardrail:
- Empty and delete the S3 bucket.
- Delete the knowledge-base IAM function and coverage.
Conclusion
You constructed a claims assistant with Amazon Bedrock Information Bases and artificial paperwork in Amazon S3.
AgenticRetrieveStream handles multi-part questions, dialog historical past, metadata filters, grounding checks, streamed solutions, and citations.
The identical sample applies to underwriting and policy-service paperwork. Be taught extra in Amazon Bedrock Information Bases and Use agentic retrieval to question a data base.
Concerning the authors