
On this article, you’ll learn the way pgvector compares to devoted vector databases when it comes to actual, measured efficiency, and the way to resolve which strategy fits your manufacturing workload.
Matters we are going to cowl embrace:
- What pgvector and devoted vector databases are, and the way they differ architecturally.
- The best way to arrange and run a hands-on benchmark evaluating pgvector and Qdrant by yourself machine.
- What production-scale benchmark knowledge truly reveals about throughput, latency, and the tradeoffs between the 2 approaches.
A workforce provides pgvector to their present Postgres database on a Tuesday afternoon, embeddings and relational knowledge sitting in the identical desk, one question doing each the filter and the similarity search. Six months later, a vendor pitch lands of their inbox insisting they should migrate to a “actual” vector database earlier than they hit a wall. No benchmark accompanies the declare in both course, simply confidence. That hole — sturdy opinions with no numbers behind them — is strictly what this text exists to shut.
What pgvector Truly Is
pgvector is an open-source Postgres extension, presently at model 0.8.6 and supporting Postgres 13 and later, in line with its official GitHub repository. It provides a local vector column sort to Postgres, together with actual and approximate nearest-neighbor search, immediately contained in the database you’re possible already working.
What which means in apply: a vector embedding lives in the identical desk because the document it describes, in the identical row if you need, queried with the identical SQL you already know. There’s no separate service to face up, no second system to maintain in sync, no community hop between your relational knowledge and your vector knowledge. pgvector helps single-precision, half-precision, binary, and sparse vector sorts, and 5 distance features — L2, interior product, cosine, L1, and Hamming — overlaying primarily each distance metric an actual embedding mannequin makes use of.
What a Devoted Vector Database Is
A devoted vector database is a separate, purpose-built service, run as its personal course of with its personal storage engine, designed from the bottom up round vector search relatively than having it added onto a general-purpose database. It’s a genuinely totally different architectural selection, not only a totally different product, because it means a brand new system to deploy, monitor, again up, and maintain synchronized with no matter holds your precise supply of fact.
Right here’s a plain rundown of the 5 mostly reached for:
| Database | Greatest for |
|---|---|
| Pinecone | A totally managed, zero-setup cloud database, greatest for low-ops enterprise scale |
| Qdrant | A high-performance Rust-based database, greatest for quick queries with advanced JSON payload filtering |
| Weaviate | An open-source, AI-native system, greatest for built-in vectorization and hybrid BM25 search |
| Milvus | A distributed, GPU-accelerated database, greatest for large, billion-scale enterprise workloads |
| ChromaDB | A light-weight, embedded database, greatest for native prototyping and Python improvement |
Stipulations
The whole lot on this tutorial runs completely by yourself machine — no cloud account required. You’ll want Docker and Docker Compose put in, Python 3.10 or later, roughly 8GB of free RAM, and fundamental consolation studying SQL and Python. The hands-on benchmark under is sized to run comfortably on a laptop computer.
Setting Up pgvector Domestically
Begin with a Docker Compose file that runs Postgres with pgvector already inbuilt:
|
# docker-compose.yml companies: postgres: picture: pgvector/pgvector:pg17 ports: – “5432:5432” atmosphere: – POSTGRES_PASSWORD=benchmark – POSTGRES_DB=vectorbench |
Run docker compose up -d, then join and arrange the extension and desk:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
import psycopg2
conn = psycopg2.join( host=“localhost”, port=5432, dbname=“vectorbench”, person=“postgres”, password=“benchmark”, ) conn.autocommit = True cur = conn.cursor()
# Allows the vector sort and index entry strategies for this database cur.execute(“CREATE EXTENSION IF NOT EXISTS vector;”)
# 1536 dimensions matches OpenAI’s text-embedding-3-small, a practical # stand-in for a real manufacturing embedding mannequin cur.execute(“”“ CREATE TABLE IF NOT EXISTS objects ( id bigserial PRIMARY KEY, embedding vector(1536) ); ““”) |
pgvector/pgvector:pg17 is the official Docker picture that bundles the extension with Postgres 17, so there’s no separate compile step. CREATE EXTENSION IF NOT EXISTS vector is the one-time step that registers the vector sort and its index strategies on this particular database, per the pgvector documentation.
Setting Up Qdrant Domestically
For the dedicated-database facet of the comparability, run Qdrant with a single Docker command:
|
docker run –d —identify qdrant–bench –p 6333:6333 –p 6334:6334 qdrant/qdrant |
Then join from Python and create an identical assortment:
|
from qdrant_client import QdrantClient from qdrant_client.fashions import Distance, VectorParams
qdrant = QdrantClient(url=“http://localhost:6333”)
qdrant.create_collection( collection_name=“objects”, vectors_config=VectorParams(measurement=1536, distance=Distance.COSINE), ) |
Qdrant is price selecting particularly for this comparability as a result of it’s the topic of probably the most detailed, methodologically clear public benchmark towards pgvector out there, which this text attracts on immediately in a later part. VectorParams(measurement=1536, distance=Distance.COSINE) mirrors the identical dimensionality and distance metric used within the pgvector desk above, which issues — a good comparability wants each methods measuring the identical factor.
Producing and Loading a Actual Check Dataset
With each methods working, generate a practical set of artificial vectors and cargo them into every:
|
import numpy as np
NUM_VECTORS = 100_000 DIM = 1536
rng = np.random.default_rng(seed=42) vectors = rng.regular(measurement=(NUM_VECTORS, DIM)).astype(np.float32)
# Actual embedding fashions produce normalized vectors, so normalize # these to size 1 for a practical cosine-distance comparability vectors /= np.linalg.norm(vectors, axis=1, keepdims=True) |
Load into pgvector utilizing pgvector-python’s adapter, which lets psycopg2 settle for NumPy arrays immediately:
|
from pgvector.psycopg2 import register_vector from psycopg2.extras import execute_values
register_vector(conn)
knowledge = [(v,) for v in vectors] execute_values(cur, “INSERT INTO objects (embedding) VALUES %s”, knowledge, template=“(%s)”) |
Load the identical vectors into Qdrant in batches:
|
from qdrant_client.fashions import PointStruct batch_size = 1000 for begin in vary(0, NUM_VECTORS, batch_size): batch = vectors[start:start + batch_size] factors = [ PointStruct(id=start + i, vector=batch[i].tolist()) for i in vary(len(batch)) ] qdrant.upsert(collection_name=“objects”, factors=factors) |
register_vector(conn) is the important thing line on the pgvector facet — it teaches psycopg2 the way to convert a NumPy array into the format pgvector expects, so execute_values can insert uncooked arrays with out guide string formatting. On the Qdrant facet, upsert is batched intentionally at 1,000 vectors per name relatively than one large request, since Qdrant’s shopper, like most vector database purchasers, performs higher with fairly sized batches than both single inserts or one large payload.
Constructing the Indexes
Create an HNSW index in pgvector, straight from pgvector’s personal indexing documentation:
|
cur.execute( “CREATE INDEX ON objects USING hnsw (embedding vector_cosine_ops) “ “WITH (m = 16, ef_construction = 64);” ) |
Apply matching HNSW parameters in Qdrant, so each methods are working the identical underlying algorithm with the identical settings:
|
from qdrant_client.fashions import HnswConfigDiff
qdrant.update_collection( collection_name=“objects”, hnsw_config=HnswConfigDiff(m=16, ef_construct=64), ) |
m controls the utmost variety of connections per node within the HNSW graph, and ef_construction controls how thorough the search is whereas constructing it. Each are set to 16 and 64 right here — pgvector’s personal defaults — intentionally mirrored on the Qdrant facet. This issues greater than it may appear: evaluating two methods working totally different index parameters isn’t a benchmark, it’s two separate, incomparable outcomes. Matching them is what makes the numbers within the subsequent part imply something.
Operating the Benchmark
Right here’s the precise measurement script, querying each methods with a recent, held-out set of question vectors that weren’t a part of the loaded dataset:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 |
import time import statistics
query_vectors = rng.regular(measurement=(200, DIM)).astype(np.float32) query_vectors /= np.linalg.norm(query_vectors, axis=1, keepdims=True)
def benchmark_pgvector(cur, query_vectors, ef_search=64, restrict=10): cur.execute(f“SET hnsw.ef_search = {ef_search};”) latencies = [] for qv in query_vectors: begin = time.perf_counter() cur.execute( “SELECT id FROM objects ORDER BY embedding <=> %s LIMIT %s”, (qv, restrict), ) cur.fetchall() latencies.append((time.perf_counter() – begin) * 1000) # ms return latencies
def benchmark_qdrant(shopper, query_vectors, restrict=10): latencies = [] for qv in query_vectors: begin = time.perf_counter() shopper.query_points(collection_name=“objects”, question=qv.tolist(), restrict=restrict) latencies.append((time.perf_counter() – begin) * 1000) return latencies
def summarize(identify, latencies, total_time): latencies_sorted = sorted(latencies) p50 = statistics.median(latencies_sorted) p95 = latencies_sorted[int(len(latencies_sorted) * 0.95)] p99 = latencies_sorted[int(len(latencies_sorted) * 0.99)] qps = len(latencies) / total_time print(f“{identify}: p50={p50:.2f}ms p95={p95:.2f}ms p99={p99:.2f}ms QPS={qps:.1f}”)
begin = time.perf_counter() pg_latencies = benchmark_pgvector(cur, query_vectors) summarize(“pgvector”, pg_latencies, time.perf_counter() – begin)
begin = time.perf_counter() qdrant_latencies = benchmark_qdrant(qdrant, query_vectors) summarize(“Qdrant”, qdrant_latencies, time.perf_counter() – begin) |
A couple of issues price understanding right here. The 200 question vectors are freshly generated, not pulled from the 100,000 already loaded, since querying with a vector that’s actually already within the index trivially returns itself at zero distance, which might make the benchmark meaningless.
SET hnsw.ef_search = 64 controls how thorough pgvector’s search is at question time — larger values commerce pace for higher recall, and setting it explicitly relatively than counting on the default makes the take a look at reproducible. embedding <=> %s is pgvector’s cosine distance operator, matching the Distance.COSINE setting used on the Qdrant assortment. And shopper.query_points() is Qdrant’s present advisable search technique, changing the older search() name in latest variations of the shopper. The summarize operate computes the identical three percentiles — p50, p95, p99 — plus queries-per-second for each methods, so the output is immediately comparable line for line.
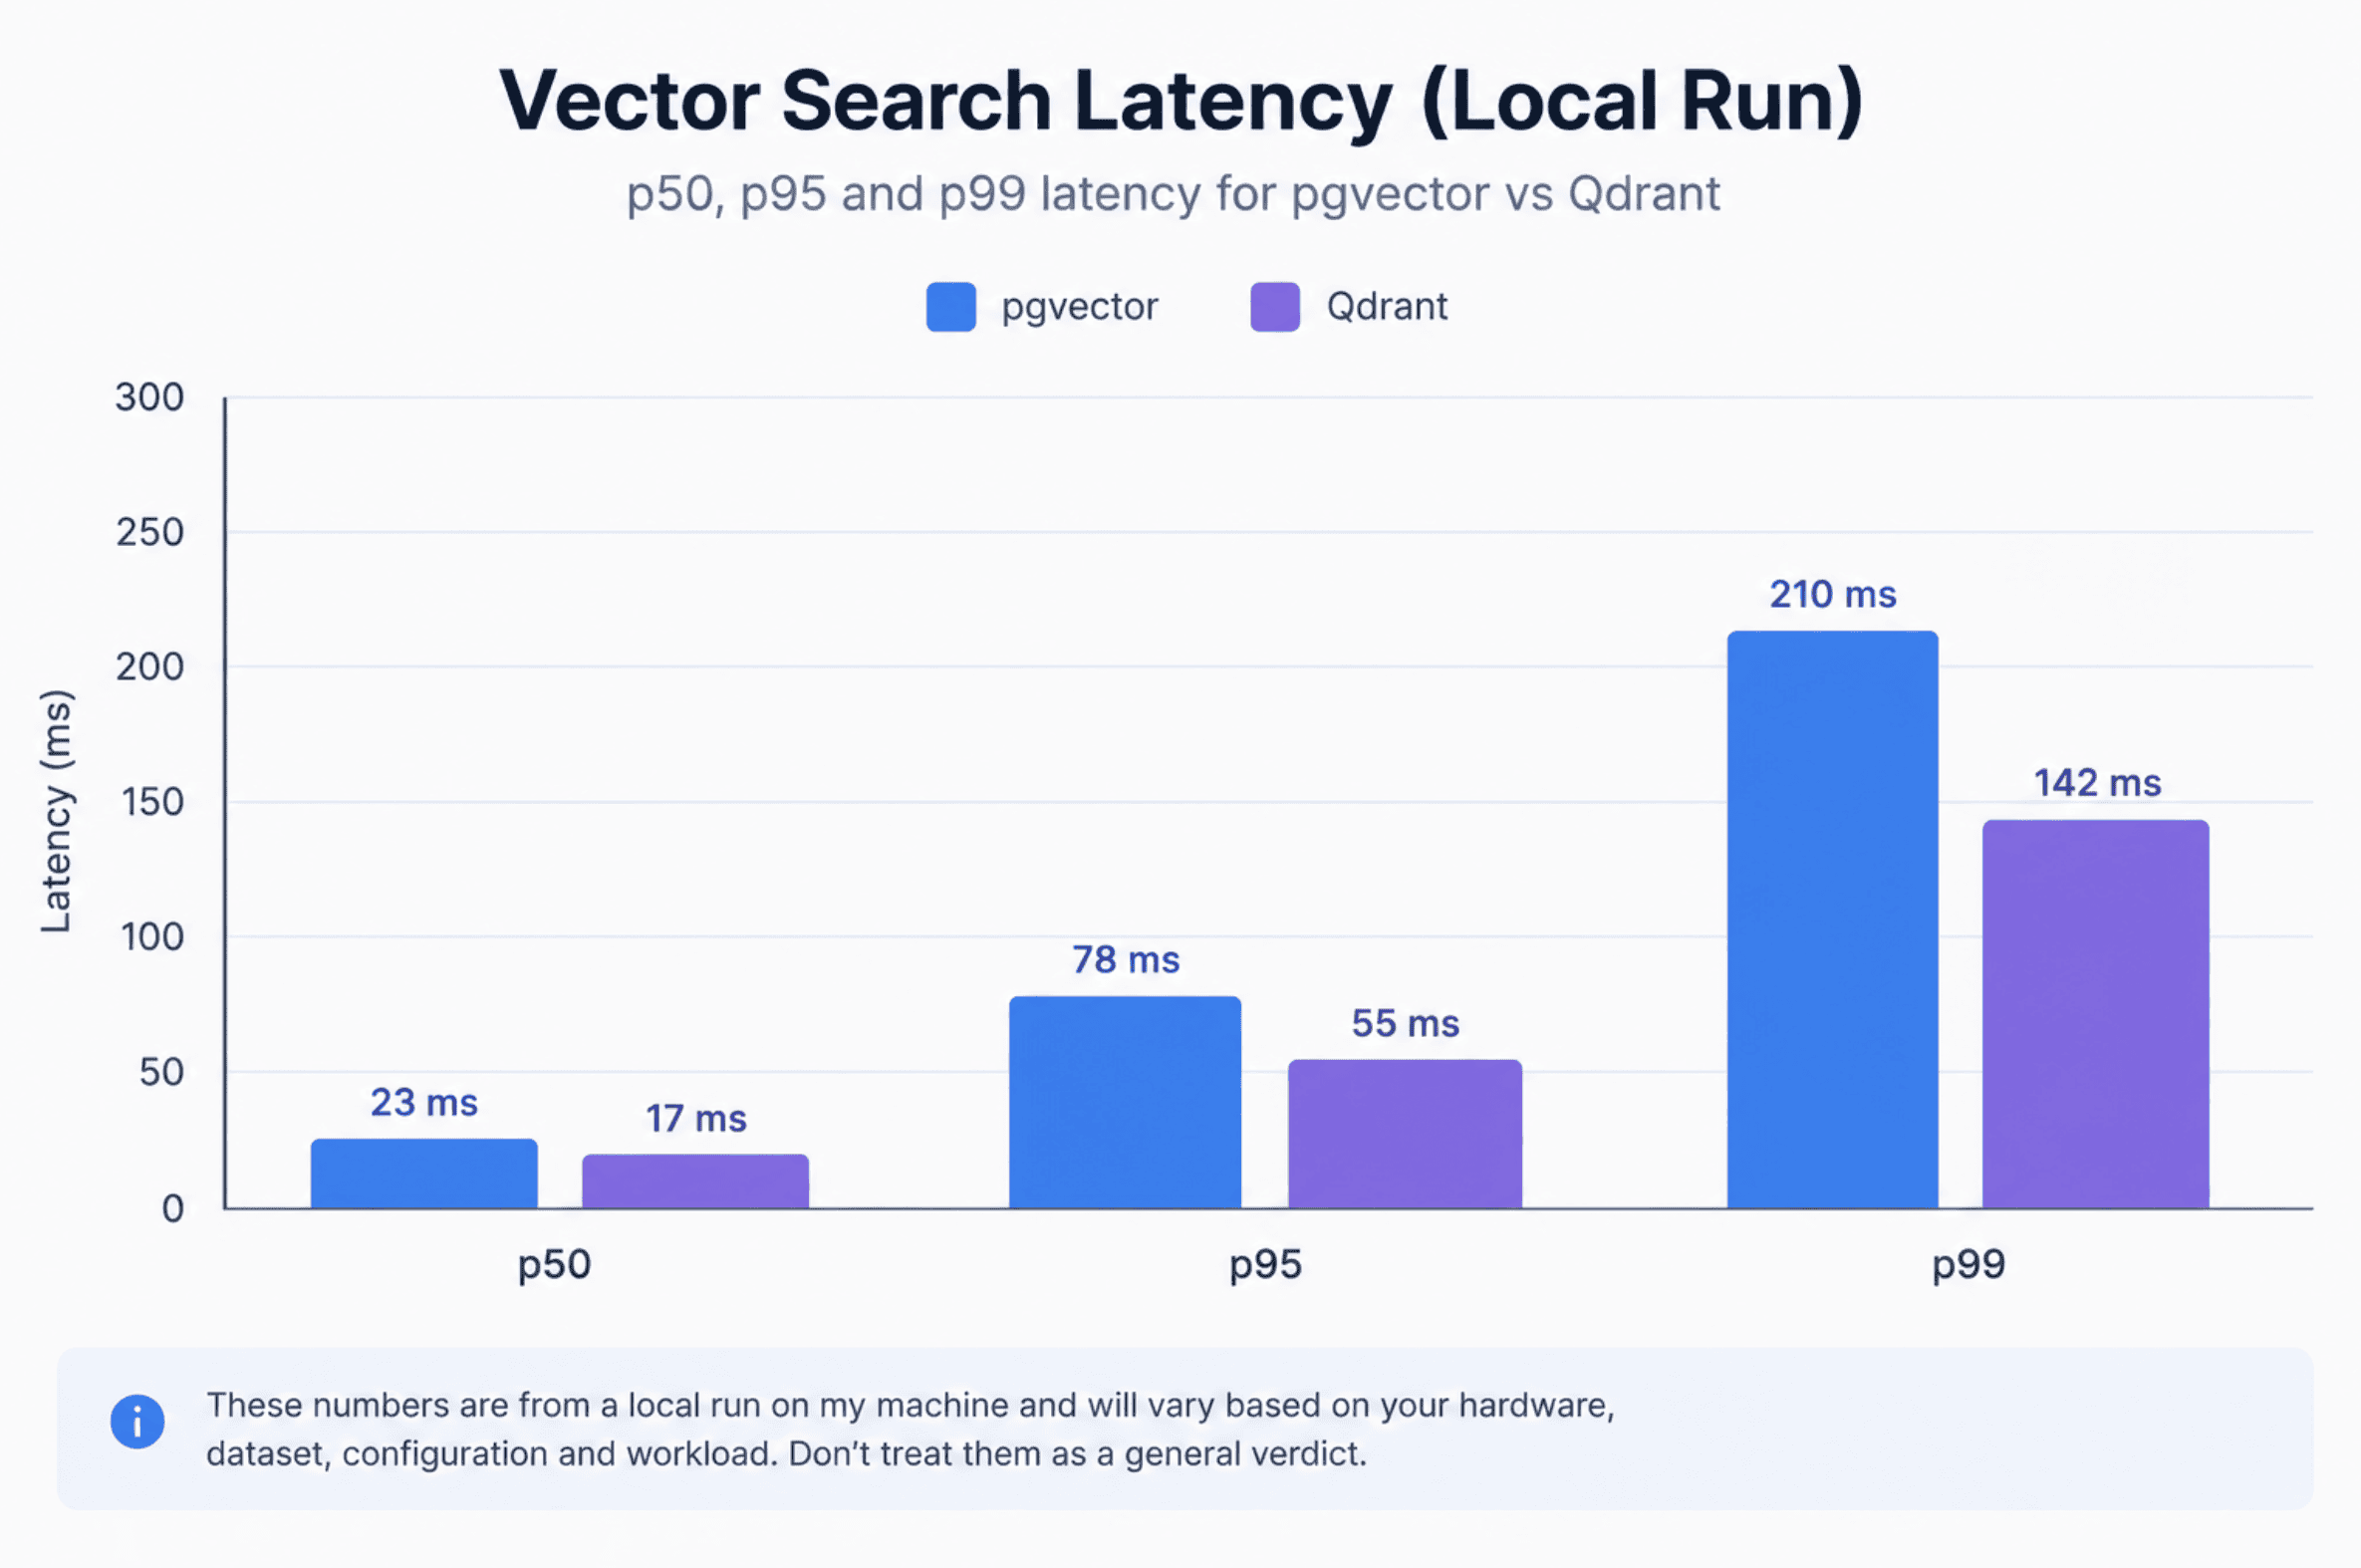
A easy bar chart mockup exhibiting p50, p95, and p99 latency for pgvector and Qdrant (click on to enlarge)
What the Native Outcomes Truly Present
Run this on a typical laptop computer and each methods will report latencies within the low single-digit to tens of milliseconds vary, with the precise numbers relying closely in your CPU, out there RAM, and no matter else is working in your machine on the time. That variability is the trustworthy level of this part: 100,000 vectors on a laptop computer is a high quality approach to be taught the mechanics of each methods and ensure your setup works appropriately, nevertheless it’s genuinely too small a scale to attract an actual manufacturing conclusion from. Each methods are quick sufficient at this measurement that the distinction between them barely issues but. The actual query — which one holds up as knowledge and question load truly develop — wants numbers gathered at actual manufacturing scale, not a laptop computer benchmark.
How This Holds at Manufacturing Scale
That is the place Tiger Knowledge’s printed benchmark turns into genuinely helpful, because it’s probably the most detailed, methodology-transparent public comparability out there. They examined 50 million actual Cohere embeddings at 768 dimensions, on matched AWS r6id.4xlarge {hardware} (16 vCPUs, 128GB RAM) for each methods, utilizing a modified fork of the industry-standard ANN-Benchmarks instrument.
One essential accuracy be aware earlier than the numbers: this particular benchmark used Postgres with pgvector plus pgvectorscale — Timescale’s personal extra extension that provides a unique index sort known as StreamingDiskANN — not vanilla pgvector alone. That distinction will get blurred in a number of secondary protection of this benchmark, and it issues, because the numbers under replicate that mixed setup.
| Metric | pgvector + pgvectorscale | Qdrant |
|---|---|---|
| p50 latency @ 99% recall | 31.07 ms | 30.75 ms |
| p95 latency @ 99% recall | 60.42 ms | 36.73 ms |
| p99 latency @ 99% recall | 74.60 ms | 38.71 ms |
| Throughput @ 99% recall | 471.57 QPS | 41.47 QPS |
| p50 latency @ 90% recall | 9.54 ms | 4.74 ms |
| Throughput @ 90% recall | 1,589.79 QPS | 360.81 QPS |
| Index construct time (50M vectors) | 11.1 hours | 3.3 hours |
The sample that emerges is genuinely two-sided, not a clear win for both system. At 99% recall, Postgres with pgvectorscale delivered 11.4 occasions the question throughput of Qdrant — 471.57 QPS towards 41.47. Qdrant, in flip, held an actual, measurable benefit on tail latency: 48% higher p99 (38.71ms vs. 74.60ms), which means its slowest queries stayed noticeably sooner though its general capability was decrease. Qdrant additionally constructed its index roughly 3.4 occasions sooner. Each methods saved each measured percentile underneath 100 milliseconds at 99% recall on a 50-million-vector dataset, which is itself price sitting with — because it immediately undercuts the idea {that a} general-purpose database can’t sustain at actual scale.
When pgvector Is Good Sufficient
Scale underneath roughly 5 to 10 million vectors is comfortably inside pgvector’s vary on cheap {hardware}. A real want for transactional consistency between your relational knowledge and its embeddings — updating a doc and its vector in the identical atomic transaction — is an actual structural benefit pgvector has {that a} separate database merely can’t supply. An present Postgres funding, a workforce that already is aware of the way to function, monitor, and again it up, means including vector search prices an extension and an index, not a brand new system. And average question concurrency, relatively than hundreds of simultaneous queries per second, retains you effectively inside what a single well-tuned Postgres occasion handles comfortably.
When to Attain for a Devoted Vector Database
The opposite facet of the road is equally concrete. Genuinely large scale — a whole bunch of hundreds of thousands to billions of vectors — is the place purpose-built distributed architectures earn their operational price. A tough tail-latency SLA underneath heavy concurrent filtered search, the sort of requirement the place a p99 above 25 to 40 milliseconds is an actual drawback, favors Qdrant’s demonstrated tail-latency benefit particularly. GPU-accelerated indexing wants level towards Milvus, the one system on the record constructed round that from the bottom up. And a real organizational desire for zero-operations managed infrastructure — no database experience on the workforce, no urge for food for working and tuning something — is strictly what a totally managed service like Pinecone exists to take away out of your plate completely.
Conclusion
The benchmark knowledge on this article doesn’t help both of the clear tales individuals have a tendency to achieve for — “pgvector is all the time high quality” or “devoted databases all the time win.” It reveals two methods with genuinely totally different tradeoffs measured underneath matched, clear situations: one wins decisively on throughput, the opposite wins decisively on tail latency, and each comfortably clear the bar most actual functions really want. The trustworthy reply to “which one ought to I exploit” was by no means going to be a single identify. It’s whichever facet of that tradeoff your precise workload — not a vendor’s pitch — truly sits on.