
Search brokers powered by massive language fashions (LLMs) are remodeling how enterprises retrieve info. Somewhat than requiring customers to craft the proper question, a search agent autonomously decides what to seek for, which retrieval technique to make use of, and when to cease looking. It does this throughout a number of rounds of interplay, refining its method primarily based on what it has already retrieved.
Nonetheless, getting this multi-step conduct to work nicely is difficult. No base mannequin arrives realizing your instruments or your setting. Immediate a small mannequin and also you hardly ever get reliable multi-turn conduct. Immediate a frontier mannequin and it typically works, however you pay for that functionality in latency and value. Advantageous-tuning provides a 3rd path: you educate a small mannequin your instruments and setting instantly. The result’s a small mannequin’s pace and value with the reliability that might in any other case require a frontier mannequin.
Although fine-tuning is the pure subsequent step, the normal approaches every fall quick. Supervised fine-tuning (SFT) relies on professional demonstrations of excellent multi-turn trajectories, that are pricey to gather and often don’t exist on your setup. Single-turn reinforcement studying (RL), comparable to RL with verifiable rewards (RLVR), scores one response at a time. However a search agent makes interdependent choices throughout many turns, each constructing on the context earlier than it. Optimizing a single step in isolation misses these dependencies solely.
What you want is a coaching method that optimizes the agent throughout the complete multi-turn trajectory. The reward sign solely must replicate whether or not the ultimate final result was good. That’s precisely what multi-turn reinforcement studying (MTRL) gives. It trains the agent to make good choices throughout a full sequence of steps, bakes in your environment-specific conduct, and offers you management over output high quality. Since you run a smaller, specialised mannequin, you additionally get sooner, cheaper inference.
On this put up, we describe how we fine-tuned a search agent utilizing Amazon SageMaker AI multi-turn reinforcement studying (MTRL) and share the outcomes we noticed in retrieval high quality and reliability. We start by explaining what Amazon SageMaker AI MTRL is and the way it works.
What’s Amazon SageMaker AI MTRL?
With Amazon SageMaker AI MTRL, you may fine-tune LLMs utilizing reinforcement studying in multi-turn interplay settings. It frames an agentic activity as a sequence of selections, makes use of multi-turn rollouts to generate coaching information, and optimizes the mannequin with coverage gradient algorithms.
Amazon SageMaker AI MTRL provides:
- Modular agent-environment interface: You retain integration low-code. You outline customized rewards, customized software loops, and multi-turn dialog shapes.
- Serverless execution: You get production-scale agentic RL at per-token pricing with out provisioning or managing GPU clusters.
- Asynchronous rollout and trajectory assortment: You run era and gradient updates in parallel with bounded off-policy staleness, so coaching stays quick with out drifting too removed from the present coverage.
- A local algorithm library: You select from Proximal Coverage Optimization (PPO), Clipped Significance Sampling Coverage Optimization (CISPO), and importance-sampling (IS) losses, paired with group-based benefit estimators (GRPO, GRPO go@okay, RLOO, and extra).
- Resumable coaching: You’ll be able to break up lengthy coaching runs throughout a number of jobs to work past single-job cut-off dates.
- Trajectory and reward observability: You’ll be able to examine what your agent did flip by flip and throughout coaching steps in MLflow managed by Amazon SageMaker AI.
- Analysis jobs: You’ll be able to report reward, go@okay, and trajectory metrics earlier than deploying to an Amazon SageMaker AI endpoint or Amazon Bedrock.
This makes MTRL a pure match for search brokers: you’ve a transparent reward sign (retrieval high quality), a multi-turn interplay loop (the agent issuing queries and receiving outcomes), and a well-defined setting (the search instruments).
Surroundings and setup
Our setup relied on the next:
- An AWS account with entry to Amazon SageMaker AI within the US West (Oregon) AWS Area (us-west-2).
- Coaching and validation datasets uploaded to Amazon Easy Storage Service (Amazon S3) within the required format (see the MTRL documentation for particulars).
- A deployed agent endpoint that exposes BM25 and vector search instruments for the MTRL setting to name throughout rollouts.
- Familiarity with Amazon SageMaker AI and Python.
Answer overview
On this put up, we use Amazon SageMaker AI MTRL to fine-tune a Qwen3.6-27B mannequin (supported within the US West (Oregon) Area (us-west-2)) for a search agent. The search agent is an LLM-powered system that autonomously makes use of search instruments to search out, collect, and synthesize info to reply a query or full a activity.
We give attention to an enterprise search setting the place the agent has two instruments obtainable:
- Lexical search (BM25): Finds actual key phrase matches by counting phrase frequencies. Finest for queries with particular phrases or identifiers.
- Vector search: Converts queries and paperwork into embedding vectors and computes similarities. That is advisable for semantic or conceptual queries.
We additionally restrict the variety of turns (one flip is one spherical of user-assistant interplay), stopping the agent from producing excessively lengthy responses and inspiring environment friendly search conduct.
Coaching setup
This part walks by the three key parts of our coaching setup: the datasets, the reward operate, and the MTRL job configuration.
Datasets
We use the next datasets for coaching and testing:
| Dataset | Practice/Take a look at | Public Hyperlink | Description |
| FRAMES | Practice | HuggingFace | Multi-hop factoid QA requiring synthesis throughout a number of Wikipedia articles. |
| BRIGHT | Practice | HuggingFace | Reasoning-intensive retrieval throughout 12 domains, the place relevance wants reasoning, not key phrase overlap. |
| Enterprise RAG | Practice | GitHub | A benchmark of over 500,000 artificial enterprise paperwork and 500 questions for coaching and evaluating RAG methods on inner firm information |
| ESCI | Practice | GitHub | A multilingual product-search dataset labeling question–product pairs as Precise, Substitute, Complement, or Irrelevant |
| Musique | Practice | GitHub | A matter-answering dataset constructed by composing single-hop questions into difficult multi-hop reasoning issues. |
| MLQA | Practice | HuggingFace | A parallel extractive question-answering benchmark masking seven languages for evaluating cross-lingual comprehension. |
| FreshStack | Take a look at | HuggingFace | Latest developer-tech Q&A over Stack Overflow + docs for 5 subjects. |
| WixQA | Take a look at | HuggingFace | Assist-center assist QA over the Wix information base. |
| BrowseComp-Plus | Take a look at | GitHub | Exhausting deep-research queries over ~100K human-verified open-web paperwork. |
| Wands | Take a look at | HuggingFace | A Wayfair product-search dataset containing over 42,000 question–product relevance judgments labeled as Precise, Partial, or Irrelevant. |
We preprocess the datasets into the format acknowledged by the MTRL service in keeping with the documentation. We additional reserve 5 p.c of the coaching situations inside every dataset as validation situations.
Reward operate
Our fundamental metric is nDCG@10 (Normalized Discounted Cumulative Acquire at rank 10). nDCG@10 is a normal info retrieval metric that measures how nicely the highest 10 retrieved paperwork match the best rating. It rewards methods that place extremely related paperwork close to the highest of the listing, with a rating of 1.0 that means excellent rating and 0.0 that means no related paperwork retrieved. We use nDCG@10 instantly because the reward operate in MTRL. It is a trajectory-level reward the place the agent completes its full multi-turn search, and the reward displays how nicely the ultimate retrieved paperwork match the bottom fact.
When the agent reaches the utmost variety of turns or the utmost sampling tokens in a single flip, we assign a reward of -1 to explicitly educate the mannequin to keep away from these failure modes. This sort of penalty-based reward design is efficient at steering the mannequin away from undesirable conduct without having to hand-craft complicated intermediate rewards.
MTRL job configuration
One of many appeals of Amazon SageMaker AI MTRL is how little it’s essential configure to get going. We modify three hyperparameters and go away every thing else on the default values. The next code snippet reveals easy methods to configure and launch the coaching job utilizing the MultiTurnRLTrainer SDK:
The important thing hyperparameters we modify are:
- max_epochs: 1 controls what number of full passes over the coaching information.
- global_batch_size: 128 units the variety of prompts per coaching step.
- rollout_max_concurrency: 32 controls what number of rollouts run in parallel throughout trajectory assortment.
That’s the entire setup. The alternatives that often demand RL experience, the algorithm, the benefit estimator, the off-policy staleness bounds, all run on defaults. Getting from the bottom mannequin to the ends in the subsequent part required nothing greater than the previous configuration.
Outcomes
MTRL fine-tuning improved the search agent on three of 4 held-out benchmarks and made it considerably extra dependable throughout all of them. The most important beneficial properties got here on BrowseComp-Plus (+23.7 p.c nDCG@10) and WixQA (+18.4 p.c), with a smaller acquire on Wands and a slight regression on FreshStack. The reliability enchancment was the extra hanging outcome. On BrowseComp-Plus, the failure price fell from 22.89 p.c to 0.68 p.c. This implies the agent discovered not solely to go looking higher but in addition to complete the duty inside its flip and token funds. The sections that comply with stroll by the coaching curves and the per-benchmark numbers.
Coaching progress
The next determine reveals the reward (nDCG@10) on each coaching and validation situations over the course of coaching. The x-axis represents coaching steps and the y-axis reveals the nDCG@10 rating. Two strains observe coaching and validation reward, each rising steadily earlier than plateauing. MTRL coaching can span a number of days and the MTRL service has a default time restrict of 24 hours, which is adjustable by the CreateJob JSON schema. If a job is stopped or has failed due to timeout or infrastructure error, you may proceed coaching from a earlier checkpoint with resume assist.
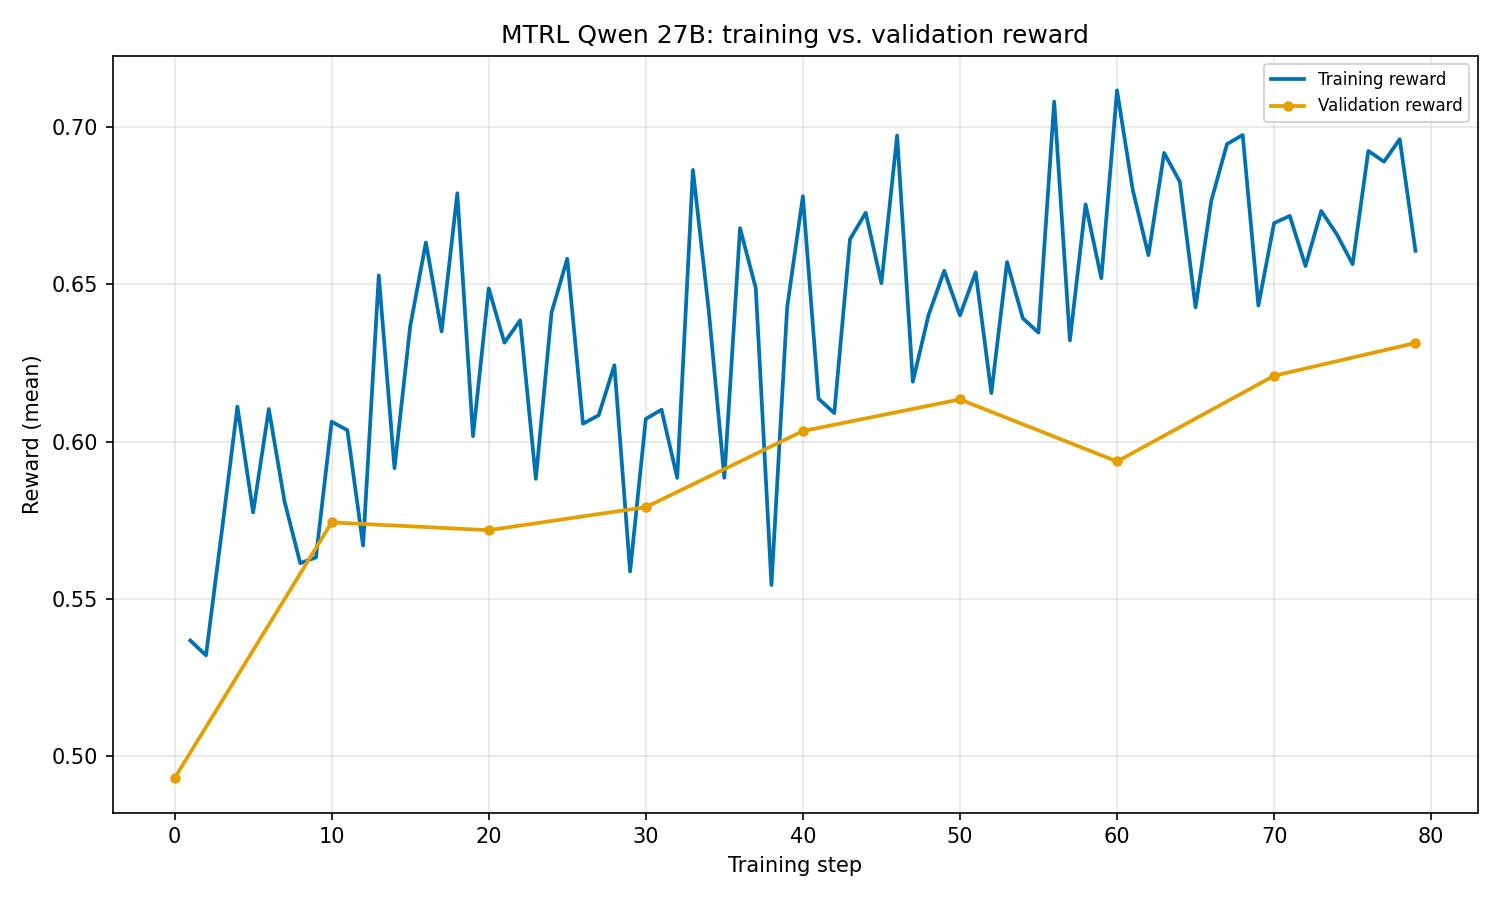
Determine 1: nDCG@10 reward on the coaching and validation units over the course of coaching
The determine plots nDCG@10 towards coaching steps for each coaching and validation units. Each curves enhance steadily as fine-tuning progresses and saturate by the tip of coaching, suggesting additional coaching wouldn’t be useful.
Take a look at efficiency
The next desk compares the fine-tuned mannequin towards the unique Qwen3.6-27B on 4 held-out take a look at datasets. All metrics within the desk are computed from our analysis runs on the datasets listed within the previous part.
Column definitions:
- Dimension is the variety of questions within the dataset.
- nDCG@10 is the usual Normalized Discounted Cumulative Acquire. The failed duties are assigned nDCG@10 of 0.
- Failure price is the share of questions the place the agent hits an error (for instance, exceeding the flip restrict or token funds).
- Turns (avg) is the typical variety of turns per query.
| benchmark | measurement | mannequin | ndcg@10 | fail_rate | turns |
| WixQA | 400 | Qwen3.6-27B | 0.5725 | 0.67% | 4.3 |
| WixQA | 400 | Qwen3.6-27B-finetune | 0.6781 | 0.17% | 4.5 |
| Wands | 147 | Qwen3.6-27B | 0.5762 | 0.00% | 2.2 |
| Wands | 147 | Qwen3.6-27B-finetune | 0.6112 | 0.00% | 2.9 |
| FreshStack | 672 | Qwen3.6-27B | 0.4112 | 0.20% | 3.1 |
| FreshStack | 672 | Qwen3.6-27B-finetune | 0.4089 | 0.05% | 2.8 |
| BrowseComp-Plus | 830 | Qwen3.6-27B | 0.5136 | 22.89% | 7.0 |
| BrowseComp-Plus | 830 | Qwen3.6-27B-finetune | 0.6354 | 0.68% | 6.3 |
The outcomes present that RL fine-tuning made a significant distinction:
- Higher search high quality: As proven within the previous desk, nDCG@10 improved on WixQA (from 0.5725 to 0.6781, a +18.4 p.c acquire), on Wands (from 0.5762 to 0.6112, a +6 p.c), and on BrowseComp-Plus (from 0.5136 to 0.6354, a +23.7 p.c acquire). The rating decreased barely on FreshStack.
- Fewer failures: Assigning a reward of -1 for failure instances was extremely efficient. On BrowseComp-Plus, the failure price dropped from 22.89 p.c to solely 0.68 p.c.
Clear up
For those who do discover this method, bear in mind to scrub up the sources afterward to keep away from ongoing costs:
- Cease or delete the MTRL coaching job within the Amazon SageMaker AI console if it’s nonetheless operating.
- Delete the mannequin artifacts in Amazon S3 in the event that they’re not wanted.
- Delete any deployed endpoints that had been created for analysis.
Conclusion
On this put up, we described our expertise utilizing Amazon SageMaker AI MTRL to fine-tune an LLM-powered search agent with reinforcement studying. With minimal configuration, the fine-tuned mannequin confirmed substantial enhancements in retrieval high quality, failure price, and switch effectivity (fewer turns per query).
Key takeaways from our expertise with Amazon SageMaker AI MTRL:
- Low barrier to entry: Default configurations work nicely, and no deep RL experience is required to get began.
- Serverless infrastructure: No have to provision GPUs or handle distributed coaching clusters. You pay per-token.
- Resumable coaching: Lengthy coaching runs may be break up throughout a number of jobs.
- Direct optimization: You practice towards your precise activity metric slightly than proxy losses.
- Full observability: You’ll be able to examine trajectories flip by flip in MLflow managed by Amazon SageMaker AI to know what the agent discovered.
Subsequent steps
If you wish to apply this method to your individual brokers, listed here are some helpful beginning factors:
- Seek the advice of the Amazon SageMaker AI MTRL documentation.
- Put together your dataset within the required format.
- Put together your agent and outline your reward operate primarily based in your task-specific metric.
- Begin with default configurations, which labored nicely in our expertise.
- Consider and iterate.
In regards to the authors