
ArisGlobal, a supplier of life sciences expertise spanning pharmacovigilance, regulatory, medical affairs, medical, and high quality features, developed NavaX, an AI engine purpose-built for all times sciences on Amazon Bedrock, to automate adverse-event case processing. ArisGlobal selected Amazon Bedrock for managed entry to basis fashions, EU geographic cross-Area inference, and managed immediate caching. As enterprise clients added distinct compliance necessities, the shared immediate prefix grew by about 150% over 6 months, whereas per-case inference prices elevated by greater than 200%.
ArisGlobal first cached every supply doc as a result of it was the most important a part of a request. That left the rising shared immediate prefix exterior the cache. By reversing the order and caching the shared prefix as a substitute, ArisGlobal decreased efficient enter price and supported extra tenants with out proportional price development.
Who’s ArisGlobal?
ArisGlobal is the creator of LifeSphere, a unified SaaS platform for pharmacovigilance, regulatory affairs, high quality, and medical data. LifeSphere serves pharmaceutical corporations globally, together with a number of Prime 20 pharma organizations by income (supply: ArisGlobal press launch). The complete system runs on AWS.
LifeSphere NavaX is ArisGlobal’s AI engine that transforms drug security from a system of document right into a system of strategic benefit. ArisGlobal productionized their first generative AI resolution on Amazon Bedrock with Anthropic’s Claude in March 2025. Based on ArisGlobal’s inner manufacturing telemetry, they’ve processed over 1 million actual transactions in regulated pharmaceutical environments, dealing with billions of tokens throughout a number of enterprise tenants. Mannequin availability varies by Area. See Mannequin help by AWS Area.
How NavaX processes an adversarial occasion case
When a pharmaceutical firm receives an adverse-event report, usually a multipage PDF describing a affected person’s response to a medicine, NavaX’s Dynamic Knowledge Extraction (DDE) agent extracts round 130 fields. These fields embody affected person demographics, suspect medication, reporter data, occasion timelines, seriousness standards, and regulatory classifications. As a result of this content material contains protected well being data, ArisGlobal applies responsible-AI controls as a typical a part of its manufacturing deployment. It attracts on capabilities akin to Amazon Bedrock Guardrails to filter content material and detect or masks delicate data. Extracted fields are additionally validated towards the schema and grounded within the supply doc.
This extraction occurs throughout a number of sequential requests to the mannequin. Every request focuses on a special part of the case kind, and every carries:
- System directions — mannequin habits guidelines, output format specs, and regulatory compliance constraints.
- Buyer-specific guidelines — per-tenant extraction logic, discipline mappings, and enterprise guidelines that differ by pharmaceutical firm.
- Extraction schema — round 130 goal fields with varieties, validation guidelines, and few-shot examples.
- The supply doc — the adversarial occasion PDF (typically 10–200 pages).
Two inputs repeat at totally different scopes. The shared immediate prefix contains the system guidelines, extraction schema, and few-shot examples. It repeats throughout requests, circumstances, and tenants utilizing the identical agent. The supply doc repeats just for the requests related to one case.
The immediate bloat drawback
When NavaX launched with its first enterprise tenant, the system immediate was lean. As ArisGlobal onboarded extra pharmaceutical corporations, every introduced particular necessities:
- Customized discipline mappings (Tenant A maps response onset otherwise from Tenant B).
- Regulatory jurisdiction guidelines (EU ICSR in contrast with FDA MedWatch and PMDA formatting).
- Firm-specific enterprise logic for seriousness evaluation and causality.
- Per-tenant few-shot examples calibrated to every firm’s historic circumstances.
Over 6 months, the shared immediate prefix grew from roughly 72,000 to 180,000 tokens, a 150% enhance. With a number of sequential requests per case, per-case inference prices elevated by greater than 200%.
The prefix grew with each tenant and was reprocessed on each request, so immediate development compounded with transaction quantity.
Desk 1 compares the unique document-first request order with the manufacturing prompt-first design.
| Facet | First method | Manufacturing design |
| Request order | Per-case doc, cache checkpoint, shared immediate prefix | Shared immediate prefix, cache checkpoint, per-case doc |
| Cached prefix | The doc, which adjustments for each case | The shared immediate prefix, which repeats throughout requests |
| Reuse scope | Solely the remaining requests for one case | Requests throughout circumstances and tenants utilizing the identical agent |
| Price impact | The rising immediate is repeatedly processed on the full enter charge | Fleet-wide immediate reuse helps sublinear price development |
| EU routing | EU geographic cross-Area inference stays unchanged | EU geographic cross-Area inference stays unchanged |
Amazon Bedrock immediate caching methods
Amazon Bedrock immediate caching reduces latency and enter token prices by caching a contiguous immediate prefix from the beginning of a request by a cache checkpoint. A later request with the identical prefix can learn cached tokens at a decreased charge as a substitute of processing them once more. Cache entries have a time-to-live (TTL) that resets after a profitable cache hit.
Caching is prefix-based slightly than block-based. Request sections are evaluated in sequence—instruments, system, then messages—so altering an earlier part invalidates matching content material that follows it.
Cache checkpoints (specific management)
With specific cache checkpoints, you may select the precise prefix boundary. Supported Claude fashions enable as much as 4 checkpoints per request.
- Place every checkpoint after a steady, reusable prefix.
- Meet the model-specific minimal prefix measurement. For Claude Sonnet 4.5 the minimal is 1,024 tokens (see supported fashions and Areas).
- Checkpoints are evaluated on this order: instruments, system, and messages.
- Altering an earlier part invalidates cache matches for later sections.
- The default TTL is 5 minutes. Choose fashions help a 1-hour TTL by setting
"ttl": "1h". Longer-TTL entries should precede shorter-TTL entries.
Simplified cache administration (automated)
With simplified cache administration, you place one checkpoint after static content material. Amazon Bedrock searches backward from that time for the longest matching prefix, as much as about 20 content material blocks.
- One checkpoint can find the longest matching prefix routinely.
- Use specific checkpoints when steady content material extends past the lookback vary.
What ArisGlobal cached, and what they intentionally didn’t
ArisGlobal makes use of one specific checkpoint instantly after the shared immediate prefix, which is distributed first. The per-case doc follows the checkpoint and is processed on every request.
This reverses the preliminary request order. As a result of solely a prefix might be cached, ordering determines which content material might be reused.
The launch design: Prioritizing doc reuse
The primary design put the ten–200 web page supply doc initially of every request and positioned the checkpoint after it. The shared immediate prefix and section-specific query adopted the checkpoint.
The design reused the doc inside one case: the primary request wrote it to cache, and later requests for that case learn it on the decreased charge.
The following case used a special doc and required a brand new cache write, so reuse by no means prolonged throughout circumstances or tenants.
Extra importantly, the shared immediate prefix remained after the checkpoint and was processed on the full enter charge on each request. The content material driving the associated fee curve was excluded from the cache.
The advanced manufacturing design: Prioritizing shared-prefix reuse
The manufacturing design modified the order slightly than including one other checkpoint: the shared immediate prefix comes first, the checkpoint follows it, and the doc comes final.
The identical checkpoint now creates a reusable fleet-wide cache entry:
- Earlier than — the cached doc prefix was distinctive to 1 case and the shared immediate was by no means cached.
- After — the cached shared immediate prefix repeats throughout requests, circumstances, and tenants utilizing the identical agent.
ArisGlobal gave up restricted doc reuse inside one case and gained immediate reuse throughout the fleet. The shared prefix can be the half that grows as clients are added.
Up to date implementation
For many energetic accounts, circumstances arrive about each 5 minutes per tenant and a number of tenants run concurrently. This site visitors retains the shared prefix heat throughout enterprise hours as a result of every cache hit resets the TTL.
Caching each the immediate and the doc
A second checkpoint after the doc would cache a mixed prefix consisting of the shared immediate and that case’s doc. The entry would nonetheless be distinctive to 1 case.
ArisGlobal due to this fact prioritized the prefix whose reads amortize throughout the fleet. The shared immediate prefix scales throughout circumstances and tenants. The per-case doc doesn’t.
In manufacturing, 65% of enter tokens on a typical request are served from the shared immediate cache. Determine 1 reveals cache reads constantly exceeding cache writes.
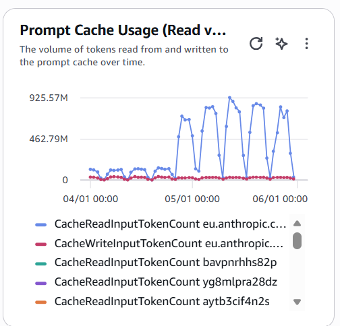
Determine 1: Amazon CloudWatch prompt-cache utilization. The blue cache-read sequence rises to roughly 10 instances the cache-write sequence in periods of manufacturing site visitors
Outcomes
Caching the shared immediate prefix produced the next outcomes whereas the EU geographic cross-Area inference profile remained in place:
- 65% of enter tokens served from cache on the decreased learn charge.
- As much as 25% decrease end-to-end latency on cached manufacturing requests.
- Roughly 50% decrease efficient enter price.
- Roughly 40% decrease total month-to-month inference spend at greater than 19 billion tokens monthly.
- Round 15% extra enterprise tenants onboarded with out proportional price will increase.
- EU geographic routing unchanged. Immediate caching operates inside the present inference configuration.
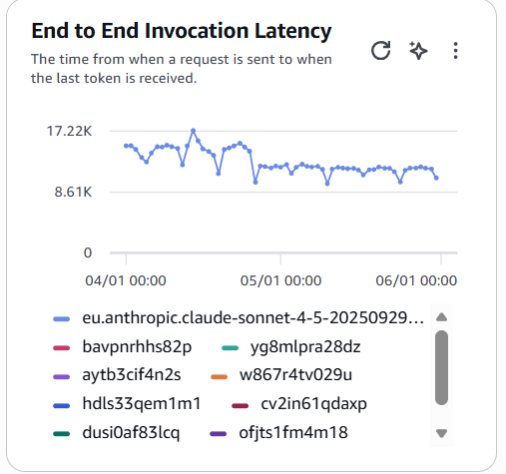
Determine 2: Finish-to-end invocation latency. The chart reveals a decrease and extra steady latency vary after prompt-cache adoption
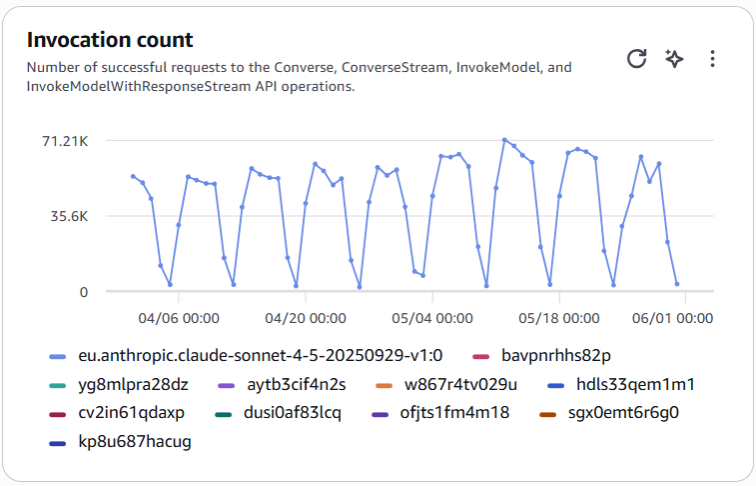
Determine 3: Invocation rely. The chart reveals sustained manufacturing request quantity whereas inference spend grew lower than proportionally
Based mostly on ArisGlobal’s manufacturing billing knowledge, serving 65% of enter tokens from cache decreased efficient enter price by roughly 50%. At greater than 19 billion tokens monthly, this produced roughly 40% total month-to-month financial savings in inference spend.
Notice: All efficiency and price figures on this part replicate ArisGlobal’s manufacturing metrics as reported to AWS. Outcomes will differ based mostly on immediate construction, site visitors patterns, and cache hit charges.
Manufacturing learnings
ArisGlobal’s expertise presents steerage for a lot of workloads with massive, repeated immediate prefixes:
Cache what repeats, not what’s largest. A big per-case doc presents restricted reuse, whereas a byte-identical shared immediate prefix can serve requests throughout the fleet.
Put steady content material first. Order instrument definitions, system directions, schemas, and examples earlier than the checkpoint. Place tenant identifiers, case knowledge, and the per-request query afterward.
Use fleet site visitors to amortize cache writes. Requests from tenants utilizing the identical agent can learn the identical prefix, and cache hits reset the TTL. For sporadic site visitors, consider the 1-hour TTL on supported fashions.
Scale back avoidable calls. Every name nonetheless processes the uncached doc, so bundle sequential questions when output limits and schema necessities allow.
Maintain the prefix byte-identical. Timestamps, request IDs, tenant names, and reordered instrument definitions may cause misses. Transfer each dynamic aspect after the checkpoint.
Monitor the manufacturing baseline. Monitor cache reads, cache writes, and complete enter tokens in CloudWatch. Alert on a sustained drop beneath the traditional 65% cache-hit baseline slightly than utilizing an incompatible 80% threshold.
Verify model-specific limits. Prefix minimums and TTL choices differ by mannequin. Claude Sonnet 4.5 requires at the least 1,024 tokens for a cache checkpoint.
Conclusion
ArisGlobal mixed EU geographic cross-Area inference with immediate caching aimed on the proper content material. Caching the steady shared prefix as a substitute of the per-case doc decreased efficient enter price by roughly 50%, contributed to roughly 40% total month-to-month inference financial savings, and supported round 15% extra enterprise tenants with out proportional price will increase.
The important thing lesson is that cache worth depends upon reuse, not measurement. For multi-tenant agentic workloads, a repeated shared immediate prefix might be extra beneficial than a bigger doc that adjustments for each case.
To be taught extra, see the Amazon Bedrock immediate caching documentation, the cross-Area inference information, and the AWS weblog put up Successfully use immediate caching on Amazon Bedrock.
Concerning the authors