
Fleet-wide laptop imaginative and prescient mannequin lifecycle administration is an issue that reveals up the second a top quality inspection proof of idea succeeds. One digicam and one mannequin work positive. Then the plant asks for a similar consequence on 40 traces, every with a number of cameras, and each digicam sees the world in a different way. Every has a unique angle, completely different glare off the identical stainless floor, and completely different ambient gentle relying on which bay door is open. In manufacturing deployments we have now labored on, a single mannequin educated on pooled footage underperforms sufficient particular person cameras that every digicam finally ends up with its personal fine-tuned mannequin. Now the actual downside is not coaching one mannequin effectively. It’s coaching, evaluating, versioning, and delivery hundreds of them with no human within the loop for each.
This publish updates the sample launched within the 2023 sequence Construct an end-to-end MLOps pipeline for visible high quality inspection on the edge for the present Amazon SageMaker Python SDK v3. It replaces the since-deprecated Amazon SageMaker Edge Supervisor with Amazon SageMaker Neo for edge optimization. I stroll by a dual-branch Amazon SageMaker Pipeline that trains an anomaly detector and a defect classifier per digicam, with high quality gates that block underperforming fashions. An in-pipeline SageMaker Neo compilation step ensures each registered mannequin ships with a device-optimized artifact, and an AWS Step Features orchestration layer paces fleet coaching. You deploy every thing with the AWS Cloud Improvement Equipment (AWS CDK), and a full pipeline run on artificial information prices about $0.07 in compute.
The entire pattern is offered within the aws-samples GitHub repository.
Answer overview
The next diagram reveals the pattern’s fleet-wide mannequin lifecycle. An orchestration layer queues re-training requests and limits concurrent work. A per-camera coaching pipeline prepares information, trains and evaluates an anomaly detector and a classifier, and produces versioned mannequin artifacts for edge units.
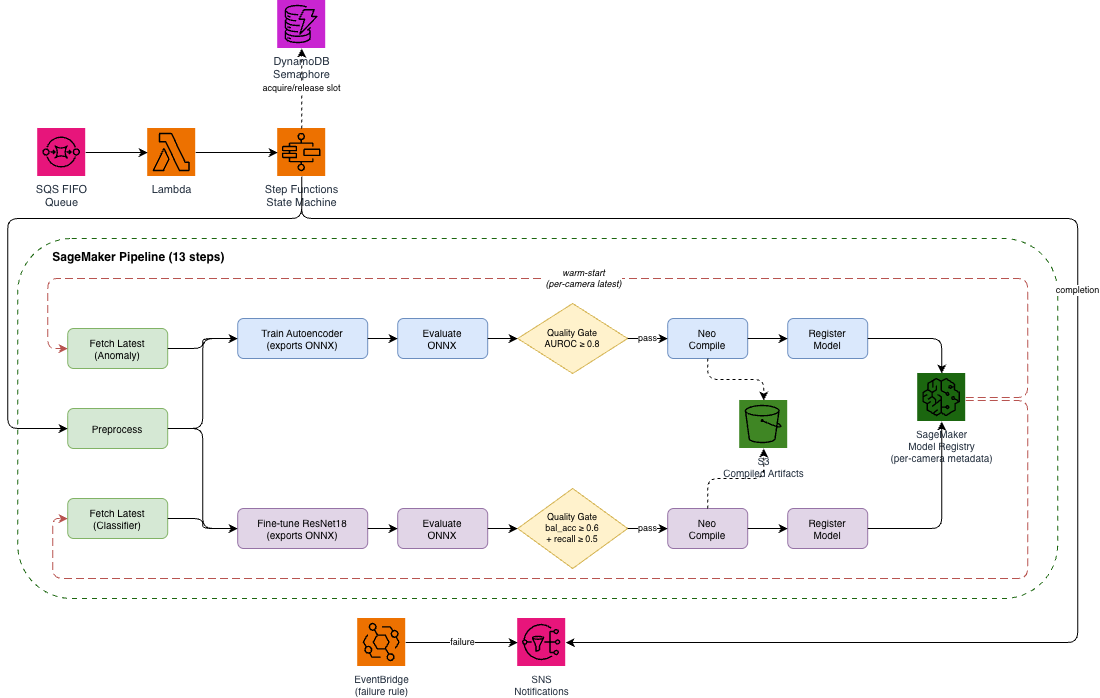
Determine 1: Answer structure
The coaching half is a single SageMaker Pipeline, parameterized by digicam, that runs 13 steps per execution. Three entry steps run in parallel: Preprocess, Fetch Newest Anomaly, and Fetch Newest Classifier. The pipeline preprocesses that digicam’s pictures and fetches the digicam’s most up-to-date authorized mannequin for every department, then trains two fashions. The primary is a small convolutional autoencoder that learns what regular product seems to be like and flags anomalies by reconstruction error. The second is a ResNet18 classifier fine-tuned to verify the defect. Every department exports its mannequin to ONNX, evaluates the exported artifact in opposition to held-out information, and passes by a top quality gate. Previous the gate, the mannequin is compiled with SageMaker Neo for the configured edge goal, and solely then registered within the SageMaker Mannequin Registry. Consequently, each authorized bundle has a device-ready compiled artifact. Packages carry the digicam ID as metadata, and every department’s warm-start fetch filters on it, so re-training at all times resumes from that digicam’s personal historical past.
The orchestration half paces the fleet. Re-training requests land on an Amazon Easy Queue Service (Amazon SQS) FIFO queue, and an AWS Lambda perform begins a Step Features execution per request. Every execution acquires a slot by a DynamoDB semaphore earlier than beginning its pipeline, so a burst of requests drains at a gradual charge as an alternative of all launching without delay. Completions publish to Amazon Easy Notification Service (Amazon SNS), and operational failures attain the identical matter by an Amazon EventBridge rule with the unique error preserved.
The output of the system is versioned, quality-gated, per-camera mannequin artifacts. The Mannequin Registry holds the transportable ONNX, and S3 holds the Neo-compiled construct of that mannequin, which is a device-optimized shared library loaded by the DLR runtime slightly than ONNX. Each are prepared for no matter supply mechanism your plant makes use of.
Conditions
To deploy the pattern you want the next:
- An AWS account with permissions to create AWS Identification and Entry Administration (IAM) roles.
- An Amazon Easy Storage Service (Amazon S3) bucket.
- An Amazon Elastic Container Registry (Amazon ECR) repository.
- The SageMaker AI, AWS Step Features, AWS Lambda, Amazon Easy Queue Service (Amazon SQS), Amazon Easy Notification Service (Amazon SNS), Amazon EventBridge, and Amazon DynamoDB sources within the stacks.
- Python 3.10, 3.11, or 3.12, Docker.
- The AWS CDK CLI model 2.1131.0 or later.
Earlier CLI variations fail with a cloud meeting schema mismatch in opposition to current variations of aws-cdk-lib. No service quota improve is required. The orchestration layer admits at most 5 pipeline executions at a time by default, which retains concurrent SageMaker coaching jobs inside the usual account quota.
In case you deploy to an AWS Area aside from your CLI default, set all three of AWS_REGION, AWS_DEFAULT_REGION, and CDK_DEFAULT_REGION on the deploy command itself slightly than in your shell profile, for instance, AWS_REGION=us-east-2 AWS_DEFAULT_REGION=us-east-2 CDK_DEFAULT_REGION=us-east-2 cdk deploy --all. The CDK CLI, Boto3, and the AWS Command Line Interface (AWS CLI) resolve the Area from overlapping however not equivalent variable units, and a mismatch produces complicated partial deployments. Prefixing the command units all three for that invocation solely, so your individual default Area is left unchanged.
Defining the coaching pipeline with SDK v3
The code on this part is excerpted from the CDK utility within the repository slightly than a standalone script, and it runs throughout cdk deploy, when the stack synthesizes the pipeline definition. Setting setup and the deploy instructions come later, beneath Deploying and operating the pattern. SDK v3 reorganized the SageMaker Python SDK into modular packages, and the imports present the brand new form of the library:
Putting in sagemaker>=3.0.0,<4 pulls in sagemaker-core, sagemaker-train, sagemaker-serve, and sagemaker-mlops as separate packages. Coaching configuration that v2 unfold throughout Estimator constructor arguments now lives in typed config objects handed to ModelTrainer. That is the anomaly department’s coach, verbatim from the pattern:
anomalib_input_data wires 4 channels (prepare, validation, take a look at, pretrained_model) from upstream step properties, and run_prefix scopes each S3 path to the pipeline execution ID so concurrent fleet runs by no means collide. Each are within the repository.
Two v3 behaviors matter when the pipeline lives inside a CDK utility, and neither seems within the changelog as a breaking change. First, SDK v3 validates the pipeline’s execution function in opposition to reside IAM whereas constructing the pipeline definition. This validation occurs at synthesis time slightly than execution time. A CDK app can’t create the function and the pipeline in a single deployment, as a result of the function doesn’t exist but when the SDK validates it. That is separate from cdk bootstrap, which provisions the CDK toolkit sources as soon as per account and Area and may already be finished in your account. The pattern’s personal two-phase deploy is pushed by a context flag that occurs to share that title. An preliminary go with -c bootstrap=true creates the function, bucket, and ECR repository, and the second go synthesizes the pipeline in opposition to the now-existing function. The function Amazon Useful resource Identify (ARN) embedded within the pipeline definition should even be a concrete string, not an unresolved CDK token.
Second, the v3 function validator simulates ECR pull permissions with no useful resource ARN, so an execution function scoped to a single ECR repository fails validation though it could work at runtime. The pattern’s function carries a broader ECR grant for that reason.
Lastly, one v3 behavior the pattern makes use of: developing the pipeline with PipelineSession(default_bucket=your_bucket) routes SDK-managed uploads, resembling step code, into the pipeline’s personal bucket, so each artifact lives in a single place and the execution function’s permissions cowl a single bucket. (Granting the function entry to the SDK’s default bucket works too. This strategy is tidier.)
High quality gates that match how defect information behaves
Each educated mannequin is evaluated earlier than registration, and the analysis runs in opposition to the exported ONNX artifact slightly than the in-memory PyTorch mannequin. That distinction issues: the artifact you gate is the artifact you ship, so an export downside can by no means slip a damaged mannequin previous a healthy-looking coaching run.
The anomaly department gates on AUROC of at the very least 0.8. The classifier department gates on two metrics without delay, and the selection of metrics is formed by the defining property of defect information: heavy class imbalance. On this pattern roughly 90 p.c of pictures are good, which is practical for a manufacturing line. Towards that distribution, plain accuracy is meaningless, as a result of a mannequin that predicts “good” for each picture scores about 0.9 whereas catching zero defects. Balanced accuracy, the imply of per-class recall, corrects for that, however it has its personal blind spot. A mannequin with excellent recall on good components and solely 20 p.c recall on defects nonetheless scores (1.0 + 0.2) / 2 = 0.6. So the gate requires balanced accuracy of at the very least 0.6 and defect recall of at the very least 0.5, collectively:
A ConditionStep ANDs its circumstances, so each should go. The thresholds are pipeline parameters, adjustable per execution with out redeploying. If a gate fails, a FailStep marks the execution failed and that department’s mannequin by no means reaches the registry (the 2 branches gate independently, so the opposite department’s mannequin should register). The fleet retains serving the earlier authorized mannequin for that digicam.
The coaching code addresses the identical imbalance from the opposite facet. The classifier is a fine-tuned resnet18 with ImageNet weights and a two-class head. At per-camera dataset sizes, fine-tuning pretrained weights is what retains the mannequin from collapsing onto the bulk class. The coaching code balances coaching batches with a WeightedRandomSampler utilizing inverse class frequencies, whereas the loss stays unweighted. Combining a weighted loss with weighted sampling over-corrects towards the minority class.
Compiling for the sting with SageMaker Neo, contained in the pipeline
Discover the gate’s if_steps within the previous code: previous the gate, compilation runs first and registration depends upon it. Each coaching scripts export ONNX with dynamic batch axes. The standard gates rating these exported artifacts beneath ONNX Runtime, after which a CompileAnomalibNeo or CompileClassifierNeo step arms the gated artifact to SageMaker Neo. The invariant is gate, then compile, then register. A mannequin solely turns into an Accredited bundle if it additionally compiled for the fleet’s edge goal, so the registry by no means advertises a mannequin the units can’t run.
The compile step encapsulates three error-prone particulars. Neo requires the enter tarball to include solely the mannequin file, however coaching jobs emit mannequin.tar.gz with the checkpoint and metrics alongside the ONNX mannequin. The step repackages an ONNX-only tarball first. Neo additionally requires concrete enter shapes whereas the exports declare a dynamic batch axis, so batch measurement 1 is pinned within the compilation request. And since pipeline steps can retry, the compilation job title derives deterministically from the execution ID, so a retry resumes polling the job it already began as an alternative of orphaning it.
The goal is a pipeline parameter: NeoTargetDevice selects a named machine resembling jetson_xavier or rasp4b, and its default compiles for the NeoTargetOs/NeoTargetArch platform, LINUX/X86_64 by default. The compiled bundle comprises the optimized compiled.so plus the DLR runtime for loading it. The default output runs on any x86_64 Linux host, so you may validate it earlier than committing to device-specific targets. Compilation itself incurs no cost. You pay for the processing occasion that drives it and the S3 storage of the outputs. For compiling an already-registered mannequin for extra machine sorts later, with out re-training, the repository contains an ad-hoc script that runs the identical move in opposition to the Mannequin Registry.
Per-camera fashions within the Mannequin Registry
Every department registers into its personal mannequin bundle group, and each bundle carries the digicam ID and its analysis metrics. From the pattern, with the metrics wiring elided:
Digicam id in customer_metadata_properties is what turns two shared bundle teams right into a fleet catalog. Packages from all cameras reside in the identical teams, and per-camera historical past is recovered by filtering on the metadata. Every department has a fetch step that pages by authorized packages newest-first till it finds the requesting digicam’s newest mannequin, as a result of ListModelPackages can’t filter on buyer metadata server-side. On a digicam’s first run the fetch finds nothing and coaching falls again to its cold-start initialization (ImageNet weights for the classifier, random initialization for the autoencoder). Each later run resumes from that digicam’s personal prior mannequin, which is what makes frequent, low cost, incremental re-training viable throughout a fleet.
Word what these registry entries are and are usually not: they catalog versioned, quality-gated artifacts, however their container reference is the coaching picture, which serves no inference endpoints. They exist for a fleet workflow the place a downstream system pulls artifacts and ships them to units, not for CreateEndpoint.
Orchestrating fleet coaching requests
Each AWS account has service quotas on concurrent SageMaker coaching jobs, and every pipeline execution right here launches a number of jobs, so fleet re-training wants pacing. One thing has to maintain a burst of 500 requests from turning into 500 simultaneous pipeline launches. The pattern makes use of a semaphore, a counter of obtainable slots that works like a car parking zone with 5 areas. Earlier than the Step Features state machine begins a pipeline, it takes a slot by atomically incrementing a counter in DynamoDB, with a situation that refuses the increment as soon as the cap is reached:
If all slots are taken, the execution waits and retries. When its pipeline finishes, it decrements the counter to launch the slot. One element is price carrying into your individual designs. The DynamoDB situation expression enforces the cap in a single atomic operation, slightly than the state machine studying the counter and deciding, which would depart a race window between the learn and the write. The repository implements the remainder of the operational hardening, together with releasing slots on each failure path and forwarding failed executions to Amazon SNS by Amazon EventBridge. Its README covers sizing the wait bounds.
The cap of 5 is a stack parameter, set low so the pattern deploys and runs in any commonplace account with out requesting quota will increase. Regulate it to no matter your account’s training-job quotas assist. Previous a single account’s quotas, scaling fleet coaching is its personal matter. The usual levers are elevating the service quotas, spreading coaching throughout occasion sorts or Areas, and distributing the fleet throughout a number of accounts. You can even maintain the backlog in SQS and admit work solely as capability frees up. These decisions rely in your fleet’s measurement and form. The pattern provides you the working skeleton to increase.
Deploying and operating the pattern
The walkthrough within the repository README is the authoritative model. The next brief kind begins from a clear checkout and units up the setting earlier than the primary deploy:
By default the pipeline generates artificial manufacturing line pictures, so you may validate the entire system finish to finish with no dataset and no information approvals. A full run executes all 13 steps, together with each Neo compilations, in about quarter-hour and prices roughly $0.07 in billed ml.m5.xlarge time (US East (Ohio) Area (us-east-2), July 2026, on-demand). The orchestration sources collectively price effectively beneath $0.10 per 30 days at pattern scale.
To train the pipeline on actual pictures, the repository features a downloader for the BCCD dataset. The dataset is a set of 364 annotated blood smear microscopy pictures initially open sourced on GitHub and reorganized into Pascal VOC format beneath an MIT license. The identical dataset can be distributed by Roboflow as public area. The script maps platelet presence to the defect class, optionally splits the pictures per digicam to simulate a fleet, and uploads coaching tarballs to the pipeline bucket. The accompanying pocket book runs the total pipeline on the actual information and does side-by-side ONNX inference on a traditional and an anomalous pattern. Treating platelets as defects is an illustrative stand-in for a producing defect distribution, not a scientific declare.
Cleansing up
Mannequin packages are created at pipeline runtime, so AWS CloudFormation can’t delete them. Take away them with the AWS CLI first, then destroy the stacks with cdk destroy --all -c bootstrap=true --force. The README lists the precise instructions.
Conclusion
On this publish, I confirmed a working SageMaker SDK v3 reference structure for the fleet-scale laptop imaginative and prescient lifecycle. The structure features a dual-branch coaching pipeline the place each mannequin is quality-gated on its exported ONNX artifact, compiled with SageMaker Neo, and solely then registered. A Mannequin Registry structure makes use of digicam metadata to show shared bundle teams into per-camera warm-startable historical past, and a Step Features orchestration layer paces fleet coaching inside account quotas. For groups whose wants are met by managed choices resembling Amazon Lookout for Imaginative and prescient, that’s the less complicated path. This sample targets the per-camera, fleet-scale constraint that managed choices don’t cowl. The design guidelines switch past laptop imaginative and prescient: gate on balanced accuracy plus minority-class recall slightly than accuracy, consider and compile the artifact you ship, and make operational failures notify slightly than terminate silently.
The pattern deploys in minutes and a full validation run prices about seven cents of compute, so a low-cost subsequent step is to clone the repository and run it. From there, level the BCCD downloader at an actual bucket, set NeoTargetDevice to your {hardware}, or measurement the orchestration bounds to your fleet. For the SDK v3 migration itself, the SageMaker Python SDK documentation and the two-part sequence asserting the brand new SDK are the references I stored open all through.
If you’d like assist adapting this sample to your manufacturing setting, attain out to your AWS account crew.
In regards to the writer