
Here’s a run that handed.
Eleven turns. The checks handed on flip 4. Turns 5 by 10 have been work no one requested for, and a few of it ended up within the ultimate patch.
The agent modified eight strains throughout three information. The reference repair is simply two strains in a single file. So six of these eight modified strains have been pointless compared with the reference.
A standard go/fail verify would deal with this run the identical as a clear five-turn run. Each solved the duty. There isn’t a distinction within the rating.
There’s one essential factor I ought to say earlier than going additional: the agent on this experiment is simulated. I didn’t run Claude Code, Codex, or one other actual coding agent for this text. The repositories, edits, diffs, check runs, and failures are actual. What I simulated was the agent’s decision-making, utilizing a seeded Python coverage. I’ll clarify why I selected that method, what it lets me measure, and the place the bounds are.
The query I wished to reply is fairly easy.
When an AI coding agent takes additional turns to get to a passing patch, how a lot of that work was really wanted? And may a workflow across the agent scale back the pointless work?
I ran about 50,000 simulated runs: 24,000 in a compliance sweep, 14,400 testing particular person guidelines, and one other 12,000 on a held-out suite.
Three outcomes stood out to me. And one prediction I made earlier than working the experiment turned out to be fallacious.
Why a passing patch doesn’t inform you how properly an AI coding agent labored
SWE-bench begins with an actual GitHub problem and an actual codebase. The mannequin has to vary the code and get the related checks passing. The benchmark has 2,294 issues taken from 12 Python repositories [1]. It’s a robust benchmark, and the primary rating is simple to grasp: did the patch repair the difficulty or not?
That rating is beneficial, however there’s something it does not present. It solely appears on the ultimate outcome. It does not care what number of steps the mannequin took to get there.
Say one run finds the failing check, tracks down the bug, makes the change and will get a inexperienced check run. One other run will get there too, however first adjustments the fallacious file, backs that change out, runs the identical command a number of extra instances, adjustments some unrelated code after which runs checks that have been already passing.
Each runs are profitable in SWE-bench. They do not look similar to me, although.
The second run used extra turns. It took extra time and tokens, and there may be extra for somebody to look by. If a few of these adjustments survive into the ultimate patch, the additional work exhibits up there too.
For this experiment, I wished to maintain two issues separate:
-
Last patch measurement: what’s totally different between the beginning repository and the ultimate patch.
-
Complete work: all the things the agent did earlier than getting there, together with adjustments it will definitely reverted.
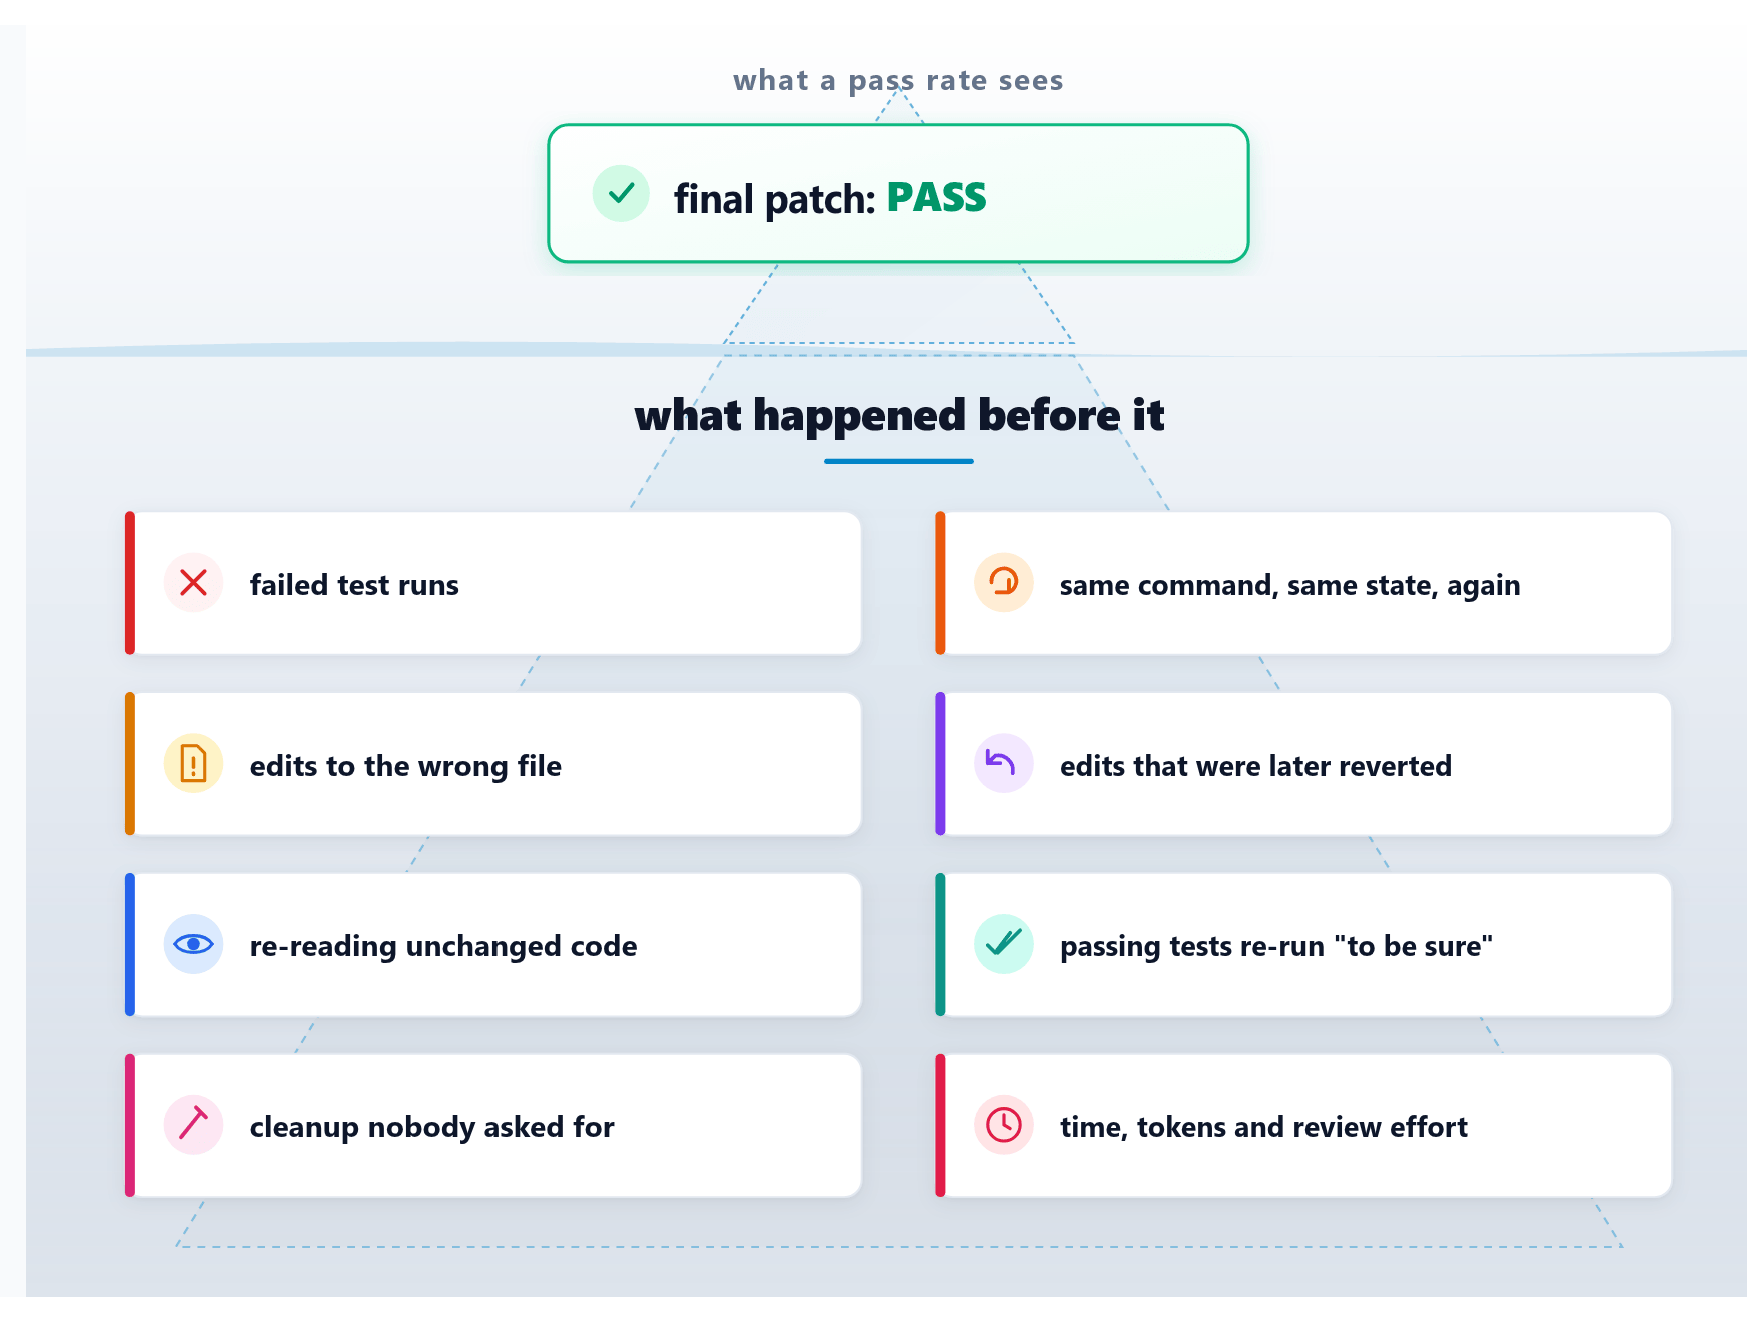
A go price scores solely the ultimate patch. Under that line sits all the things an AI coding agent did to get there: failed check runs, repeated instructions, edits to the fallacious file, reverted adjustments and passing checks run once more for no purpose.
The remainder of this text appears at what occurs earlier than that ultimate patch.
How I constructed a coding agent benchmark with out working an actual agent
I had two restrictions from the beginning: no API keys and no downloaded fashions. I additionally wished another person to have the ability to run the identical experiment and get the identical numbers.
There was another excuse for not utilizing an actual agent. If I did, I might even be measuring variations within the mannequin, its software use and the setting round it. API prices would come into the image too. That might make it more durable to inform whether or not a outcome got here from the workflow I used to be testing or from the actual agent I occurred to make use of.
So I break up the issue into two elements.
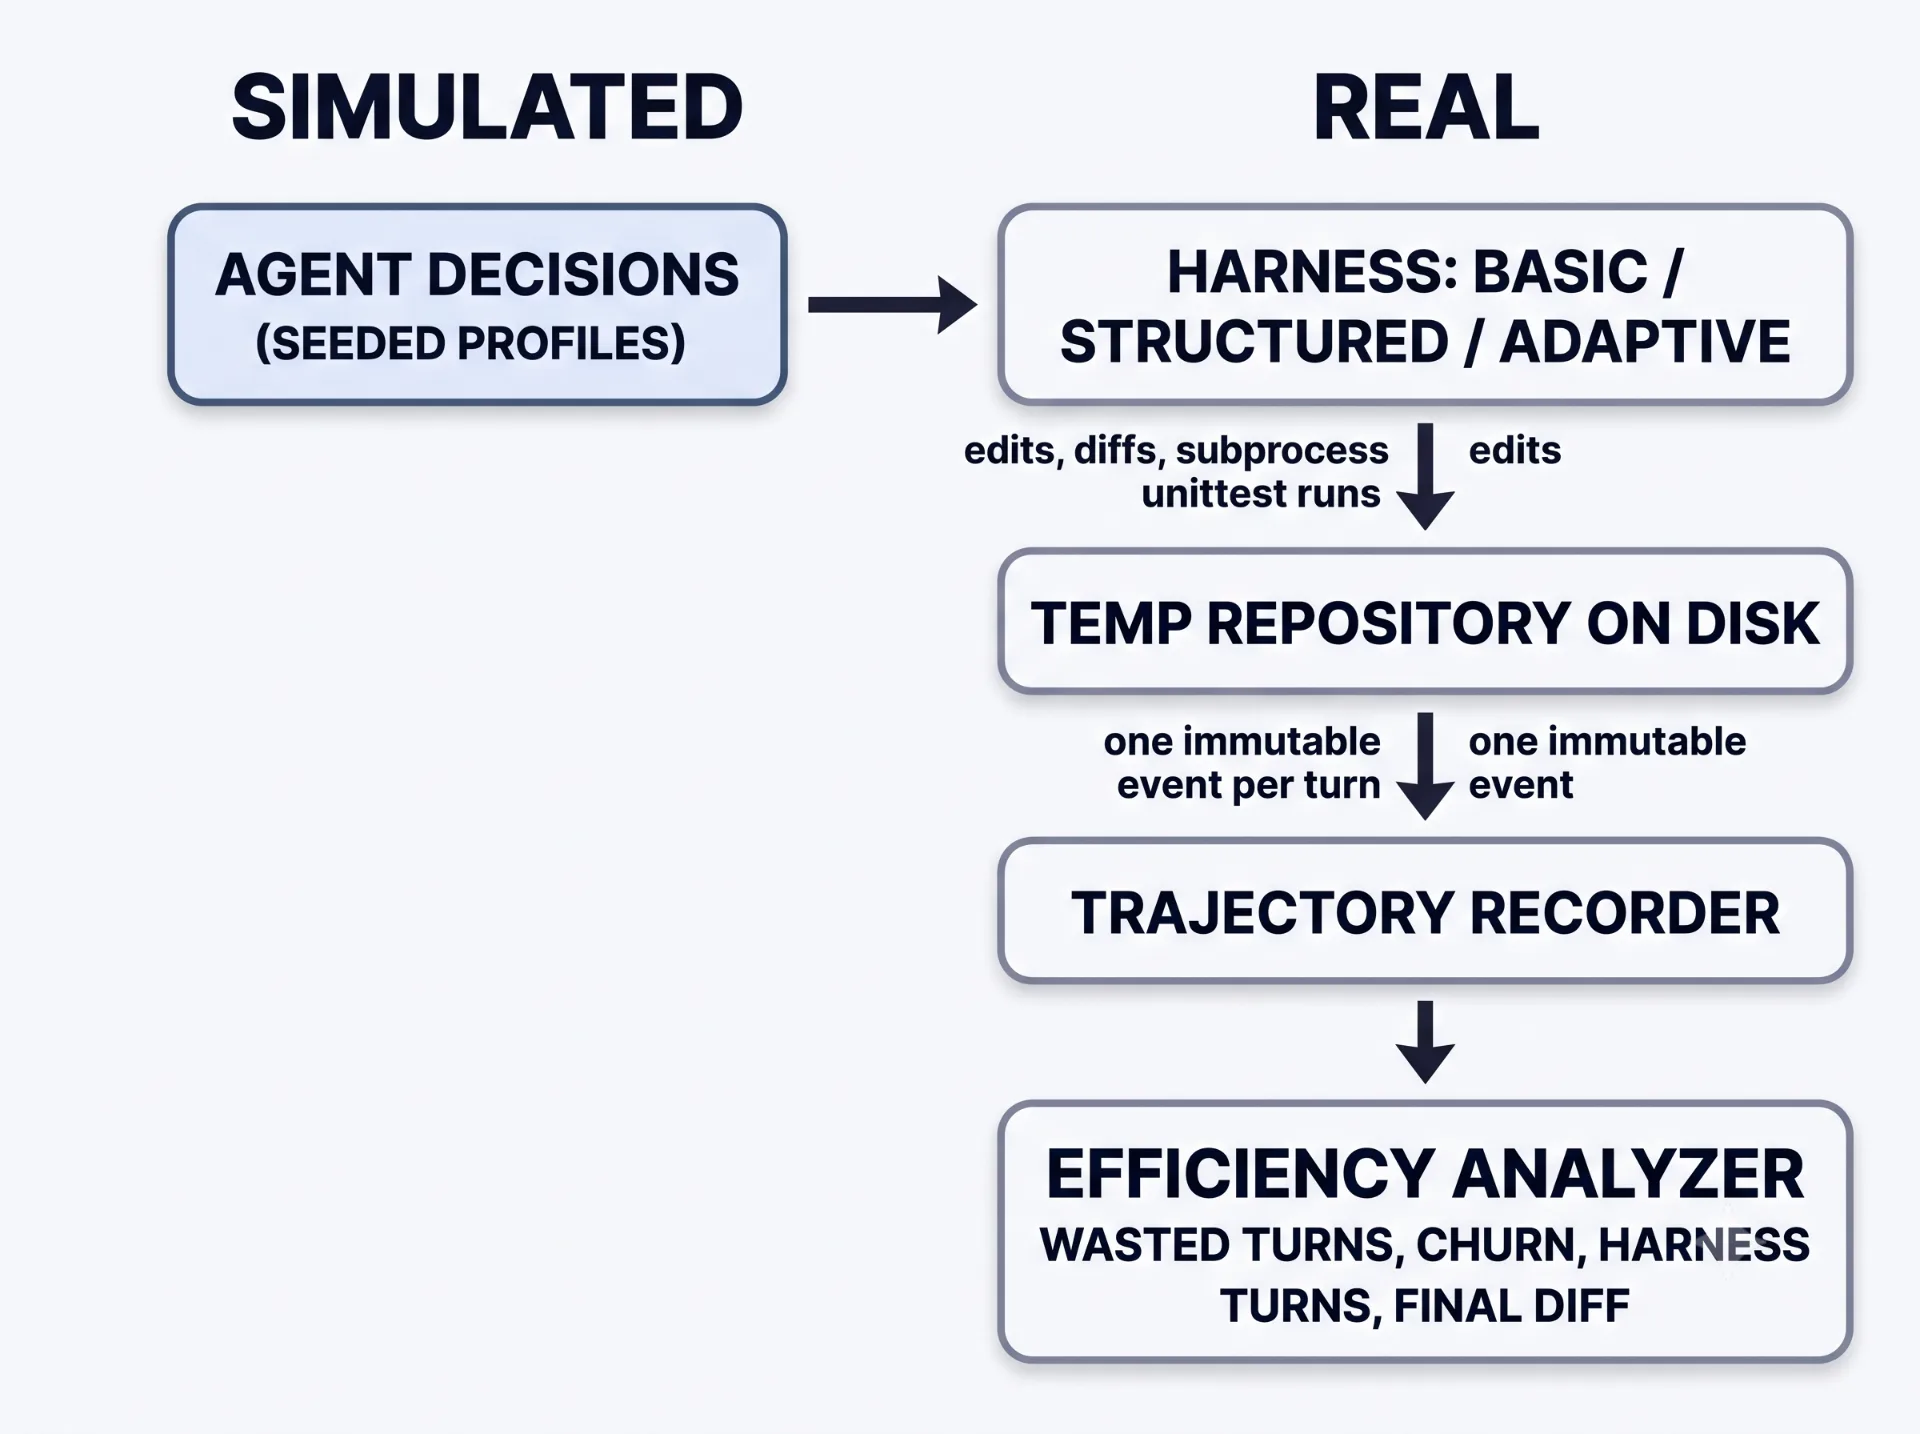
The coding agent benchmark runs seeded, simulated selections by a harness in opposition to an actual repository on disk. Each edit, diff and check run is recorded as an occasion, and the analyzer turns these occasions into wasted turns, patch churn and ultimate diff measurement.
The repository is actual, and the code really runs. The one factor I simulated is the half that decides what to do subsequent.
That issues in terms of the claims I could make. I can check how a specific harness rule behaves when the agent behaves in a specific method. I am unable to inform you how Claude Code or Codex behaves, as a result of I did not run both of them.
The duties. I made ten small bugs, with every one dwelling in its personal non permanent repository. They cowl issues like an off-by-one vary, a boundary comparability, an empty-list crash, a fallacious formulation, a lacking strip, misplaced ordering, a slice error, a fallacious variable, swapped department order and a whitespace break up.
Every repository has a unittest suite and a recognized reference repair. I additionally put a believable fallacious repair within the right file, together with a number of innocent adjustments in unrelated information. I exploit these as decoys. The checks run in a subprocess, so the agent is coping with an precise repository relatively than a toy record of predefined solutions.
The agent. The essential coverage is fairly extraordinary: run the checks, take a look at the failure, make a change, run the checks once more and cease when issues go. I then give totally different profiles some fastened probabilities of doing one thing else alongside the way in which.
|
Profile |
Improper edit |
Repeats a failing command |
Reverts |
Quits early |
Unneeded edit after a go |
|---|---|---|---|---|---|
|
cautious |
0.05 |
0.05 |
0.02 |
0.03 |
0.05 |
|
regular |
0.15 |
0.15 |
0.08 |
0.08 |
0.15 |
|
sloppy |
0.30 |
0.30 |
0.20 |
0.18 |
0.30 |
|
loop_prone |
0.10 |
0.55 |
0.15 |
0.05 |
0.40 |
These numbers are hypothetical. I selected 4 habits profiles, beginning with a cautious agent and ending with one that’s extra more likely to get caught in loops. I did not get these profiles by measuring actual brokers, so I do not deal with absolutely the numbers as predictions of what Claude Code, Codex or one other agent would really do. The sweeps later within the article are there partly to verify how a lot the outcomes change when these assumptions change.
How the agent reacts to the harness is one thing I can change instantly. compliance controls how usually the agent follows a harness instruction as a substitute of ignoring it. plan_benefit controls how a lot a compelled planning step reduces the possibility of constructing the fallacious edit.
Paired runs. I maintain the agent’s random stream tied to the profile, job and seed. Meaning once I evaluate two harnesses, they begin with the identical agent habits. I run them as pairs relatively than evaluating two unrelated random runs.
Success comes from a verify the agent does not see. As soon as a run finishes, I run the checks in opposition to the ultimate state of the repository. In the event that they go, the run is profitable.
What counts as wasted work in an agentic coding workflow
I did not wish to rely each failed check as wasted work. A failed check may be helpful. If I simply modified one thing and the check tells me what went fallacious, that result’s a part of the debugging course of.
So I rely an motion as wasted when it does not transfer the run any nearer to the ultimate state. In my setup, that features issues like:
-
repeating one thing the agent has already seen: working the identical command once more with out altering the repository, working a check once more when not one of the related information have modified, or studying the identical contents once more
-
altering part of the repository that has nothing to do with the checks
-
making an edit that adjustments nothing, or making a change that will get undone later
A revert wants a little bit extra care. I do not rely the revert itself as waste if it was wanted to get well from a foul change. The unhealthy change is what I rely.
For instance: the agent edits the fallacious file, the check fails, it checks the diff, reverts the change, edits the correct file and the check passes. The fallacious edit is wasted work. The revert is not, as a result of it was wanted to get again to a helpful state.
I additionally maintain harness work separate. If the harness provides a planning step, evaluate step, gate or cleanup step, I rely that as a harness flip relatively than calling it agent waste. I wish to see the price of including that construction.
Repetition itself is not uncommon. A research of failures in multi-agent LLM techniques lists step repetition as certainly one of 14 failure modes [5]. That research is not about coding brokers particularly, however the primary downside is analogous.
The recorder solely shops what occurred. It does not determine what was wasteful on the time. The analyzer works that out afterwards, which implies I can change the definition later with out working all of the experiments once more.
The core of it, trimmed:
Listed here are the foundations the analyzer makes use of for checks and edits:
By “related,” I imply a file that the check suite really imports. The harness can determine that out from the checks. It does not must know what the proper repair is.
Primary, structured and adaptive: three agent harnesses
I used three totally different harnesses for the comparability. On this experiment, the harness is solely the layer sitting between the agent and the repository.
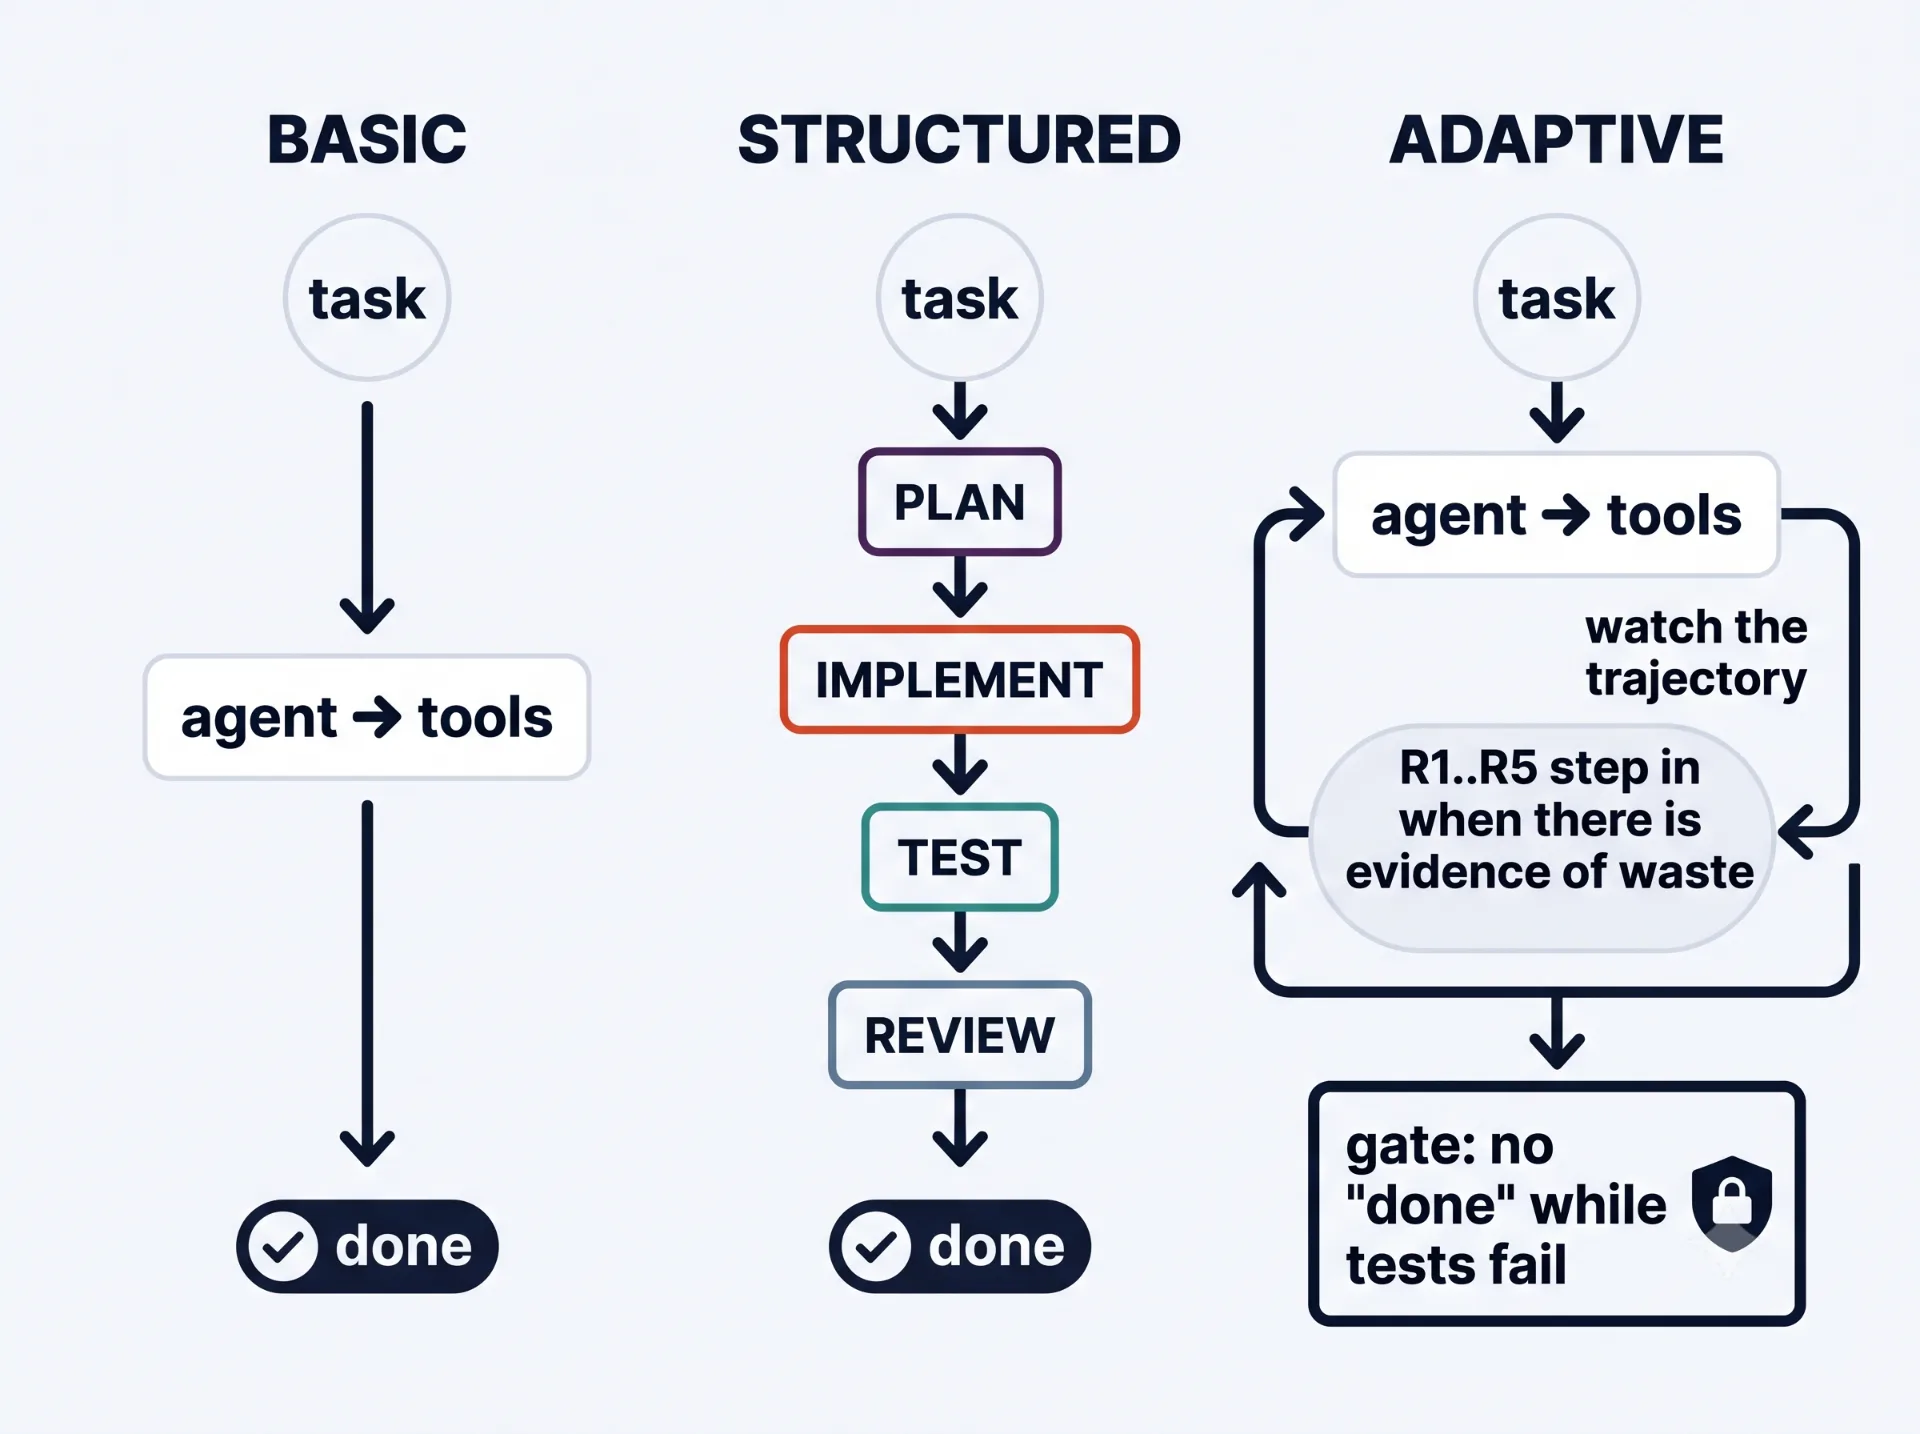
The essential harness lets the agent work till it says it’s achieved. The structured harness forces plan, implement, check and evaluate. The adaptive harness watches the trajectory, steps in with 5 guidelines, and refuses to let the agent end whereas checks fail.
Anthropic has a helpful distinction right here. A workflow has the steps labored out upfront. An agent will get to determine what to do subsequent. Additionally they advocate beginning easy as a substitute of including loads of equipment upfront [3].
That’s mainly how I take into consideration the 2 harnesses. The structured one tells the agent what to do. The adaptive one does not. It waits for sure issues to occur after which reacts.
There are comparable concepts in instruments individuals already use. Claude Code has hooks that may run a command at a specific level in a session, together with issues like formatting a file after an edit or stopping a command earlier than it runs [4]. SWE-agent additionally discovered that the setup across the mannequin issues: the way it edits information, strikes across the repository and runs checks can have an effect on the outcome [2].
I am not making an attempt to breed both system right here. My adaptive harness is way smaller. I simply wished a number of fastened guidelines that would react to what the simulated agent was doing.
I locked these guidelines earlier than beginning the runs:
|
Rule |
Fires when |
Directive |
|---|---|---|
|
R1 |
the identical command failed twice with no state change |
diagnose earlier than modifying once more |
|
R2 |
the identical file was modified twice, or two reverts occurred |
examine the accrued diff |
|
R3 |
three turns handed with no state change |
change technique |
|
R4 |
checks go after a messy run |
confirm by reviewing the diff |
|
R5 |
an edit touched a file the checks don’t import |
justify it or undo it |
|
Gate |
the agent tries to complete whereas checks fail |
refuse |
Two of the three harnesses refuse to let the agent end whereas checks fail. Hold that in thoughts. It issues within the subsequent part.
End result 1: the most cost effective agent harness was deceptive
Right here is the primary comparability. Twenty seeds, ten duties, 200 runs per cell, compliance 0.5.
|
Profile |
Harness |
Success |
Turns |
Wasted turns |
Harness turns |
|---|---|---|---|---|---|
|
cautious |
primary |
92.5% |
5.20 ± 0.19 |
0.29 ± 0.11 |
0.00 |
|
cautious |
structured |
100.0% |
7.66 ± 0.20 |
0.44 ± 0.14 |
2.12 |
|
cautious |
adaptive |
100.0% |
5.76 ± 0.26 |
0.28 ± 0.10 |
0.42 |
|
regular |
primary |
77.5% |
5.25 ± 0.27 |
0.63 ± 0.16 |
0.00 |
|
regular |
structured |
100.0% |
8.82 ± 0.33 |
1.31 ± 0.25 |
2.35 |
|
regular |
adaptive |
100.0% |
6.62 ± 0.34 |
0.74 ± 0.17 |
0.86 |
|
sloppy |
primary |
51.5% |
5.62 ± 0.41 |
1.44 ± 0.27 |
0.00 |
|
sloppy |
structured |
100.0% |
11.91 ± 0.62 |
3.15 ± 0.37 |
3.10 |
|
sloppy |
adaptive |
100.0% |
9.95 ± 0.68 |
1.97 ± 0.29 |
2.83 |
|
loop_prone |
primary |
89.0% |
7.45 ± 0.46 |
2.46 ± 0.37 |
0.00 |
|
loop_prone |
structured |
100.0% |
11.59 ± 0.56 |
3.85 ± 0.43 |
2.48 |
|
loop_prone |
adaptive |
100.0% |
9.04 ± 0.56 |
2.29 ± 0.31 |
1.97 |
Desk 1. All runs, 200 per cell. Imply ± 95% interval. Created by the creator from the benchmark output.
At first look, the fundamental harness appears just like the winner. It has the fewest turns for all 4 profiles, and in two profiles it additionally has the bottom waste.
However take a look at the success numbers too.
The sloppy agent solely solves 51.5% of its duties with the fundamental harness. It might merely cease whereas the checks are nonetheless failing. That provides you a brief run with little or no wasted work, however solely as a result of the agent gave up.
So flip counts on their very own could make a failing harness look higher than it truly is.
For the fee comparability, I solely use seeds the place each harnesses really solved the duty. Then I evaluate these runs instantly, one in opposition to the opposite.
|
Profile |
Harness |
Matched pairs |
Additional turns vs primary |
Additional wasted turns vs primary |
Harness turns |
|---|---|---|---|---|---|
|
cautious |
structured |
185 |
+2.16 ± 0.08 |
+0.12 ± 0.07 |
2.04 |
|
cautious |
adaptive |
185 |
+0.23 ± 0.12 |
-0.04 ± 0.05 |
0.31 |
|
regular |
structured |
155 |
+2.52 ± 0.16 |
+0.46 ± 0.15 |
2.06 |
|
regular |
adaptive |
155 |
+0.37 ± 0.17 |
-0.01 ± 0.10 |
0.49 |
|
sloppy |
structured |
103 |
+3.13 ± 0.29 |
+0.86 ± 0.27 |
2.26 |
|
sloppy |
adaptive |
103 |
+1.05 ± 0.51 |
-0.41 ± 0.29 |
1.70 |
|
loop_prone |
structured |
178 |
+3.46 ± 0.27 |
+1.14 ± 0.25 |
2.32 |
|
loop_prone |
adaptive |
178 |
+1.10 ± 0.51 |
-0.30 ± 0.32 |
1.84 |
Desk 2. Seeds the place primary and the harness each solved the duty, in contrast run by run. Compliance 0.5. Created by the creator from the benchmark output.
The image adjustments as soon as I line up the profitable runs.
Structured provides between two and three and a half turns for each profile, together with the cautious agent. It does not scale back waste in any of them both. The waste really goes up.
There could also be a easy purpose for a part of that. When the structured harness sends the agent again from “end” to do a evaluate, the simulator offers its random deviations one other probability to occur. I have not remoted that impact or tried to right for it, so I would not put an excessive amount of weight on the structured waste numbers.
Adaptive is way nearer to primary for the cautious and regular profiles. With the sloppy and loop-prone profiles, it cuts the waste a little bit. The loop-prone outcome remains to be shut sufficient to zero that I would not name it a transparent win.
The success numbers inform a fair easier story.
Each structured and adaptive cease the agent from ending whereas the checks are failing. So I examined that rule by itself, with out the opposite 5 adaptive guidelines.
It produced the identical success price as the total adaptive harness. On seeds the place each runs succeeded, it additionally matched primary precisely: 0.00 ± 0.00 additional wasted turns and 0.00 ± 0.00 additional turns throughout all 4 profiles.
That outcome is not stunning when you take a look at how I constructed the simulator. Early quitting is without doubt one of the behaviors I put into it. The gate prevents that habits from ending the run. On this experiment, that one rule accounts for all the enchancment in success.
End result 2: just one rule really minimize wasted work
So if the gate explains the advance in success, what in regards to the 5 different guidelines? Do they really scale back the wasted work?
That seems to rely loads on whether or not the agent follows them.
The chart beneath exhibits the change in wasted turns in contrast with primary, utilizing matched seeds, as compliance will increase.
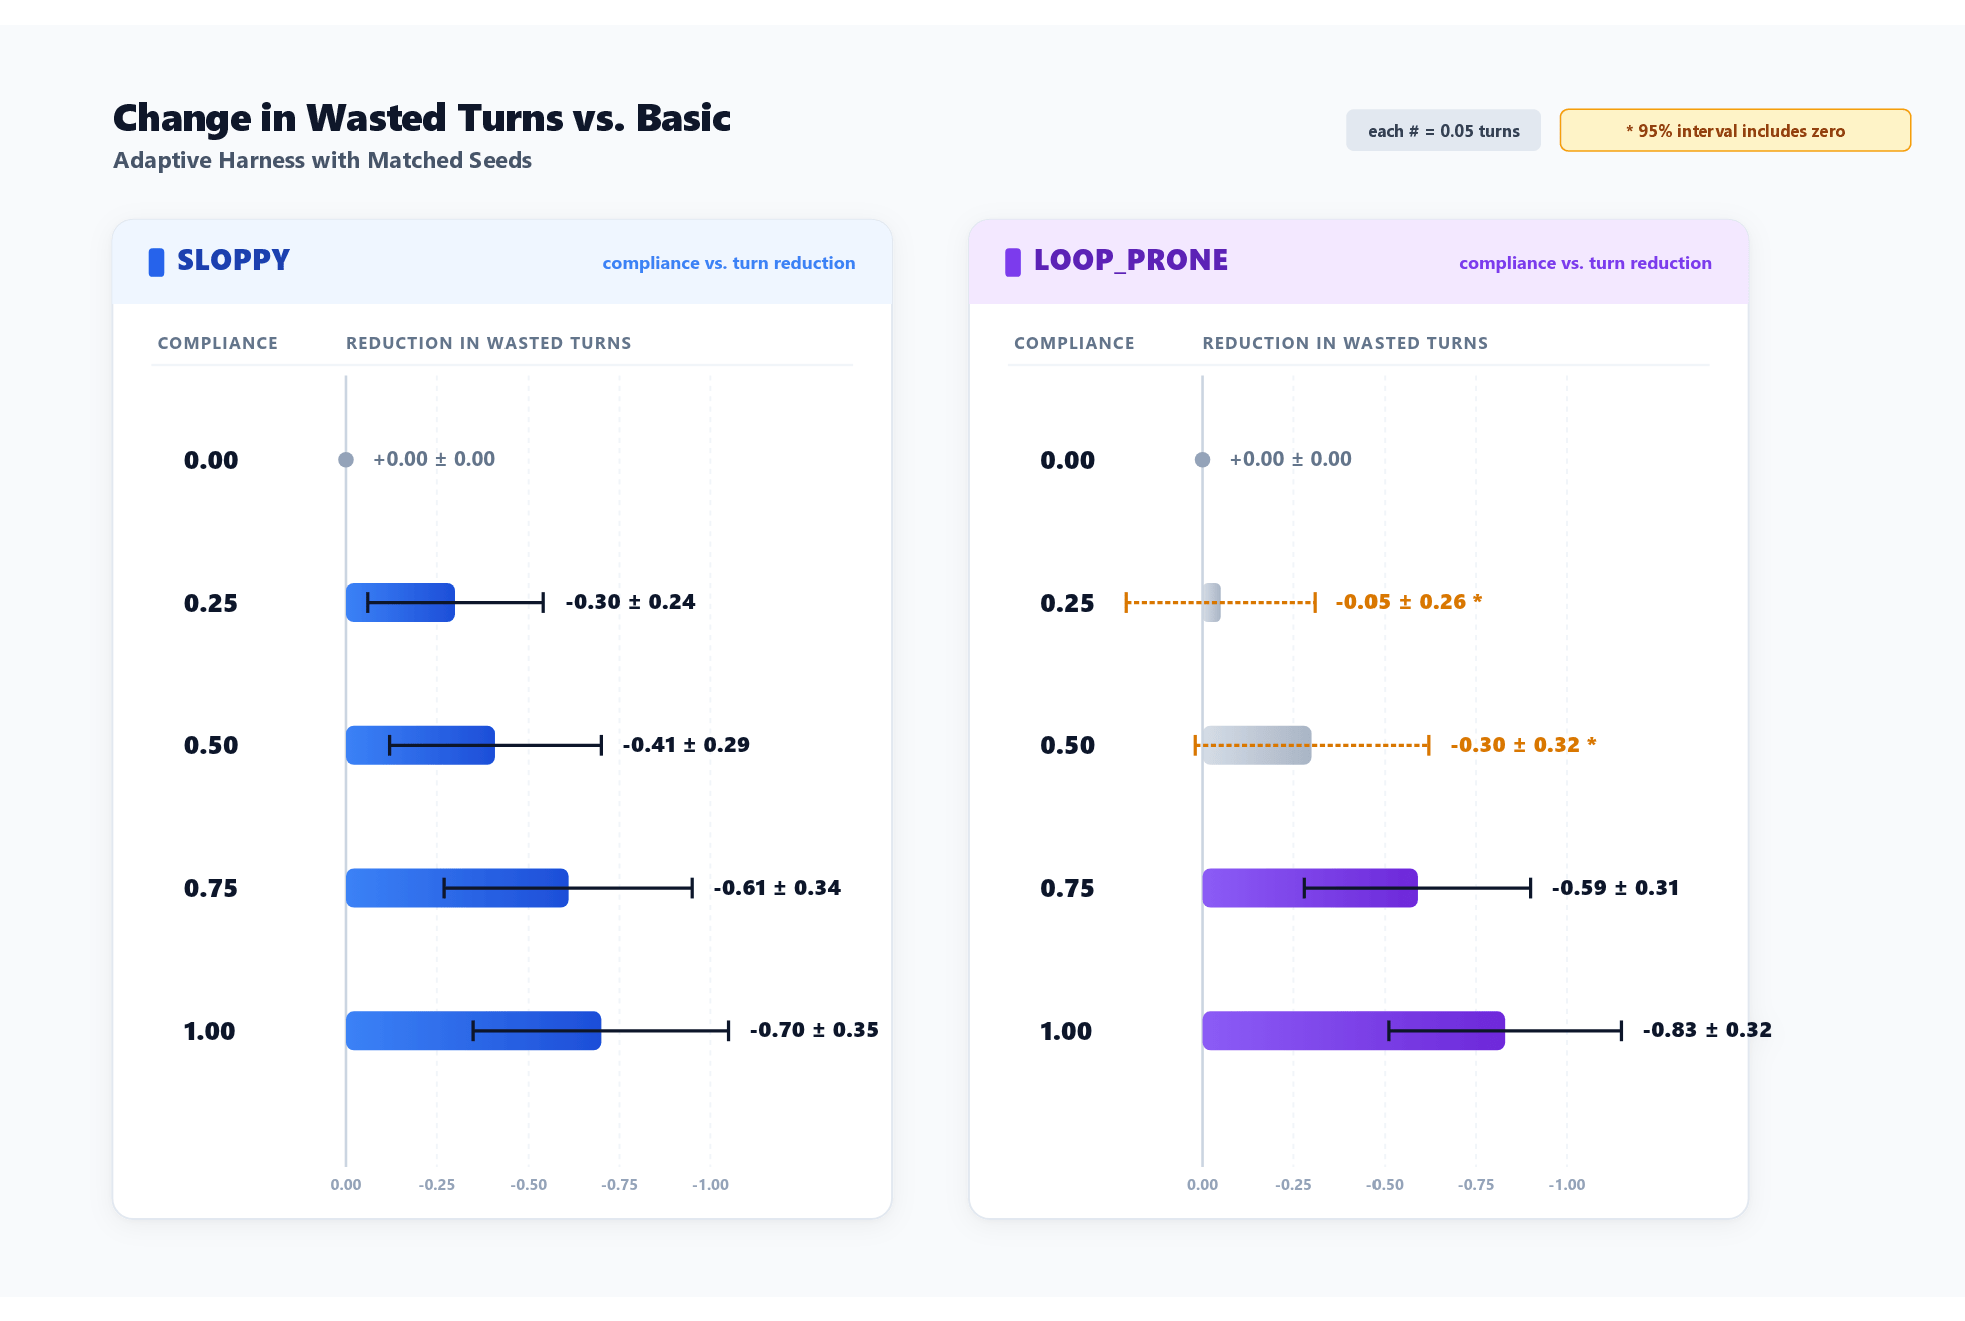
On matched seeds, the adaptive harness removes extra wasted turns because the agent follows its directives extra usually. At compliance 1.0 it removes 0.70 turns for sloppy brokers and 0.83 for loop-prone brokers. An asterisk marks an interval that features zero.
At compliance = 0, the foundations nonetheless hearth, however the agent ignores them. Nothing adjustments, which makes this a helpful management.
As soon as compliance goes above zero, the sloppy profile begins losing fewer turns at each stage I examined. The loop-prone profile is more durable to maneuver. I do not see a transparent discount there till compliance reaches 0.75, the place the interval lastly strikes away from zero.
The dimensions of the saving is the larger problem. At compliance = 1.0, adaptive saves 0.70 ± 0.35 wasted turns for the sloppy agent. However it makes use of 2.99 harness turns to do it, and the entire run remains to be 1.77 ± 0.68 turns longer than primary.
So on this setup, I am spending roughly three additional turns to save lots of lower than one wasted flip.
I then took the 5 guidelines aside separately to see which one was chargeable for the saving.
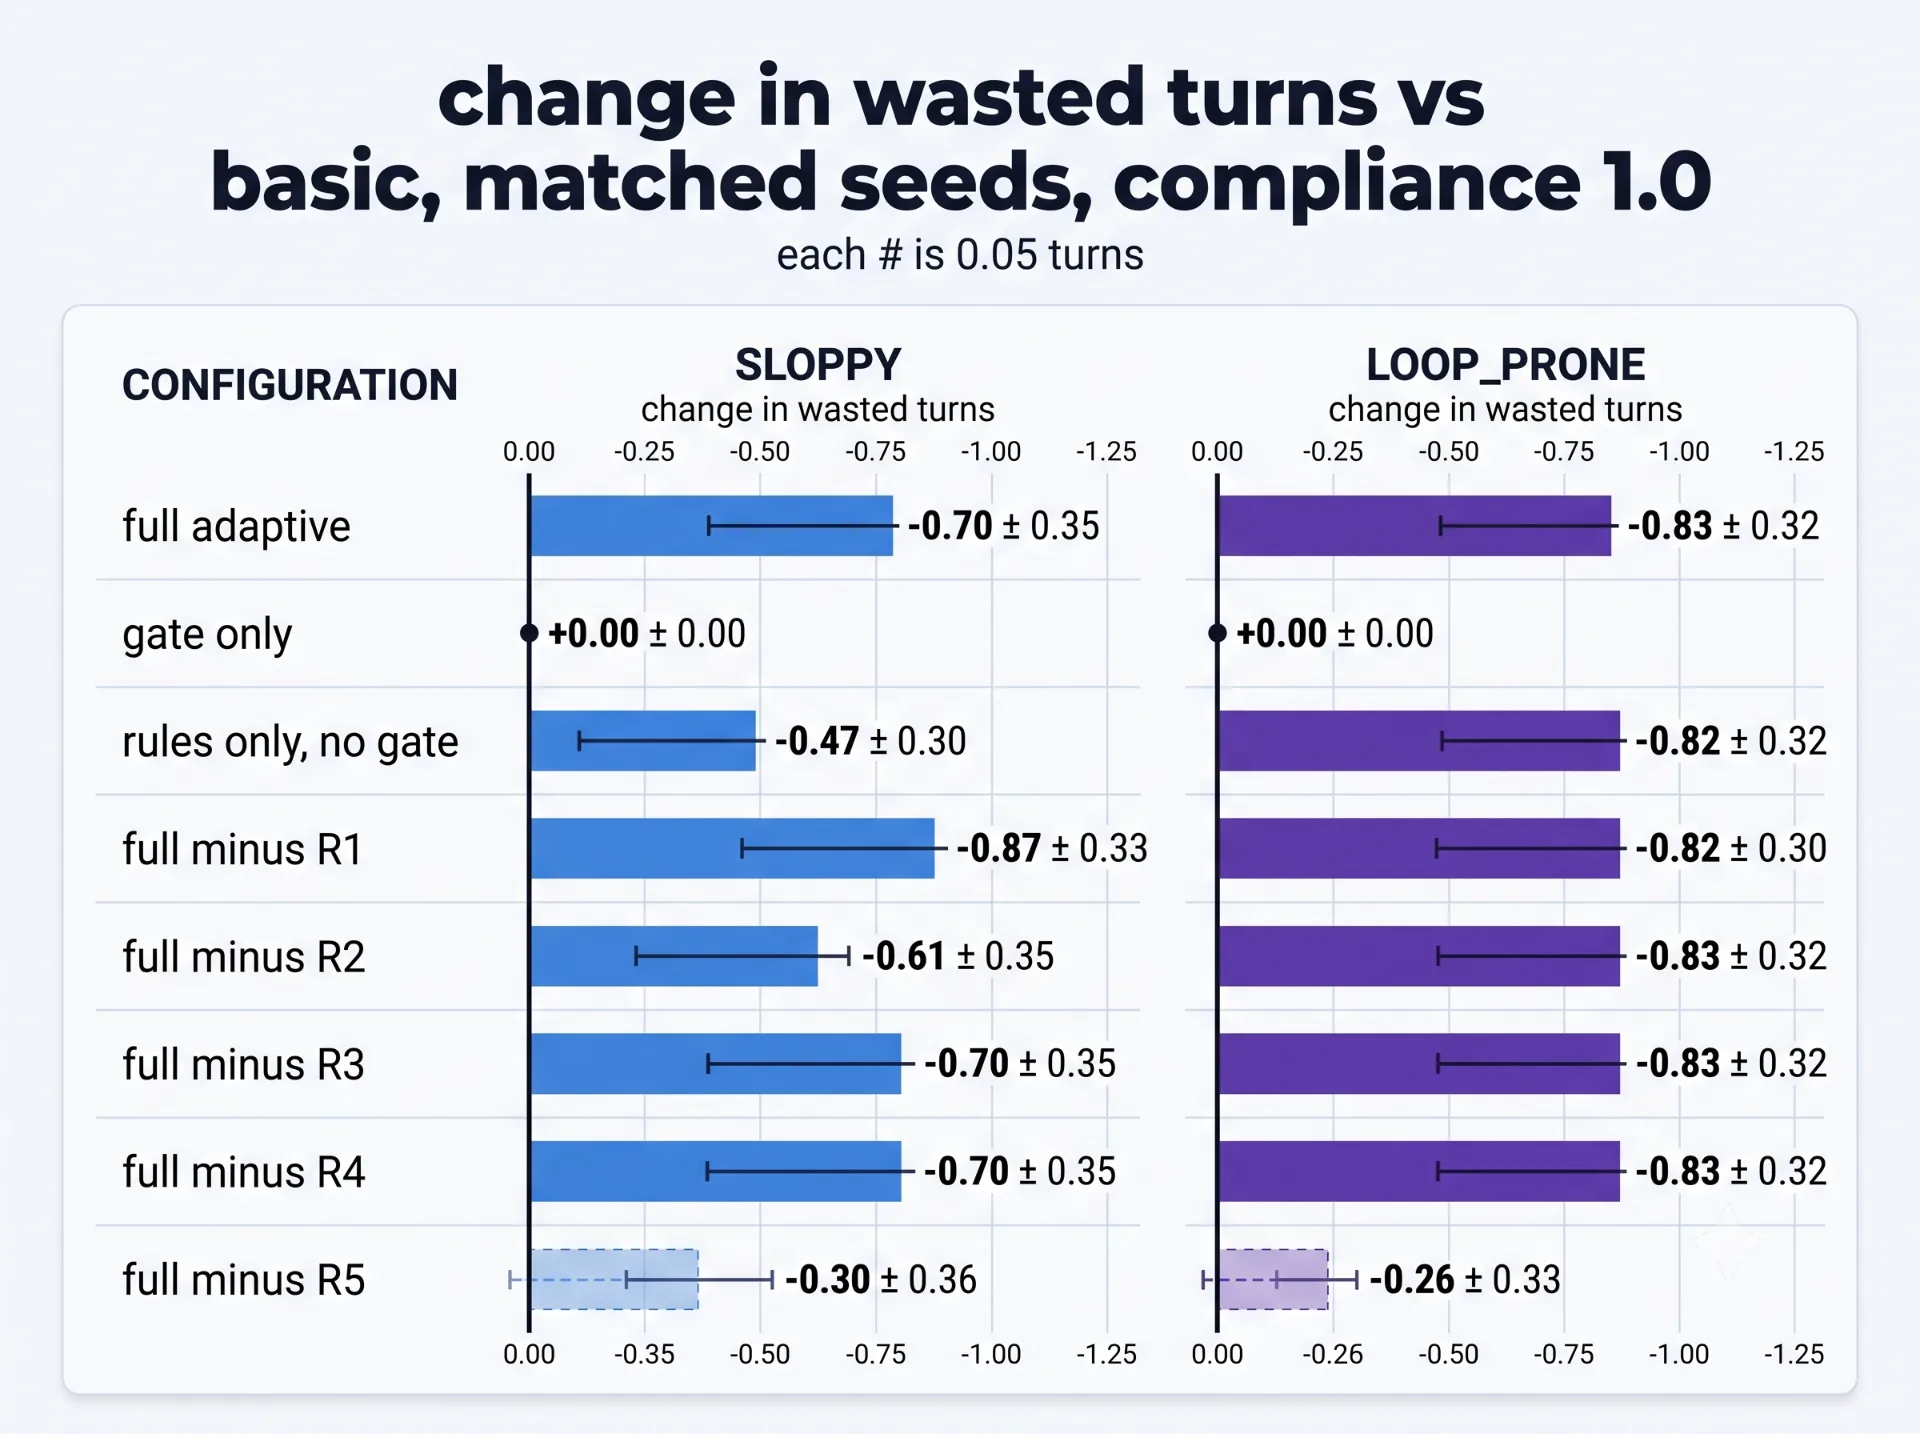
Every bar exhibits the change in wasted turns in opposition to the fundamental harness when one rule is eliminated. The completion gate alone adjustments nothing on matched seeds. Dropping R5 shrinks the discount from 0.70 to 0.30 turns for sloppy brokers and from 0.83 to 0.26 for loop-prone brokers.
R5 is doing a lot of the work right here.
I discovered that once I eliminated it at compliance = 1.0, the discount in wasted work dropped by greater than half for the sloppy profile. For the loop-prone profile, it dropped by roughly two thirds. The opposite two profiles have been totally different. With R5 gone, the change was barely optimistic: +0.11 ± 0.11 for regular and +0.03 ± 0.04 for cautious.
I additionally tried taking out R1, R2, R3 and R4. The waste numbers barely moved. Eradicating R1 or R2 did scale back the additional flip rely a little bit, so these guidelines appear to be including overhead with out doing a lot for waste on this explicit setup.
That is what R5 really does within the harness:
R5 fires when the agent adjustments a file that not one of the checks import. The simulator creates precisely this example with its decoy edits.
That can also be the half the place I needed to query my very own outcome. I created the decoy edit, after which I created the rule that catches it. So is adaptive really higher, or did I simply give it an issue that I knew find out how to detect?
I believe a skeptical reader is true to ask that. I requested it too.
The following part is my try to verify it. One caveat up entrance: I designed the rule ablations after seeing the primary outcomes, so they’re put up hoc relatively than a part of the unique plan.
End result 3: what occurs when the foundations do not cowl the habits
Earlier than I ran the held-out checks, I wrote down what I anticipated to occur. That is the fundamental thought behind preregistration: determine on the questions, predictions and evaluation earlier than trying on the outcomes, relatively than arising with a proof after the actual fact [6]. I borrowed that method right here. The predictions are in a file within the repository, and I froze it earlier than working the held-out suite.
For the held-out runs, I added 4 new agent profiles. None of them edits a file exterior the module being examined, and none of them quits whereas the checks are failing. Meaning R5 has nothing to catch, and the success gate has nothing to do.
I additionally added a unit check to verify R5 actually can’t hearth on these profiles.
-
held_oscillate. The agent makes a fallacious edit, reverts it, after which has a 0.6 probability of constructing the identical fallacious edit once more.
-
held_rerun. After the checks go, the agent runs the identical passing checks once more, as much as 3 times.
-
held_core_thrash. After getting a go, the agent makes a pointless beauty change inside
app/core.py. R5 does not see this, and neither does my file-level definition of waste. -
held_mixed. A mixture of the three behaviors above.
There’s a catch right here. Two of those behaviors are associated to guidelines I had already written. R2 was meant to catch oscillation, and repeated passing checks can set off R3. So this is not a very untouched check of the foundations. It’s extra of a stress check.
I could not give you a habits that the entire guidelines would miss, as a result of the foundations themselves are pretty basic.
My prediction was easy: adaptive would present no demonstrated discount in waste on any of those 4 profiles.
I used 50 seeds, 10 duties and 500 runs per cell, with solely matched seeds included within the comparability.
|
Profile |
Compliance |
Pairs |
Adaptive: wasted turns |
Adaptive: complete turns |
Adaptive: additional diff strains |
Structured: wasted turns |
Structured: complete turns |
|---|---|---|---|---|---|---|---|
|
held_oscillate |
0.5 |
489 |
-0.91 ± 0.27 |
-0.32 ± 0.31 |
+0.00 ± 0.00 |
+0.00 ± 0.00 |
+2.00 ± 0.00 |
|
held_oscillate |
1.0 |
488 |
-1.67 ± 0.36 |
-0.42 ± 0.37 |
+0.00 ± 0.00 |
+0.00 ± 0.00 |
+2.00 ± 0.00 |
|
held_rerun |
0.5 |
500 |
+0.00 ± 0.04 |
+0.19 ± 0.06 |
+0.00 ± 0.00 |
+0.71 ± 0.08 |
+2.71 ± 0.08 |
|
held_rerun |
1.0 |
500 |
+0.03 ± 0.04 |
+0.48 ± 0.10 |
+0.00 ± 0.00 |
+0.71 ± 0.08 |
+2.71 ± 0.08 |
|
held_core_thrash |
0.5 |
500 |
+0.48 ± 0.05 |
+0.95 ± 0.11 |
-0.45 ± 0.04 |
+0.29 ± 0.04 |
+2.77 ± 0.07 |
|
held_core_thrash |
1.0 |
500 |
+0.66 ± 0.05 |
+1.43 ± 0.12 |
-0.60 ± 0.04 |
+0.60 ± 0.04 |
+3.07 ± 0.06 |
|
held_mixed |
0.5 |
499 |
+0.05 ± 0.12 |
+0.65 ± 0.20 |
-0.21 ± 0.04 |
+0.66 ± 0.07 |
+3.05 ± 0.11 |
|
held_mixed |
1.0 |
499 |
-0.09 ± 0.17 |
+1.18 ± 0.25 |
-0.29 ± 0.04 |
+0.82 ± 0.08 |
+3.21 ± 0.11 |
Desk 3. Held-out profiles, 50 seeds, matched seeds solely, distinction vs primary. Created by the creator from the benchmark output.
The prediction was proper for 3 of the 4 profiles and fallacious for one.
held_rerun and held_mixed did what I anticipated. Adaptive did not scale back waste, and it added turns.
held_core_thrash was extra attention-grabbing. Adaptive elevated the quantity of labor my analyzer referred to as waste, however on the similar time it eliminated stray strains from the ultimate patch. I am going to come again to that distinction beneath.
The miss was held_oscillate. I anticipated the agent to maintain going across the similar loop as a result of R2 solely appears on the diff. As an alternative, adaptive lowered waste by 0.91 ± 0.27 turns at compliance = 0.5 and by 1.67 ± 0.36 at compliance = 1.0. It did not add any complete turns both.
So I checked out what was taking place.
There was an assumption in my simulator that I hadn’t observed. When the harness reverted the stray edit, the simulated agent additionally forgot that it had wished to make that edit once more. That makes the harness look higher than it ought to.
I modified the simulator in order that the agent nonetheless desires to re-apply an edit after the harness reverts it, then ran the case once more.
|
Agent after a harness revert |
Wasted turns, adaptive minus primary (0.5 / 1.0) |
Complete turns, adaptive minus primary (0.5 / 1.0) |
|---|---|---|
|
Forgets the edit (pre-registered) |
-0.91 ± 0.27 / -1.67 ± 0.36 |
-0.32 ± 0.31 / -0.42 ± 0.37 |
|
Nonetheless desires it |
-0.62 ± 0.25 / -1.21 ± 0.32 |
+0.15 ± 0.33 / +0.59 ± 0.43 |
The waste discount will get smaller by a couple of third, but it surely does not disappear. The benefit in complete turns does disappear, although.
I did not break down the remaining discount to see precisely the place it comes from, so I’m treating this rerun as exploratory. The unique preregistered outcomes keep unchanged.
Last patch measurement vs complete work: the identical run by three harnesses
The core-thrash outcome made me take a look at one other a part of the run. Counting wasted turns tells me what occurred alongside the way in which, but it surely does not all the time inform me what was left behind within the ultimate patch.
So let’s return to the run from the beginning of the article: the loop-prone agent, the off-by-one job, seed 6, with compliance = 0.5.
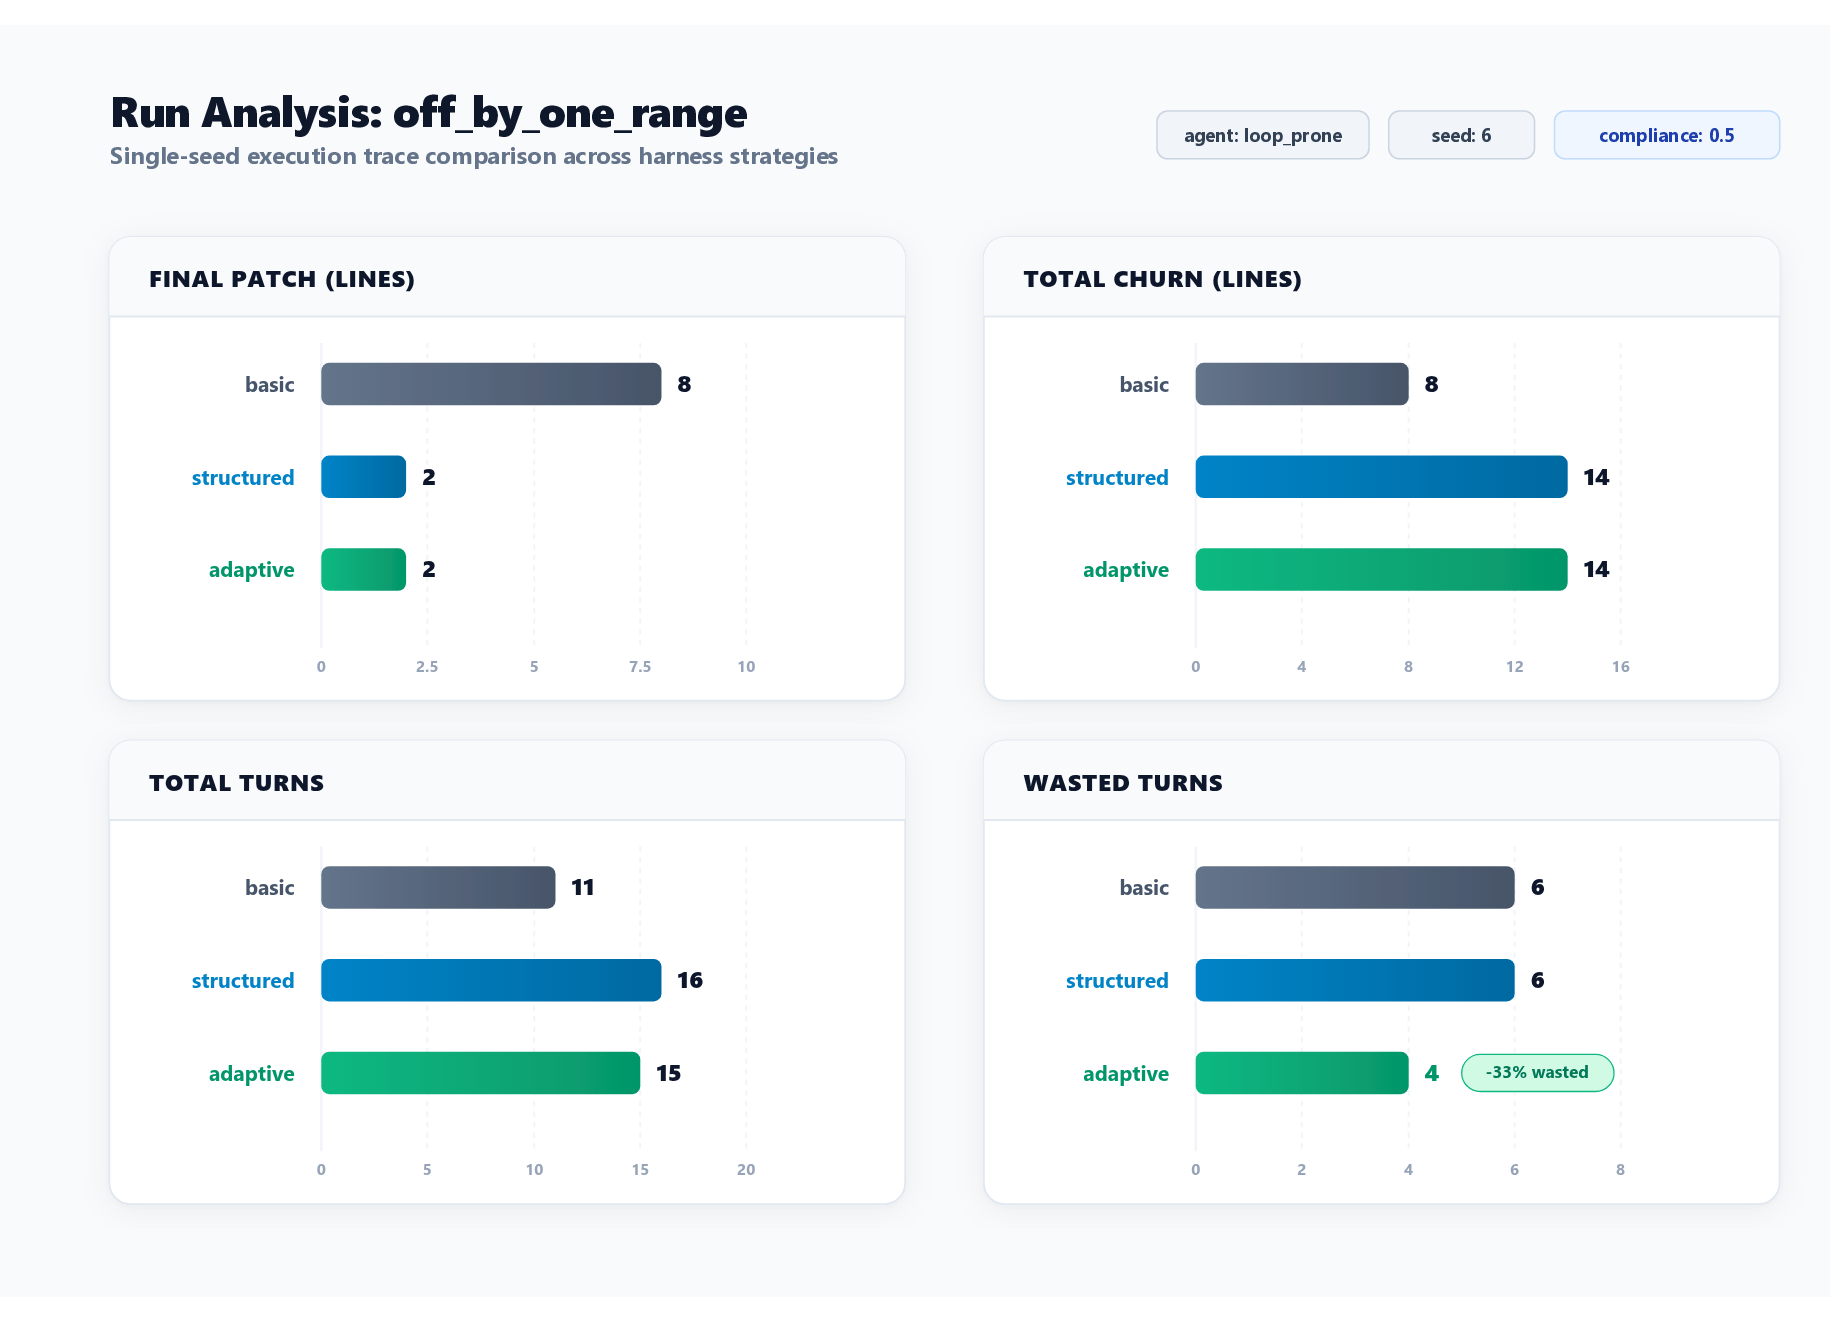
On this run, the fundamental harness returns an eight-line patch with eight strains of churn in 11 turns. The structured and adaptive harnesses return the two-line repair, however with 14 strains of complete churn, as a result of they apply stray edits after which revert them.
The essential harness leaves an eight-line patch, together with three edits that don’t have anything to do with the duty. Structured and adaptive depart the two-line repair.
However they do extra work to get there. Each undergo the stray edits after which undo them, so the entire churn is 14 strains.
That creates a humorous outcome. If I solely take a look at turns, primary wins. If I take a look at the ultimate diff, primary loses. Neither quantity is fallacious. They’re measuring totally different elements of the run.
The identical factor exhibits up throughout the matched seeds. For sloppy brokers, adaptive leaves a ultimate patch that’s 0.97 ± 0.35 strains smaller on common. For loop-prone brokers, the distinction is 0.71 ± 0.29 strains. However complete churn goes up by 0.66 ± 0.54 and 1.00 ± 0.45 strains respectively.
The held_core_thrash case makes the issue even clearer. Adaptive can take away a pointless line from the ultimate patch and nonetheless get the next waste rating. The reason being how I outlined waste: as soon as the harness cleans up that edit, it turns into an edit that was “reverted later”, and that will get counted as waste.
So one metric says the run obtained worse whereas one other says the ultimate patch obtained cleaner.
I do not assume that may be a bug in both metric. It’s a good purpose to not squeeze all the things into one effectivity rating.
Design selections I might defend, and those I might not
There are a number of selections within the experiment that I believe are value making express. Change any of them and among the numbers change too.
Paired seeds. Each harness begins with the identical agent habits for a given seed. That removes loads of random noise from the comparability. With out paired runs, the intervals can be wider and I might be a lot much less assured in regards to the variations.
Harness turns are separate from agent waste. A evaluate step is figure, but it surely is not one thing the agent determined to do. Counting it as agent waste would make structured look worse for the fallacious purpose. Leaving it out utterly would make these turns look free. So I report the 2 individually.
The success verify is hidden. The agent does not get to determine whether or not it solved the duty. As soon as the run ends, I run the checks on the ultimate repository state. If it stop whereas the checks have been failing, that is a failure.
The recorder shops details, not judgments. It information what occurred and leaves the waste labels to the analyzer. Meaning I can change the waste definition later with out working the entire experiment once more.
Take a look at outcomes are cached. If the repository is unchanged, the check outcome ought to be the identical, so I solely run every distinct repository state as soon as. I’ve a unit check that compares a cached outcome with a contemporary subprocess run, and --no-cache disables the cache once I need each check run to execute for actual.
There are additionally 4 selections I would not defend practically as strongly.
One chance for compliance. Actual brokers do not have a single setting that claims how usually they comply with a directive. I exploit one quantity as a result of it makes the sweep simple to grasp. The truth that the outcomes transfer as that quantity adjustments is beneficial, however the mannequin remains to be crude.
File-level relevance. I name a file related when the checks import it. That works for the decoy edits I wished to catch, but it surely has an apparent gap. A pointless edit inside the proper file is not caught by both R5 or my waste definition.
The agent forgetting. Within the first model of the simulator, as soon as the harness reverted an edit, the agent forgot that it had wished to make that edit. That made the oscillation outcome look higher than it ought to have. The rerun with a persistent intention lowered the impact.
The 40-turn cap. This one issues for the oscillation profile. At compliance = 0.5, each unsuccessful run hit the cap: 11 of 500 for primary, 15 of 500 for structured and none for adaptive. If I elevated the cap, these success charges might change. So I would not deal with the precise success numbers there as steady past this experiment.
Limits of this coding agent benchmark
There are some issues this experiment merely can’t inform me. I do not need the outcomes to sound broader than they’re.
-
The agent is simulated. I did not run Claude Code, Codex or one other actual coding agent right here. An actual agent might behave in methods none of my profiles seize.
-
The profile and compliance numbers are mine. I various them and ran sweeps over compliance, however the values themselves aren’t measurements of actual brokers.
-
The duties are tiny. I used ten bugs, every affecting a single operate. Actual repositories carry a lot messier issues: adjustments throughout a number of information, flaky checks, gradual builds and different issues this setup does not mannequin.
-
Waste is outlined on the file stage. If the agent makes a pointless change inside the proper file, my analyzer does not know that it was pointless. The
held_core_thrashoutcome exhibits this beautiful clearly. -
I should still have simulator assumptions I have not observed. The oscillation outcome discovered one for me. I hadn’t realised that the simulated agent forgot a couple of change after the harness reverted it.
-
The ablations got here after the primary outcomes. The held-out suite additionally overlaps with behaviors that R2 and R3 have been designed to catch. I’ve already referred to as this out above, but it surely issues sufficient to repeat.
-
The intervals have limits too. I exploit normal-approximation intervals on paired means throughout loads of cells. With this many comparisons, some outcomes will look attention-grabbing simply by probability, and success charges are bounded proportions. I subsequently put extra weight on patterns that present up throughout profiles and compliance ranges than on any single cell.
What to measure in your personal agent workflow
In the event you’re working coding brokers on actual work, these are the issues I might take from my experiment. All of them held in my simulation, however that does not imply they will maintain in yours. I might verify them relatively than assuming.
-
Hold ultimate patch measurement and complete churn separate. A small ultimate diff can conceal loads of edits that occurred alongside the way in which.
-
Examine value solely the place each setups succeed. In any other case, the setup that provides up early can look cheaper just because it stops doing work.
-
Do not let the agent declare success whereas the verify is failing. This was the most cost effective rule I examined, and it made the largest distinction to success.
-
Take a look at guidelines on issues you did not construct them round. In the event you write a rule to catch a failure after which solely check that failure, the outcome is not very convincing.
-
Write down what you count on earlier than working the experiment. One in every of my predictions was fallacious. Having it written down meant I could not quietly change the story after seeing the outcome.
From simulation to an actual agent: how I might check this subsequent
Every little thing thus far comes from the simulator. I have not run this setup on an actual coding agent but.
The very first thing I might want is a recorder that captures a number of particulars for each motion: what the agent did, what it touched, the command it ran, the exit code, an output hash, the repository state earlier than and after, and the strains added or eliminated.
Claude Code hooks can run your personal instructions at totally different factors in a session, together with earlier than a command runs or after a file edit [4]. That ought to be sufficient to show every occasion into one JSON line. I might then map these occasions onto the identical construction utilized by this experiment and run the present analyzer with out altering it.
There are two elements I might watch out about.
First, “related file” wants a greater definition for an actual repository. I used the information imported by the checks. On an actual venture, I might most likely want an import graph or the information modified by a recognized reference patch.
Second, an actual agent will not give me the identical trajectory each time. I might want many runs of the identical job below every harness earlier than evaluating them. One run can present that one thing occurred. It might’t inform me how usually it occurs.
Run the benchmark your self
You solely want Python 3.10 or newer to run the benchmark. There are not any additional packages to put in as a result of it makes use of solely the usual library.
I additionally seed each random alternative, so should you run the identical benchmark, it is best to get the identical numbers I did.
The primary run takes a couple of minute on my laptop computer. The complete compliance sweep (--sweep) takes about 4 minutes. The final command exhibits the turn-by-turn trajectories, together with the precise diffs. The pre-registration file, HELDOUT.md, is within the repository alongside the code.
Repository: https://github.com/Emmimal/agent-efficiency-benchmark/
Conclusion: the go price leaves out the work
A coding-agent benchmark that solely information whether or not the ultimate patch passes misses loads of what occurred earlier than that patch. Within the run that opens this text, the checks handed, however the agent nonetheless made six wasted turns and left a ultimate patch 4 instances bigger than the reference repair.
As soon as I began recording the trajectory, the price of the harness confirmed up too. On this simulation, one rule lowered wasted work however added turns. One other harness left a cleaner ultimate patch whereas making the waste metric worse. You do not see both of these issues in a go price.
I would not take these outcomes as a verdict on an actual agent or an actual coding workflow. I see them as a purpose to log extra than simply whether or not the ultimate patch handed.
Disclosure
I’ve no affiliation with, sponsorship from or monetary curiosity in Anthropic, Princeton College or every other group or software named on this article. No actual coding agent and no language mannequin was run for this research. Each agent determination is simulated, and I say so wherever outcomes are reported. I ran each experiment and checked each quantity within the textual content in opposition to my very own output information.
All diagrams on this article, together with the featured picture, have been created by the creator. The featured picture was generated with ChatGPT (DALL·E).
Assets
[1] Jimenez, C. E., Yang, J., Wettig, A., Yao, S., Pei, Okay., Press, O., & Narasimhan, Okay. (2024). SWE-bench: Can Language Fashions Resolve Actual-World GitHub Points? Worldwide Convention on Studying Representations (ICLR 2024). arXiv:2310.06770. https://arxiv.org/abs/2310.06770
[2] Yang, J., Jimenez, C. E., Wettig, A., Lieret, Okay., Yao, S., Narasimhan, Okay., & Press, O. (2024). SWE-agent: Agent-Pc Interfaces Allow Automated Software program Engineering. arXiv:2405.15793. https://arxiv.org/abs/2405.15793
[3] Anthropic. (2024). Constructing efficient brokers. Engineering at Anthropic. https://www.anthropic.com/engineering/building-effective-agents
[4] Anthropic. Hooks reference. Claude Code documentation. https://code.claude.com/docs/en/hooks (accessed October 2026).
[5] Cemri, M., Pan, M. Z., Yang, S., et al. (2025). Why Do Multi-Agent LLM Programs Fail? Advances in Neural Info Processing Programs (NeurIPS 2025), Datasets and Benchmarks Observe. arXiv:2503.13657. https://arxiv.org/abs/2503.13657
[6] Nosek, B. A., Ebersole, C. R., DeHaven, A. C., & Mellor, D. T. (2018). The preregistration revolution. Proceedings of the Nationwide Academy of Sciences, 115(11), 2600-2606. https://doi.org/10.1073/pnas.1708274114
[7] Alexander, E. P. (2026). Agent effectivity benchmark: code, pre-registration and outcomes. GitHub. https://github.com/Emmimal/agent-efficiency-benchmark/