
On this article, you’ll be taught what AI agent observability means, why conventional monitoring instruments fall brief for agentic methods, and learn how to implement structured logging, distributed tracing, and sensible debugging workflows for AI brokers.
Matters we’ll cowl embody:
- Why AI brokers fail in ways in which appear like success, and why that makes normal monitoring instruments inadequate.
- implement structured logging and OpenTelemetry-based tracing for agent runs, software calls, and mannequin inference steps.
- learn hint waterfalls, monitor token prices with metrics, and use that knowledge to debug actual agent failures.
An agent dealing with buyer assist tickets closes one out with a clear, skilled, completely incorrect reply. It known as the refund-lookup software as soon as, then known as it once more with barely totally different arguments a number of seconds later, then answered confidently based mostly on the second consequence as an alternative of the primary. Nothing crashed. No error fired. The uptime dashboard exhibits inexperienced your complete time. The one purpose anybody finds out is a buyer replying two days later, confused, and by then no person can reconstruct what really occurred inside that run.
That failure is the entire purpose this text exists. A standard service both returns an error 200 or throws one thing you’ll be able to grep for. An agent can do neither and nonetheless be fully incorrect, and the tooling constructed for the primary form of system is near blind to the second. This text walks by way of what really wants to vary — logging, tracing, and debugging — one after the other, with actual code.
What AI Agent Observability Really Means
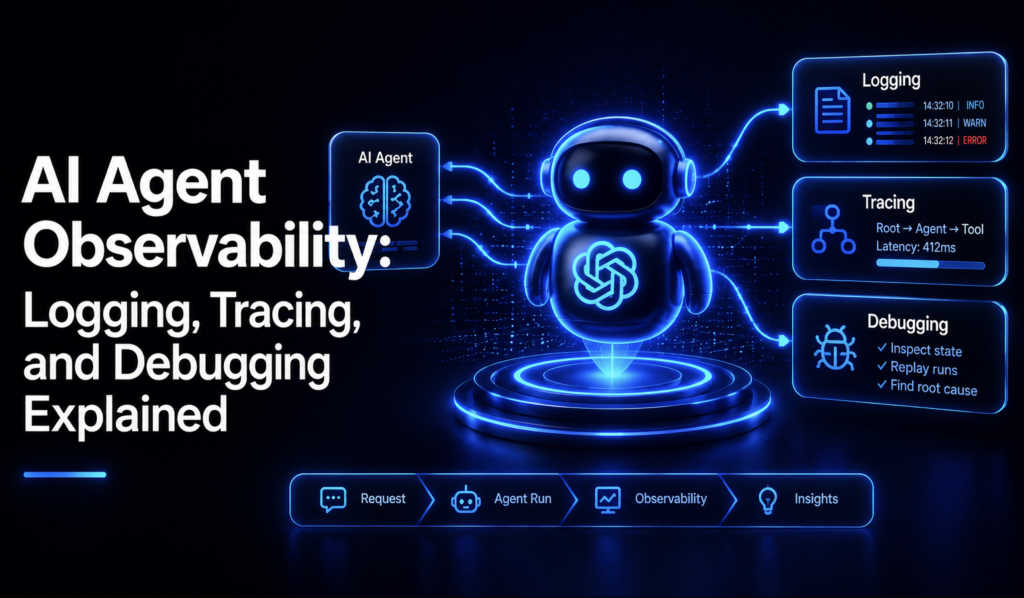
AI agent observability is the follow of capturing each mannequin name, software execution, and reasoning step an agent makes as structured knowledge, in order that when one thing goes incorrect, you’ll be able to reconstruct precisely what occurred and why, relatively than guessing or re-running the identical immediate and hoping the issue repeats itself.
It borrows from the three pillars observability engineers already know — logs, metrics, and traces — however the purpose it wants its personal title and its personal self-discipline comes all the way down to how brokers really fail. Aryan Kargwal, a researcher within the area, put it plainly in protection from Digital Utilized’s 2026 observability information: agentic methods fail in ways in which appear like success — incorrect however well-formed outputs, pointless software calls, or actions which are syntactically legitimate however semantically incorrect. None of that journeys an error handler. A well being test reporting “up” tells you nearly nothing helpful about whether or not the agent really did the best factor on any given run.
Why Brokers Break the Conventional Monitoring Mannequin
It’s value being particular concerning the mechanics right here, as a result of “brokers are unpredictable” undersells precisely what modifications.
The identical enter doesn’t reliably produce the identical conduct anymore. Temperature settings, retrieval outcomes, and which instruments occur to be out there can all shift the trail an agent takes, so the identical immediate can set off a genuinely totally different sequence of software calls on two consecutive runs. A single “it labored once I examined it” hint tells you nearly nothing about what the distribution of actual runs really seems like.
Price and latency cease correlating with request rely and begin correlating with tokens as an alternative. A single “sluggish” request is perhaps consuming ten occasions the traditional token price range, and a monitoring setup constructed round requests-per-second is structurally blind to that. Multi-step chains compound the issue: one consumer request may set off a number of mannequin calls, a handful of software calls, and a few retrieval lookups, and each is an unbiased level of failure {that a} single mixture error metric can’t distinguish between. And prompts themselves routinely carry actual private or confidential info, which suggests naive logging that dumps full immediate textual content right into a backend creates a real compliance drawback earlier than it has created any debugging worth in any respect.
A side-by-side comparability of the 2 worlds makes the shift concrete:
| Sign | Conventional app | LLM / AI agent |
|---|---|---|
| Latency driver | CPU, I/O, community | Token rely, mannequin measurement, context window |
| Price unit | Requests per second | Tokens consumed |
| Failure mode | Exception, timeout | Hallucination, context overflow, software error |
| Debug artifact | Stack hint | Immediate, completion, and the reasoning chain between them |
Logging
Begin with essentially the most acquainted pillar, as a result of it’s nonetheless the muse every little thing else builds on, simply utilized in a different way. For an agent, the occasions value logging are particular: which software received known as and with what arguments, what got here again, what number of tokens a given step consumed, how lengthy every hop took, and any error alongside the best way — and all of it structured relatively than written as free-text sentences a human has to parse later.
The element that really makes agent logging helpful is tying each log line again to the particular run it got here from. A log assertion that simply says “software name failed” is sort of nugatory at 2 am when three totally different customers triggered three totally different runs in the identical minute. Attaching the present hint ID to each log line — one thing OpenTelemetry does mechanically as soon as tracing is ready up — is what turns a pile of scattered log statements into one thing you’ll be able to filter all the way down to the precise run that broke.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import logging from opentelemetry import hint
# Commonplace Python logging, nothing unique right here logger = logging.getLogger(“agent”) logging.basicConfig(stage=logging.INFO)
tracer = hint.get_tracer(“agent-service”)
def call_tool(tool_name: str, arguments: dict): # get_current_span() pulls no matter span is lively proper now, # so the log line beneath may be tied again to the precise hint # and step it occurred inside span = hint.get_current_span() trace_id = format(span.get_span_context().trace_id, “032x”)
logger.information( “tool_call_started”, additional={ “trace_id”: trace_id, “tool_name”: tool_name, “arguments”: arguments, }, )
attempt: consequence = execute_tool(tool_name, arguments) logger.information( “tool_call_succeeded”, additional={“trace_id”: trace_id, “tool_name”: tool_name, “result_length”: len(str(consequence))}, ) return consequence besides Exception as e: logger.error( “tool_call_failed”, additional={“trace_id”: trace_id, “tool_name”: tool_name, “error”: str(e)}, ) elevate |
A couple of issues value noticing in that snippet. hint.get_current_span() doesn’t require you to manually move a hint ID down by way of each perform name — it reads no matter span is lively within the present execution context, which is precisely what makes this sample sensible to sprinkle all through an actual codebase with out threading an ID parameter by way of each layer.
Logging the arguments and the consequence size, relatively than the total consequence content material, is a deliberate alternative, not an oversight; full software outputs may be giant and might carry delicate knowledge, and a size or a truncated preview is often sufficient to identify an issue with out turning each log line right into a privateness legal responsibility. And logging each a begin and an finish occasion for a similar software name, relatively than simply the result, is what enables you to later measure precisely how lengthy that particular name took — which turns into the uncooked materials tracing formalizes correctly within the subsequent part.
Tracing
Logging tells you what occurred at particular person cut-off dates. Tracing is what stitches these factors right into a form — a full file of 1 agent run from the primary request to the ultimate reply, with each step nested contained in the step that triggered it. That nested form is the precise reply to “why did the agent do this,” as a result of it exhibits you not simply {that a} software was known as, however which reasoning step determined to name it and what occurred instantly earlier than and after.
The vocabulary right here comes from the OpenTelemetry GenAI semantic conventions, which outline a normal set of gen_ai.* span sorts and attributes particularly for this. Slightly than each group inventing their very own span names, the spec defines a handful of operation sorts value realizing: create_agent for when an agent is first outlined, invoke_agent for a single agent run, invoke_workflow for orchestration throughout a number of brokers handing off to one another, execute_tool for a person software name, and chat for the precise mannequin inference name itself. Each carries a normal set of attributes — gen_ai.request.mannequin, gen_ai.utilization.input_tokens, gen_ai.utilization.output_tokens, and gen_ai.response.finish_reasons amongst them — so a hint produced by one group’s agent seems structurally the identical as one produced by a totally totally different framework.
Right here’s what manually instrumenting a small tool-calling agent really seems like:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 |
from opentelemetry import hint from opentelemetry.hint import Standing, StatusCode
tracer = hint.get_tracer(“agent-service”)
def run_agent(job: str) -> str: # The basis span for this complete run; each step beneath nests # inside it, which is what produces the parent-child tree with tracer.start_as_current_span(“invoke_agent”) as agent_span: agent_span.set_attributes({ “gen_ai.system”: “openai”, “agent.title”: “support-agent”, “gen_ai.request.mannequin”: “gpt-4o”, })
messages = [ {“role”: “system”, “content”: “You are a support assistant.”}, {“role”: “user”, “content”: task}, ]
whereas True: # The mannequin name itself will get its personal little one span with tracer.start_as_current_span(“chat”) as chat_span: response = model_client.chat.completions.create( mannequin=“gpt-4o”, messages=messages, instruments=AVAILABLE_TOOLS ) alternative = response.decisions[0]
chat_span.set_attributes({ “gen_ai.response.mannequin”: response.mannequin, “gen_ai.utilization.input_tokens”: response.utilization.prompt_tokens, “gen_ai.utilization.output_tokens”: response.utilization.completion_tokens, })
if alternative.finish_reason != “tool_calls”: agent_span.set_status(Standing(StatusCode.OK)) return alternative.message.content material
# Every software name will get its personal little one span, nested beneath # the agent run, not beneath the chat span, since a software # name is a sibling step, not a sub-step of inference for tool_call in alternative.message.tool_calls: with tracer.start_as_current_span(“execute_tool”) as tool_span: tool_span.set_attributes({ “gen_ai.software.title”: tool_call.perform.title, “gen_ai.software.name.id”: tool_call.id, }) attempt: consequence = call_tool(tool_call.perform.title, tool_call.perform.arguments) besides Exception as e: tool_span.record_exception(e) tool_span.set_status(Standing(StatusCode.ERROR, str(e))) elevate
messages.append({ “function”: “software”, “content material”: str(consequence), “tool_call_id”: tool_call.id, }) |
The nesting is doing the true work right here. Each chat span and each execute_tool span opens contained in the with tracer.start_as_current_span(…) block belonging to the run above it, which is precisely what OpenTelemetry makes use of to construct the parent-child relationship mechanically — you by no means manually wire “this span belongs beneath that one,” it’s implicit in how the with blocks are structured in your code. record_exception plus set_status(StatusCode.ERROR, …) on the software span is what makes a failed software name present up clearly in a hint viewer relatively than silently vanishing into the returned string, which issues immediately for the debugging part later on this article. And separating token utilization attributes onto the chat span particularly, relatively than the top-level invoke_agent span, is what lets a hint viewer later present you token price damaged down per mannequin name inside a single run, not only a single mixed whole for the entire thing.
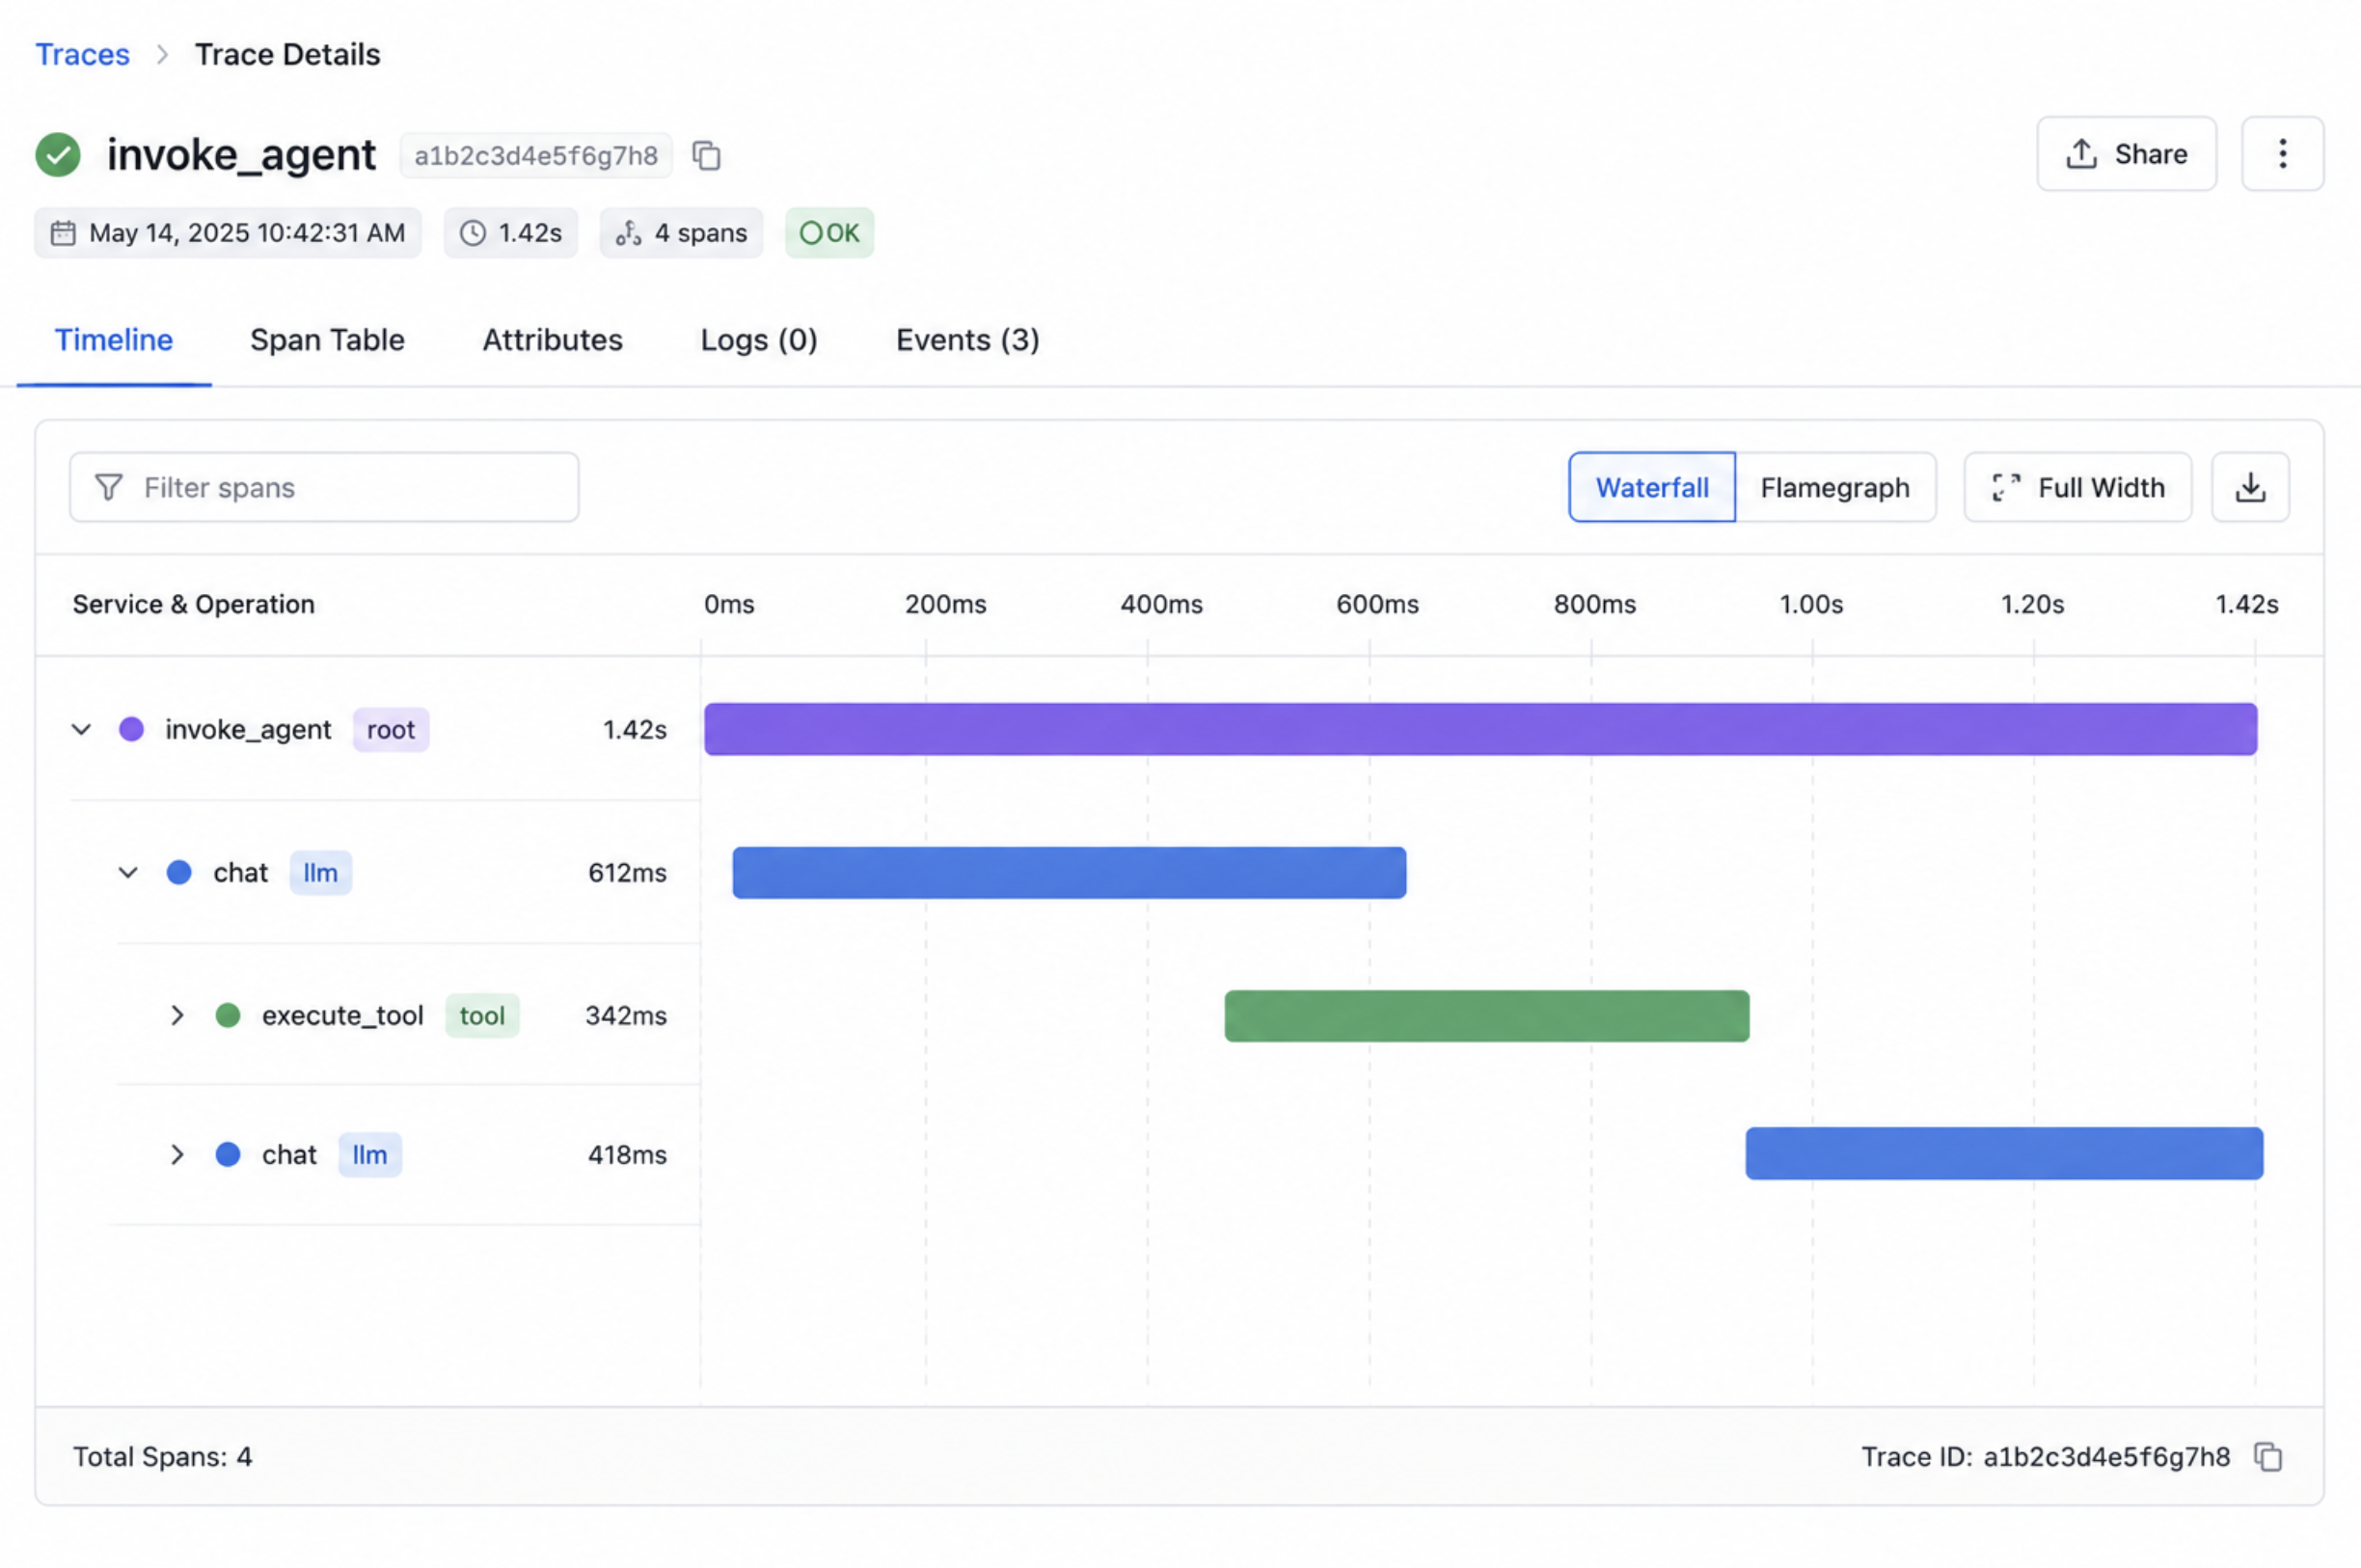
A screenshot of a hint waterfall view in an observability dashboard (click on to enlarge)
Picture by Writer
Chain Visualization: Studying the Hint Waterfall
The spans from the final part don’t imply a lot as a uncooked checklist. What really makes them helpful is a waterfall view — spans stacked by their nesting depth and stretched horizontally by how lengthy each took, so an entire agent run turns into a single image you’ll be able to scan in seconds. It’s value studying to learn one in plain textual content earlier than ever opening an actual dashboard, for the reason that form is similar both manner:
|
invoke_agent (1850ms) ├── chat (920ms) ← decides to name two instruments │ ├── execute_tool: refund_lookup (310ms) │ └── execute_tool: refund_lookup (295ms) ← known as once more, identical software └── chat (530ms) ← remaining reply |
That waterfall alone tells you greater than an hour of guessing would. The 2 refund_lookup calls sitting as siblings beneath the identical chat span is precisely the form of redundant software name that induced the failure this text opened with, and it’s seen at a look relatively than buried in a wall of logs. In an actual dashboard, this identical construction renders as horizontal bars, and the habits value constructing are easy: search for a bar that’s unusually vast relative to its siblings, since that’s the place time and token price range are literally going; search for a software name that repeats when it shouldn’t; and search for a chat span the place the mannequin reached for a software in any respect when the duty didn’t clearly want one. None of that requires studying a single log line. It’s all seen within the form of the hint itself.
Token Monitoring and Price Metrics
Traces are wonderful for understanding one particular run intimately. They’re the incorrect software for recognizing a development throughout 1000’s of runs, which is what metrics are for. The 2 genuinely load-bearing metrics for an agent, per the OpenTelemetry GenAI conventions, are gen_ai.shopper.token.utilization and gen_ai.shopper.operation.period, tracked as a counter and a histogram respectively.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 |
from opentelemetry import metrics import time
meter = metrics.get_meter(“agent-service”)
token_counter = meter.create_counter( “gen_ai.shopper.token.utilization”, unit=“token”, description=“Tokens consumed, damaged down by mannequin and enter/output”, )
duration_histogram = meter.create_histogram( “gen_ai.shopper.operation.period”, unit=“s”, description=“Length of every mannequin name, in seconds”, )
def tracked_chat_call(messages: checklist, mannequin: str = “gpt-4o”) -> str: attrs = {“gen_ai.system”: “openai”, “gen_ai.request.mannequin”: mannequin} begin = time.time()
attempt: response = model_client.chat.completions.create(mannequin=mannequin, messages=messages)
# Recording enter and output tokens as two separate calls, # not one mixed whole, is what preserves the precise # price construction, since enter and output tokens are # priced in a different way on almost each supplier token_counter.add(response.utilization.prompt_tokens, {**attrs, “gen_ai.token.kind”: “enter”}) token_counter.add(response.utilization.completion_tokens, {**attrs, “gen_ai.token.kind”: “output”})
return response.decisions[0].message.content material lastly: duration_histogram.file(time.time() – begin, attrs) |
The selection to file enter and output tokens as two separate counter calls, relatively than one mixed total_tokens worth, issues greater than it seems. A single mixed counter hides precisely the knowledge you’d want to note — as an example, {that a} system immediate has quietly grown so giant it’s dwarfing the precise consumer enter on each single name. Splitting them aside is what makes that seen in a dashboard relatively than buried inside a median.
With these two metrics flowing, a small set of alert situations covers most of what really goes incorrect in manufacturing, per Uptrace’s suggestions:
| Metric | Alert situation | Why it issues |
|---|---|---|
| Token utilization charge | Greater than double the baseline over 10 minutes | Typically a runaway loop or a immediate injection try |
| Operation period, p99 | Above 30 seconds | The mannequin is overloaded, or the context window is simply too giant |
| Error charge | Above 2% over 5 minutes | Fee limiting or quota exhaustion, value catching earlier than customers do |
| Enter-to-output token ratio | Persistently above 10 to 1 | The system immediate has probably grown bloated and wishes trimming |
Telemetry Pipelines: Getting Traces from Code to a Backend
All the things thus far has assumed traces and metrics land someplace helpful, and that plumbing deserves its personal consideration relatively than being an afterthought. In a typical setup, your instrumented utility exports telemetry to an OpenTelemetry Collector — a separate course of that receives it, optionally transforms or filters it, and forwards it on to wherever you’re really storing and viewing traces. That center layer is the place two sensible issues get dealt with with out touching a single line of utility code.
- The primary is sampling. Capturing each single hint at full quantity is affordable in growth, however LLM calls are sluggish and their spans are giant, so full seize in manufacturing will get costly quick with out including proportional worth. The sensible sample is to pattern in a different way relying on the state of affairs: full seize in growth, a modest proportion — typically 5 to 10% — of routine profitable manufacturing calls, and 100% seize for something genuinely invaluable: each error, each high-token request, and each full agent run, since these are precisely the instances you’ll really wish to look again at.
- The second is privateness, and it deserves to be handled as a first-class design determination relatively than one thing bolted on later. Immediate and completion content material belongs in span occasions, not span attributes, since attributes are all the time listed and exported with no measurement restrict, whereas occasions may be filtered, truncated, or dropped completely on the Collector stage. A Collector configuration can strip or hash immediate content material from each span crossing the pipeline earlier than it ever reaches a storage backend, which suggests a compliance requirement doesn’t have to show right into a code change scattered throughout each instrumented name website in your utility.
|
processors: remodel: trace_statements: – context: spanevent statements: # Strips immediate and completion content material from each span # occasion that passes by way of the Collector, no utility # code modifications required – delete_matching_keys(attributes, “gen_ai.immediate.content material”) – delete_matching_keys(attributes, “gen_ai.completion.content material”) |
MCP Tracing
This can be a genuinely latest addition value realizing about particularly, because it closes a niche most present protection of this subject hasn’t caught as much as but. Earlier than OpenTelemetry’s Mannequin Context Protocol semantic conventions, added in spec model 1.39, the precise protocol mechanics beneath an MCP software name — which methodology received invoked, which session it belonged to, and which protocol model was in use — have been successfully invisible in a hint. You could possibly see {that a} software ran and what it returned, however not the layer beneath that.
The element value understanding is how these new attributes get connected. Slightly than making a second, separate span for the protocol layer, MCP instrumentation enriches the present execute_tool span with attributes like mcp.methodology.title, mcp.session.id, and mcp.protocol.model, layering the additional element onto the span you already had as an alternative of doubling the hint’s noise. For anybody constructing brokers that decision out to a number of MCP servers, that’s the distinction between a hint that stays readable and one which turns right into a wall of near-duplicate spans.
Debugging Workflows
That is the place every little thing constructed thus far really pays off. An actual debugging workflow, as soon as tracing is in place, tends to observe the identical form whatever the platform behind it: begin from the dangerous output a consumer reported, pull the hint ID that produced it, open the waterfall, and scan for the span the place the run really went incorrect — an unexpectedly vast chat span, a repeated execute_tool name, an error standing someplace within the tree. When you’ve discovered the step, the span’s attributes and occasions let you know precisely what arguments have been handed and what got here again, which is often sufficient to grasp the error immediately, no re-running required, no guessing.
Two extra superior methods are value realizing as this follow matures. Replay, generally known as time-travel debugging, enables you to re-run an agent session with point-in-time precision — successfully restoring the precise state the agent was in at a given step and persevering with from there, a functionality AgentOps is particularly identified for. And a more recent sample value watching is natural-language hint querying, the place as an alternative of manually scanning a waterfall, an engineer can immediately ask a platform one thing like “why did the agent enter this loop” and get a solution generated from analyzing the hint knowledge itself — a functionality LangSmith has constructed immediately into its product. Neither replaces the basics coated above. Each are what these fundamentals make potential as soon as a group has sufficient traces flowing to make asking that form of query worthwhile.
The Instruments High Groups Really Use in 2026
Constructing this your self with uncooked OpenTelemetry, as proven all through this text, works and retains you vendor-neutral, however most groups finally attain for a platform to retailer, visualize, and question the traces they’re producing. The choice genuinely comes all the way down to deployment mannequin earlier than it comes all the way down to options, since that single alternative eliminates many of the area by itself, per Digital Utilized’s 2026 breakdown.
Self-hosted platforms — Langfuse and Arize Phoenix amongst them — go well with groups with actual knowledge residency necessities or a necessity for tight price management at scale, at the price of proudly owning the operational overhead your self. Managed SDKs — LangSmith and Braintrust — commerce that possession for velocity: you add an SDK, the seller runs the backend and storage, and also you sometimes get analysis tooling bundled in from day one. Proxy gateways — Helicone being the clearest instance — sit your visitors behind a routing layer that logs price and utilization throughout lots of of fashions with near zero code change, with the tradeoff that the gateway itself turns into a single level of failure value planning actual uptime round.
| Platform | Deployment mannequin | Free tier | OpenTelemetry assist | 2025 to 2026 sign |
|---|---|---|---|---|
| Langfuse | Self-hosted or cloud | Free self-hosting | Sure | Acquired by ClickHouse, January 2026 |
| Arize Phoenix | Self-hosted | Open supply, free | Sure, OTLP-native | Actively rising open-source challenge |
| LangSmith | Managed SDK | 5,000 traces per 30 days | Sure | Pure-language hint querying in-built |
| Braintrust | Managed SDK | 1 million spans per 30 days | Sure | $80M Sequence B, February 2026 |
| Helicone | Proxy gateway | 10,000 requests per 30 days | By way of gateway | Price monitoring throughout 300+ fashions |
| AgentOps | SDK | Open supply, free | Sure | Identified for time-travel replay debugging |
| Datadog LLM Observability | Managed, extends present APM | 40,000 LLM spans per 30 days | Sure | Payments solely LLM spans, not software or retrieval spans |
Placing It Collectively
Right here’s how all the items above mix into one working script, so the ideas on this article don’t keep disconnected. This wires up tracing, token metrics, and structured logging collectively round a single small agent.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 |
import logging import time from opentelemetry import hint, metrics from opentelemetry.hint import Standing, StatusCode
tracer = hint.get_tracer(“agent-service”) meter = metrics.get_meter(“agent-service”) logger = logging.getLogger(“agent”)
token_counter = meter.create_counter(“gen_ai.shopper.token.utilization”, unit=“token”) duration_histogram = meter.create_histogram(“gen_ai.shopper.operation.period”, unit=“s”)
def run_instrumented_agent(job: str) -> str: with tracer.start_as_current_span(“invoke_agent”) as agent_span: trace_id = format(agent_span.get_span_context().trace_id, “032x”) agent_span.set_attributes({“agent.title”: “support-agent”, “gen_ai.request.mannequin”: “gpt-4o”}) logger.information(“agent_run_started”, additional={“trace_id”: trace_id, “job”: job[:100]})
messages = [{“role”: “user”, “content”: task}]
whereas True: with tracer.start_as_current_span(“chat”) as chat_span: begin = time.time() response = model_client.chat.completions.create( mannequin=“gpt-4o”, messages=messages, instruments=AVAILABLE_TOOLS ) duration_histogram.file(time.time() – begin, {“gen_ai.request.mannequin”: “gpt-4o”})
utilization = response.utilization token_counter.add(utilization.prompt_tokens, {“gen_ai.token.kind”: “enter”}) token_counter.add(utilization.completion_tokens, {“gen_ai.token.kind”: “output”}) chat_span.set_attributes({ “gen_ai.utilization.input_tokens”: utilization.prompt_tokens, “gen_ai.utilization.output_tokens”: utilization.completion_tokens, })
alternative = response.decisions[0]
if alternative.finish_reason != “tool_calls”: agent_span.set_status(Standing(StatusCode.OK)) logger.information(“agent_run_completed”, additional={“trace_id”: trace_id}) return alternative.message.content material
for tool_call in alternative.message.tool_calls: with tracer.start_as_current_span(“execute_tool”) as tool_span: tool_span.set_attribute(“gen_ai.software.title”, tool_call.perform.title) logger.information( “tool_call_started”, additional={“trace_id”: trace_id, “tool_name”: tool_call.perform.title}, ) attempt: consequence = call_tool(tool_call.perform.title, tool_call.perform.arguments) besides Exception as e: tool_span.record_exception(e) tool_span.set_status(Standing(StatusCode.ERROR, str(e))) logger.error( “tool_call_failed”, additional={“trace_id”: trace_id, “tool_name”: tool_call.perform.title}, ) elevate messages.append({“function”: “software”, “content material”: str(consequence), “tool_call_id”: tool_call.id}) |
Run this with a Collector configured to export to whichever backend you’ve picked from the desk above, and a single name to run_instrumented_agent produces a full hint with nested spans for each software name, token metrics recorded per mannequin name, and structured log traces carrying the hint ID that ties every little thing again collectively — precisely the setup this complete article has been constructing towards.
Conclusion
An unsupervised agent isn’t a smaller danger than an unmanaged net service; it’s a bigger one, exactly as a result of its failures are constructed to look positive till somebody checks intently. The refund lookup known as twice, the assured reply constructed on stale knowledge — none of that journeys an alarm by itself. Logging tells you what occurred at every step. Tracing exhibits you the way these steps really linked. Debugging is what turns that file into a solution as an alternative of a guess. Construct all three in earlier than an agent is dealing with something that really issues, not after the primary buyer notices one thing went incorrect.