
This weblog put up relies on our latest work, “Can LLM Brokers Uncover? Evaluating Creativity on ML Engineering Duties“, printed at COLM 2026 and written with Yunxiang Zhang and Professor Lu Wang on the College of Michigan. Do try the paper for a extra detailed studying, whereas this weblog put up acts as a summarized model of our work. The principle query we are attempting to reply right here is that this: whereas there was a large push for AI for Science, with large investments in LLM brokers for scientific discovery, these brokers nonetheless fall in need of the top-1 human on actual ML analysis challenges. On the identical time, we see common experiences of LLMs making breakthroughs (AlphaEvolve, the Kosmos AI scientist, and so on.), and OpenAI just lately claimed to have solved Navier-Stokes. So why the disconnect?
A standard reply to that might be the underlying framework and scaffolding the mannequin has entry to, as these higher frameworks may enable for extra environment friendly search of the answer house, however how can we quantify this notion of “higher search”? We argue that creativity gives a helpful lens.
So then what’s Creativity?
A pure trait we would like in these brokers is that they give you concepts which are each novel and ship nice outcomes, and that’s precisely what creativity is.
In accordance with the “The Commonplace Definition of Creativity” by Mark A. Runco and Garrett J. Jaeger, “Creativity is the manufacturing of concepts or merchandise which are concurrently unique and helpful (i.e., efficient or acceptable)”
Curiously, there have been many different works in inventive psychology that hyperlink creativity to look in a conceptual house:
Boden, M. A. (1998). “Creativity and Synthetic Intelligence” →
“the era of novel concepts by the exploration of structured conceptual areas.”
Boden, M. A. (2004). The Artistic Thoughts: Myths and Mechanisms (2nd ed.) →
“Western music springs from a search-space outlined by the principles of concord, and its melodies are pathways by a exactly mappable panorama of musical intervals.”
Newell, A., Shaw, J. C., & Simon, H. A. (1962). “The Strategy of Artistic Considering” →
“success of an issue solver who’s confronted with a fancy job rests totally on his skill to pick out, accurately, a really small a part of the overall problem-solving maze for exploration.”
This results in the primary query that we are attempting to research on this mission:
To research whether or not the efficiency variations between agent frameworks may be attributed to how they construction and information the inventive search course of, and to quantify how creativity emerges and evolves inside these frameworks.
Creativity → Originality + Usefulness
For the remainder of this put up, we’re going to break creativity down additional into subparts based mostly on analysis from inventive psychology. Following Boden, originality may be additional damaged down into P-Creativity and H-Creativity. P-Creativity or P-novelty mainly measures how novel one thing is relative to this system’s personal reminiscence and historical past. H-Creativity measures how novel one thing is in comparison with your entire physique of human data. Following Chan and Schunn, usefulness may be cut up into affect and feasibility.
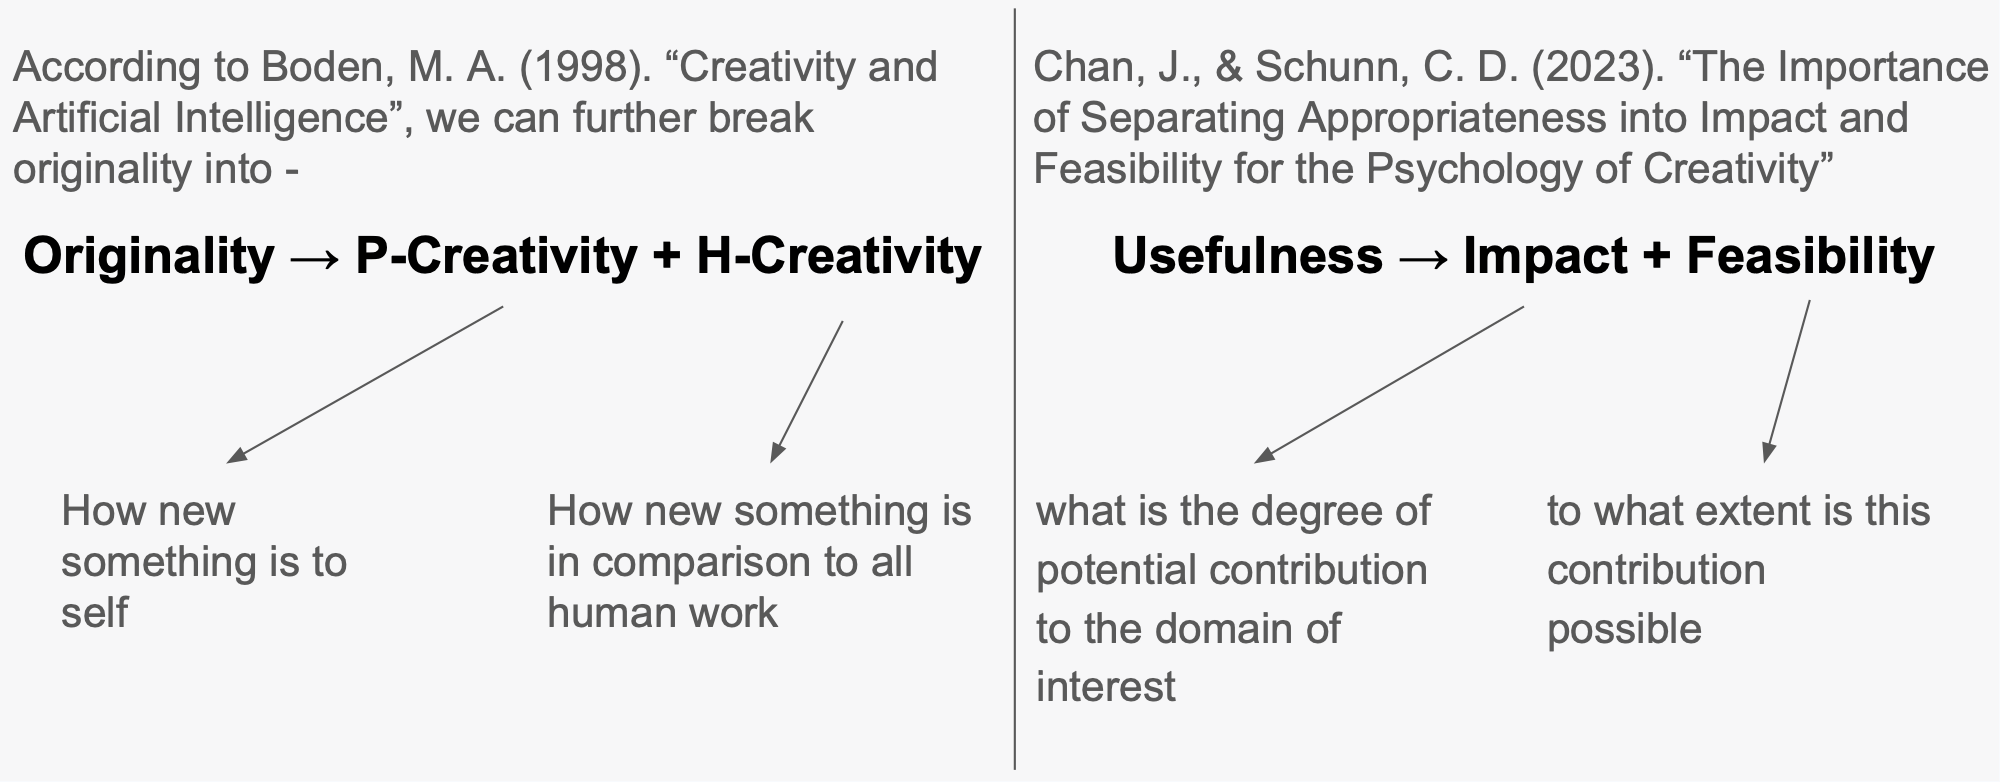
Placing these collectively, we get:
Creativity → P-Creativity + H-Creativity + Affect + Feasibility
…which is the definition we’re going to be working with for the remainder of this put up. Curiously, this mixture of ‘novelty’ and ‘usefulness’ is what makes creativity fascinating for science brokers.
Drawback Formulation
Okay, now that now we have our definition of creativity, the subsequent query is the place it makes probably the most sense to measure it with a view to check the modern skill of fashions. In a multi-turn agentic setting, we’d like three circumstances to measure creativity meaningfully: quantifiable usefulness metrics, wealthy human baselines for H-creativity comparability, and an answer house the place real novelty is feasible. Based mostly on these standards, machine studying duties are the perfect match, so our downside turns into:
Given a hard and fast LLM and a collection of ML duties, how do totally different agent frameworks information the era of inventive options over time, and might we use creativity metrics to clarify why some frameworks/LLMs outperform others?
As said earlier, the metrics that we’re curious about measuring listed below are:
|
Metric |
How can we measure it? |
|---|---|
|
P-Creativity |
LLM-as-a-Decide (GPT-5) scoring in opposition to all prior episodes on a 0–4 rubric. The rubric is grounded in boden’s creativity framework: 0 (Routine) by 4 (Transformational). |
|
H-Creativity |
Retrieval (embedding NN) + GPT-5 decide vs. 877–3,747 Kaggle notebooks per job |
|
Affect |
(S(e) − S_baseline) / (S_top1 − S_baseline) |
|
Feasibility |
Implicit: episode solely enters evaluation if code runs efficiently |
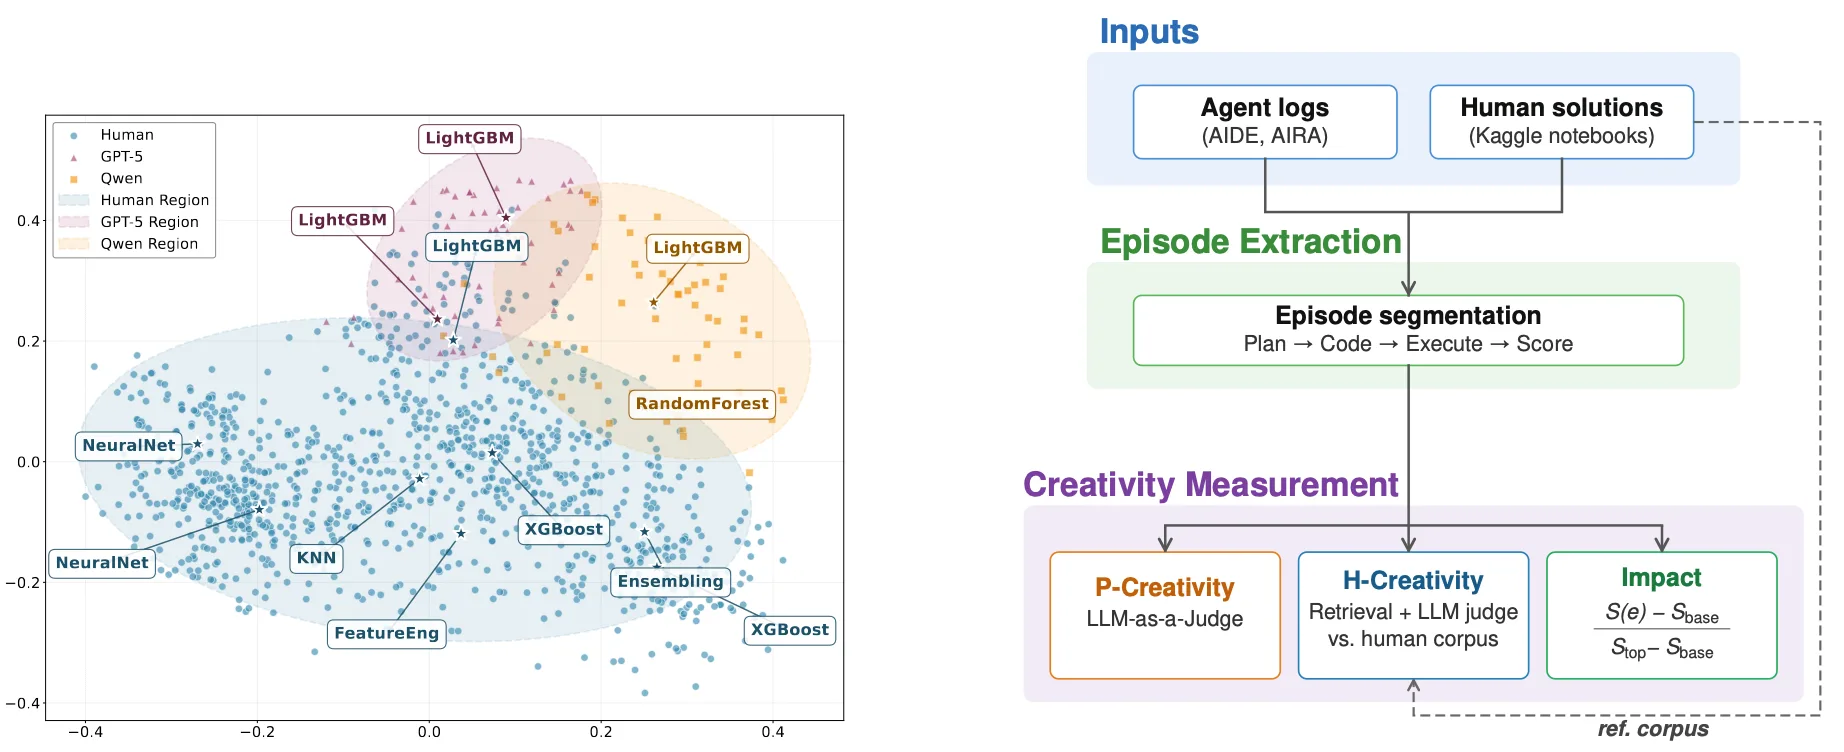
For P and H-creativity, LLM-as-a-judge finally ends up as our predominant rating. Affect is a normalized 0–1 rating of how shut the mannequin will get to the top-1 human rating, and feasibility is implicit, in that we measure creativity just for these episodes that are possible. We additionally use this notion of episodes right here the place an episode is a set of steps which led to a profitable submission.
Let’s attempt to perceive our job setup and metric measurement with an instance run:
Cassava Leaf Illness Classification
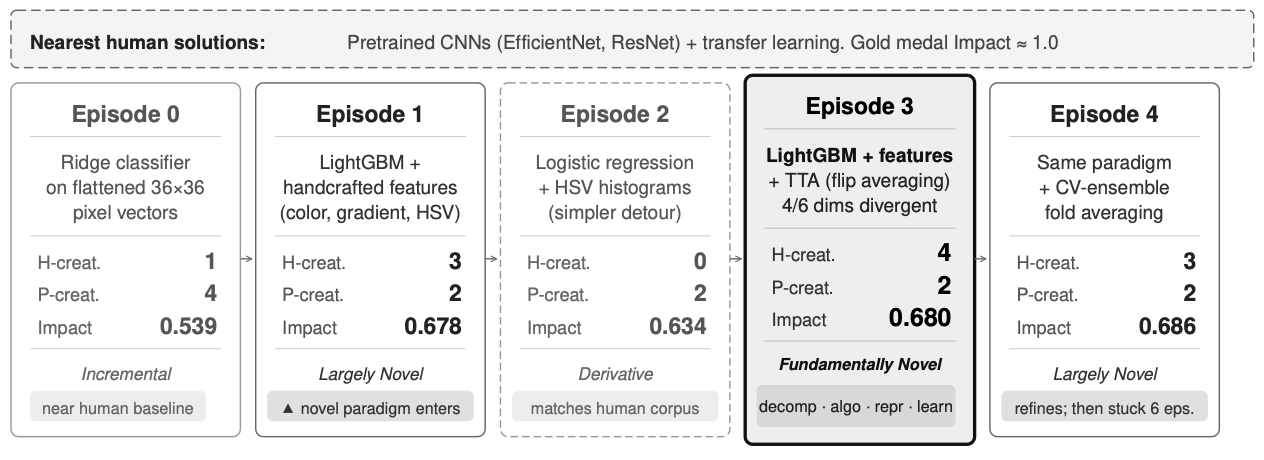
The duty right here is picture classification. The agent (AIDE with GPT-5) is supplied with a folder containing the practice dataset and the issue assertion. The agent begins off with a ridge classifier method, and since that is the primary episode, with no prior historical past to check in opposition to, it will get a P-creativity of 4 by conference. The agent then strikes on to strive a pair extra approaches, with H-creativity and affect peaking when it makes use of LightGBM with handcrafted options. Curiously, people most likely found very early within the competitors that CNNs carried out greatest, and so centered on neural nets, which is why LightGBM stands out as novel in comparison with 3,747 human approaches. After solely episode 4, the agent will get caught attempting the identical method time and again for the remainder of the run focusing extra on exploitation slightly than exploration, and finally ends up properly in need of a medal.
Setup
We take 10 duties from MLE-bench, a benchmark that assessments ML engineering skill on Kaggle competitions, spanning picture, NLP, and tabular knowledge. We filtered for competitions with a wealthy corpus of human options, which right here means between 877 and three,747 public notebooks per competitors.
We consider two brokers: AIDE, a grasping tree-search agent, and AIRA-Dojo, which builds on AIDE however provides extra search methods and operators. We use GPT-5 and Qwen3-32B because the spine fashions for these brokers. For every agent, we run 8 runs per model-task mixture, every with an 8-hour finances and a most of 10 episodes.
A bonus of selecting MLE-bench is entry to human trajectories. Curiously, we are able to additionally construct trajectories of how human affect and P-creativity change over the course of a complete competitors. Think about an individual who labored on a contest for 3 months and posted lots of public work: we are able to use that trajectory to see how the concepts they used modified because the competitors went on, and what impact these adjustments had on their rating. We are able to use this to instantly examine in opposition to an agent’s iterative behaviour to see how they match as much as people.
Can we Reliably measure P&H Creativity at scale?
This brings us to our first query: can we even measure P and H-creativity at scale, and the way would we go about it? Ideally, we might use knowledgeable human judges, however that method does not scale in any respect. So can we use automated metrics as a proxy for human judgement? Seems that we are able to! We had 3 annotators label 300 episodes for P-creativity after which measured automated approaches in opposition to it. Plenty of earlier works have adopted numerous totally different approaches to measure P-Creativity: some use LLM-as-a-judge, some use conceptual novelty, some use semantic distance, some use surprisal, and so forth. We examine all of them in opposition to the human annotations to see which does greatest, and use the winner for our P-creativity evaluation.
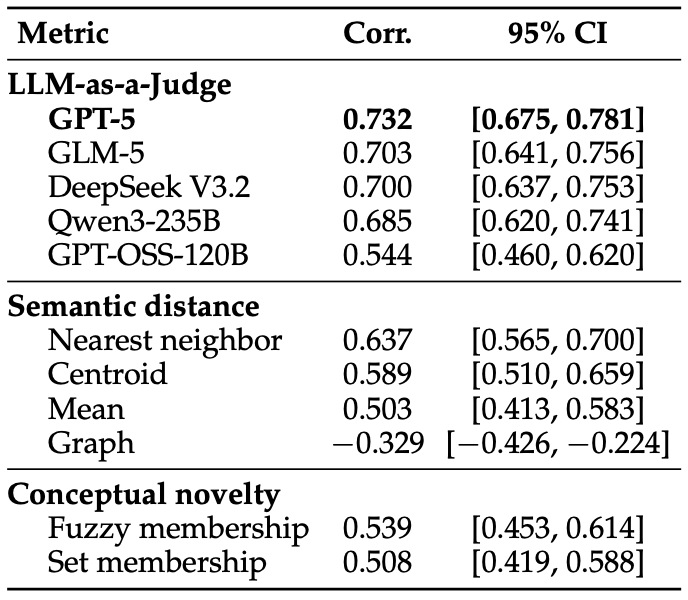
LLM-as-a-judge carried out the perfect thus driving our resolution to make use of it for measuring P-creativity. Semantic distance does decently properly and the hole between efficiency of various fashions as decide underlines the necessity for higher reasoning capabilities to measure novelty. For H-creativity, given the large human corpus would exceed context size of most LLMs, we went with a two-step technique: first use semantic distance to retrieve the 5 closest neighbors, then run LLM-as-a-judge in opposition to these 5 reference options.
Brokers go from exploration to exploitation
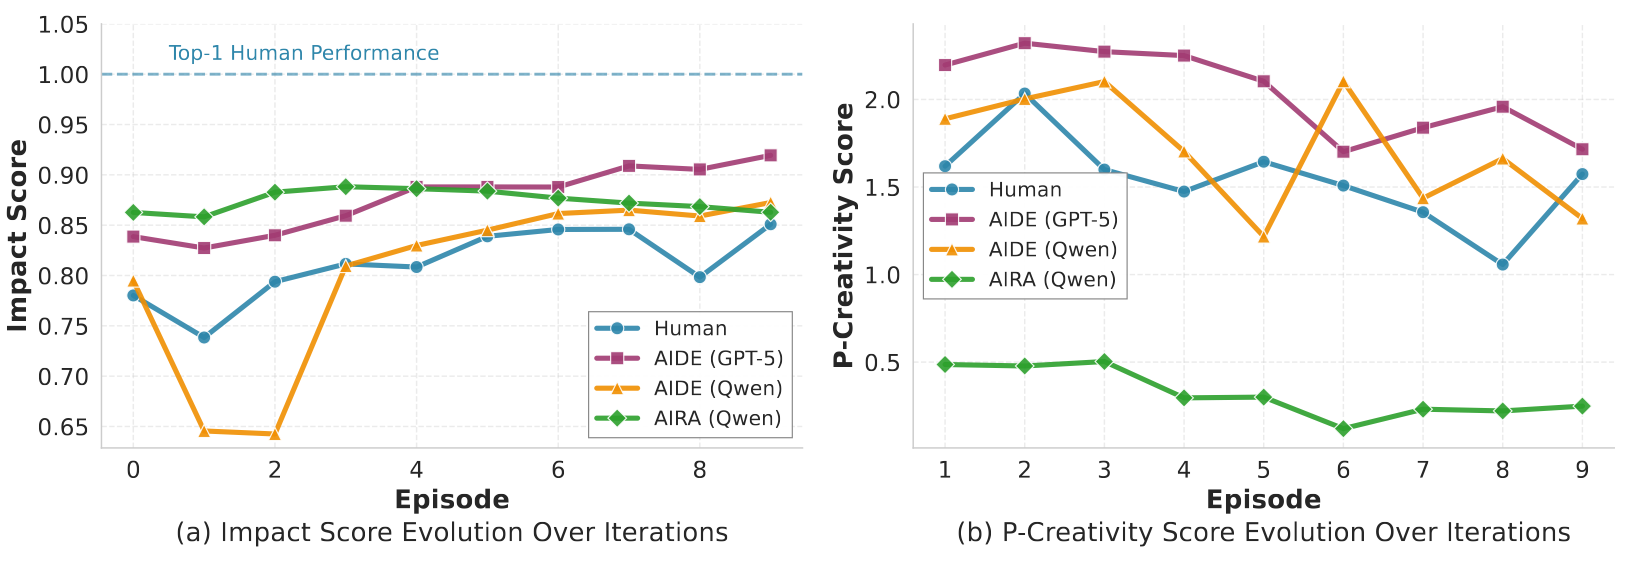
Throughout all our brokers, we see a standard development of going from exploration to exploitation. As we spend extra test-time compute, the brokers naturally strikes from exploring new concepts to attempting to refine a selected path, however seeing how early an agent begins transferring in the direction of exploitation is fascinating. We see the identical development in people too however brokers present a a lot steeper decline. This type of means that even when we gave the agent, let’s say, 100 steps, it could solely use the primary few for any exploration. Curiously, P-creativity and affect are basically uncorrelated: optimizing for one doesn’t assure good outcomes for the opposite!
An additional habits evaluation of agent reasoning traces confirms this exploration-to-exploitation mechanism: strategic exploration accounts for ~75% of reasoning traces early in a run, dropping to ~25% by the top. Brokers decide to a paradigm shortly and refine inside it.
Search technique alone doesn’t decide creativity or affect
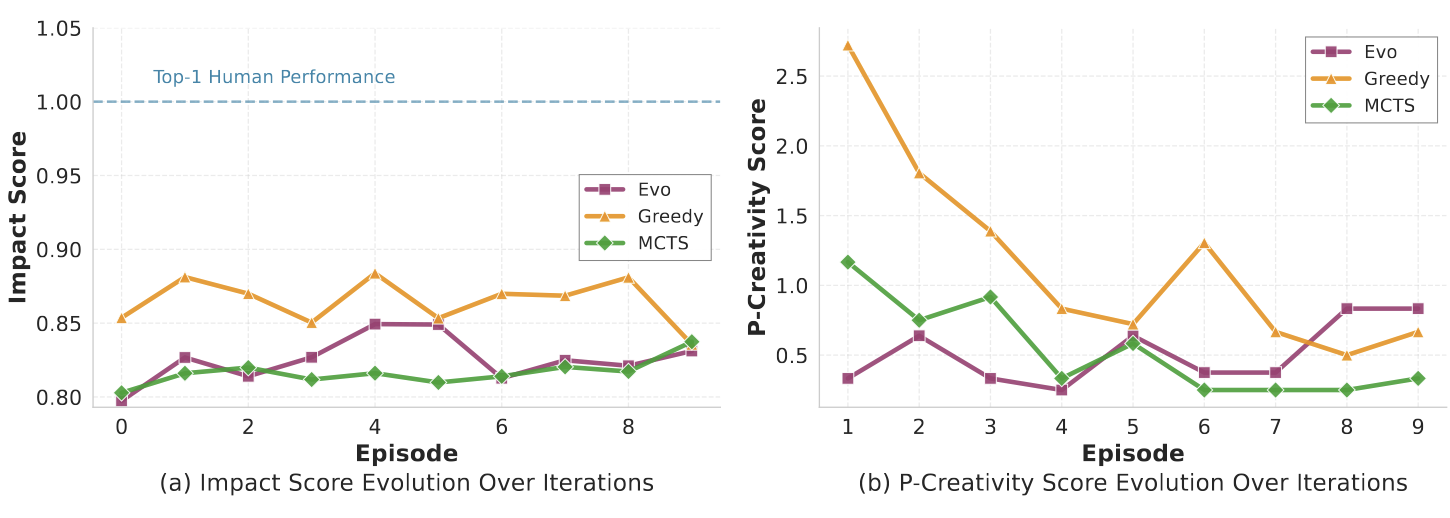
One other fascinating end result we noticed was that totally different search methods do not actually present very totally different tendencies! Over a number of iterations, all of them find yourself in about the identical vary, which is form of counterintuitive. We’d anticipate totally different tendencies and outcomes from totally different search methods, however this end result underlines the significance of all the pieces else in a framework: the underlying scaffolding, the prompts, how context is handed, and so forth. We will not simply change the search technique and anticipate totally different outcomes. As a substitute, we’d like all the pieces across the agent to work in concord.
Brokers attain novel territory, however cannot convert it
|
Group |
H-Creativity ( 0 to 4, greater is extra novel) |
|
AIDE (GPT-5) |
1.423 |
|
AIDE (Qwen3-32B) |
0.838 |
|
AIRA-MCTS (Qwen3-32B) |
0.800 |
|
Human Gold Medalist |
0.744 |
|
Human Silver Medalist |
0.524 |
|
Human Bronze Medalist |
0.293 |
One of many key takeaways we had is that after we measure the H-creativity of those brokers in opposition to people who obtain medals put up the competitors finish date, we see that LLMs really present greater novelty than these people but they carry out a lot worse than mentioned people. GPT-5 with AIDE achieves ~2x the historic novelty of gold-medal profitable people but solely 21% of GPT-5 runs achieved any medal. This end result matches the findings of different works that brokers are in a position to give you extra novel options, however these options are not often possible or helpful.
The place are these nearest neighbors?
A possible concern is that agent novelty displays regression to early approaches people later deserted, slightly than forward-looking exploration.
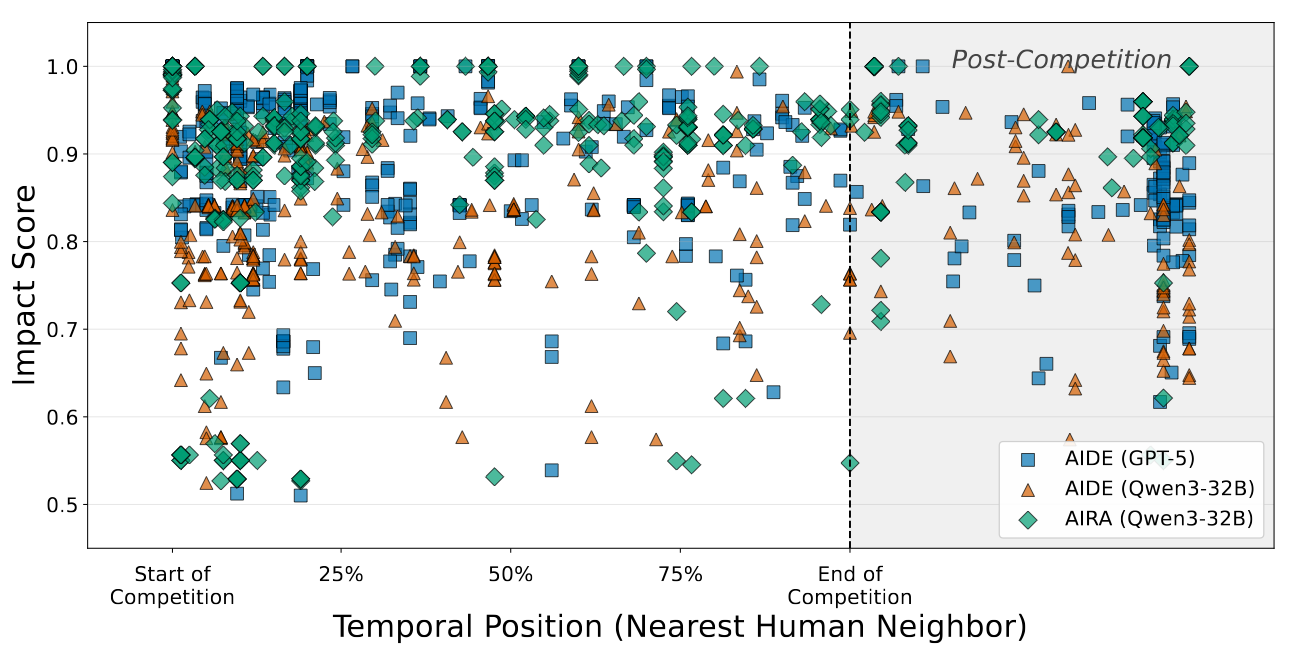
Temporal evaluation of agent episodes exhibits that agent concepts are unfold all through the competitors timeline. Curiously, GPT-5 exhibits probably the most uniform unfold, whereas Qwen does present some clustering round concepts the people tried early on. This implies that stronger reasoning capabilities in fashions could allow convergence in the direction of extra mature human options.
Limitations & Potential Future Instructions
A key takeaway that I wish to share from this work is the necessity to concentrate on the twin optimization of novelty and affect if we’re going to have brokers that may do autonomous analysis. With the rising significance of RL, this factors to the viability of utilizing P-creativity and affect as a twin optimization goal.
Scaling to longer trajectories: our analysis caps at 10 episodes as a result of context and compute limits; summarization or agent-as-a-judge approaches might allow P-creativity measurement over longer runs.
Extending to open-ended duties: our framework will depend on a quantitative metric and a bounded human corpus; making use of it to open-ended analysis settings would require surrogate usefulness indicators and richer reference corpora.
Since this work was achieved, lots of new outcomes have come out additional exhibiting LLM brokers discovering new algorithms and outcomes. A few of these got here from brokers working with little human involvement, however most got here from people and AI engaged on an issue collectively. Human-AI complementarity appears the perfect path ahead for now. That being mentioned, with every new mannequin launch we’re seeing an increasing number of work achieved autonomously by these brokers, they usually present a lot greater capabilities than what we noticed on this work with GPT-5 and Qwen3-32B. This factors to a future the place AI brokers doing science autonomously can grow to be a real actuality.
···
Word: All pictures have been created by the creator.